Introduction
dictk (Digital Image Correlation Toolkit) is a Python library for digital
image correlation (DIC) — comparing images of a specimen before and after
deformation to measure displacement and strain fields.
Installation
pip install dictk
Overview
DIC compares a reference image (often of an undeformed specimen) to a subject image (often of a deformed specimen) as a means to optically quantify displacement and strain fields.
Before we discuss the image portion of DIC, it is useful to introduce basic concepts of Continuum Mechanics and the Finite Element Method. This introduction will formalize definitions of displacement and strain and lay the groundwork for motion of discrete points locatable in reference/subject image pairs that are mapped to nodes of a finite element mesh (i.e., nodes).
The basic workflow is as follows:
- Collect a pair of before and after images that capture an area of interest.
- The before image, often called the reference image, captures some (possibly undeformed or deformed) configuration of the specimen.
- The after image, often called the current image or subject image, captures the specimen in a newly deformed state, different from the before state.
- Within each pair of images, identify points of interest.
- Use the coordinates of the image points as coordinates of nodes that compose a finite element mesh.
- Use DIC to quantify the displacement field of each (nodal) point.
- Use the mesh (nodal) deformation to calculate a discrete strain field at Gauss points.
The following sections explicate this workflow in detail.
Literature Overview
Sutton, Orteu, and Schreier provide the field's most comprehensive reference text: basic image-correlation and computer-vision theory, camera calibration and optics, two-dimensional, stereo, and volumetric correlation methods, and the continuum-mechanics, statistics, and optimization background needed to apply them all.1 For a shorter, more recent introduction alongside an annotated bibliography of the field, see Brown.2 The development of modern Digital Image Correlation (DIC) spans from specialized hardware acquisition to advanced mathematical frameworks and open-source implementations. For high-resolution SEM imaging, Lenthe et al. describe advanced detector signal acquisition and scanning methods,3 while Black et al. demonstrate high-throughput measurements using multi-beam SEM imaging.4 When dealing with plastic localization, the Heaviside-DIC approach offers a robust method for capturing discontinuities.5
Mathematical foundations for the DICe engine are established through the work of Turner, covering gradient-based local formulations,6 stereo correlation and triangulation,7 and the implementation of virtual strain gauges.8 Alternatively, the Augmented Lagrangian DIC (ALDIC) framework provides a global approach to displacement fields, available as both a theoretical framework9 and a MATLAB implementation.10 For complex geometries and large deformations, the SpatioTemporally Adaptive Quadtree (STAQ) mesh offers significant improvements in resolution.11
Software accessibility is primarily supported by the µDIC toolkit, an open-source Python library for DIC tasks.12 The project's evolution is tracked through specific version forks,13 comprehensive online documentation, and its primary repository.14 Finally, looking toward performance optimization, the Rust GPU project provides the infrastructure for hardware-accelerated computations that could benefit future DIC processing pipelines.15
References
-
Sutton MA, Orteu JJ, Schreier HW. Image Correlation for Shape, Motion and Deformation Measurements: Basic Concepts, Theory and Applications. Springer; 2009. ISBN 978-0-387-78746-6. link ↩
-
Brown C. Introduction to Digital Image Correlation (DIC) with annotated bibliography. Lawrence Livermore National Laboratory. 2025 Dec. LLNL-TR-2013494. link ↩
-
Lenthe WC, Stinville JC, Echlin MP, Chen Z, Daly S, Pollock TM. Advanced detector signal acquisition and electron beam scanning for high resolution SEM imaging. Ultramicroscopy. 2018 Dec 1;195:93-100. link ↩
-
Black RL, Garbowski T, Bean C, Eberle AL, Nickell S, Texier D, Valle V, Stinville JC. High-throughput high-resolution digital image correlation measurements by multi-beam SEM imaging. Experimental Mechanics. 2023 Jun;63(5):939-53. link ↩
-
Bourdin F, Stinville JC, Echlin MP, Callahan PG, Lenthe WC, Torbet CJ, Texier D, Bridier F, Cormier J, Villechaise P, Pollock TM. Measurements of plastic localization by heaviside-digital image correlation. Acta Materialia. 2018 Sep 15;157:307-25. link ↩
-
Turner DZ. An overview of the gradient-based local DIC formulation for motion estimation in DICe. 2016 Aug 19. SAND2016-7360R. link ↩
-
Turner DZ. An overview of the stereo correlation and triangulation formulations used in DICe. 2017 Mar 10. SAND2017-1876R. link ↩
-
Turner DZ. An overview of the virtual strain gauge formulation in DICe. 2018 May 21. SAND2018-5463R. link ↩
-
Yang J, Bhattacharya K. Augmented Lagrangian digital image correlation. Experimental Mechanics. 2019 Feb 15;59:187-205. link ↩
-
Augmented Lagrangian Digital Image Correlation (2D_ALDIC) MATLAB code. link ↩
-
Yang J, Rubino V, Ma Z, Tao J, Yin Y, McGhee A, Pan W, Franck C. SpatioTemporally adaptive quadtree mesh (STAQ) digital image correlation for resolving large deformations around complex geometries and discontinuities. Experimental Mechanics. 2022 Sep;62(7):1191-215. link ↩
-
Olufsen SN, Andersen ME, Fagerholt E. μDIC: An open-source toolkit for digital image correlation. SoftwareX. 2020 Jan 1;11:100391. link ↩
-
Olufsen SN. Fork: µDIC: A Python toolkit for Digital Image Correlation (DIC), GitHub: https://github.com/ElsevierSoftwareX/SOFTX_2019_193 link fork of https://github.com/PolymerGuy/muDIC for the 2020 paper. ↩
-
Olufsen SN. docs for µDIC: A toolkit for digital image correlation, docs and repo ↩
-
Rust GPU https://rust-gpu.github.io/ and https://github.com/rust-gpu/rust-gpu ↩
Continuum Mechanics
This section summarizes the kinematics of general (finite) motion, the motion map, the deformation gradient and its Jacobian, the family of finite-strain measures and their linearizations, and the polar and spectral decompositions.
- Upper case indices denote vector components in the reference configuration and
- Lower case indices denote vector components in the current configuration.
All vectors are referenced to origin and dextral, orthonormal basis vectors , , (equivalently, , , ).
Motion
Let the arbitrary time interval be defined as , from initial to final time, inclusive.1 Let the motion, a one-parameter family of configurations, , map the material particle (the reference configuration) into the current configuration ,
A motion evaluated at a particular time is referred to as a current configuration or placement. For any placement at time , there is a displacement field ,
Thus, the current configuration is simply a function of the original placement , plus a displacement , which is a function of reference configuration and time ,
The initial condition is found from the initial placement and the reference configuration ,
Deformation Gradient
To each configuration , we define a deformation gradient ,
Real, square matrices of dimension three with positive determinant are denoted . Gradient operations with and without a subscript "" are gradients taken in the reference and current configurations, respectively:
Alternative notations are and , respectively.
Jacobian of the Deformation Gradient
The Jacobian of the deformation gradient,
describes the (generally non-uniform) volumetric expansion or contraction of the motion from the reference configuration . All configurations must be admissible in the sense that the Jacobian of the deformation must be positive . This requirement keeps the deformations from mapping the body to a single, infinitesimally small point or turning the body inside-out .
Isochoric motions preserve the body's total volume. A Jacobian of unity describes an isochoric motion. The table below describes the categories of motions (expansion, volume-preserving, contraction, and inadmissible) by Jacobian measure.
| inadmissible | inadmissible | contraction | isochoric | expansion |
| body has turned inside-out | body has shrunk to zero volume | body's total volume has decreased | body's total volume is preserved | body's total volume has increased |
Four important isochoric deformations are (1) pure translation, (2) pure rotation, (3) isochoric stretch, and (4) isochoric shear.
Displacement Gradient
From the displacement field defined above, the relationship between the displacement gradient and the deformation gradient is given by
Right Cauchy-Green Deformation
The right Cauchy-Green deformation arises from the inner product of two differential fiber elements in the reference configuration, and , mapped by the deformation gradient to obtain the inner product of the same differential fibers in the current configuration, and ,
where
The right Cauchy-Green deformation tensor :
- is defined in the reference configuration,
- is symmetric and positive-definite,
- gets its name from the location of the deformation gradient in the definition, which is to the right,
- is a metric that maps fiber lengths from the reference configuration to the current configuration, and
- is second-order in reference displacement gradients, as shown below:
This result can be expected since, by definition, is second-order in the deformation gradient , and the relationship between the deformation gradient and the displacement gradient is linear.
Left Cauchy-Green Deformation
The left Cauchy-Green deformation arises from similar multiplication as with the right Cauchy-Green deformation, but with the stretching going in reverse, from the current configuration back to the reference configuration,
where
The left Cauchy-Green deformation tensor :
- is defined in the current configuration,
- is symmetric and positive-definite,
- gets its name from the location of the deformation gradient in the definition, which is to the left,
- is a metric whose inverse maps fiber lengths from the current configuration to the reference configuration, and
- is second-order in current displacement gradients.
Green-Lagrange Strain
The Green-Lagrange strain tensor,
is closely related to the right Cauchy-Green deformation tensor and is often used in defining constitutive law relationships because the measure, when linearized about the reference configuration, coincides with the small strain tensor of linear deformation elasticity, denoted and defined in the Infinitesimal Strain section. This relationship can be seen as follows:
where the higher-order (quadratic) term in the first line is set to zero to achieve the linearized second line.
Almansi-Euler Strain
The Almansi-Euler strain tensor,
can likewise be used to approximate the small strain tensor by combining the definitions of the left Cauchy-Green deformation and the deformation gradient as follows:
where the higher-order (quadratic) term is set to zero to achieve the linearized final line.
Small Strain
When displacement gradients are small in the reference configuration,
or in the current configuration,
respectively, the nonlinear gradient terms are negligible and the finite strain theory simplifies to small strain theory, which occurs when finite strain measures are linearized to obtain and in the previous sections.
Note that we have restricted the gradients of displacement, and not the displacement itself. Thus, displacements between the reference and current configurations can be large (finite), but the gradients of the displacement, either in the reference or current configuration, are small.
The Strain Tensors and Finite Rotations section will demonstrate that the small strain tensors are not suitable to describe motion that contains finite rotation. This makes sense because, in finite rotation, gradients of displacement are large, not small. To adequately describe motion that includes finite rotation, a fully nonlinear strain measure, such as the Seth-Hill strain family, must be used.
Infinitesimal Strain
If we further restrict the small strain theory such that the displacement is small compared to unity,
the infinitesimal strain theory is obtained, which has no distinction between Lagrangian and Eulerian strain tensors.
In this case, the two small strain tensors, and , converge to a single definition of strain, called the infinitesimal strain tensor , defined as
Note that the notation has been dropped since the distinction between the reference and current configurations is nonexistent. Also, note that the factor of appears because it then follows that the infinitesimal strain is simply the symmetric part of the displacement gradient,
Finally, note that the finite Lagrangian and Eulerian strain tensors were defined with the factor of so that their expressions, once linearized and subject to a small displacement assumption, simplify to exactly the infinitesimal strain tensor .
Seth-Hill Strain Family
We now return to finite strain definitions. Seth and Hill showed that the Green-Lagrange strain tensor and the Almansi-Euler strain tensor are special cases of the so-called Seth-Hill family of strain measures, defined as
The principal stretches , , allow the strain measure to be written as principal strains, as a function of principal stretch, ,
where the stretch function
For integer values2 of , five common strain measures result, listed in the table below, in their three-dimensional and one-dimensional forms. Similar relationships can be constructed for the spatial tensors using
| Name | 3D | 1D | |
|---|---|---|---|
| Green-Lagrange | |||
| engineering (Biot, nominal) | |||
| log (Hencky, natural) | |||
| true | |||
| Almansi-Euler |
The one-dimensional strains are illustrated as a function of stretch ratio in the figure below.
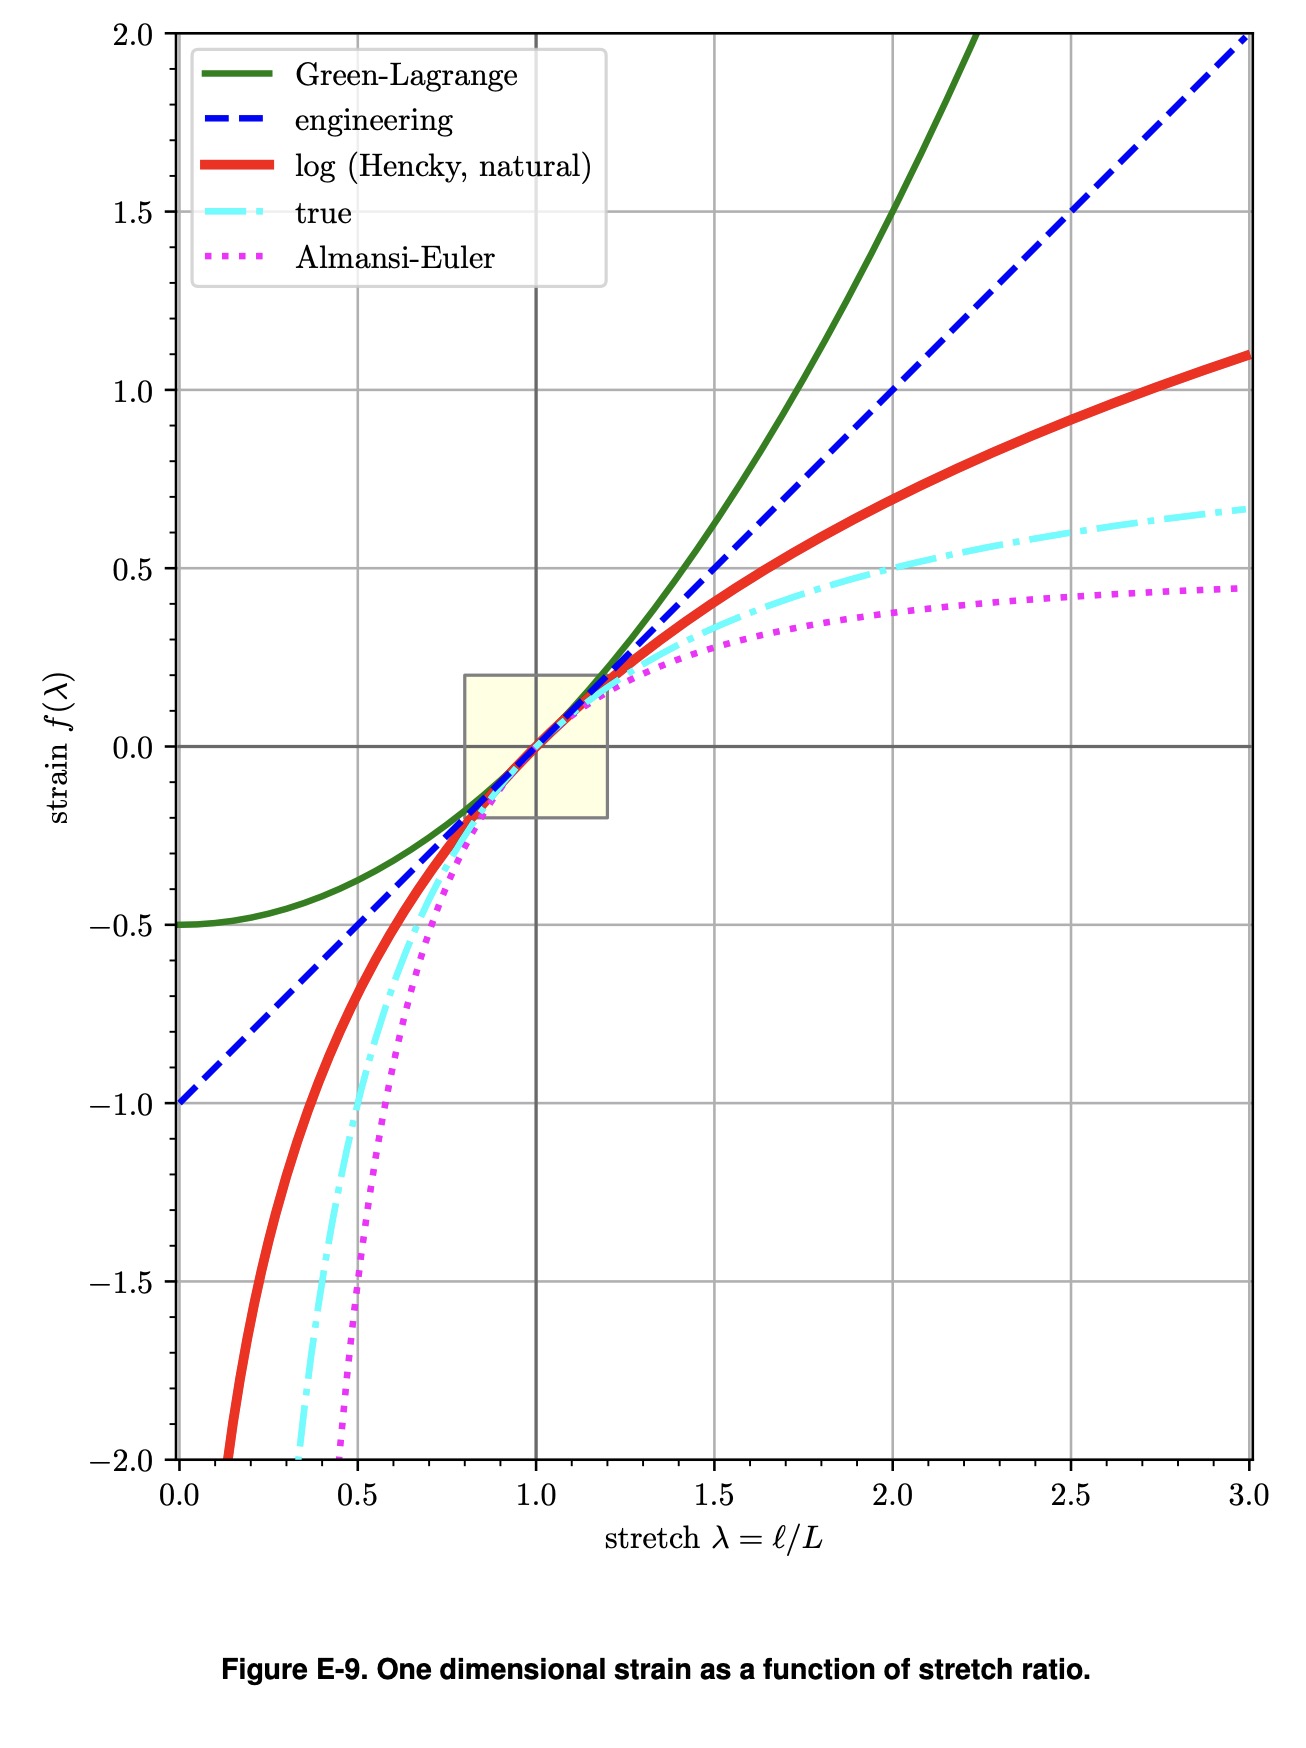
Source: Terpsma et al.3
The figure illustrates several results:
- For small stretches, , (a) the stretch ratio is near unity, , (b) the strain values are small, , and (c) the tangent of the strains with respect to the stretch ratio is near unity, .
- For elongations, , the strain monotonically increases since when .
- For extreme compressions, , (a) the Green-Lagrange strain goes to a value of , (b) the engineering (Biot, nominal) strain tensor goes to a value of , and (c) the log, true, and Eulerian strains tend to .
- The engineering (Biot, nominal) strain is a linear function of stretch ; all other measures are nonlinear functions of stretch .
Neff (2013)4 suggested "reasonable requirements" on , summarized in the table below, wherein a "+" indicates the requirement is satisfied and a "−" indicates the requirement is not satisfied.
| Requirement | |||||
|---|---|---|---|---|---|
| is smooth | + | + | + | + | + |
| is monotonically increasing | + | + | + | + | + |
| + | + | + | + | + | |
| + | + | + | + | + | |
| as , | + | + | + | − | − |
| as , | − | − | + | + | + |
| − | − | + | − | − | |
| for | − | − | + | − | − |
The results above illustrate that the log strain retains more of the desired qualities than any other strain tensor, in the context of finite compression and extension.5
- For infinitesimal deformation, all tensors converge to the infinitesimal strain tensor .
- For finite deformation, the Seth-Hill strain measures given by the function diverge quickly for both large compression and large tension.
The figure below illustrates the one-dimensional strains subtracted from the natural logarithmic strain, , as a function of stretch ratio . The log strain is considered as the finite deformation baseline.
The results show, for example, that in compression at , the Green-Lagrange strain tensor underreports the log strain by nearly 5%. Such a result illustrates that for finite deformation:
- Strain measures are not interchangeable, and
- It is ambiguous and incomplete to simply refer to "strain" as a deformation measure.
For finite deformation, both the strain value and the strain tensor must be specified.
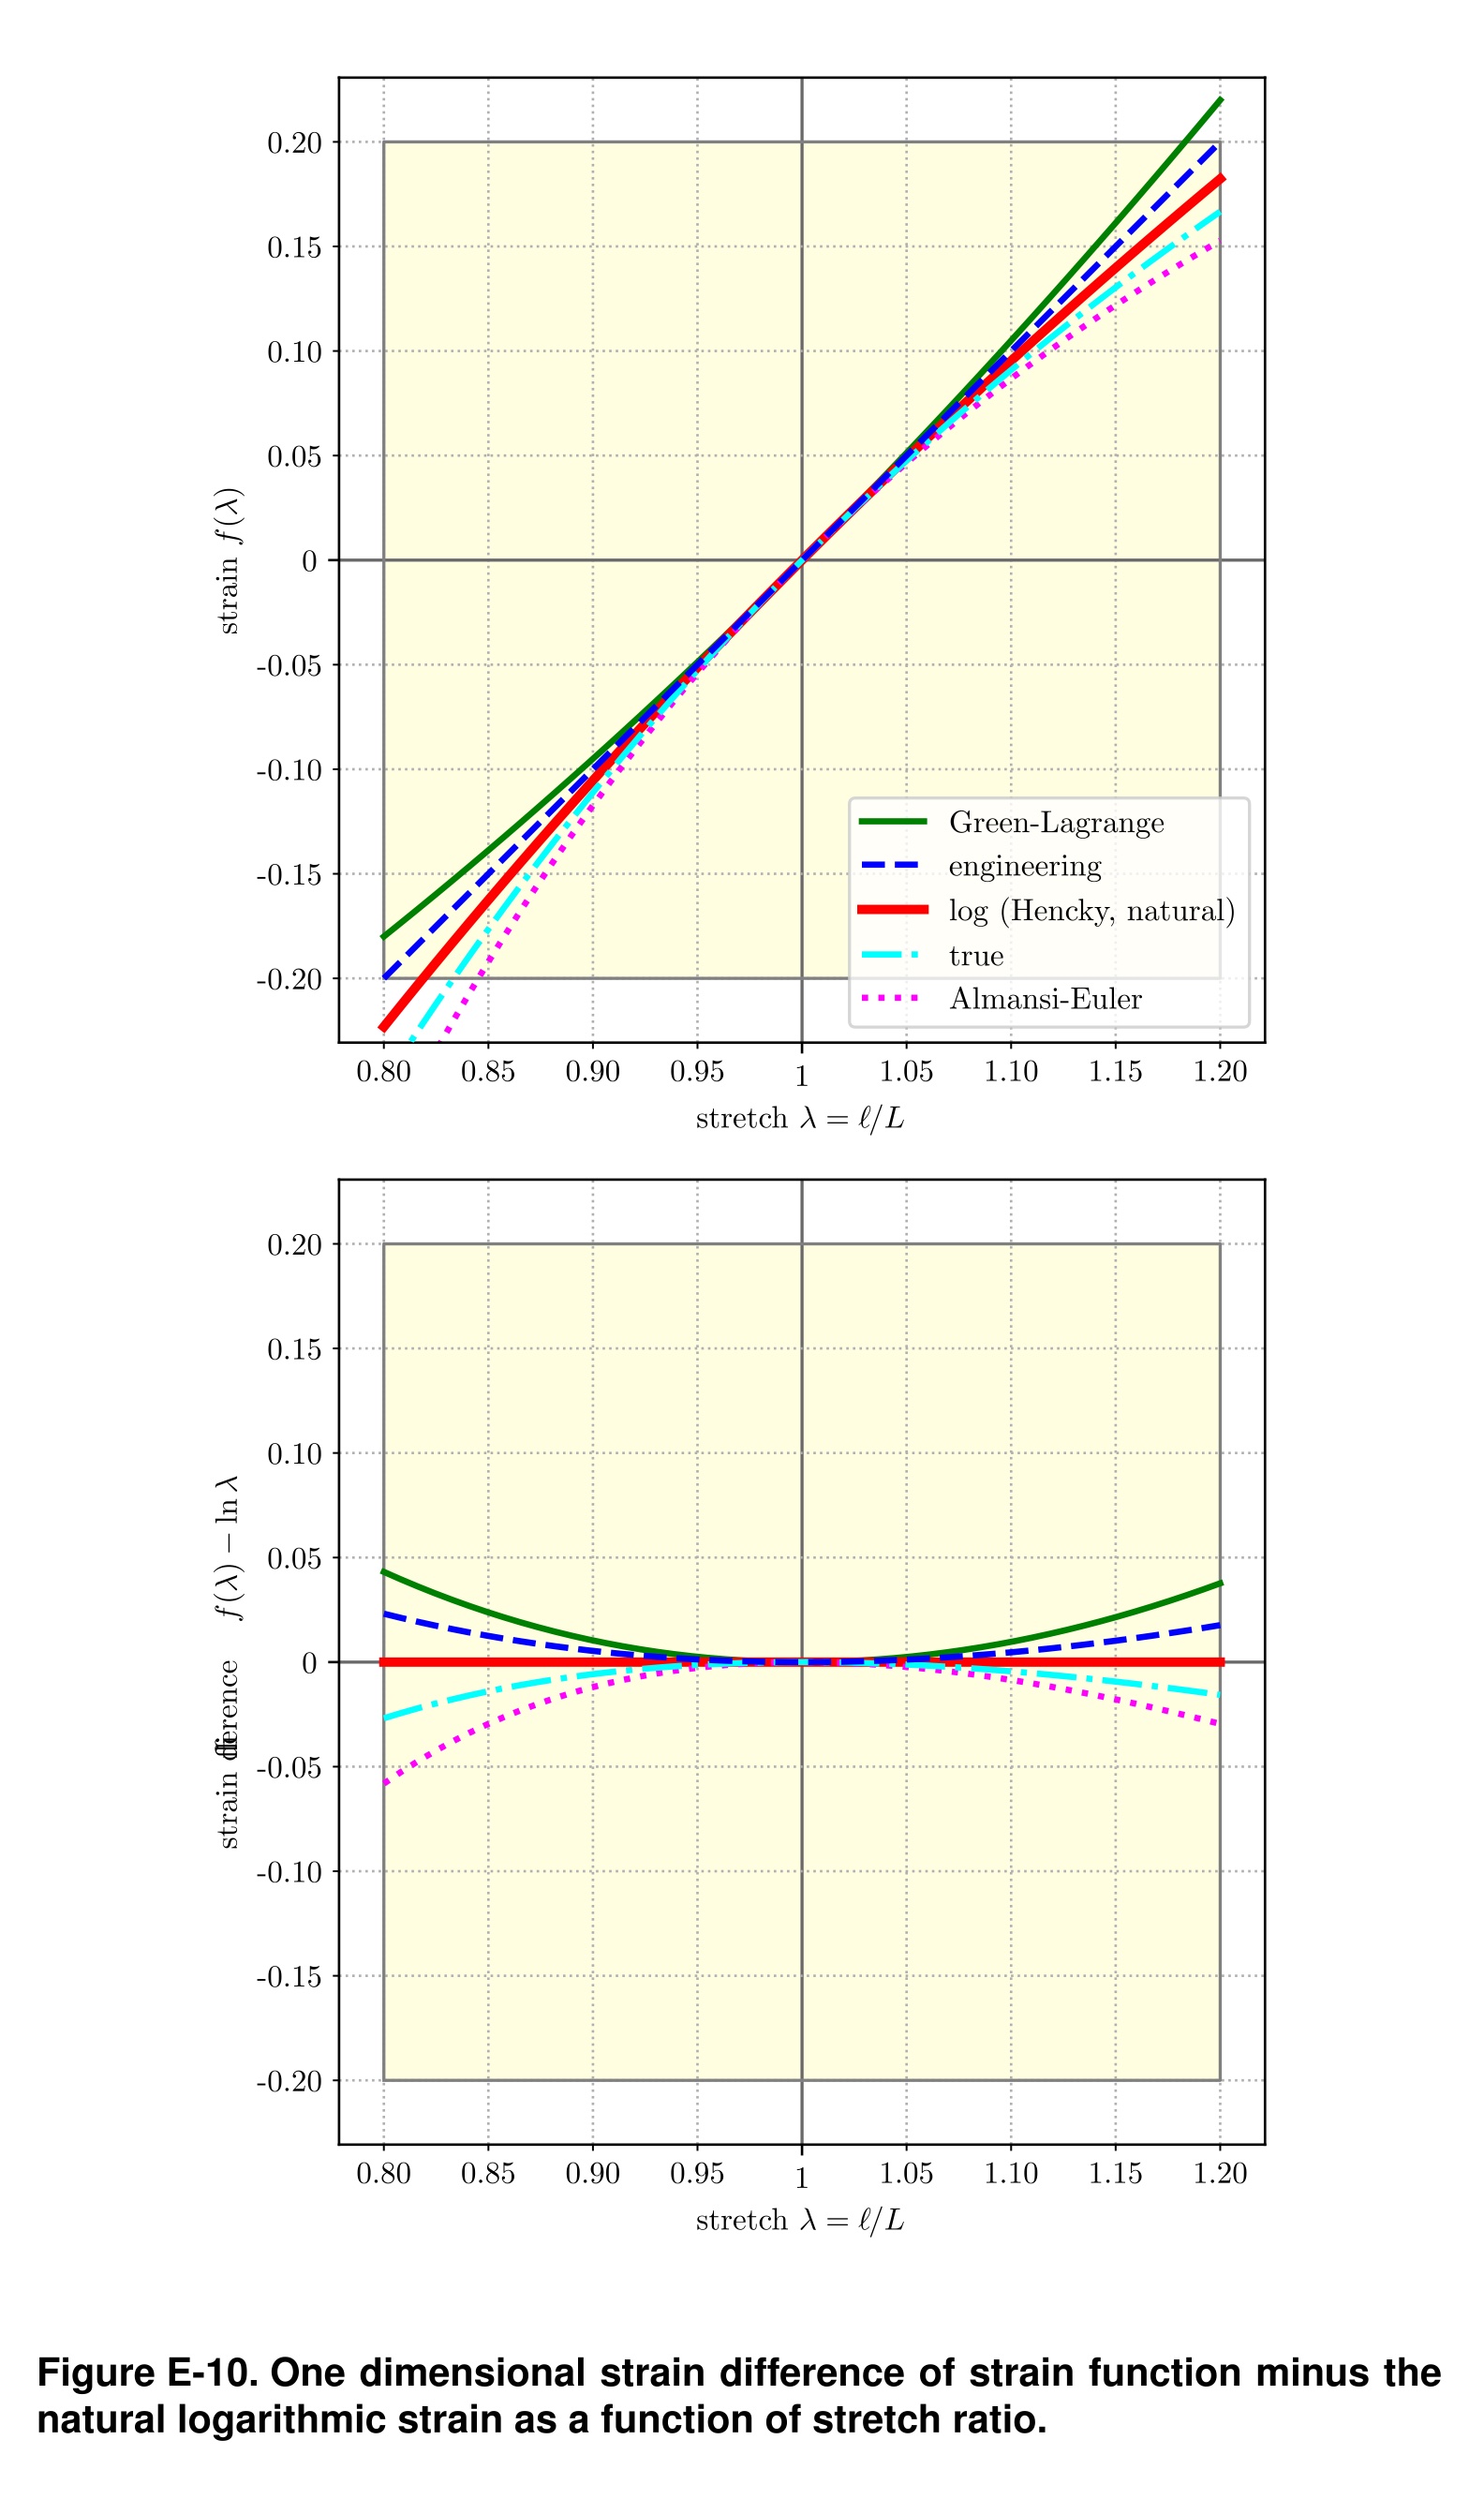
Source: Terpsma et al.3
Strain Tensors and Finite Rotations
Because it takes on nonzero values under finite rotation, the linearized strain tensor should not be used for geometrically nonlinear analysis. These nonzero values are completely artificial and strictly a result of using a linear strain definition with geometrically nonlinear motions. This result is shown as follows.
Let be a two-dimensional, rigid body rotation parameterized by time and scaled by constant radians per second. Then, the motion of a body can be written as
Then the deformation gradient is a function of time alone,
The linearized strain tensor is found to be
Now, for small angles, , which is for small deviations , , then for rigid body rotations. However, for arbitrary finite angles, , and the linearized strain tensor reports nonzero strain for rigid body rotations, which is nonsensical.
A correct strain tensor will report zero strain for rigid body rotations. One such strain tensor is the fully nonlinear Green-Lagrange strain tensor. This result is shown as follows:
Polar Decomposition
Given the rotation tensor , the material stretch tensor , and the spatial stretch tensor , the deformation gradient has the multiplicative decomposition,
Here we have a slight abuse of notation, where intermediate configurations that have stretched but not yet rotated are denoted with capital letter indices. Thus the "" subscript in is an intermediate stretched but non-rotated configuration.
The stretch tensors and are both symmetric and positive definite. The rotation tensor is non-symmetric and orthogonal. The figure below shows the polar decomposition about a material point and fibers in its vicinity mapped to the spatial point with the same fibers mapped to .
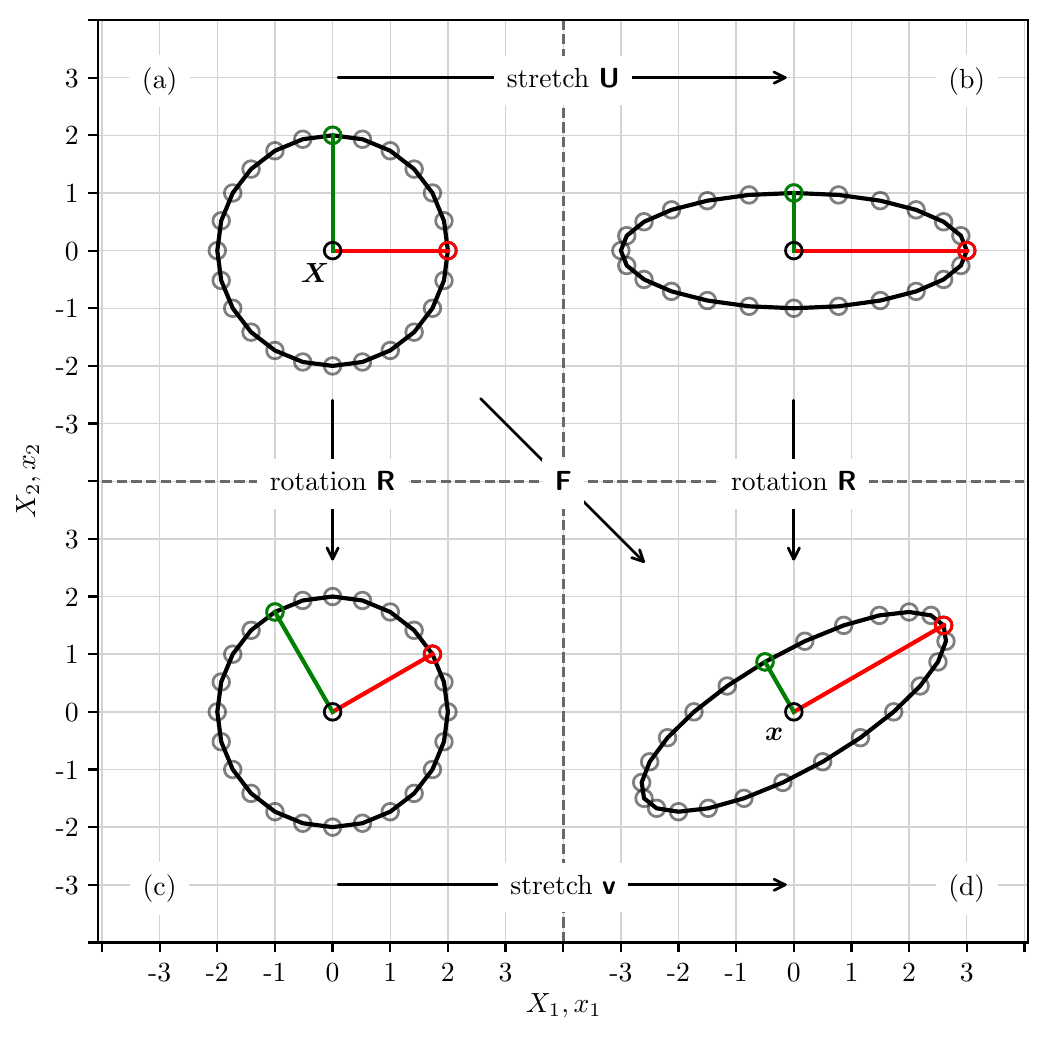
polar_decomposition.py.
Principal Stretches and Axes
The stretch tensors and have the same eigenvalues, , called principal stretches. For non-trivial rotations, i.e. , and have unique eigenvectors, called principal stretch directions. The principal stretch directions of are . The principal stretch directions of are . The two sets of eigenvectors are related through rotation ,
or generally,
Spectral Representation
The deformation gradient, its polar decomposition, and the Cauchy-Green deformations have spectral decompositions in terms of the principal stretches and stretch directions,
The Green-Lagrange strain tensor and the Almansi-Euler strain tensor , in principal stretches and stretch directions, are
The generalization of the Seth-Hill material strain tensor and spatial strain tensor , in principal stretches and stretch directions, are
and the relationship between the two strain tensors is given through a rotation transformation,
In the case when , the material and spatial logarithmic strain tensors, also known as the Hencky material and spatial strain tensors, and , are obtained as6
Two concrete illustrations follow: Rigid Body Motion works through pure translation as the simplest possible deformation, and Simple Shear works through an isochoric shear in closed form, computing , , , , and explicitly.
-
Note that , while typically zero, may be any real number less than . ↩
-
Technically, can be any real number, not just an integer. ↩
-
Terpsma RJ, Hovey CB. Blunt impact brain injury using cellular injury criterion. Sandia National Lab. (SNL-NM), Albuquerque, NM (United States); 2020 Oct 1. link ↩ ↩2
-
Neff, P. (2013). The Hencky strain measure is the geodesic distance to SO(), at 6. ↩
-
The Bažant strain, , not considered here, also satisfies . ↩
-
See Xiao H, Bruhns OT, Meyers A. Hypo-elasticity model based upon the logarithmic stress rate. Journal of Elasticity. 1997 Apr 1;47(1):51-68, at page 54, Eq. (2.2). ↩
Rigid Body Motion
Translation
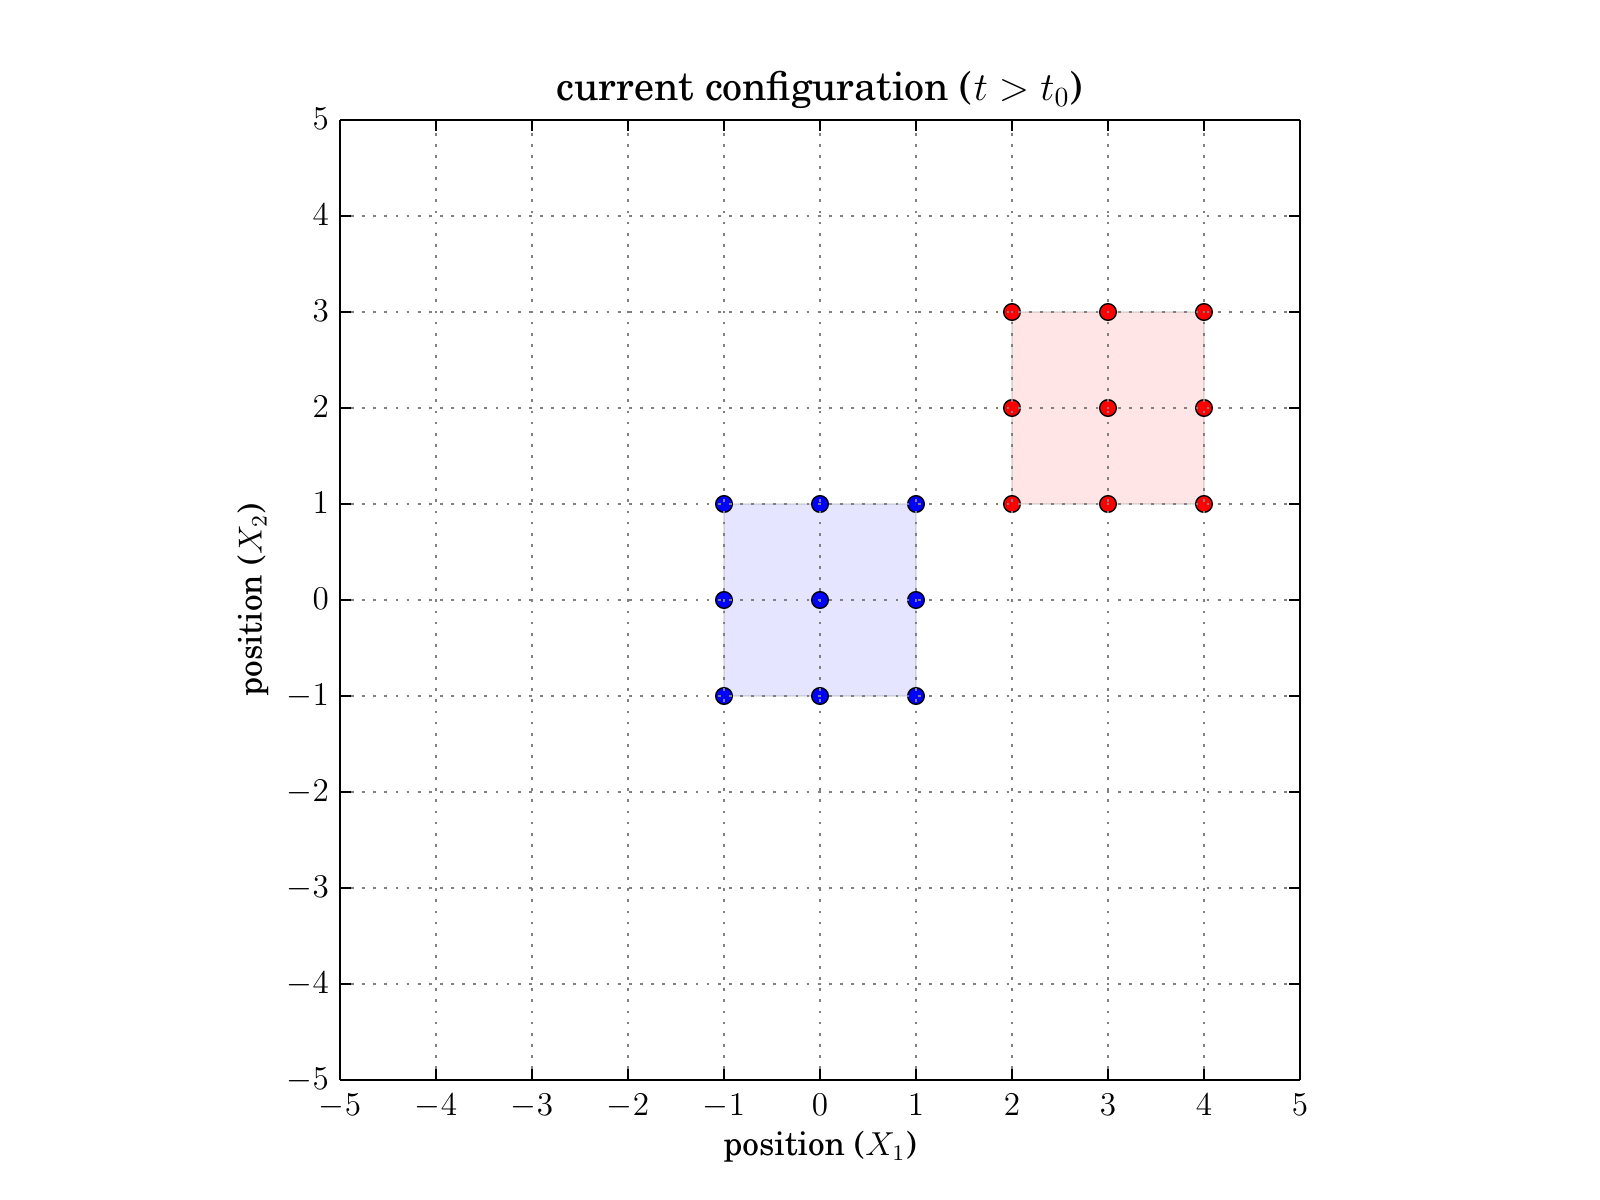
A translation is a homogeneous deformation of the form
This deformation occurs when the displacement is a constant , and thus not a function of reference position or time .
For the concrete example in the figure below, let . In this case, we see the placement moves right and up on the page, relative to the reference configuration , by an amount of 3 and 2, respectively. The reference configuration is shown in blue. The current configuration is shown in red.
Simple Shear
Note: The source code for this section is listed below.
In this section, we cover simple shear, a deformation that illustrates several concepts without being too complicated. That said, we will find that simple shear isn't quite as trivial as its name would suggest. In fact, a paper titled Simple shear is not so simple1 reviews some details not discussed here.
The figure below illustrates simple shear, with relative motion of planes normal to the vertical axis. For all configurations (reference and current):
- Horizontal fibers remain horizontal.
- The length of horizontal fibers remains constant.
- The vertical distance between the horizontal fibers remains constant.
- The body's volume is constant. The deformation is isochoric since .
The relative motion is characterized by the non-dimensional ratio of length per unit height, where . The angle, , subtended by simple shear is . In the limit as , the shear angle . For small values of , the small-angle assumption is valid, with .
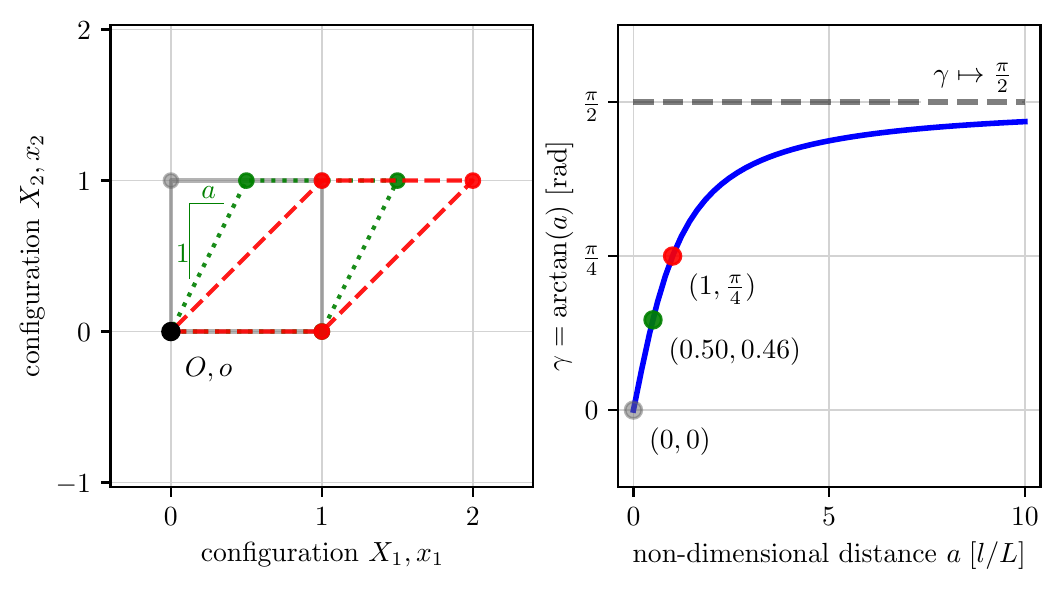
Source: simple_shear.py
Rate-Independent Form
The simple shear deformation in rate-independent form is
The deformation gradient is
Note that the volume remains constant for all deformations since . The deformation thus belongs to the group of isochoric motions. The right Cauchy-Green strain, , in simple shear, is
The principal directions of are given with the three eigenvectors and their respective eigenvalues ,
For simple shear, the eigenvalues of and their corresponding eigenvectors, satisfying , are
The Green-Lagrange strain, , in simple shear is
The left Cauchy-Green strain, , (and its inverse), in simple shear, are
The Almansi-Euler strain, , for simple shear is
Source
simple_shear.py
"""Demonstrate simple shear deformation of a square body."""

from typing import Tuple
import os
import numpy as np
from numpy.typing import NDArray

from matplotlib import rc
import matplotlib.pyplot as plt
from matplotlib.ticker import MultipleLocator

rc("text", usetex=True)
# rc('font', **{'family': 'serif', 'serif': ['Computer Modern Roman']})
rc("font", family="serif")


def rotate(x0: NDArray, y0: NDArray, rotation: float) -> Tuple[NDArray, NDArray]:
    """Given list of reference points (x0, y0), rotate them about the
    z-axis by rotation angle (radians) to the current points (x1, y1).
    """
    x1 = np.cos(rotation) * x0 - np.sin(rotation) * y0
    y1 = np.sin(rotation) * x0 + np.cos(rotation) * y0
    return x1, y1


def simple_shear(x0: NDArray, y0: NDArray, shear: float) -> Tuple[NDArray, NDArray]:
    """Given a list of reference points (x0, y0), simple shear them in
    the x-axis by distance shear_x (Length) to the current points (x1, y1).
    """
    x1 = x0 + shear * y0
    y1 = y0
    return x1, y1


def draw_shape(
    axis,
    xs: np.ndarray,
    ys: np.ndarray,
    color: str = "dimgray",
    linestyle: str = "-",
    alpha: float = 1.0,
):
    """Draw the body and points."""

    # Draw body outline
    axis.plot(
        xs,
        ys,
        color=color,
        linestyle=linestyle,
        alpha=alpha,
    )  # body outline

    # Plot points on the body
    axis.plot(xs, ys, "o", color=color, markersize=5, alpha=alpha)


SHOW = False
SAVE = True

fig = plt.figure(figsize=(6, 3))  # inches, (wide, tall)
ax1 = fig.add_subplot(1, 2, 1)
ax2 = fig.add_subplot(1, 2, 2)

# Subfigure 1

OFFSET_X = 0
OFFSET_Y = 0
RADTODEG = 180.0 / np.pi
DEGTORAD = 1.0 / RADTODEG

# Defined reference configuration path, in a closed circle
xs_0 = np.array([0, 1, 1, 0, 0])
ys_0 = np.array([0, 0, 1, 1, 0])

# Draw reference shape
draw_shape(axis=ax1, xs=xs_0, ys=ys_0, color="dimgray", linestyle="-", alpha=0.5)

# Draw first sheared shape
SHEAR_1 = 0.5
(xs_1, ys_1) = simple_shear(xs_0, ys_0, shear=SHEAR_1)
draw_shape(axis=ax1, xs=xs_1, ys=ys_1, color="green", linestyle=":", alpha=0.9)

# Draw second sheared shape
SHEAR_2 = 1.0
(xs_2, ys_2) = simple_shear(xs_0, ys_0, shear=SHEAR_2)
draw_shape(axis=ax1, xs=xs_2, ys=ys_2, color="red", linestyle="--", alpha=0.9)

# Draw origin point
ax1.plot(0, 0, "o", color="black", label="origin = (0, 0, 0)")
# Draw origin label
ax1.text(0.25, -0.25, r"$O, o$", ha="center", va="center")

# Draw 1:a rise over run lines
SCALE = 0.90  # scale
HAIRLINE_OFFSET_Y = 0.1
epsx, epsy = 0.125, 0.25 + HAIRLINE_OFFSET_Y
slope_x, slope_y = np.array([0, 0, 0.25]) * SCALE, np.array([0, 0.5, 0.5])
ax1.plot(slope_x + epsx, slope_y + epsy, lw=0.5, color="green")
ax1.text(0.125, 0.5, "1", color="green", ha="right", va="center")
ax1.text(0.25, 0.88, r"$a$", color="green", ha="center")


# SHEAR_12 = 0.5  # Length units, shear in the X_1 direction
# draw(ax1, ux=OFFSET_Y, uy=OFFSET_Y, ur=dr, shear=SHEAR_12, t0=False, c="green", ls=":")

# SHEAR_12 = 1.0  # Length units, shear in the X_1 direction, larger shear
# draw(ax1, ux=OFFSET_X, uy=OFFSET_X, ur=dr, shear=SHEAR_12, t0=False, c="red", ls="--")


ax1.axis("equal")
# ax2.axis('equal')
# major axes
ax1.xaxis.set_major_locator(MultipleLocator(1.0))
ax1.yaxis.set_major_locator(MultipleLocator(1.0))
ax2.xaxis.set_major_locator(MultipleLocator(1.0))
ax2.yaxis.set_major_locator(MultipleLocator(1.0))
# minor axes
# ax1.xaxis.set_minor_locator(MultipleLocator(0.5))
# ax1.yaxis.set_minor_locator(MultipleLocator(0.5))

ax1.grid(
    visible=True, which="major", linestyle="solid", linewidth=0.5, color="lightgray"
)  # FIX APPLIED HERE
ax2.grid(
    visible=True, which="major", linestyle="solid", linewidth=0.5, color="lightgray"
)  # FIX APPLIED HERE
#
# ax.grid(b=True, which='minor', linestyle=':')
ax1.set_xlabel(r"configuration $X_1, x_1$")
ax1.set_ylabel(r"configuration $X_2, x_2$")

# Subfigure 2

X_MIN = 0
X_MAX = 10
epsx, epsy = 0.4, np.pi / 16
x = np.linspace(X_MIN, X_MAX)
y = np.arctan(x)
ax2.plot(x, y, linewidth=2, color="blue")
ax2.text(
    X_MAX - epsx,
    np.pi / 2 + epsy / 2,
    r"$\gamma \mapsto \frac{\pi}{2}$",
    ha="right",
    backgroundcolor="white",
)
ax2.plot(
    [X_MIN, X_MAX],
    np.pi / 2 * np.array([1, 1]),
    lw=2,
    alpha=0.5,
    color="black",
    linestyle="--",
    zorder=4,
)

ax2.plot(0, 0, "o", color="dimgray", alpha=0.5, zorder=4)
ax2.text(0 + epsx, 0 - epsy, r"$(0, 0)$", backgroundcolor="white")

ax2.plot(0.5, 0.46, "o", color="green", alpha=0.9, zorder=4)
ax2.text(0.50 + epsx, 0.46 - epsy, r"$(0.50, 0.46)$", backgroundcolor="white")

ax2.plot(1, np.pi / 4, "o", color="red", alpha=0.9, zorder=4)
ax2.text(1 + epsx, np.pi / 4 - epsy, r"$(1, \frac{\pi}{4})$", backgroundcolor="white")

ax2.set_xlabel(r"non-dimensional distance $a\;[l/L]$")
ax2.set_ylabel(r"$\gamma = \arctan(a)$ [rad]")
# https://matplotlib.org/3.1.1/gallery/ticks_and_spines/tick-locators.html
# ax2.xaxis.set_major_locator(ticker.FixedLocator([0, 5, 10]))
ax2.set_xticks([0, 5, 10])
ax2.set_yticks([0, np.pi / 4, np.pi / 2])
ax2.set_yticklabels(["0", r"$\frac{\pi}{4}$", r"$\frac{\pi}{2}$"])

ax1.set_xlim(-epsx, 2 + epsx)
ax2.set_xlim(0 - epsx, X_MAX + epsx)
eps = np.pi / 8
ax2.set_ylim(0 * np.pi / 4 - eps, np.pi / 2 + eps)

if SHOW:
    plt.show()

if SAVE:
    script_name = os.path.basename(__file__)
    figure_name = os.path.splitext(script_name)[0]
    print(f"Saving figure as {figure_name}.pdf")
    fig.savefig(figure_name + ".pdf", bbox_inches="tight")
References
-
Destrade M, Murphy JG, Saccomandi G. Simple shear is not so simple. International Journal of Non-Linear Mechanics. 2012 Mar 1;47(2):210-4. download ↩
Finite Element Method
A finite element mesh is a collection of nodes (points) connected into elements — small regions used to interpolate a quantity of interest (e.g. displacement) across the whole domain. Multi-Point Motion (covered later in this book) builds exactly this kind of nodal point collection and, in Tracking the Grid, tracks every one of its 12 points to its current position — exactly the per-node displacement data a mesh needs to represent how an object deformed.
Kernel Size First also covers the kernel-size-versus-point-spacing tradeoff involved in getting that per-node data reliably — the same considerations apply whether the points come from a toy grid or a real mesh.
Once every node's current position is known, an actual finite element mesh still needs one more thing this page doesn't provide: element connectivity — which nodes join together into which elements. Building that connectivity is future work, not implemented here; what this page covers below is the element formulation that connectivity would plug into — shape functions, strain, and deformation gradient, for the four-node quadrilateral element.
Four-Noded Quadrilateral Finite Element (Q4)
The four-node quadrilateral element is one of the most commonly used elements in 2D FEA. It has four corner nodes, with each node having two degrees of freedom (DOFs): displacements in the and directions.
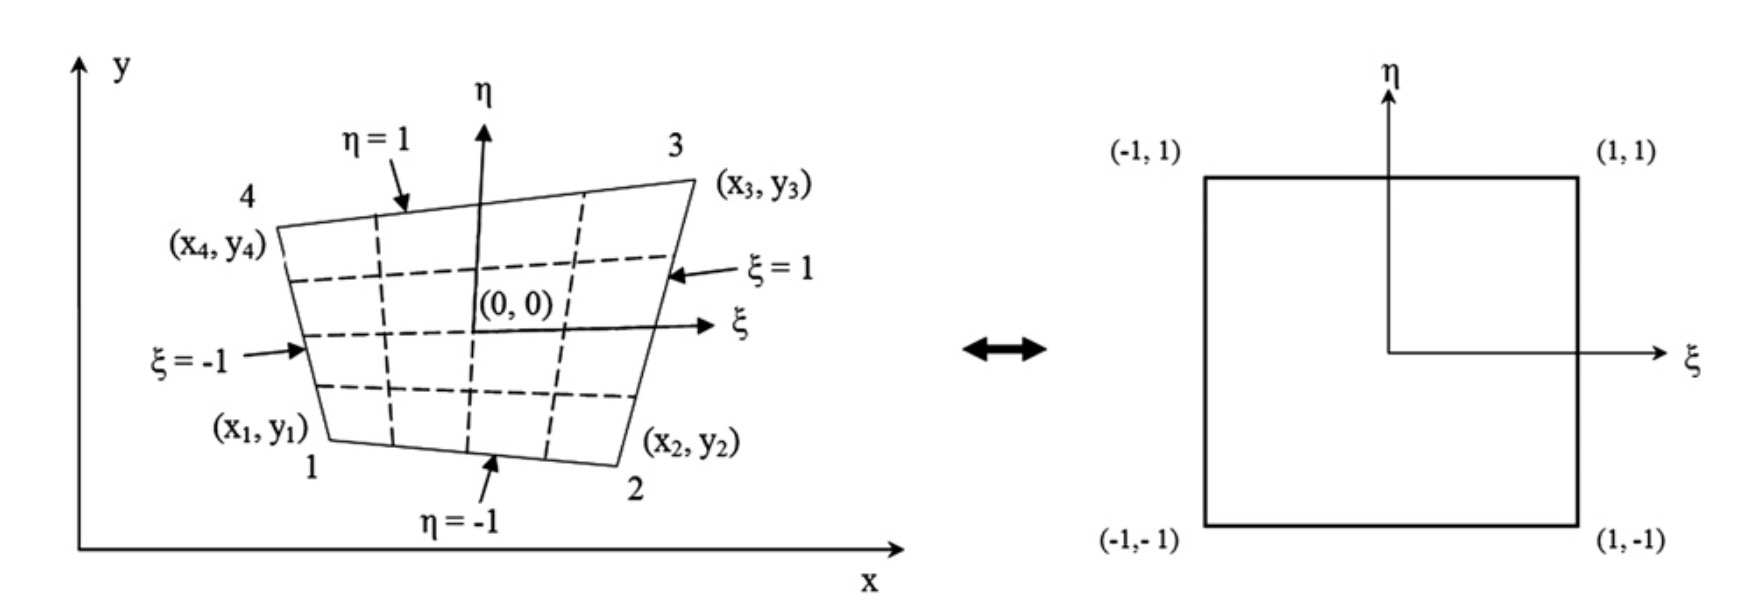
Image credit: James et al.1
Note: Since we are using a finite deformation continuum mechanics framework, we will use and (instead of and in the James et al. figure above).
Shape Functions
For the element in local coordinates , the bilinear shape functions are defined:
The shape functions satisfy the following properties:
- Kronecker delta property: (equals 1 at node , 0 at other nodes)
- Partition of unity: for all
Local Coordinates
The key concept in finite element analysis is the isoparametric mapping between the local coordinate system and the global coordinate system.
This mapping allows:
- Integration to be performed on the local domain (parent element)
- Handling of arbitrarily shaped quadrilaterals
- Use of the same shape functions for geometry and displacement (isoparametric concept)
The isoparametric coordinates range from to in both the and directions.
The mapping between global coordinates and local coordinates is introduced as a linear combination of local shape functions :
where is the position of node , and .
Shape Function Derivatives in Local Coordinates
The derivatives with respect to the local coordinate system are
These are assembled into a matrix:
Jacobian Matrix
The Jacobian matrix relates derivatives in local coordinates to derivatives in global coordinates. It is important to include the "matrix" part of "Jacobian matrix". It is distinct from the Jacobian of the Deformation Gradient , which is a scalar value (not a matrix). For nodal coordinates organized as:
the Jacobian matrix is computed as:
The individual components (dropping the reference configuration notation to avoid subscript confusion) are:
Shape Function Derivatives in Global Coordinates
The transformation from local to global coordinate derivatives requires the inverse Jacobian matrix through the chain rule. Since
then
In matrix form for all shape functions:
where:
Displacement Field
The displacement is defined as the difference between the current configuration and the reference configuration ,
The displacement field within the element is interpolated using shape functions:
where is the respective displacement of node , and .
Displacement Gradient
Each component is computed using the chain rule:
In compact matrix notation:
where is the nodal displacement matrix:
See Displacement Gradient for more information.
Deformation Gradient
The deformation gradient tensor maps material points in the reference configuration to their positions in the current (deformed) configuration :
Because ,
Explicitly:
The determinant represents the local volume ratio and must be positive for physically admissible deformations. See Deformation Gradient and Jacobian of the Deformation Gradient for more information.
Gauss Points
To evaluate quantities that depend on the displacement field and its gradient, such as strain, we use Gaussian Quadrature. We don't typically calculate quantities at the nodes. Rather, we quantify strain at specific integration points (also known as Gauss points) where mathematical precision is the highest.
For a 2D quadrilateral element, we typically use a Gauss rule. The integration points are located in the local coordinate system at
References
-
James KA, Lee E, Martins JR. Stress-based topology optimization using an isoparametric level set method. Finite Elements in Analysis and Design. 2012 Oct 1;58:20-30. link ↩
Image Generation
The source for the commands on this page is
dictk's ownrosta,checkerboard, andastronautsubcommands — seedictk --help.
Note: the images embedded on this page are rendered as PNG (
--format png), notdictk's default TIFF. Browsers don't natively render TIFF in<img>tags, so a TIFF embedded here simply wouldn't display.Among the alternatives, PNG also wins on its own merits: it is lossless, whereas JPG's compression tends to smear hard edges and speckle-pattern detail (for the 200x200 checkerboard on this page: TIFF 40,256 bytes, JPG 6,760 bytes, PNG only 418 bytes — JPG is actually larger than PNG here, because its block-based compression is a poor fit for hard-edged content like a checkerboard). SVG doesn't help either: since there's no vector structure to trace,
dictk's SVG output just wraps that same PNG in a base64-encoded XML container, which comes out to 809 bytes here — roughly double the raw PNG for no rendering benefit.TIFF remains
dictk's command-line default, since it's the lossless, uncompressed format conventionally used for DIC and other scientific-imaging workflows.
CLI vs. API: the Command Line Interface (CLI) subcommands on this page (
dictk rosta,dictk checkerboard,dictk astronaut) write an image file to disk — that's their whole job. The corresponding Python functions,dictk.rosta,dictk.checkerboard, anddictk.astronaut, take the same parameters but perform no file I/O: they return a NumPy array only. That keeps the Python API composable in a functional style — arrays can be piped through further functions (e.g.combinebelow) before anything touches disk — and callers who do want a file calldictk.image.writeexplicitly, as a separate step. See each function's docstring (rendered in the API reference) for details.
Rosta
We create a synthetic example speckle pattern with the built-in rosta
image generator. It implements the Rosta algorithm described by
Olufsen (Olufsen SN,
Andersen ME, Fagerholt E. muDIC: An open-source toolkit for digital image
correlation. SoftwareX. 2020 Jan 1;11:100391, Algorithm 1, page 6,
repository).
The help text for rosta:
dictk rosta --help
returns
usage: dictk rosta [-h] [--dot-size DOT_SIZE] [--density DENSITY]
                   [--smoothness SMOOTHNESS] [--random-seed RANDOM_SEED]
                   [--output OUTPUT] [--format {tiff,png,jpg,svg}]
                   [width] [height]

positional arguments:
  width                 Image width in pixels (int), default: 200.
  height                Image height in pixels (int), default: 200.

options:
  -h, --help            show this help message and exit
  --dot-size DOT_SIZE, -s DOT_SIZE
                        Dot pattern size factor, 0.0 to 100.0 (float),
                        default: 4.0.
  --density DENSITY, -d DENSITY
                        Dot pattern density, 0.0 to 1.0 (float), default:
                        0.32.
  --smoothness SMOOTHNESS, -m SMOOTHNESS
                        Smoothness factor, 0.0 to 100.0 (float), default: 2.0.
  --random-seed RANDOM_SEED, -r RANDOM_SEED
                        Seed for reproducible pattern generation (int),
                        default: 42.
  --output OUTPUT, -o OUTPUT
                        Output directory (path), default: current directory.
  --format {tiff,png,jpg,svg}, -f {tiff,png,jpg,svg}
                        Output image format (str), default: tiff.
Create a synthetic image, 200 by 200 pixels, 50% dot density:
dictk rosta 200 200 --density 0.5 --format png -o .
Saved image: rosta_200w_by_200h_dot_4.0_den_0.5_smo_2.0.png
Note that the file name is automatically chosen based on the input parameters.
The result:
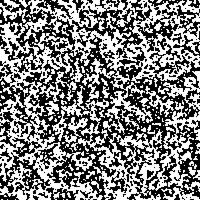
The Python equivalent returns the same pixel data as a NumPy array, with no file written:
import dictk

pattern = dictk.rosta(width=200, height=200, density=0.5)
shape=(200, 200), dtype=uint8
Checkerboard
To make it easier to manually identify discrete points in the speckle
pattern, dictk can also generate a checkerboard test image.
The help text for checkerboard:
dictk checkerboard --help
returns
usage: dictk checkerboard [-h] [--count-x COUNT_X] [--count-y COUNT_Y]
                          [--output OUTPUT] [--format {tiff,png,jpg,svg}]
                          [width] [height]

positional arguments:
  width                 Image width in pixels (int), default: 200.
  height                Image height in pixels (int), default: 200.

options:
  -h, --help            show this help message and exit
  --count-x COUNT_X, -x COUNT_X
                        Number of rectangles along the width (int), default:
                        8.
  --count-y COUNT_Y, -y COUNT_Y
                        Number of rectangles along the height (int), default:
                        8.
  --output OUTPUT, -o OUTPUT
                        Output directory (path), default: current directory.
  --format {tiff,png,jpg,svg}, -f {tiff,png,jpg,svg}
                        Output image format (str), default: tiff.
Create a synthetic image, 200 by 200 pixels:
dictk checkerboard 200 200 --format png -o .
Saved image: checkerboard_200w_by_200h_8x8.png
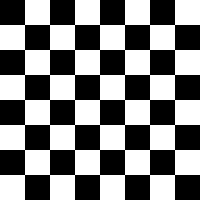
The Python equivalent, again returning an array with no file written:
import dictk

board = dictk.checkerboard(width=200, height=200)
shape=(200, 200), dtype=uint8
Astronaut
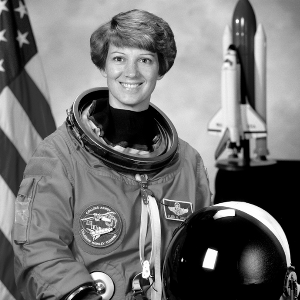
Unlike rosta and checkerboard, which procedurally generate a fresh
synthetic pattern from parameters, astronaut loads a bundled real-world
photograph and converts it to grayscale — useful for exercising dictk's
imaging utilities against something other than a synthetic pattern. The
source is a NASA portrait of astronaut Eileen Collins, from the NASA Great
Images database ("No known copyright restrictions, released into the
public domain."). Its native resolution is 512x512; passing width/
height other than that resizes the source image rather than generating a
new one at that size.
The help text for astronaut:
dictk astronaut --help
returns
usage: dictk astronaut [-h] [--output OUTPUT] [--format {tiff,png,jpg,svg}]
                       [width] [height]

positional arguments:
  width                 Image width in pixels (int), default: 512.
  height                Image height in pixels (int), default: 512.

options:
  -h, --help            show this help message and exit
  --output OUTPUT, -o OUTPUT
                        Output directory (path), default: current directory.
  --format {tiff,png,jpg,svg}, -f {tiff,png,jpg,svg}
                        Output image format (str), default: tiff.
Save it at 300 by 300 pixels — smaller downscales from the native 512x512 start to lose too much detail:
dictk astronaut 300 300 --format png -o .
Saved image: astronaut_300w_by_300h.png
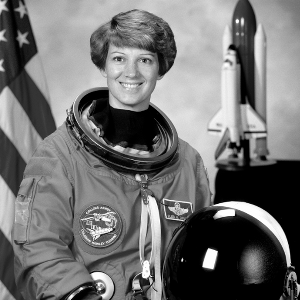
The Python equivalent, again returning an array with no file written:
import dictk

photo = dictk.astronaut(width=300, height=300)
shape=(300, 300), dtype=uint8
Combining into a reference image
combine works on any
two grayscale images of the same shape, so it isn't limited to combining
the two synthetic images below —
Speckle + Astronaut further down combines rosta
with a real photograph instead.
Speckle + Checkerboard
We combine the rosta speckle pattern with the checkerboard into a
reference image checkerboard0 by averaging their pixel values and
normalizing back to uint8:
from dictk.image import combine, read, write

speckle = read(path="rosta_200w_by_200h_dot_4.0_den_0.5_smo_2.0.png")
checker = read(path="checkerboard_200w_by_200h_8x8.png")
checkerboard0 = combine(a=speckle, b=checker)
write(arr=checkerboard0, path="checkerboard0.png")
Saved image: checkerboard0.png
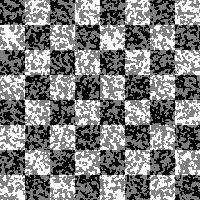
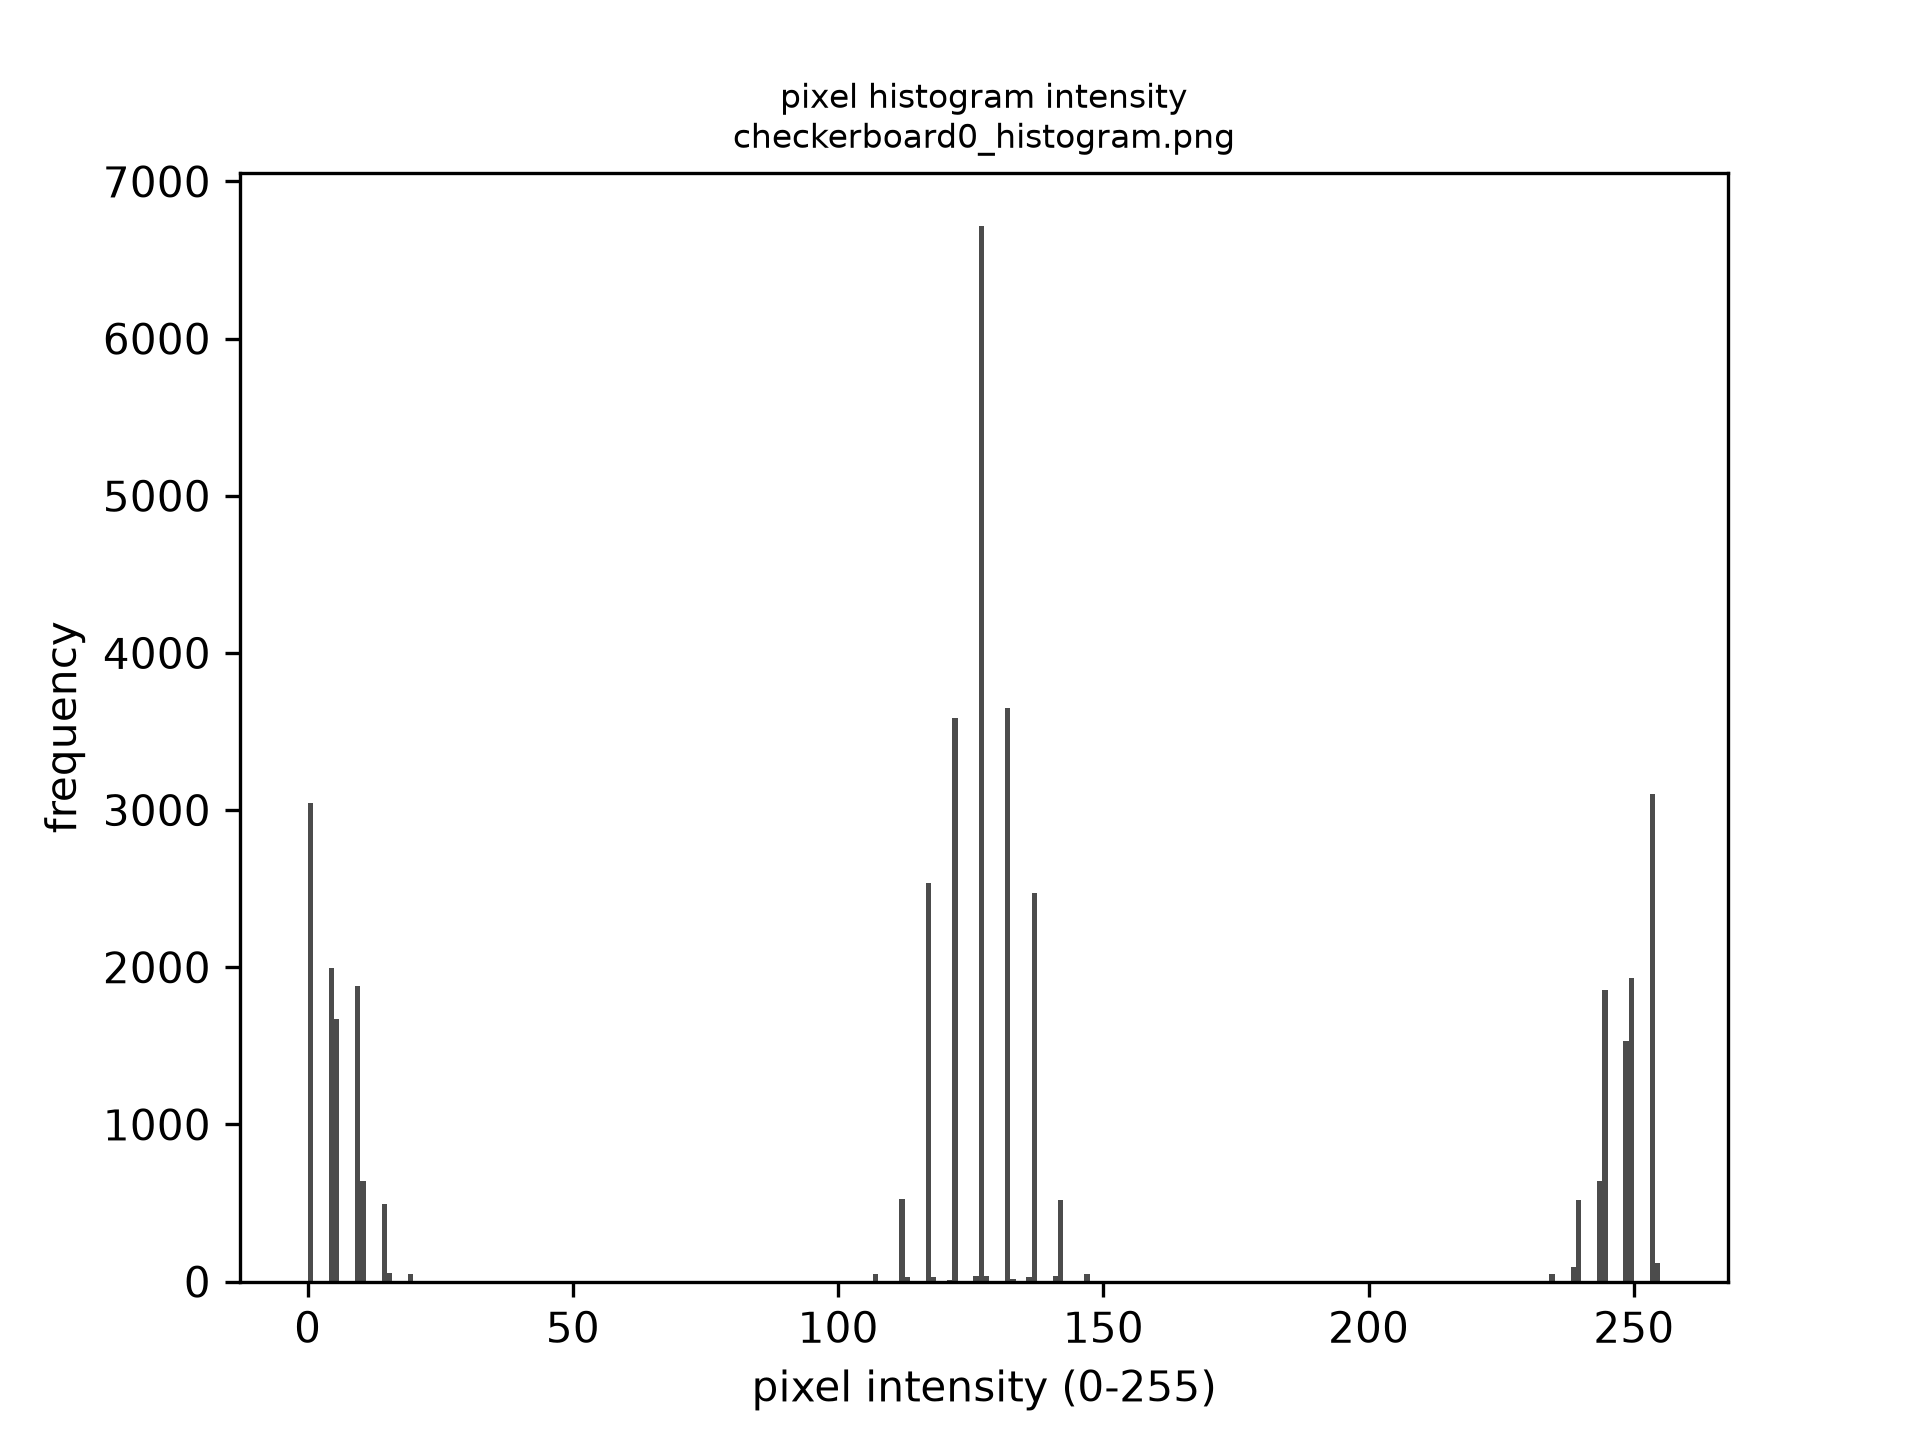
Because both inputs are averaged and rescaled together, the checkerboard's squares stay clearly black or white while the speckle pattern shows up as gray texture within them:
- Where the checkerboard is black, speckle white maps to gray and speckle black stays black.
- Where the checkerboard is white, speckle black maps to gray and speckle white stays white.
That trimodal structure is visible in the pixel-intensity histograms below:
speckle and checkerboard are both roughly bimodal (dark/light), while
checkerboard0 picks up a distinct middle hump from the
black/white-speckle-on-opposite checkerboard combinations.
from dictk.image import read
from dictk.plot import histogram_save

speckle = read(path="rosta_200w_by_200h_dot_4.0_den_0.5_smo_2.0.png")
checker = read(path="checkerboard_200w_by_200h_8x8.png")
checkerboard0 = read(path="checkerboard0.png")

histogram_save(arr=speckle, path="rosta_histogram.png")
histogram_save(arr=checker, path="checkerboard_histogram.png")
histogram_save(arr=checkerboard0, path="checkerboard0_histogram.png")
Saved histograms: rosta_histogram.png, checkerboard_histogram.png, checkerboard0_histogram.png
| rosta | checkerboard | checkerboard0 |
|---|---|---|
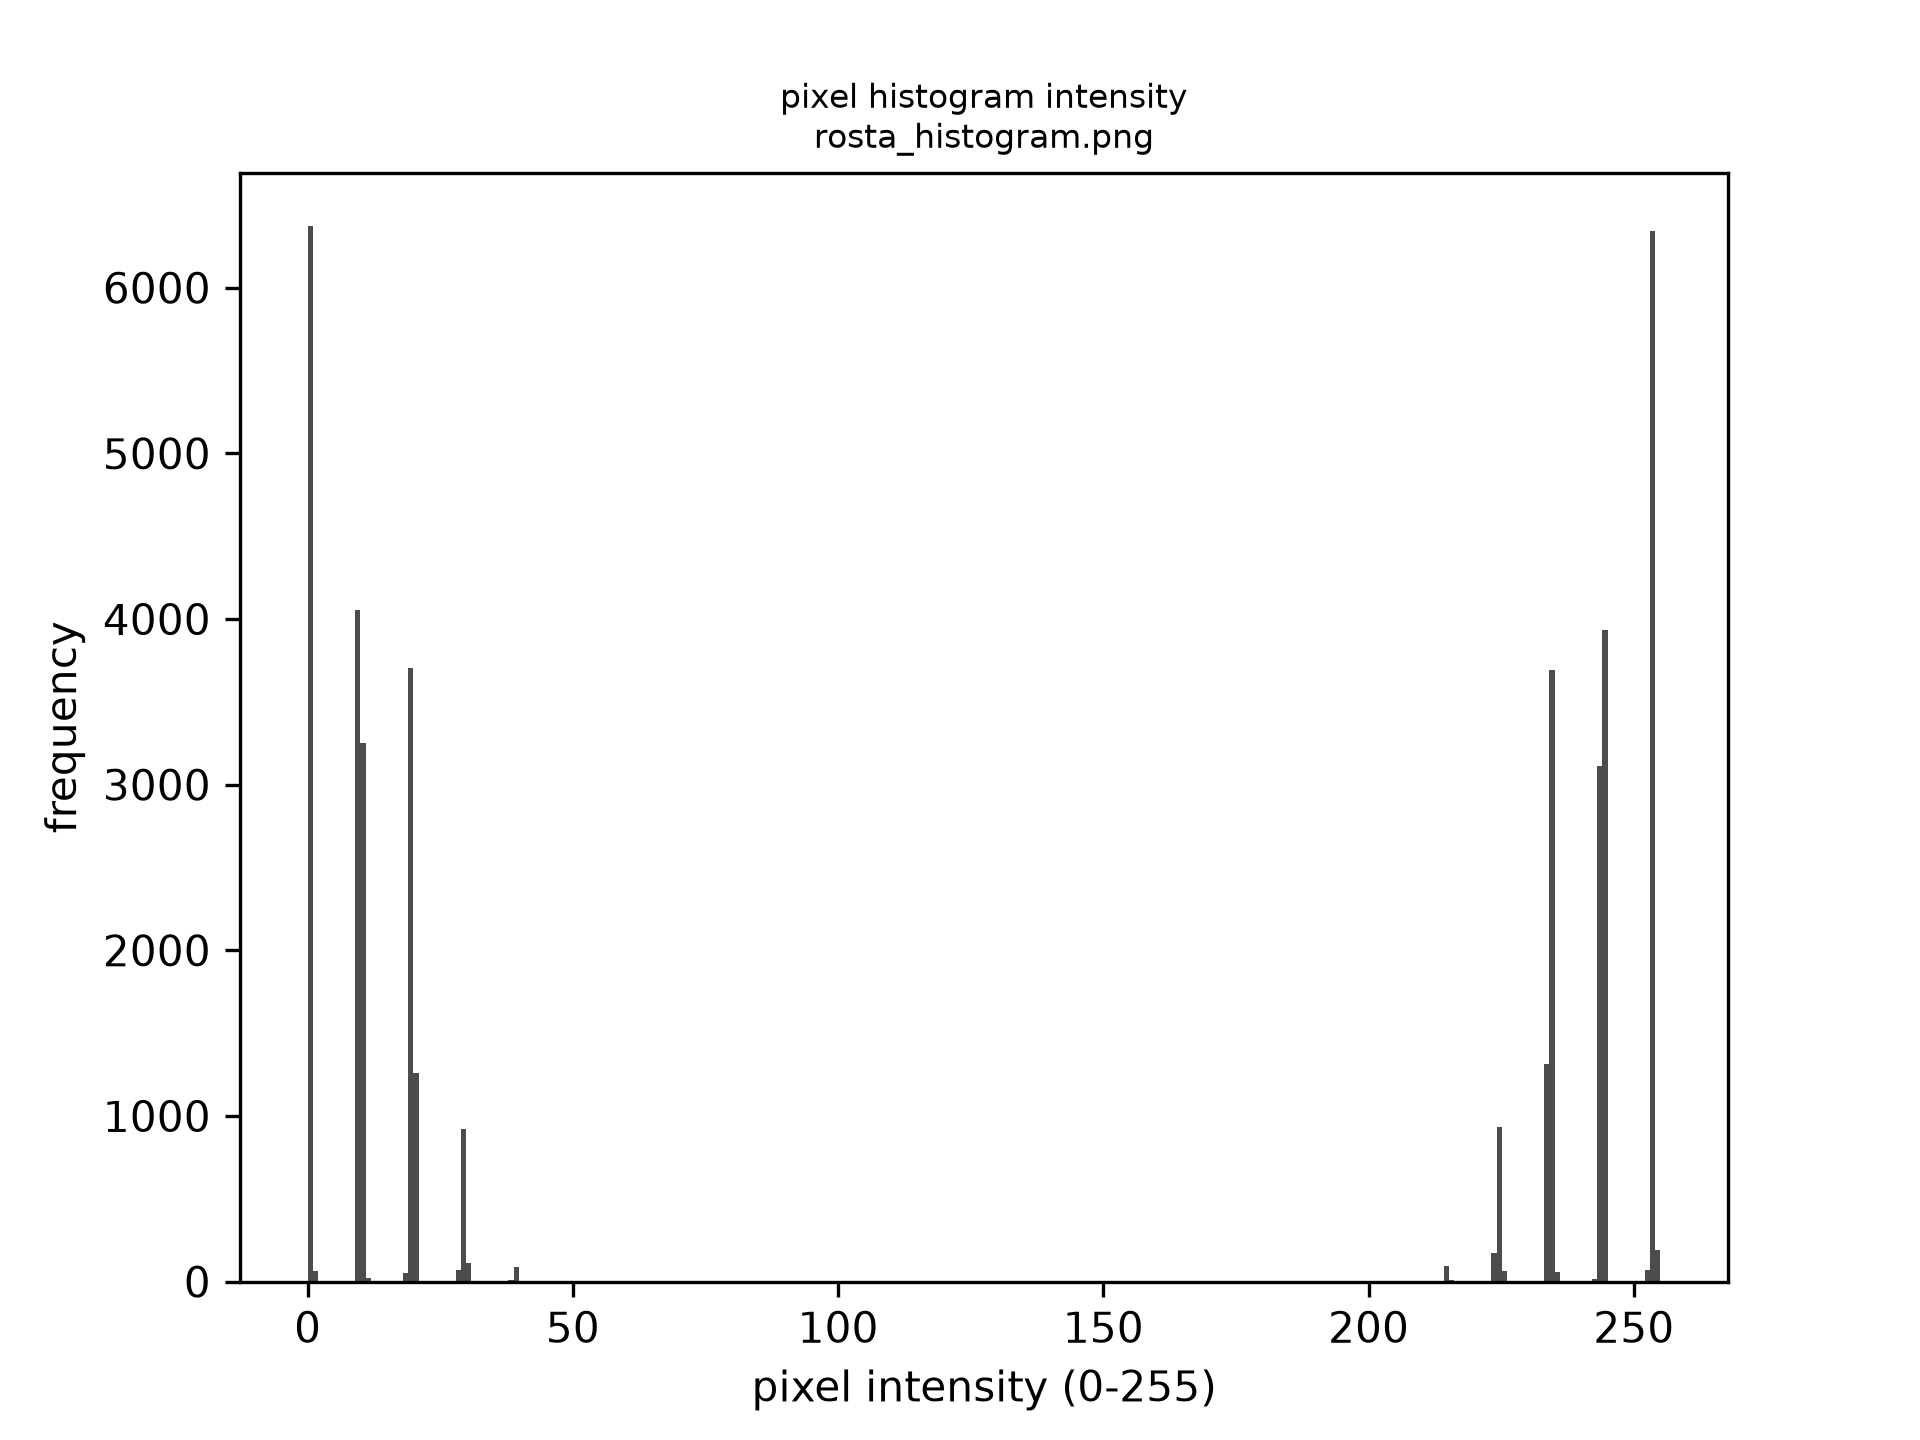 | 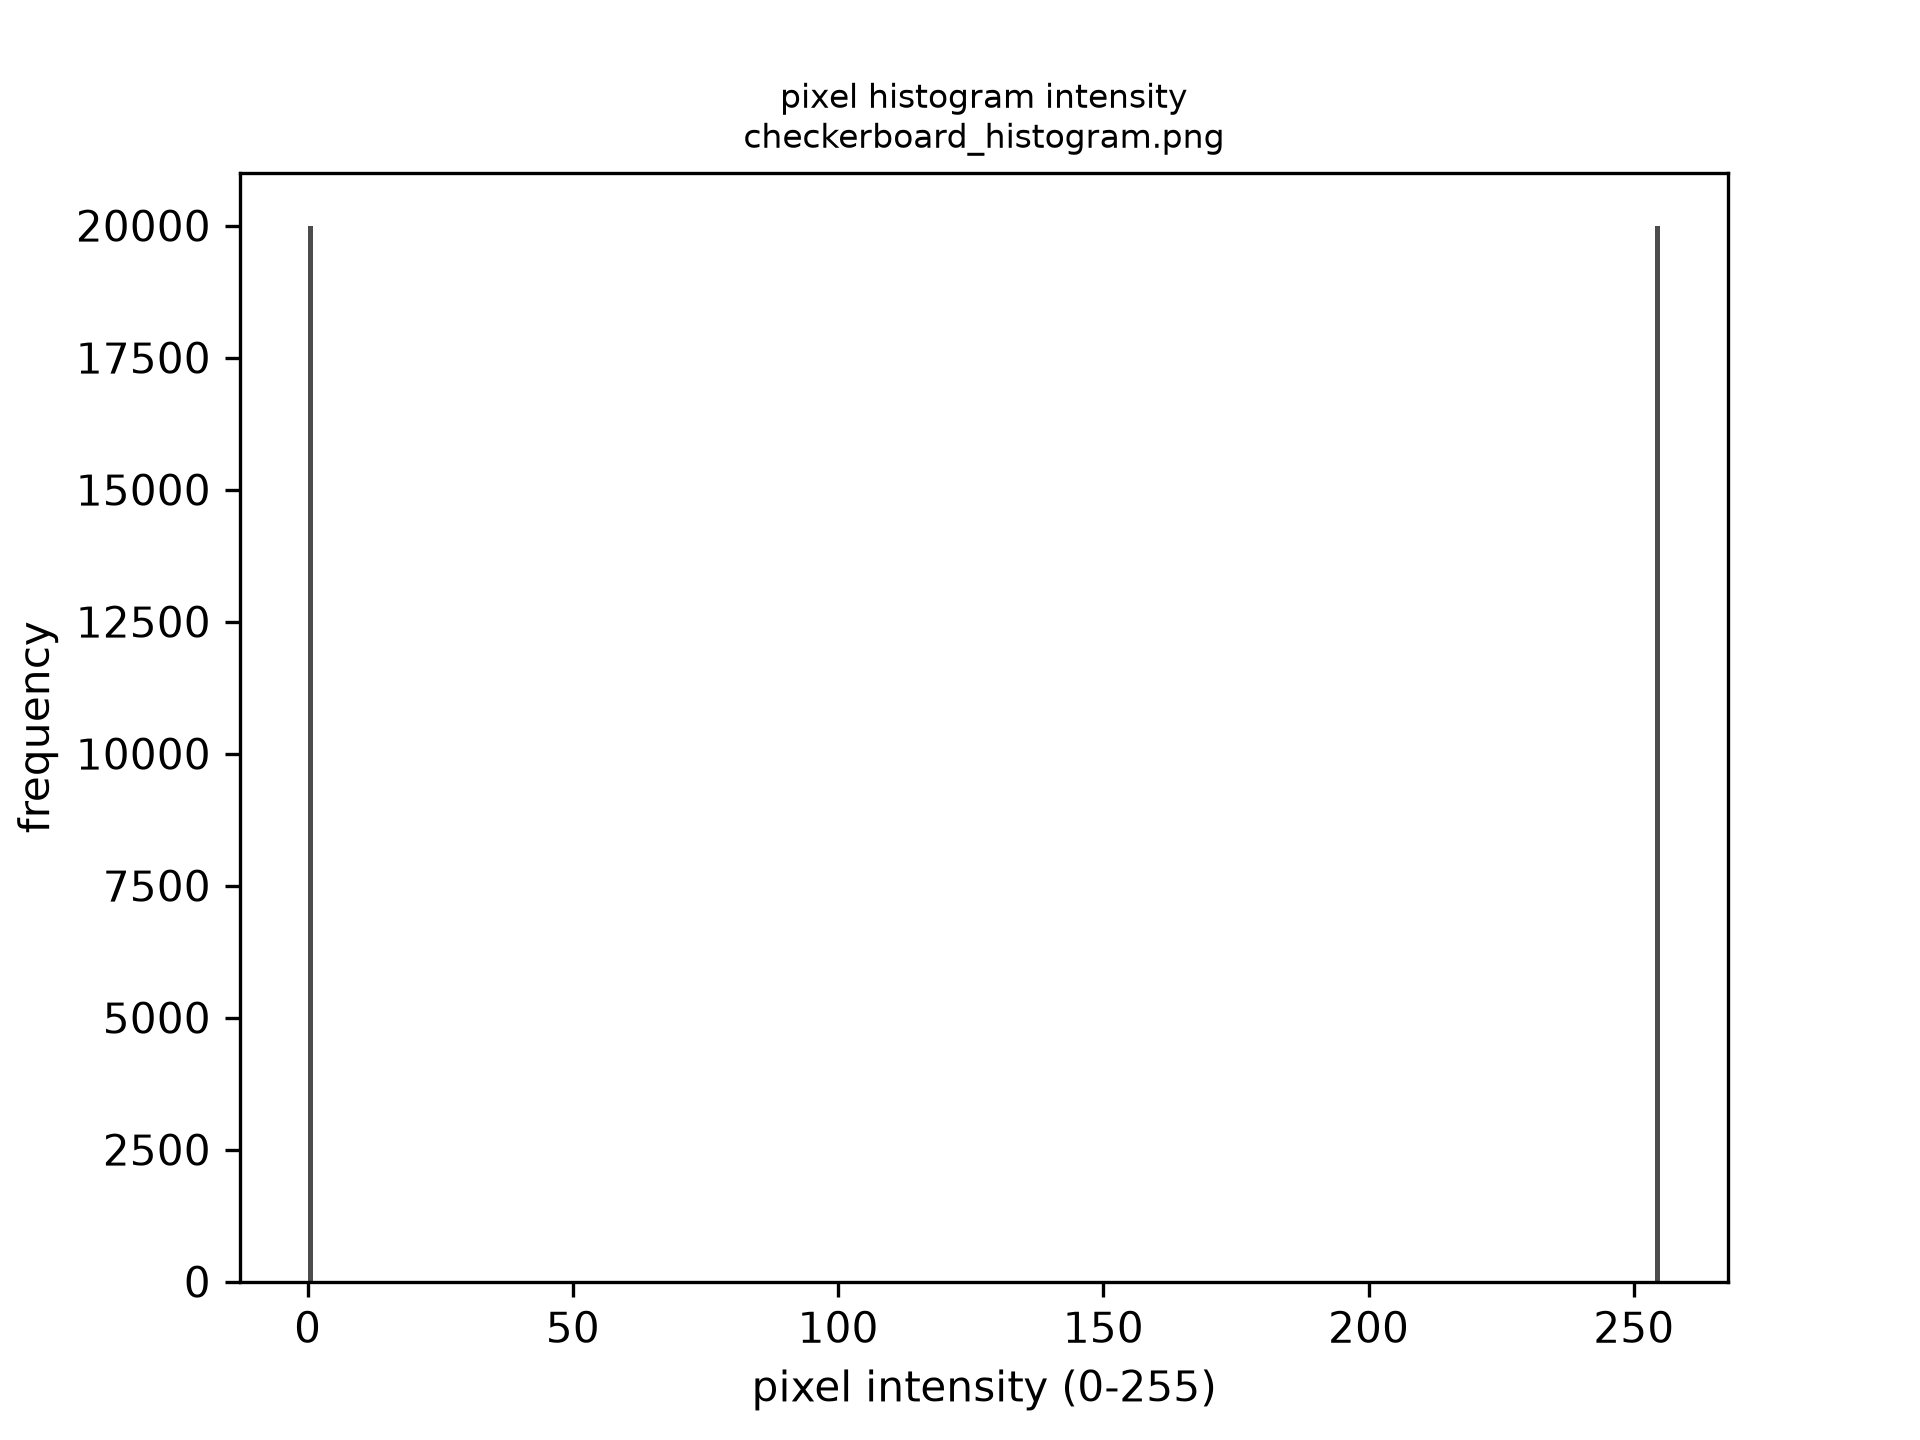 |  |
Speckle + Astronaut
The checkerboard above is a stand-in for an actual specimen — in a real
DIC setup, the speckle pattern is applied directly to the surface being
measured, not swapped in from another generator. Combining rosta with
the astronaut photo instead of the checkerboard is closer to that: a
speckle pattern overlaid on a realistic, non-uniform grayscale image.
This time the two source images are never written to disk at all — both
dictk.rosta and
dictk.astronaut return arrays directly,
which combine accepts
as-is, so only the combined result astronaut0 is saved:
import dictk
from dictk.image import combine, write

speckle = dictk.rosta(width=300, height=300, density=0.5)
photo = dictk.astronaut(width=300, height=300)
astronaut0 = combine(a=speckle, b=photo)
write(arr=astronaut0, path="astronaut0.png")
Saved image: astronaut0.png
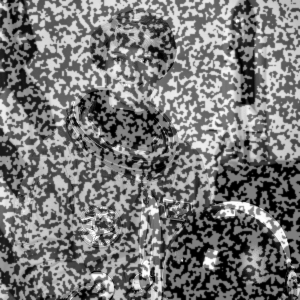
Both checkerboard0.png and astronaut0.png are also bundled in
src/dictk/data/, alongside the source astronaut.png, so later examples
can reuse them without regenerating from scratch each time.
Subimage Generation
Now we consider extracting a subimage from a subject image. A subimage is a useful precursor to image computation: narrowing the data down to a region of interest makes the computation more efficient than considering the full image.
Reference Frames
When we have just a single image, we have a single, trivial reference
frame : origin (blue dot) at the top-left corner, with
the -axis (red) running left-to-right and the -axis (green)
running top-to-bottom. origin, and every pixel coordinate on this
page, is expressed in this frame — one that's always implicitly
present, even in the left panel below where nothing is drawn to show
it. astronaut0 here is the same reference image created in Image
Generation:
from dictk.image import read
from dictk.plot import reference_frame_plot

astronaut0 = read(path="astronaut0.png")
reference_frame_plot(image=astronaut0, path="reference_frame.png")
Saved: reference_frame.png
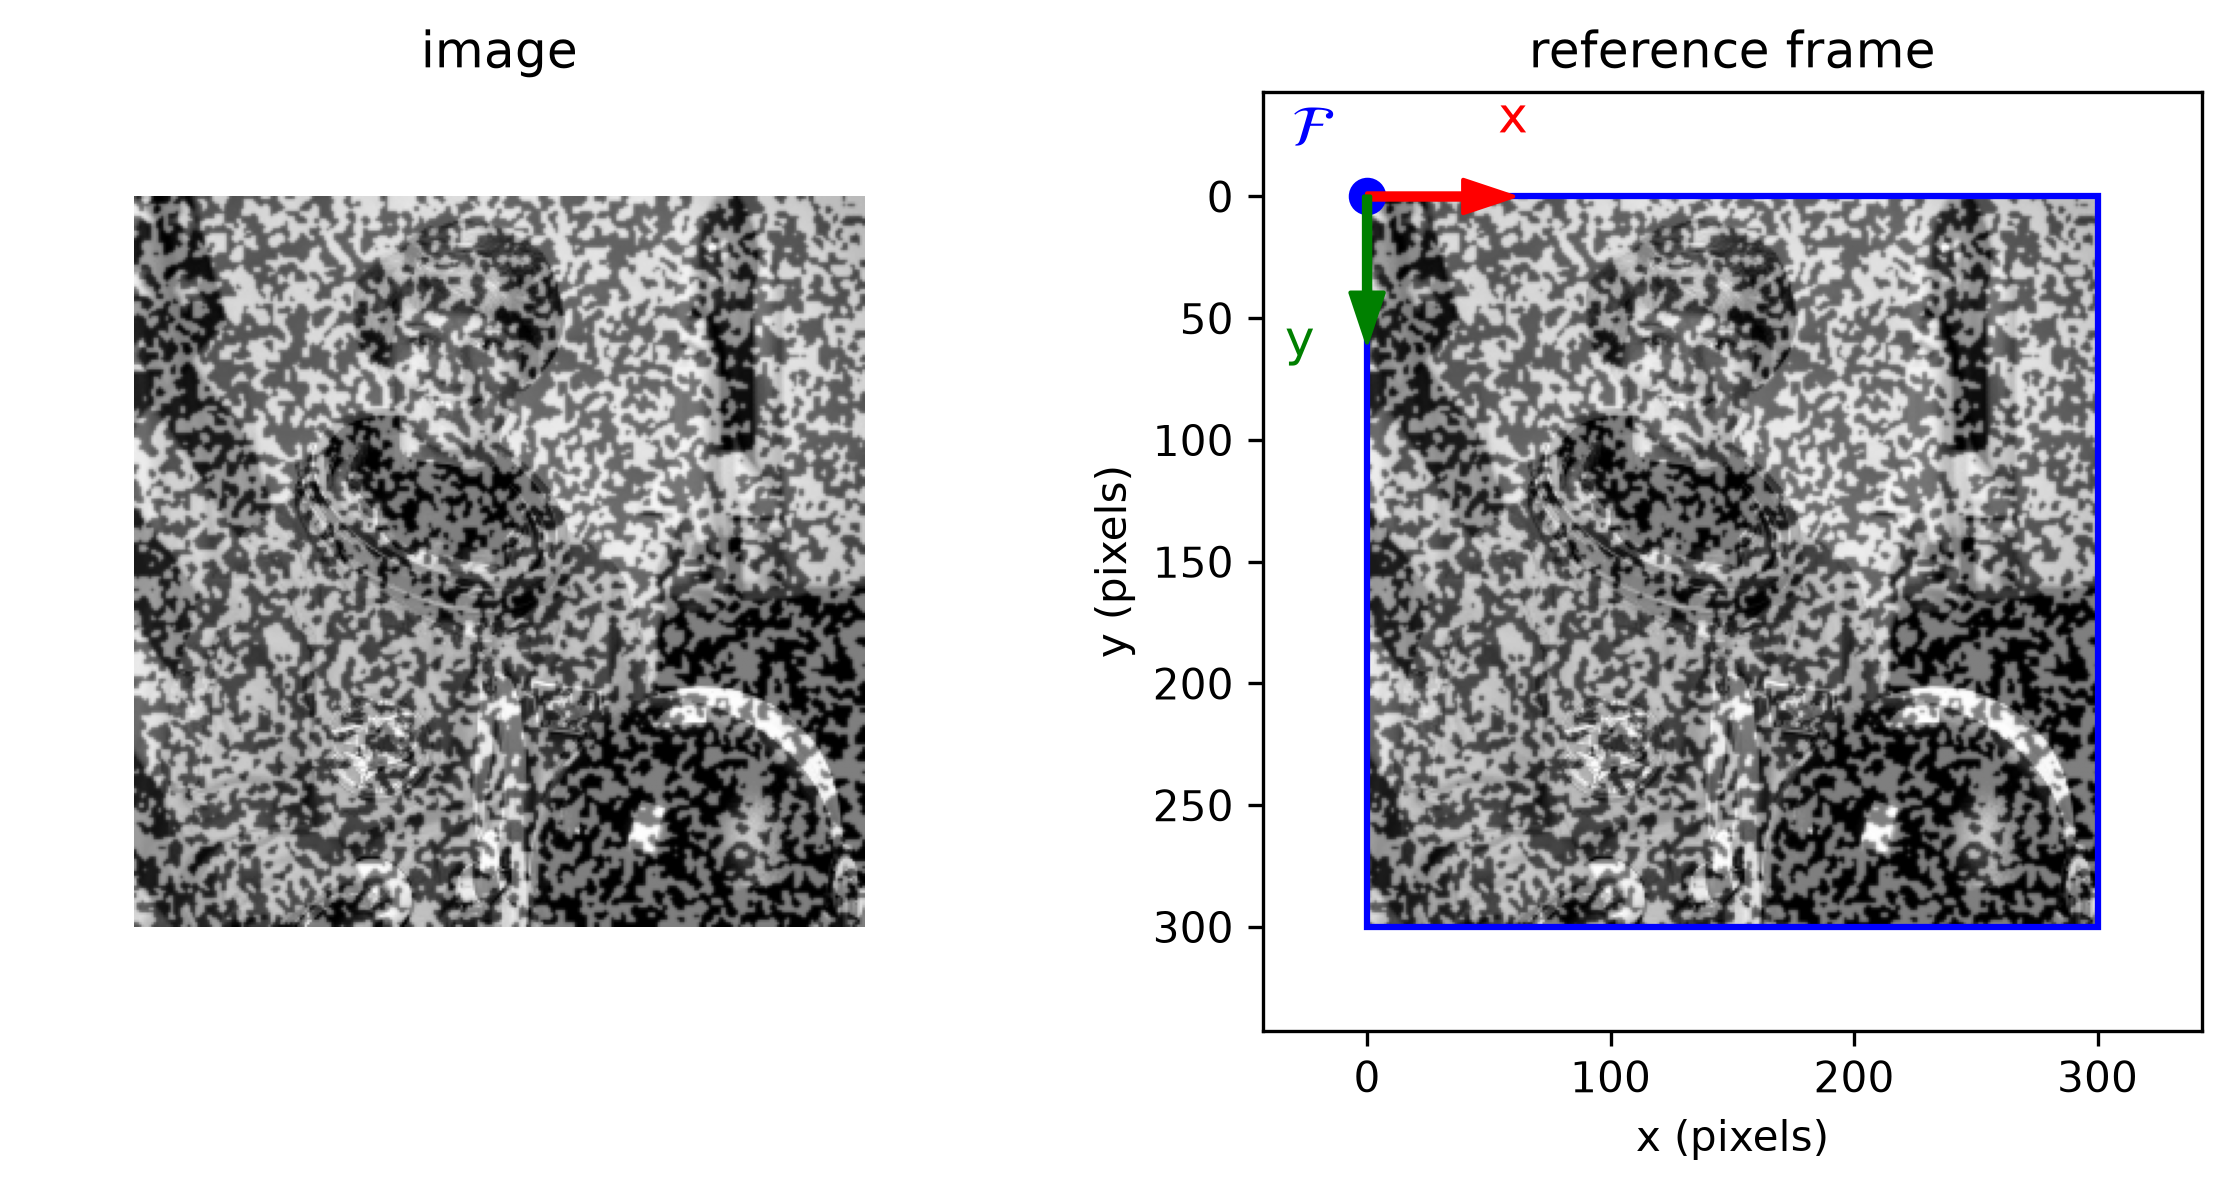
astronaut0 (300x300 pixels) alone. Right: the same image with its reference frame made explicit and labeled near the origin — origin (blue dot) at the top-left corner, -axis (red), and -axis (green), used throughout this page.When we extract a subimage from an image, it is useful to be explicit about reference frames: the subimage has its own frame , located within the image's frame . The Python API section below demonstrates this concept.
Python API
dictk.image.subimage extracts a
rectangular crop from a source image: a width x height region whose
top-left corner sits at origin. origin may place the requested
region partially or completely outside the source image — rather than
raising an error, subimage fills whatever doesn't overlap with black
(zero) pixels, so the result is always a well-formed height x width
array. This is the building block later tutorials use to pull a kernel
or search area out of a larger reference/current image pair around a
point of interest.
dictk.image.PixelCoordinate
is a simple (x, y) NamedTuple used for origin.
dictk.image.subimage itself
returns the cropped array directly, with no file written.
The examples below use
subimage_comparison_plot,
which saves a two-panel figure: the left panel shows where the region
falls relative to the source image (blue/red boxes), and the right panel
shows the extracted result on its own, in its own local frame
— sharing the same axis limits as the left panel so the
two red boxes render at matching scale. It's built from two smaller
single-panel functions, also available individually:
subimage_bounds_plot
(the left panel alone) and
subimage_plot (the right
panel alone, but zoomed to the subimage's own size rather than sharing
the source image's scale).
Square, fully inside
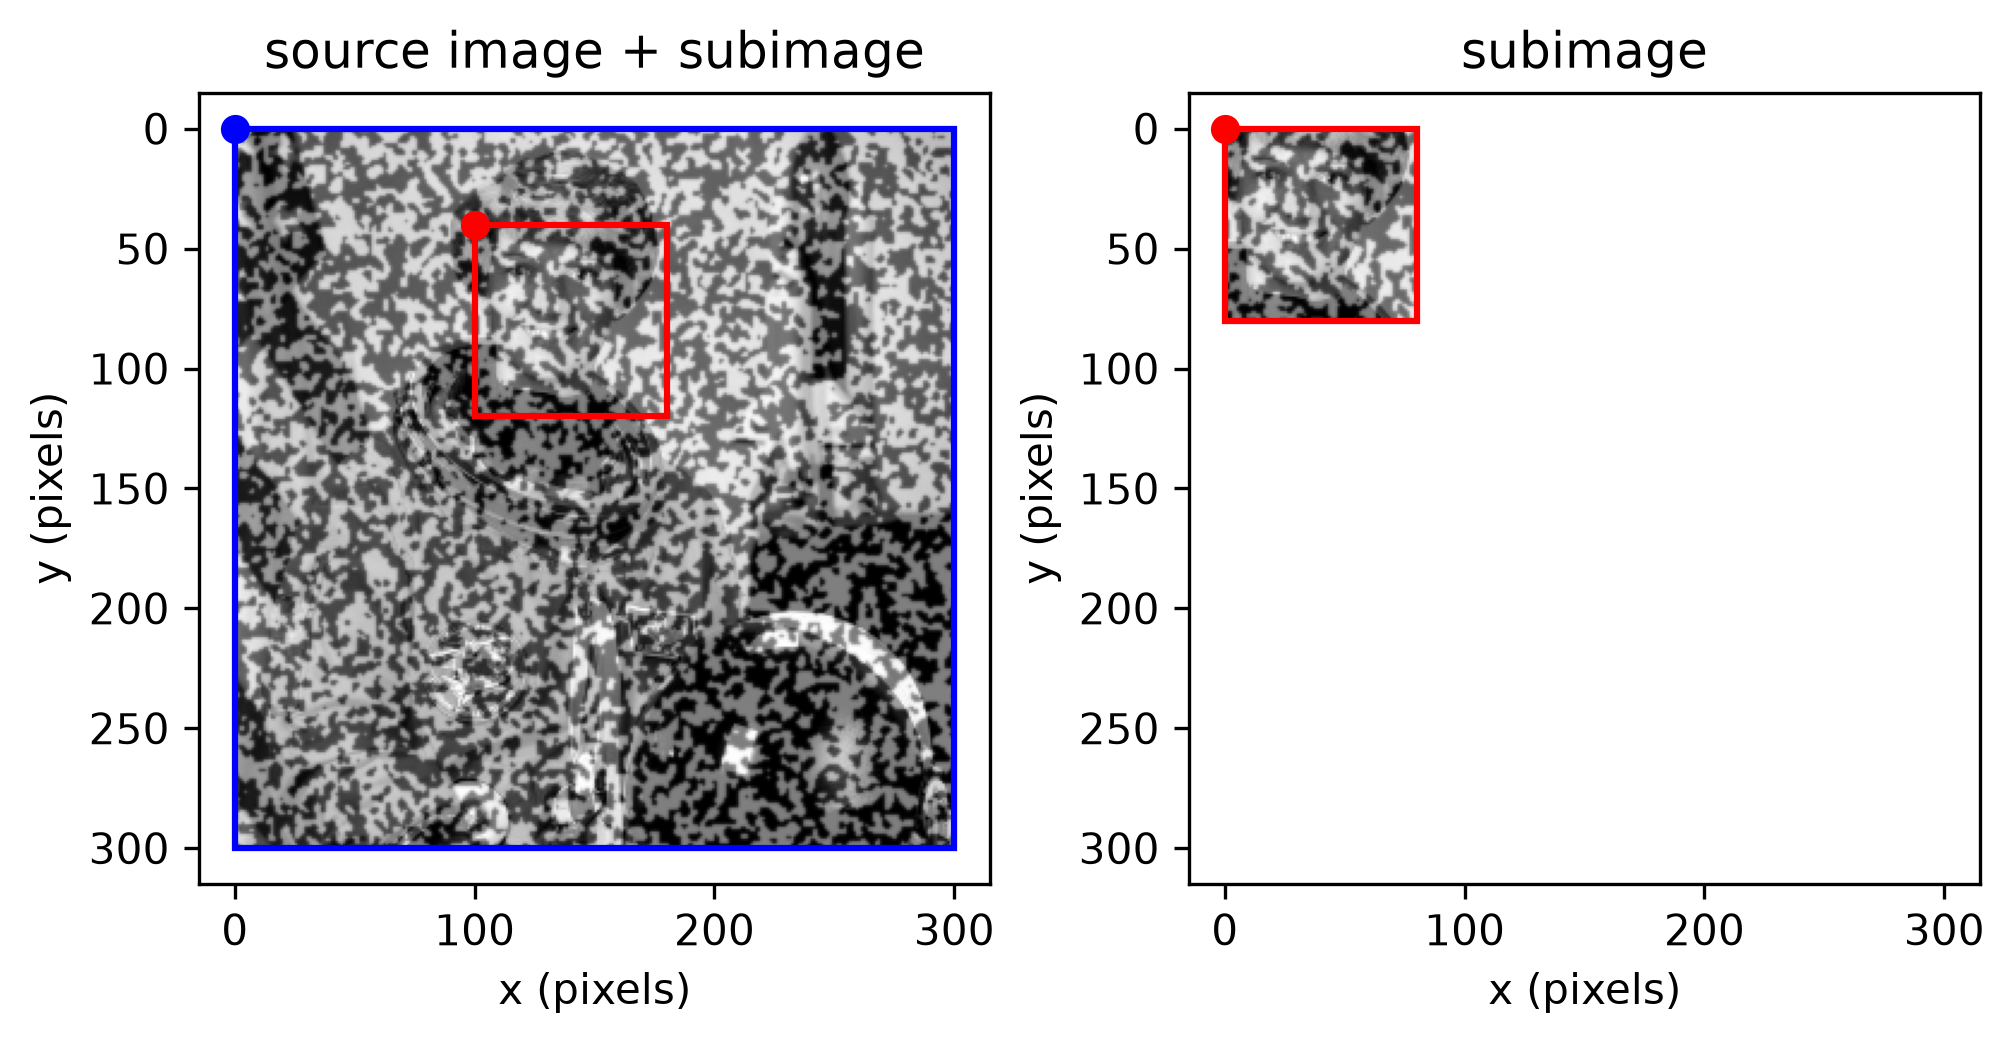
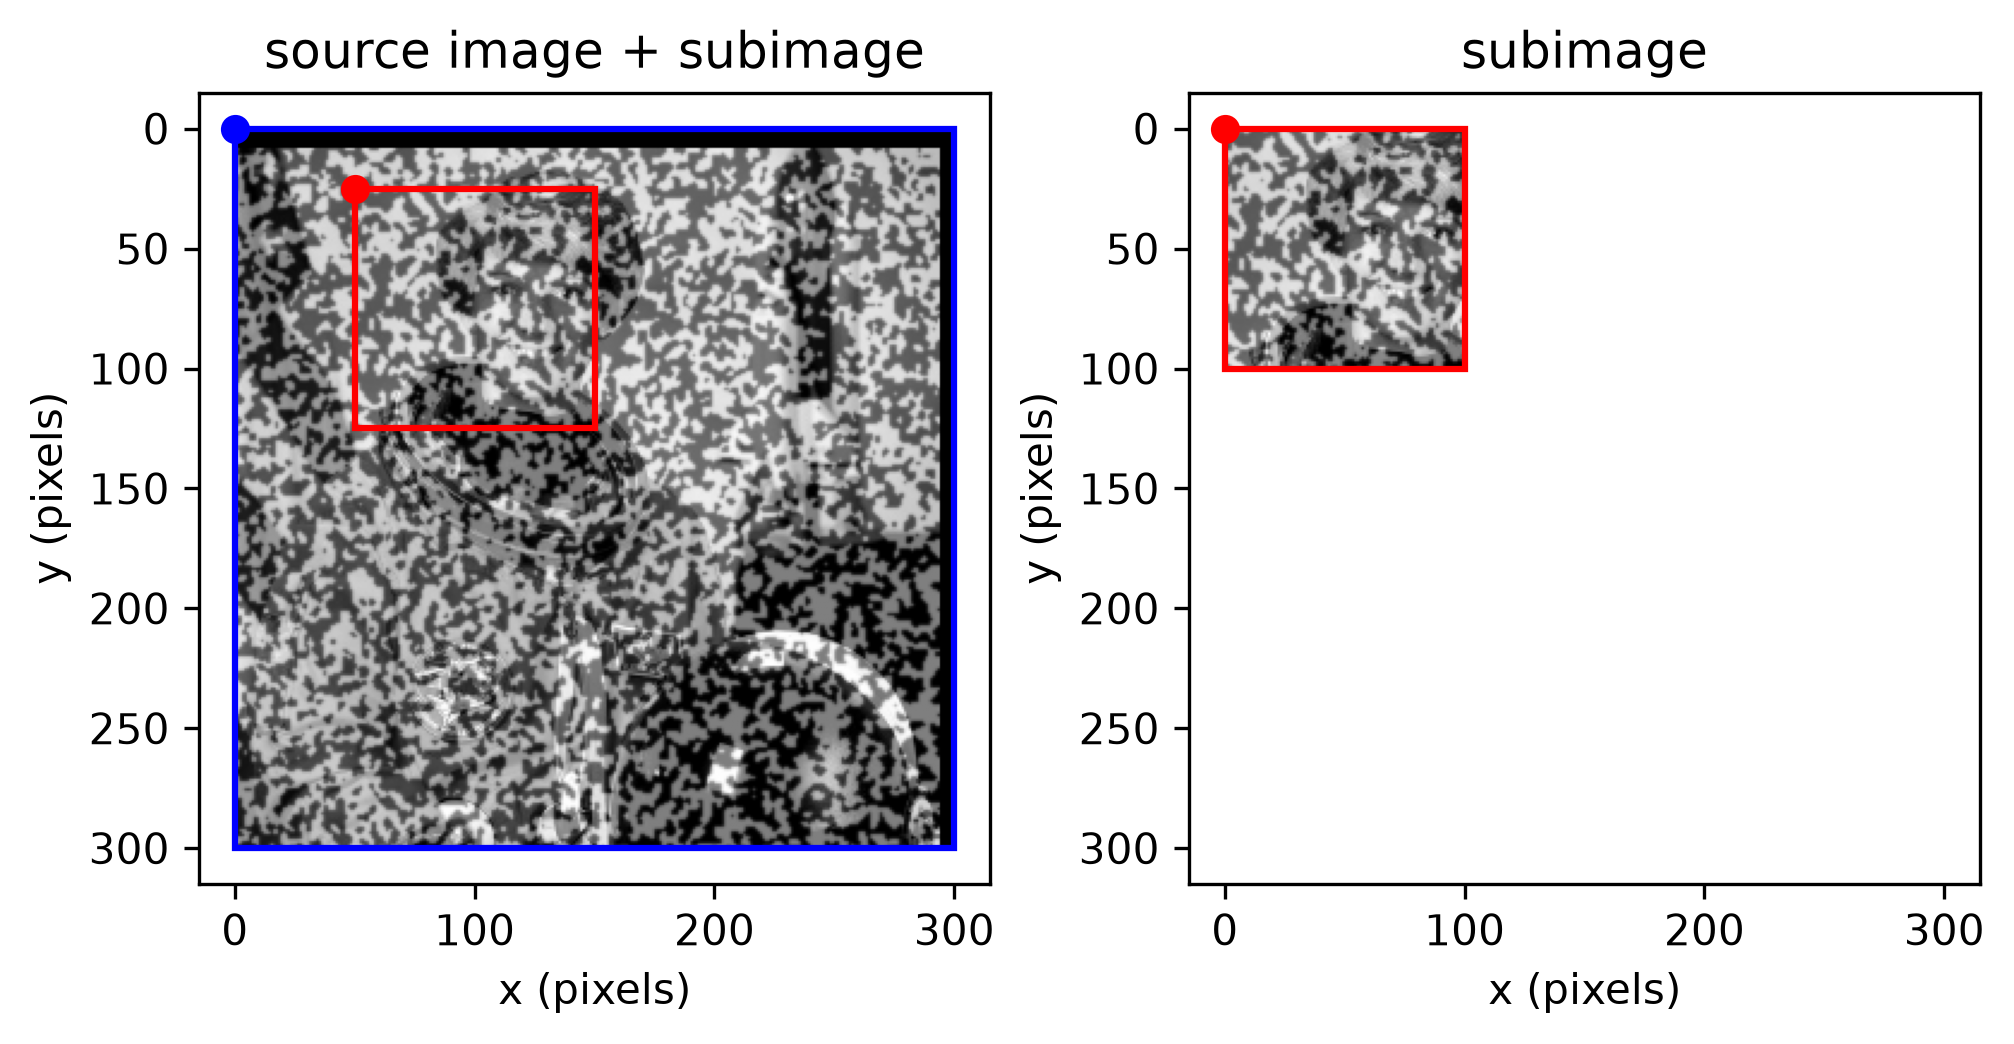
An 80x80 square region entirely within astronaut0's 300x300 bounds.
subimage_comparison_plot
draws both panels side by side, sharing the same axis limits, so the
red box in the right panel renders at identical scale to the one on the
left.
from dictk.image import PixelCoordinate
from dictk.plot import subimage_comparison_plot

origin = PixelCoordinate(x=100, y=40)
subimage_comparison_plot(image=astronaut0, origin=origin, width=80, height=80, path="subimage_comparison_80w_by_80h_at_100_40.png")
Saved: subimage_comparison_80w_by_80h_at_100_40.png
Rectangle, fully inside
A 180x70 region — wider than it is tall — also entirely within the source image bounds:
from dictk.image import PixelCoordinate
from dictk.plot import subimage_comparison_plot

origin = PixelCoordinate(x=50, y=200)
subimage_comparison_plot(image=astronaut0, origin=origin, width=180, height=70, path="subimage_comparison_180w_by_70h_at_50_200.png")
Saved: subimage_comparison_180w_by_70h_at_50_200.png
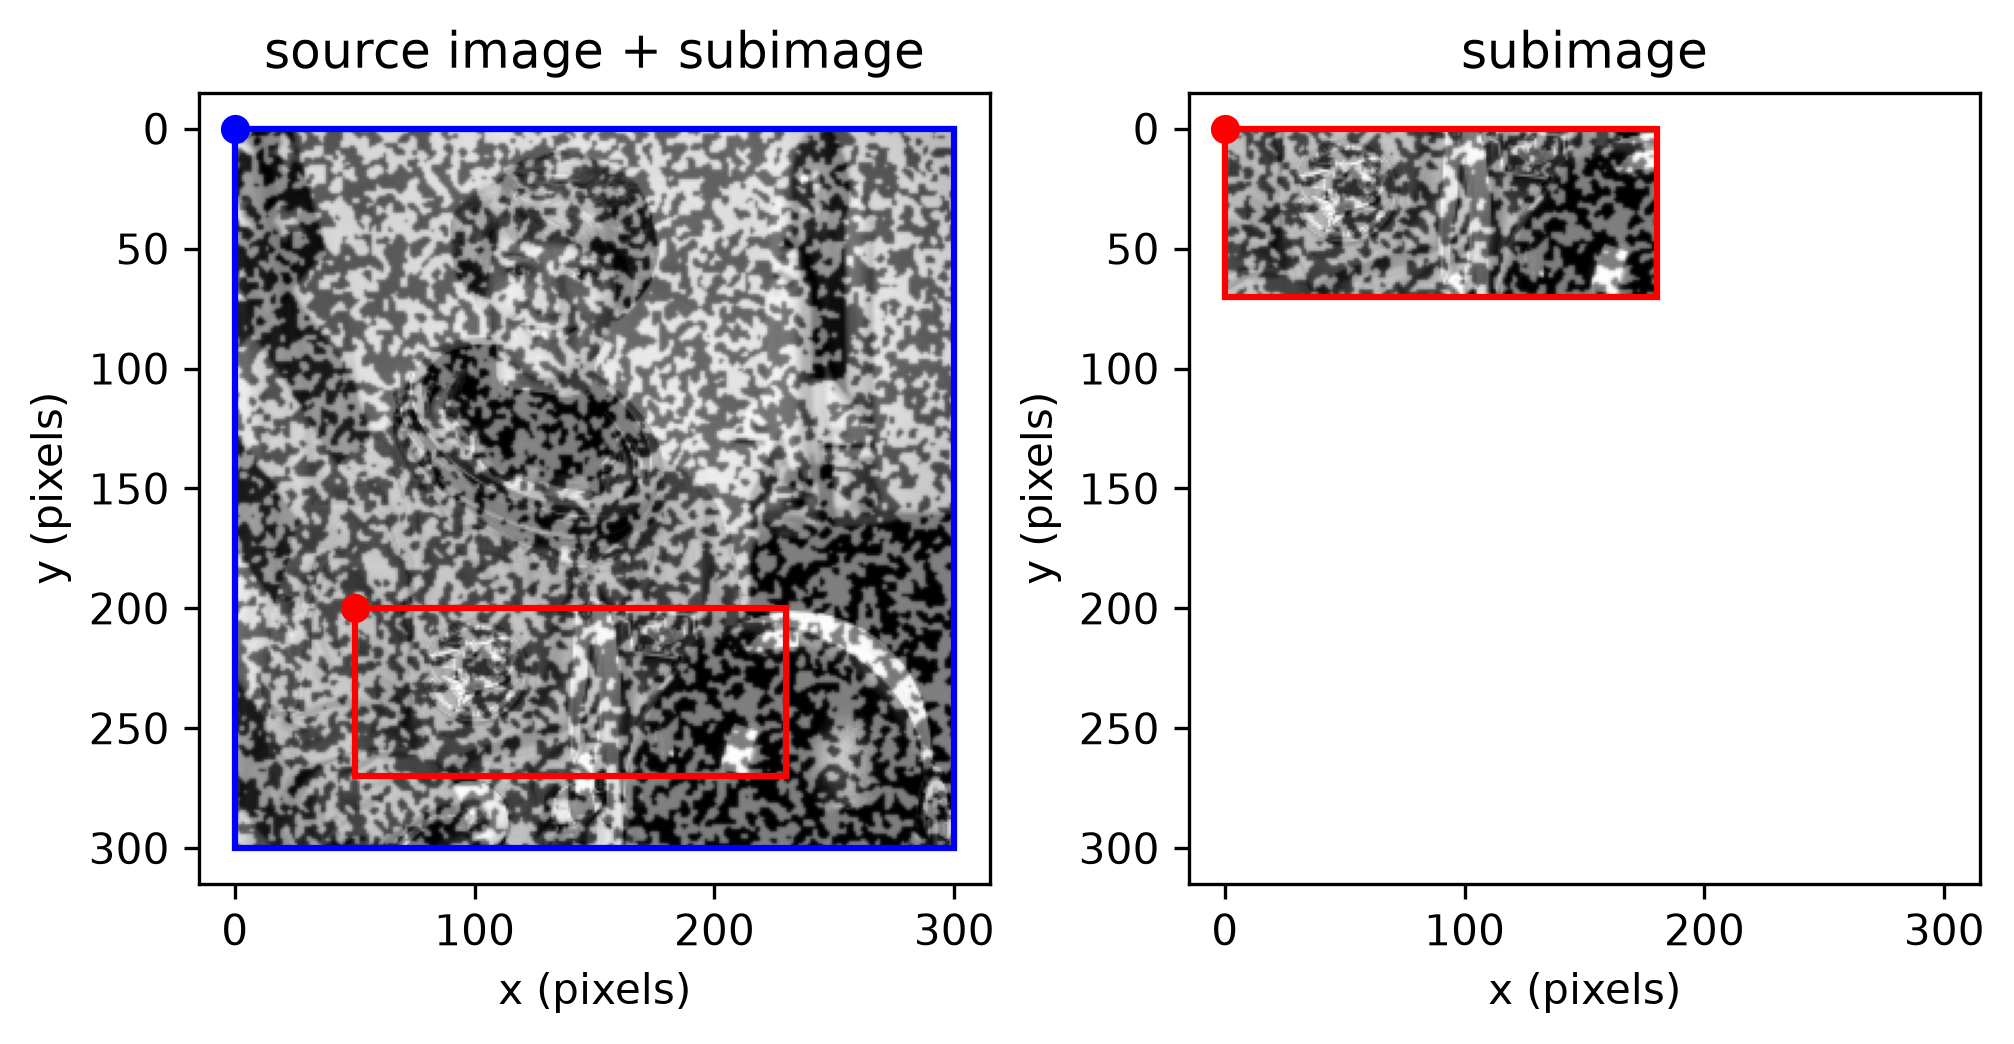
Partially outside
A 120x120 region with a negative origin, straddling the source image's
top-left corner. subimage fills the part of the region above and to
the left of the source with black:
from dictk.image import PixelCoordinate
from dictk.plot import subimage_comparison_plot

origin = PixelCoordinate(x=-20, y=-40)
subimage_comparison_plot(image=astronaut0, origin=origin, width=120, height=120, path="subimage_comparison_120w_by_120h_at_-20_-40.png")
Saved: subimage_comparison_120w_by_120h_at_-20_-40.png
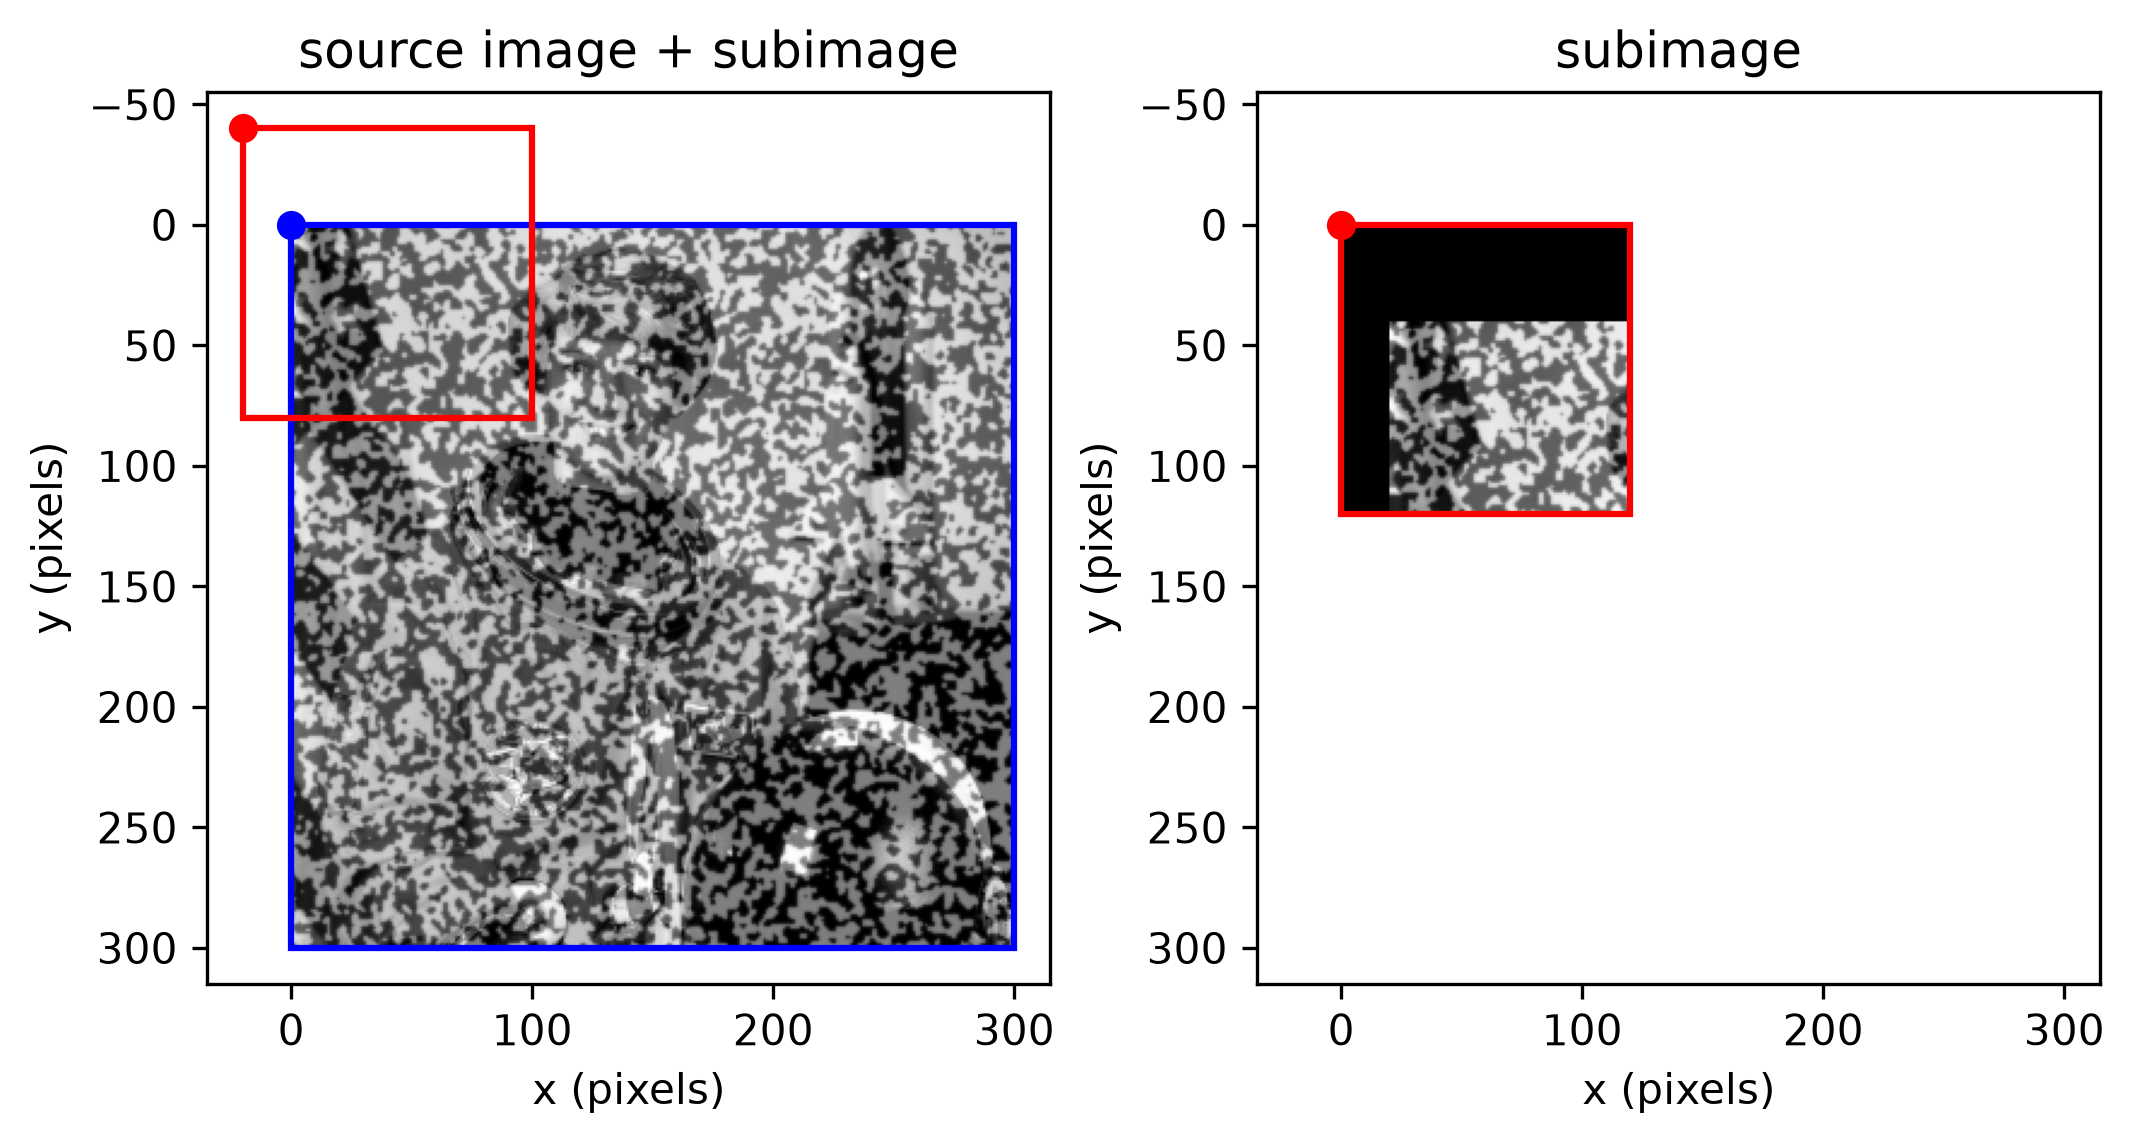
astronaut0.Completely outside
A 40x100 region entirely beyond the source image's bounds — its x-range (310 to 350) shares no pixels with the source's (0 to 300), so there is no overlap at all and the result is entirely black:
from dictk.image import PixelCoordinate
from dictk.plot import subimage_comparison_plot

origin = PixelCoordinate(x=310, y=250)
subimage_comparison_plot(image=astronaut0, origin=origin, width=40, height=100, path="subimage_comparison_40w_by_100h_at_310_250.png")
Saved: subimage_comparison_40w_by_100h_at_310_250.png
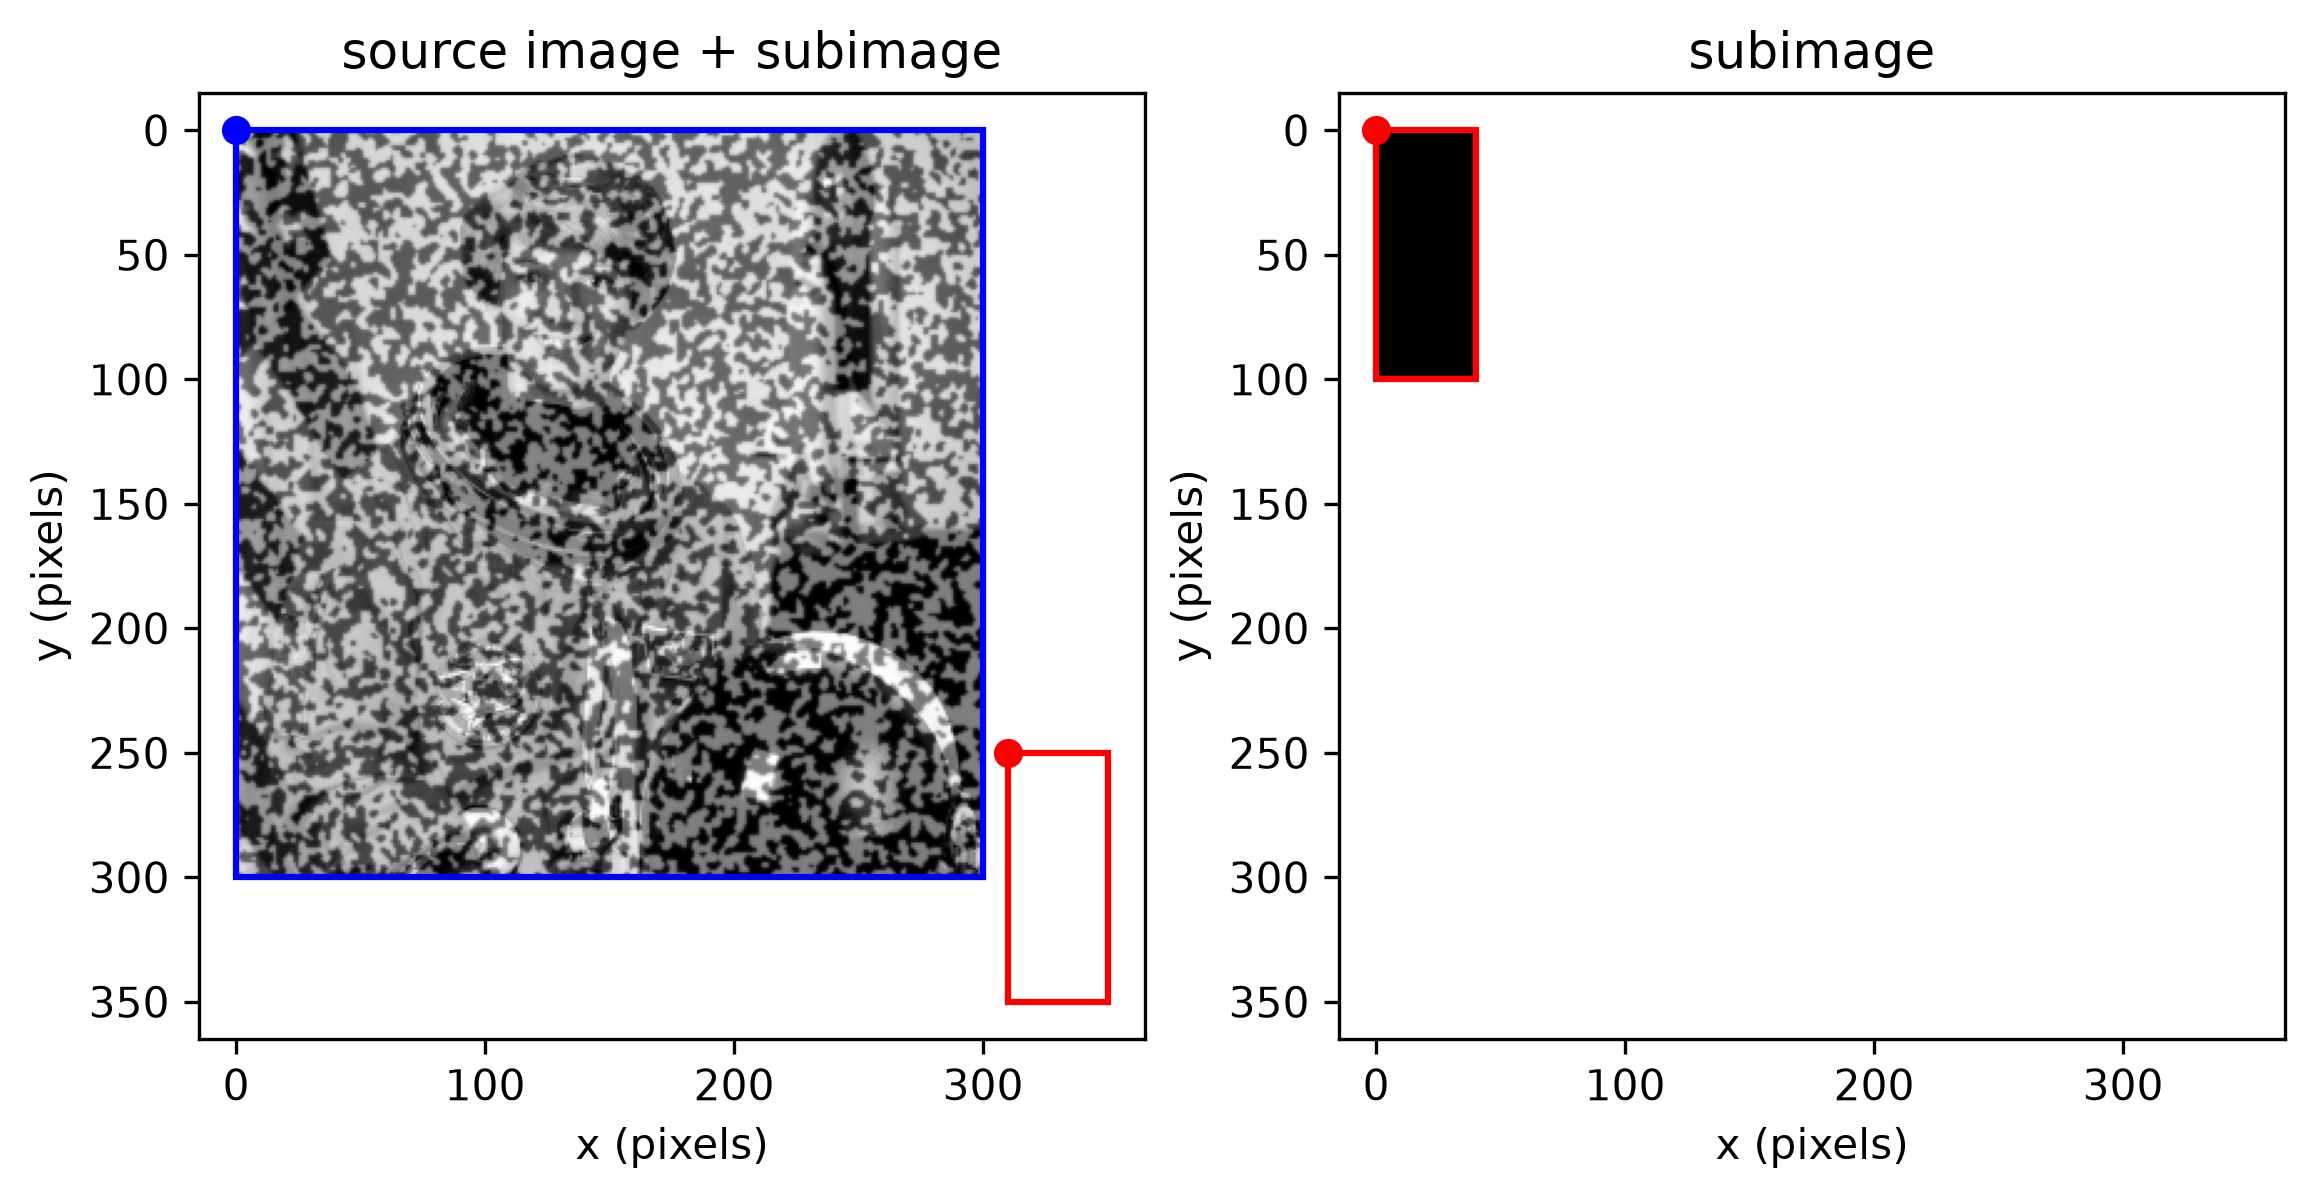
astronaut0.Image Preprocessing
Certain preprocessing steps can make digital image correlation more robust to differences between a reference and current image — some in pixel intensity, others in how well an image's content suits an FFT-based technique such as phase correlation.
- Brightness and Contrast shift and stretch the pixel-intensity histogram, the two most basic differences a reference and current image can have.
- Windowing tapers an image's edges toward zero before a Fourier transform, reducing spectral leakage.
Brightness and Contrast
This page covers two preprocessing steps that can make digital image correlation more robust to pixel-intensity differences between a reference and deformed image, using the astronaut reference image from Image Generation as an example.
Brightness
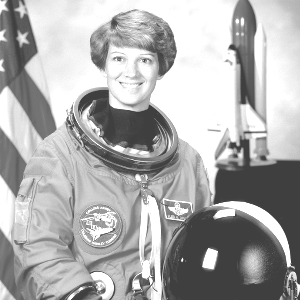
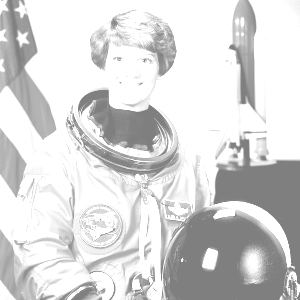
Brightness shifts the entire pixel-intensity histogram up or down by a constant amount — the whole image gets lighter or darker together, dark areas included. Pushed too far, dark regions wash out to a flat gray and highlights clip at pure white (255), permanently losing detail.
import dictk
from dictk.image import brightness, write
from dictk.plot import histogram_save

photo = dictk.astronaut(width=300, height=300)
write(arr=photo, path="astronaut_original.png")
histogram_save(arr=photo, path="astronaut_original_histogram.png")

bright_1_5 = brightness(arr=photo, factor=1.5)
write(arr=bright_1_5, path="astronaut_brightness_1.5.png")
histogram_save(arr=bright_1_5, path="astronaut_brightness_1.5_histogram.png")

bright_2_0 = brightness(arr=photo, factor=2.0)
write(arr=bright_2_0, path="astronaut_brightness_2.0.png")
histogram_save(arr=bright_2_0, path="astronaut_brightness_2.0_histogram.png")
Saved: astronaut_original.png, astronaut_brightness_1.5.png, astronaut_brightness_2.0.png
| factor=1.0 (original) | factor=1.5 | factor=2.0 |
|---|---|---|
 |  |  |
| factor=1.0 (original) | factor=1.5 | factor=2.0 |
|---|---|---|
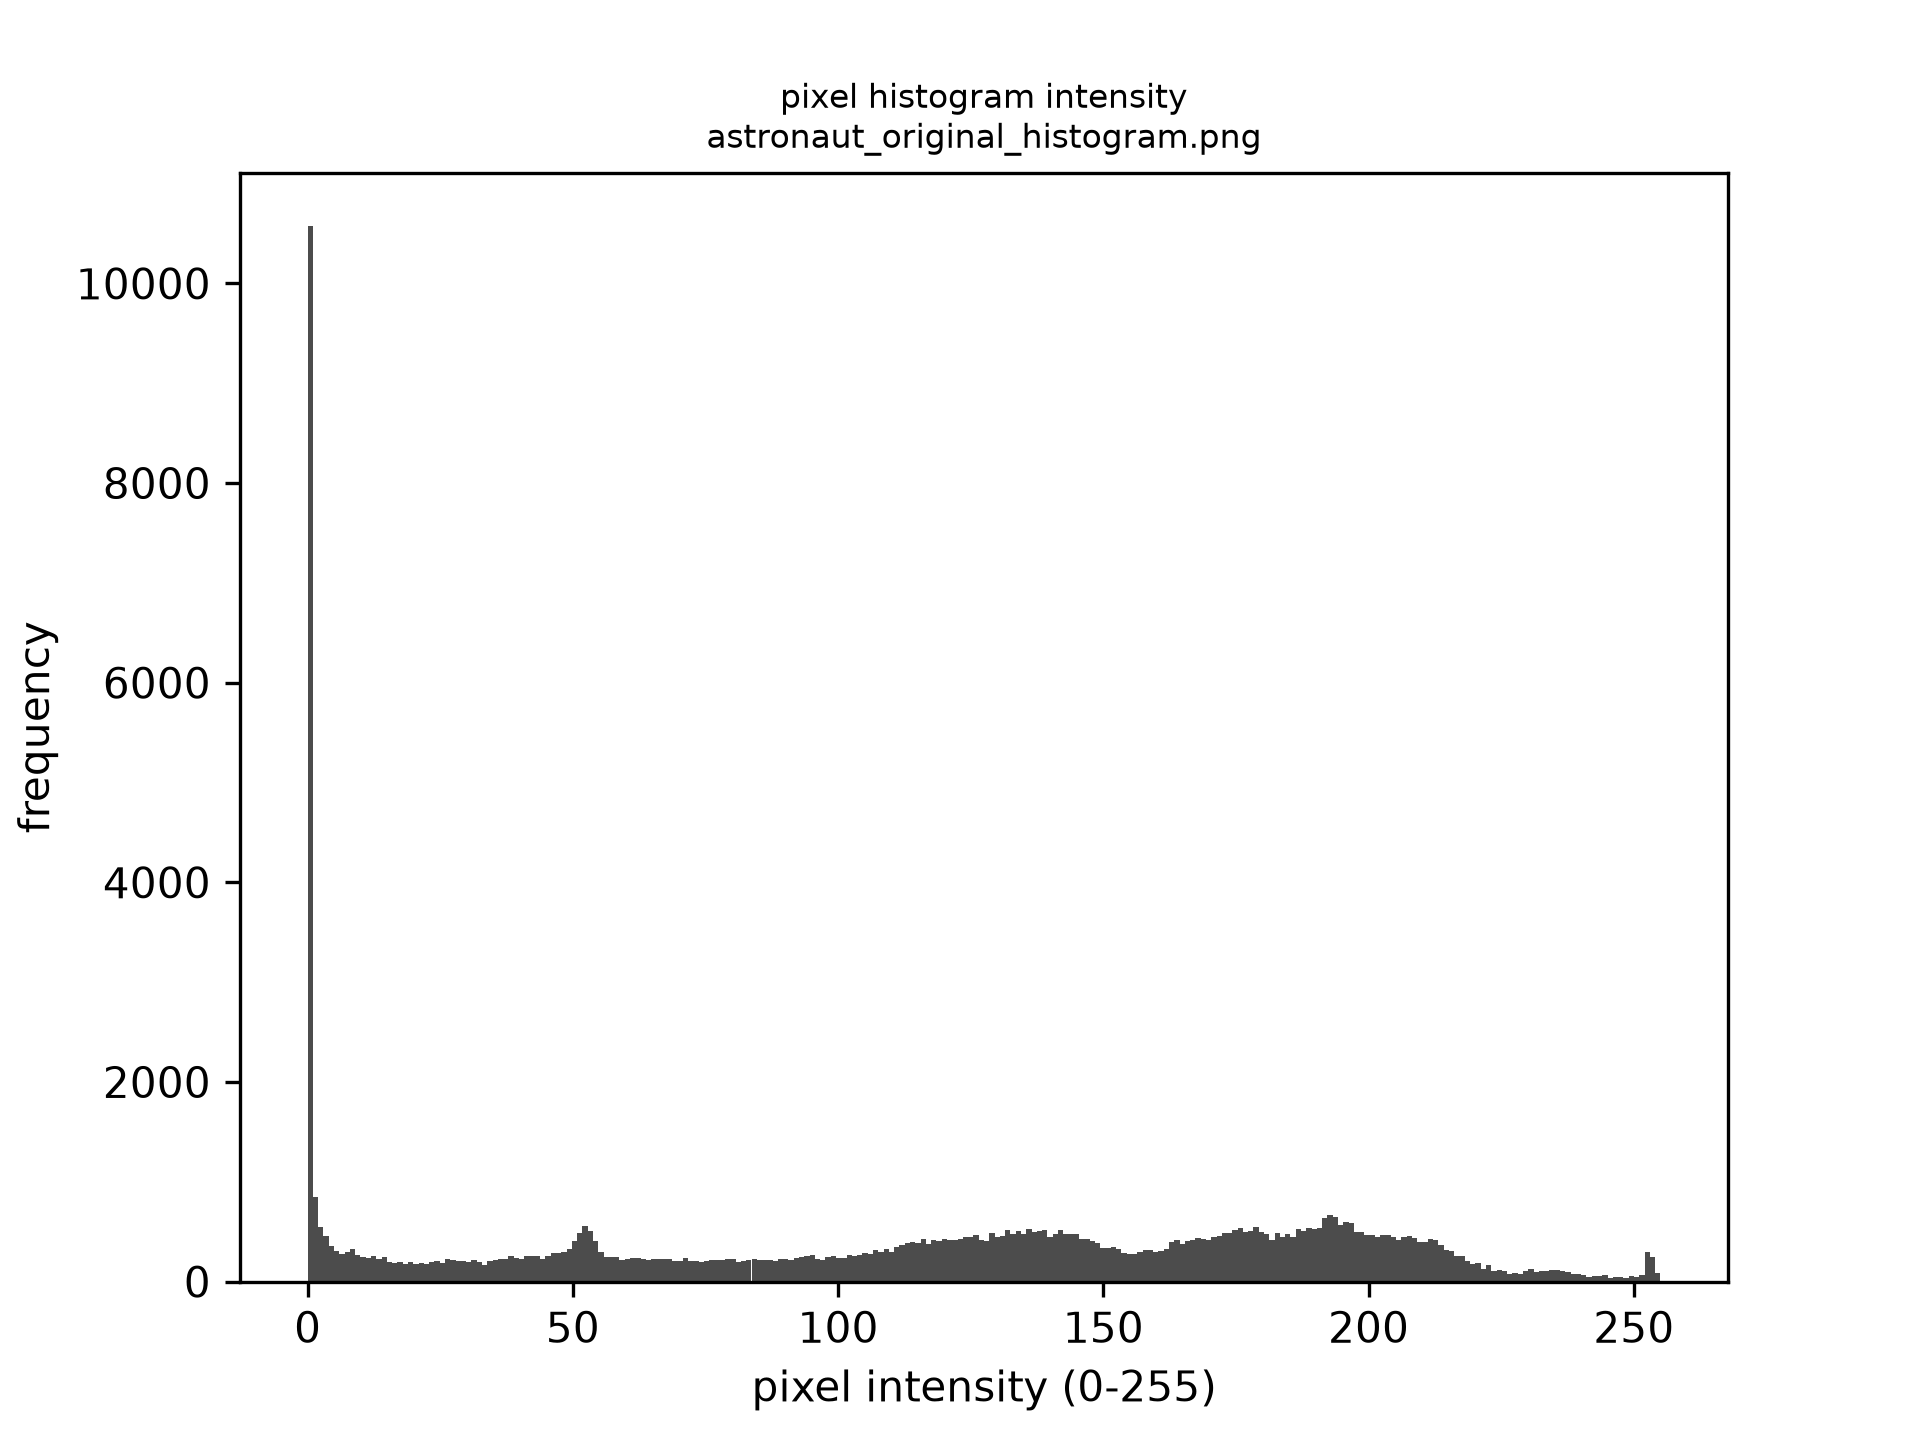 | 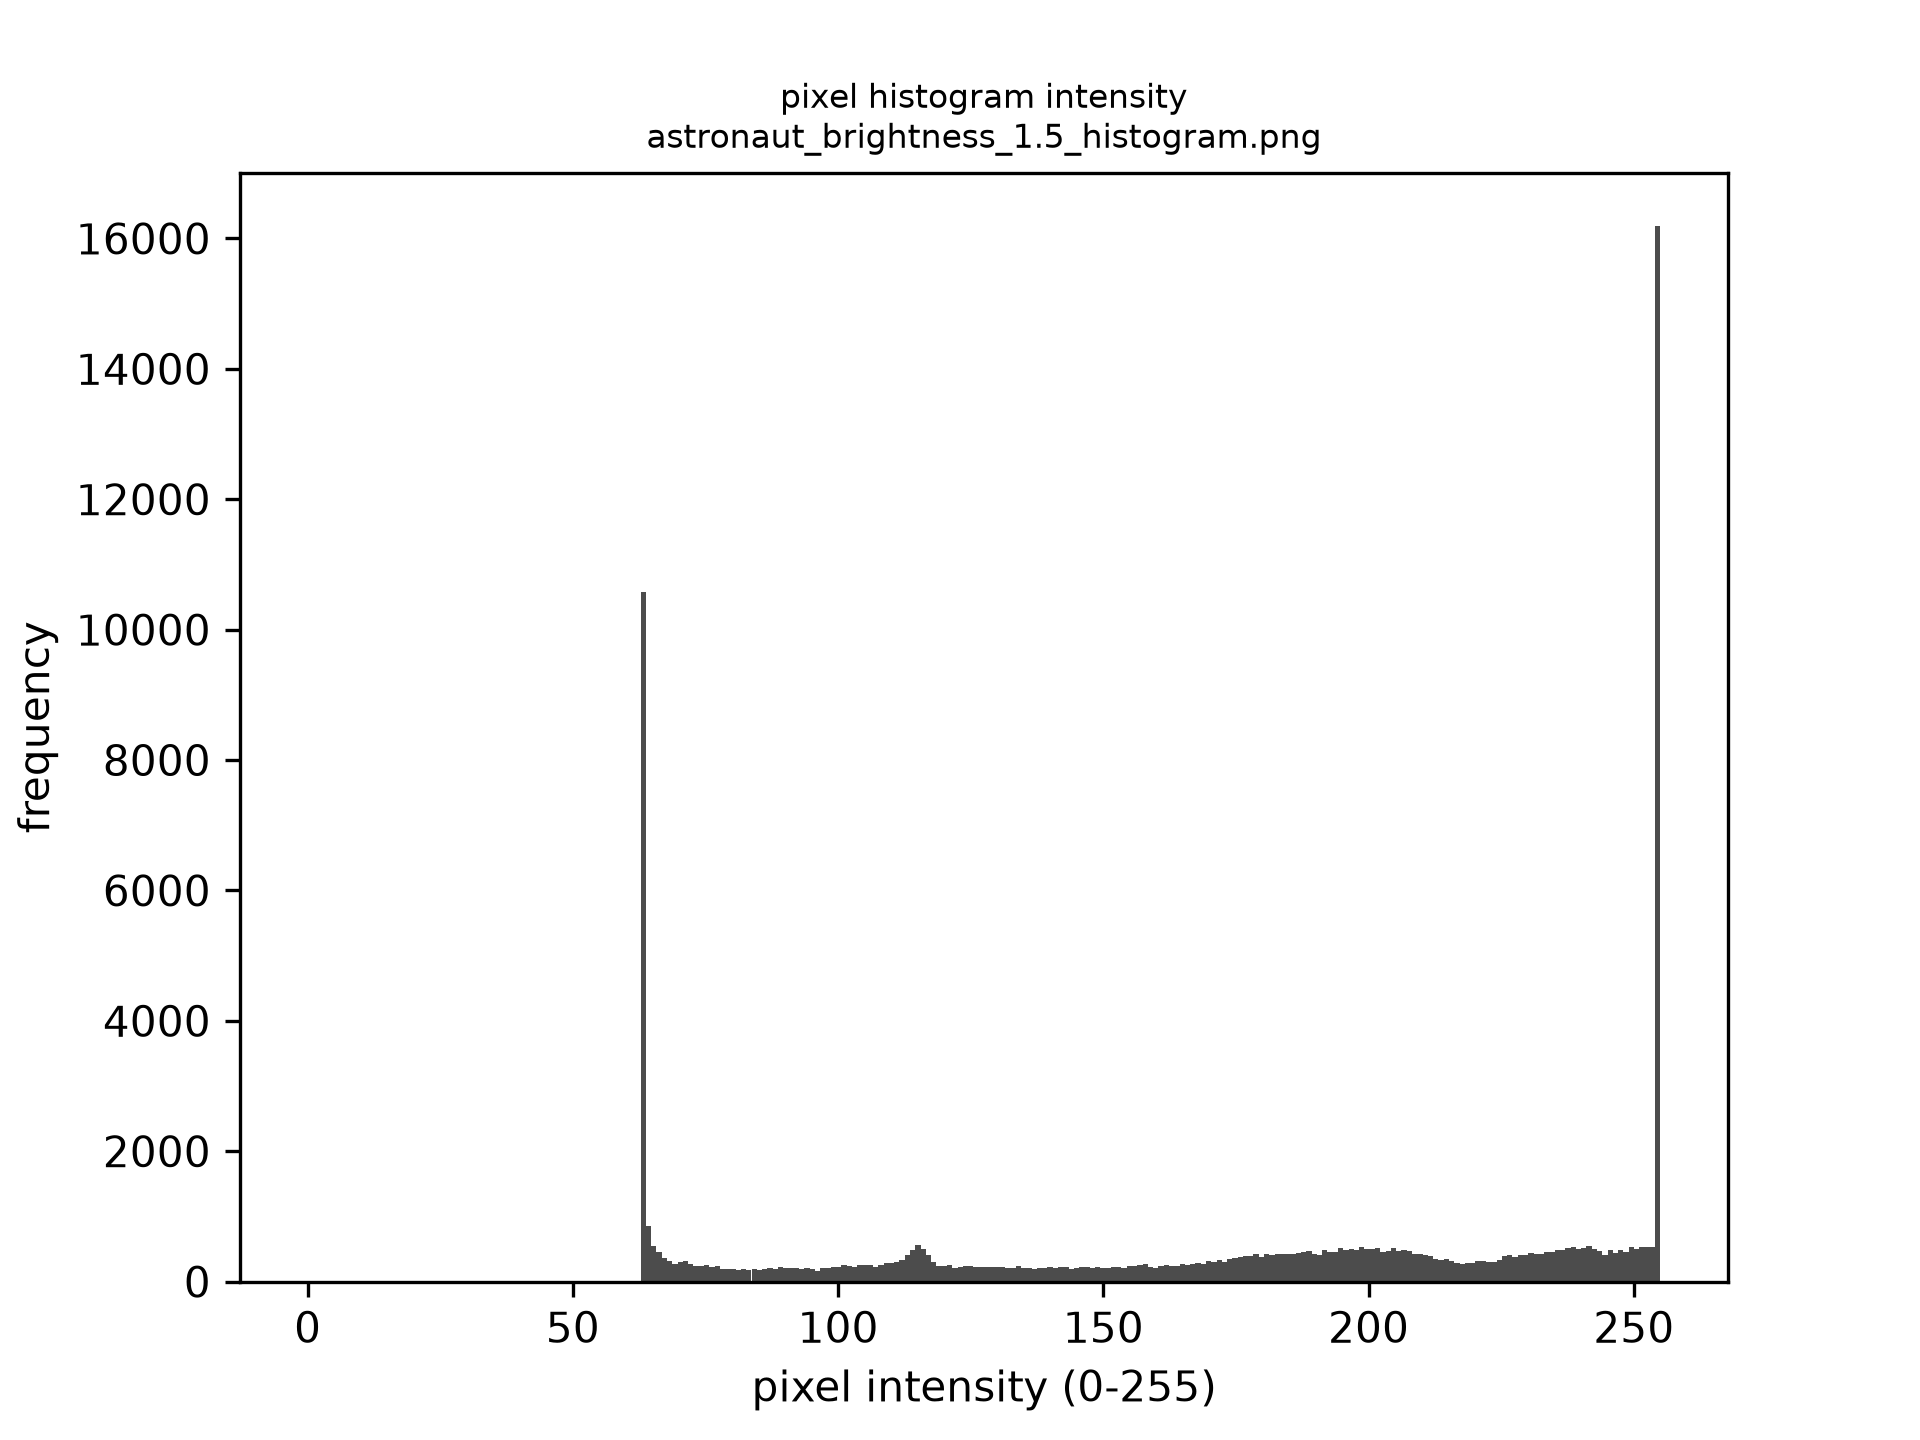 | 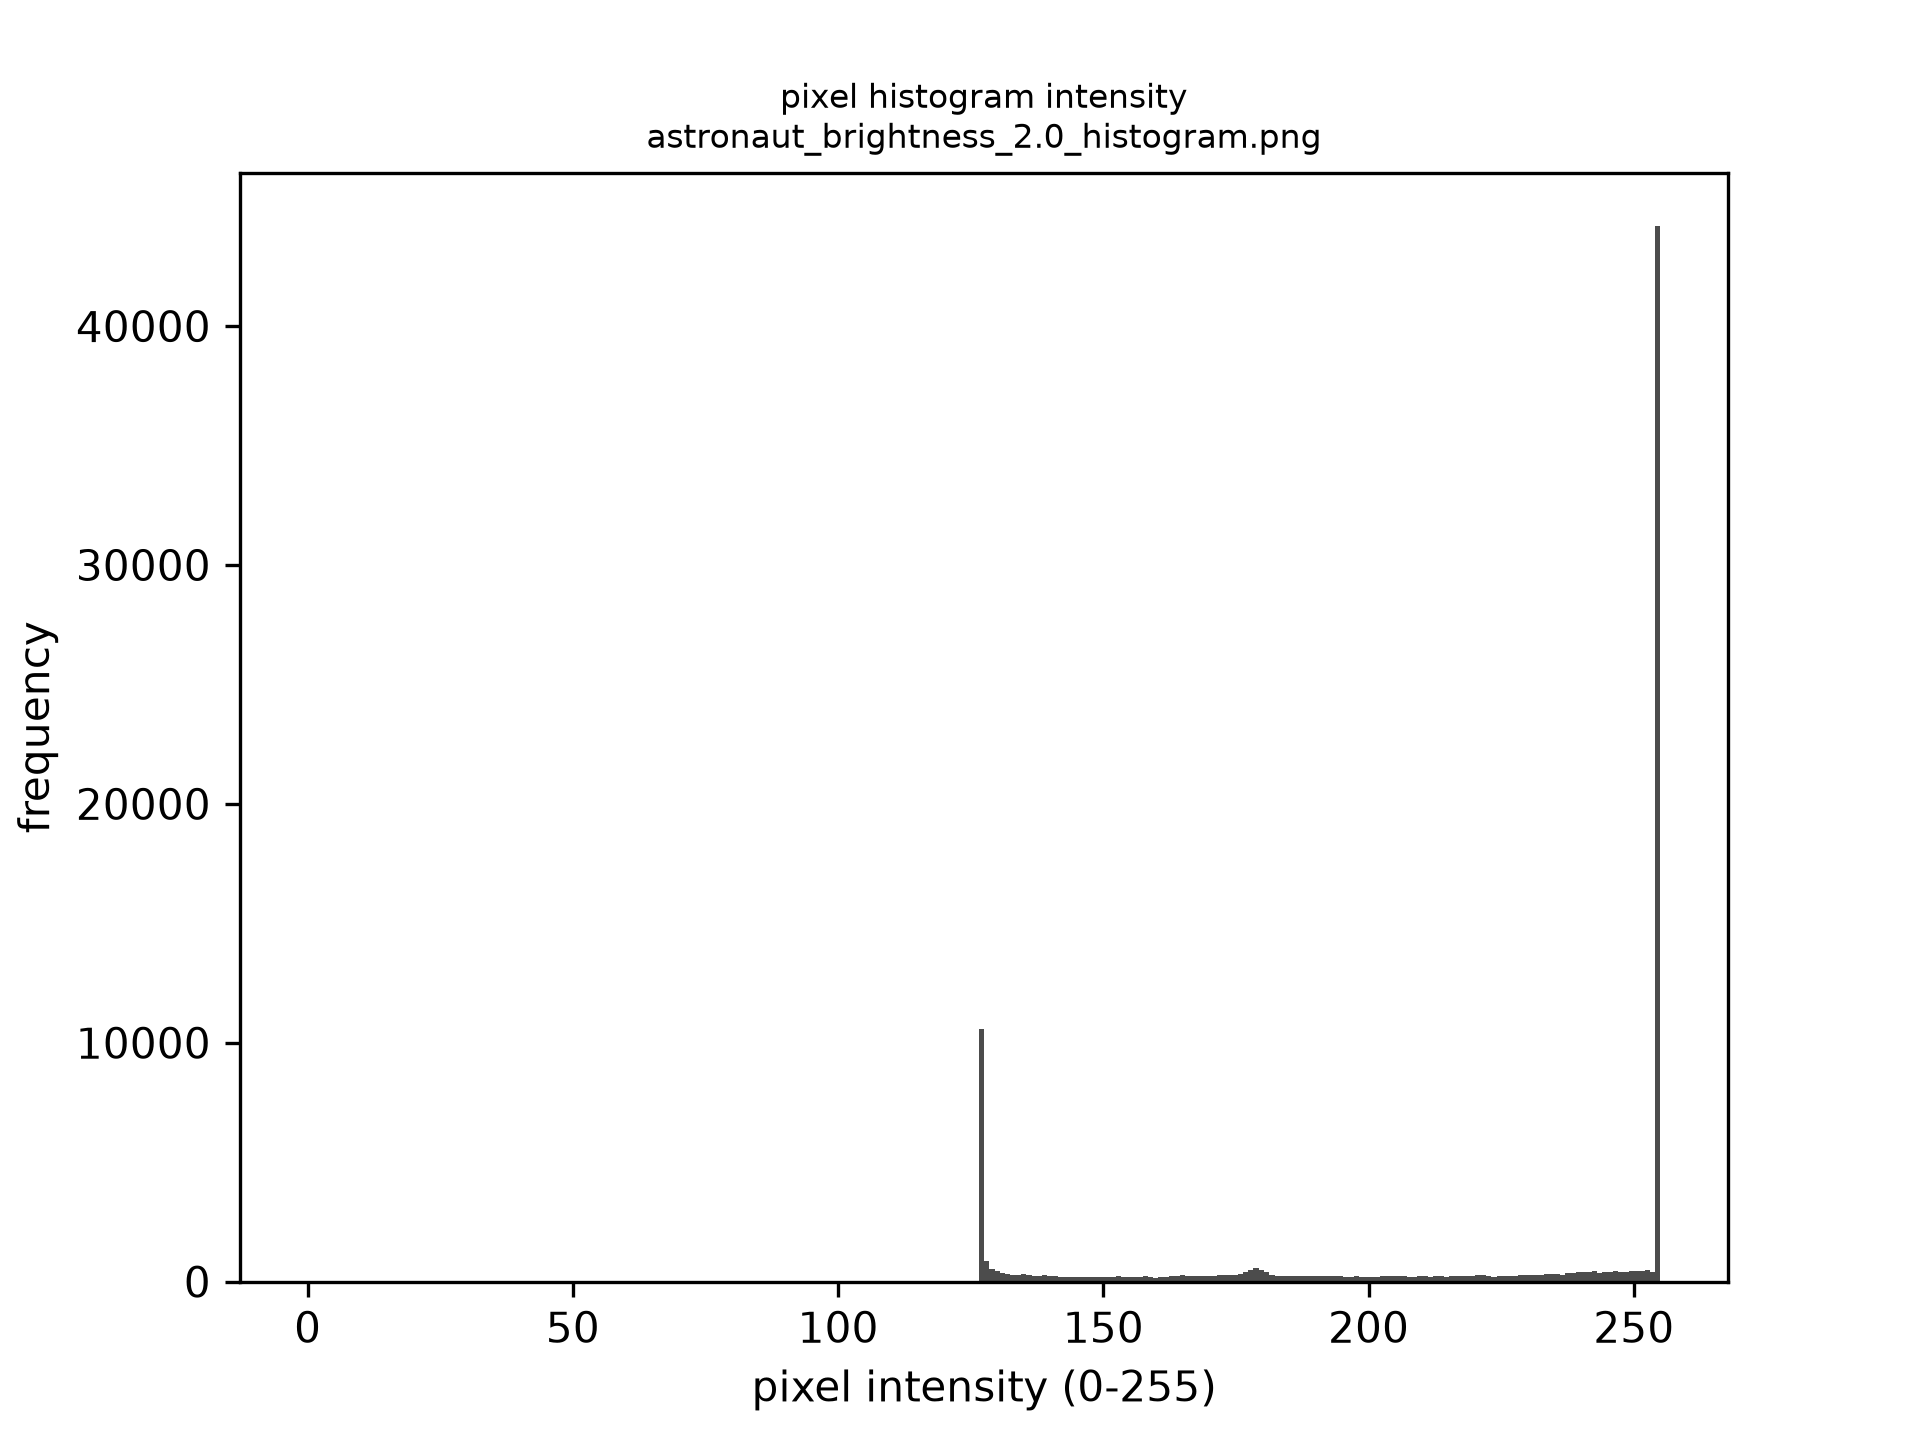 |
At factor=1.5 the histogram shifts right as a whole — midtones move into the brighter half and the mean climbs, with a few highlights starting to clip at 255. At factor=2.0 the shift is large enough that a big share of pixels pile up at that 255 ceiling, visible as a tall spike at the histogram's right edge: real detail that's been clipped away and can't be recovered.
Contrast
Contrast is the spread between an image's darkest and lightest pixels. Increasing contrast stretches the histogram outward from its own mean — darks get darker, lights get lighter — while the mean itself stays roughly where it was.
import dictk
from dictk.image import contrast, write
from dictk.plot import histogram_save

photo = dictk.astronaut(width=300, height=300)

contrast_1_5 = contrast(arr=photo, factor=1.5)
write(arr=contrast_1_5, path="astronaut_contrast_1.5.png")
histogram_save(arr=contrast_1_5, path="astronaut_contrast_1.5_histogram.png")

contrast_2_0 = contrast(arr=photo, factor=2.0)
write(arr=contrast_2_0, path="astronaut_contrast_2.0.png")
histogram_save(arr=contrast_2_0, path="astronaut_contrast_2.0_histogram.png")
Saved: astronaut_contrast_1.5.png, astronaut_contrast_2.0.png
| factor=1.0 (original) | factor=1.5 | factor=2.0 |
|---|---|---|
|  |  |
| factor=1.0 (original) | factor=1.5 | factor=2.0 |
|---|---|---|
| 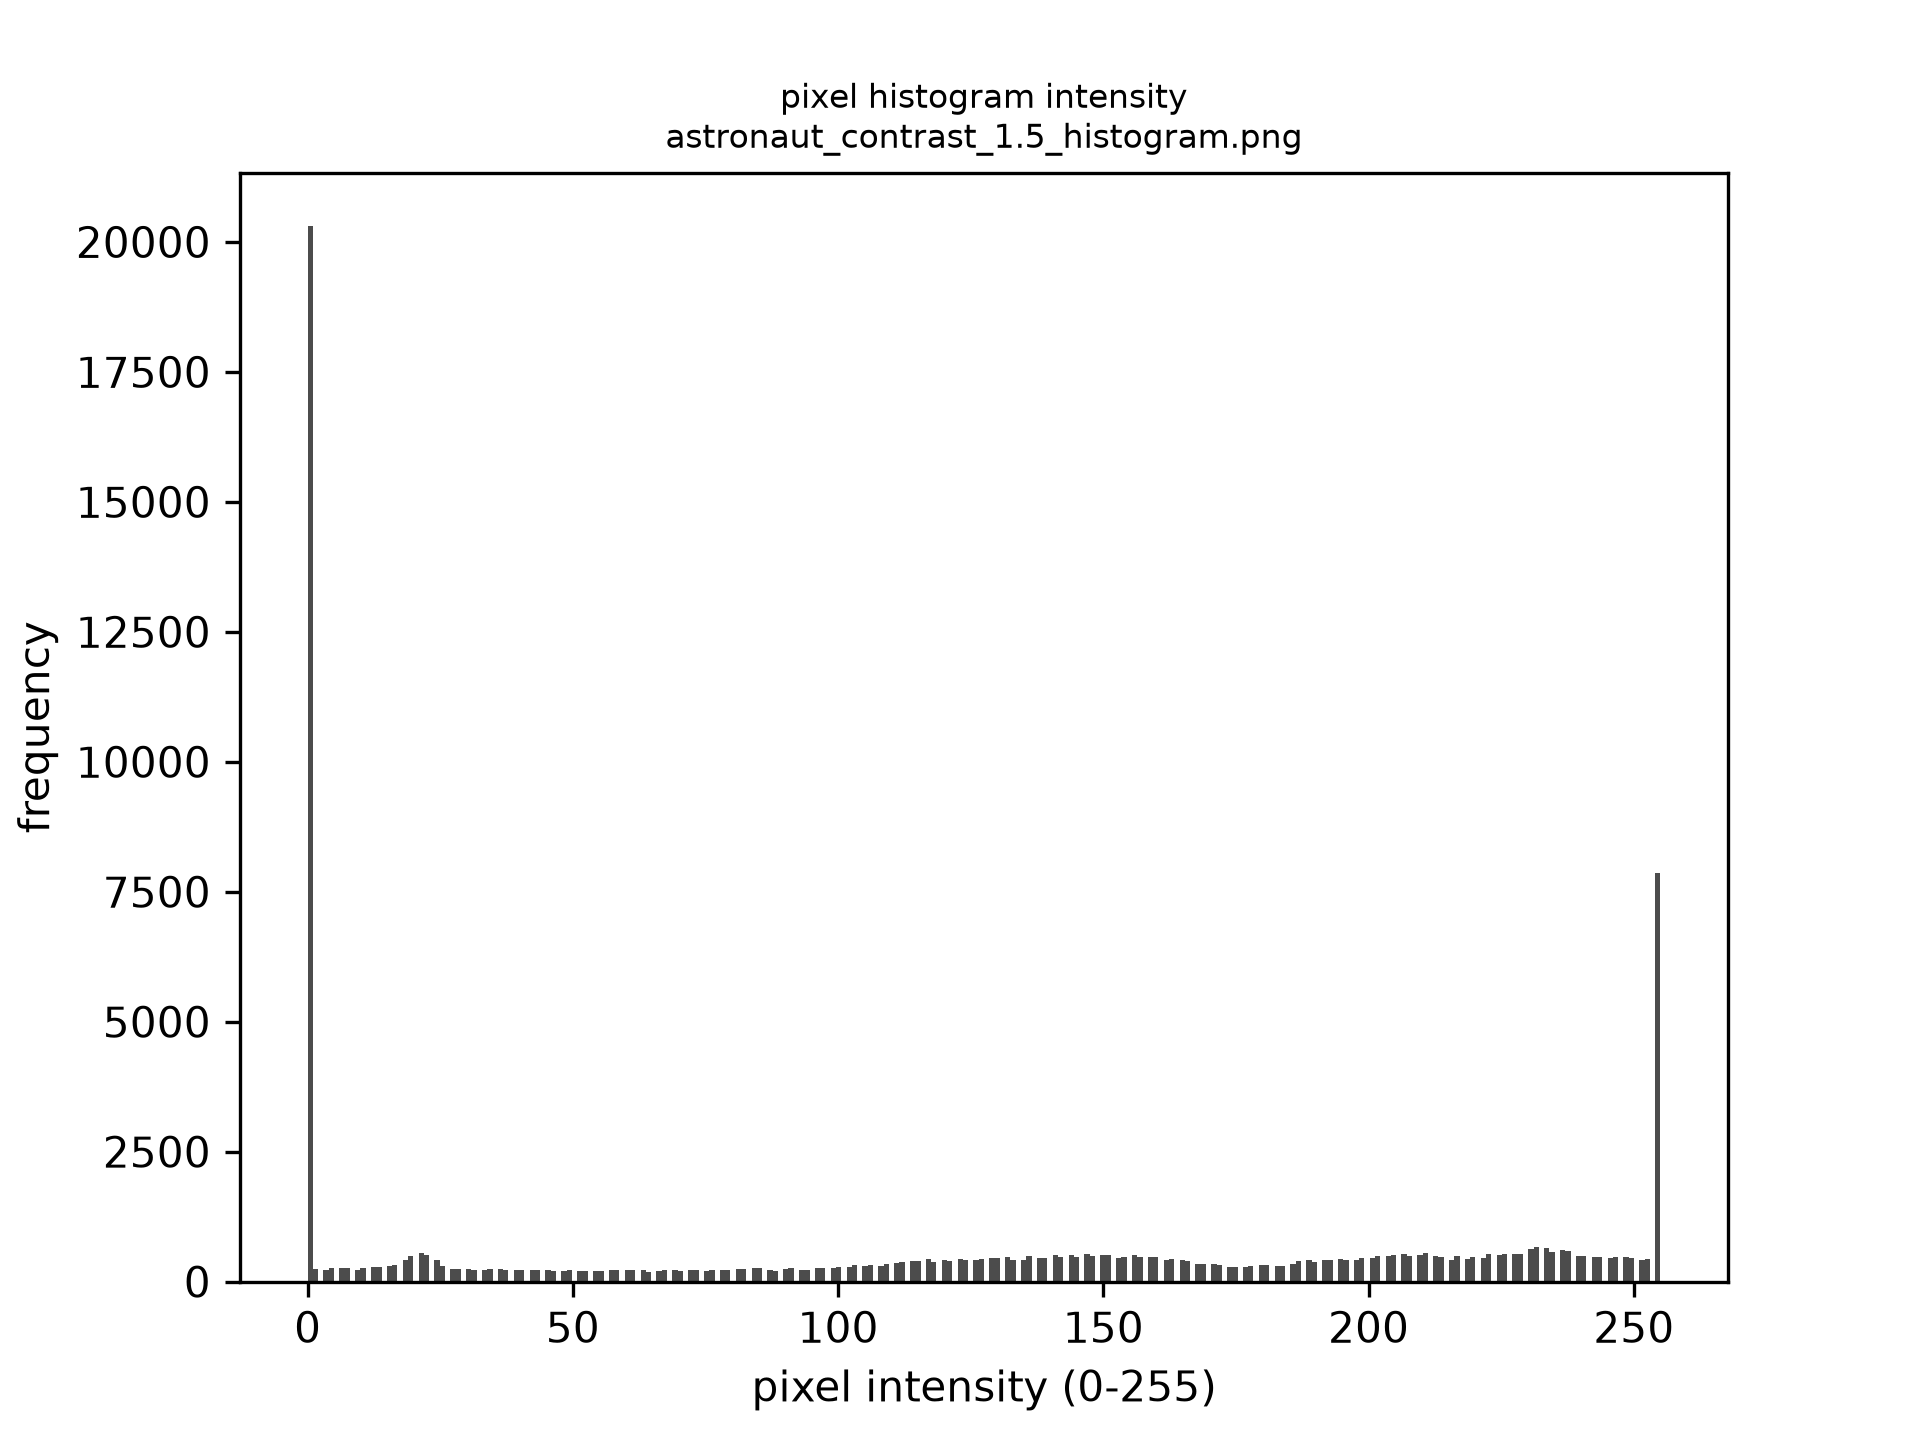 | 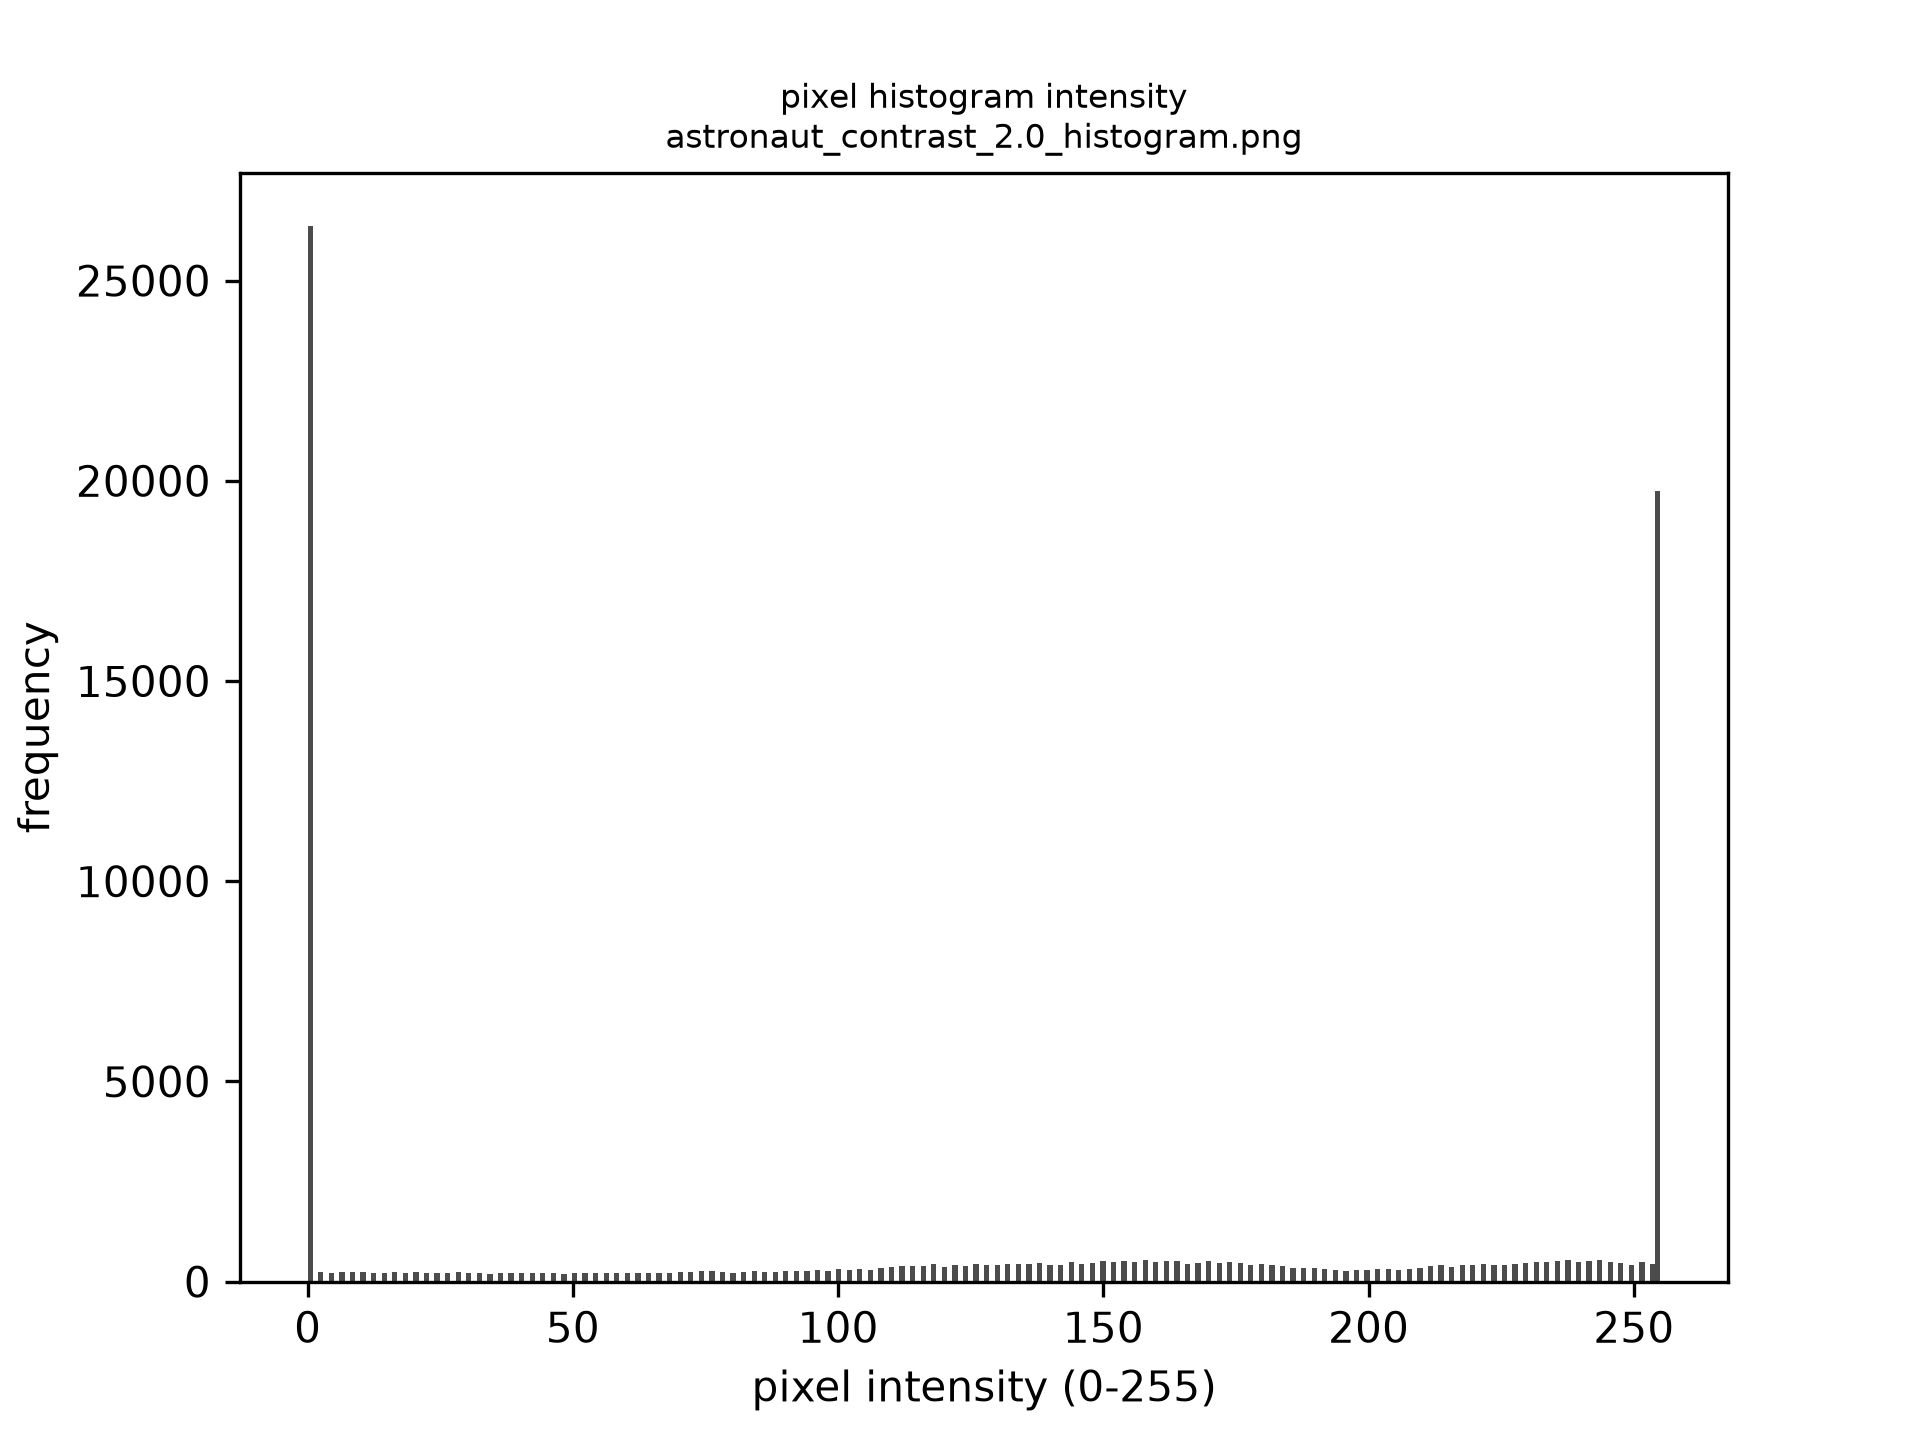 |
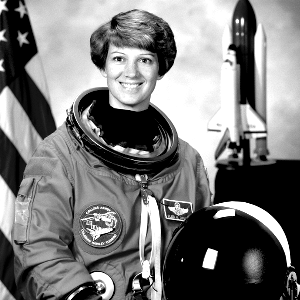
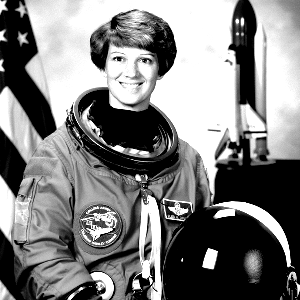
At factor=1.5 the histogram spreads outward from the mean rather than shifting — the astronaut's silhouette and helmet edges get sharper, while the mean barely moves. At factor=2.0 the spread is wide enough that more pixels pile up at both the 0 and 255 ends, crushing fine midtone detail even as high-contrast edges sharpen further.
Key Insight: Contrast stretches the histogram, while brightness translates it.
Windowing
The FFT implicitly treats an image as one period of an infinitely-repeating signal. If the content doesn't tile seamlessly, which is the general case since nothing arranges an image's edges to match up, that discontinuity leaks energy across many frequencies rather than the few the underlying content actually has, an effect called spectral leakage. In a correlation surface, leakage broadens and can shift the peak, hurting the precision of any technique that searches that surface for a match.
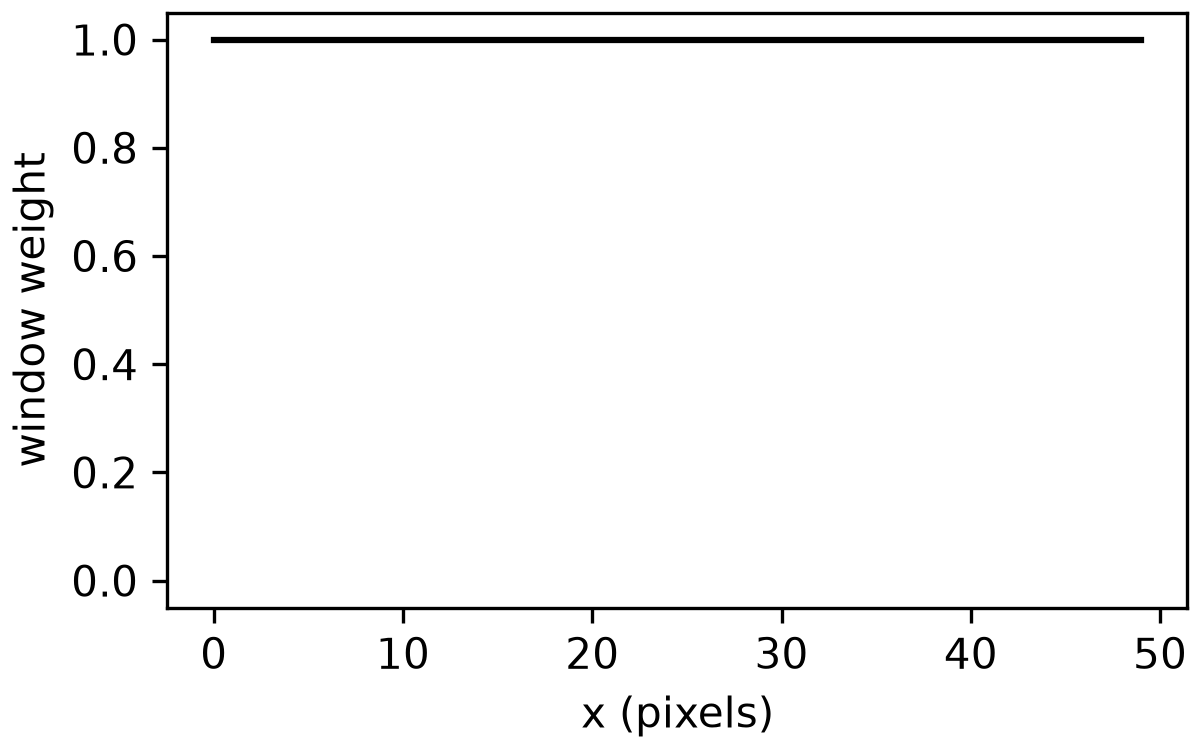
Windowing counters this by tapering an image's edges toward zero before transforming it, so the (still discontinuous, but now near-zero) seam contributes far less energy. Two standard 1D windows, applied to an image by taking the outer product of a window with itself along each axis:
for across a window of length . Hann tapers all the way to exactly zero at both ends; Hamming stops short (around ), trading a little residual discontinuity for a narrower main lobe in the transformed signal.
See Harris FJ. "On the use of windows for harmonic analysis with the discrete Fourier transform." Proceedings of the IEEE 1978;66(1):51-83. A U.S. government work, not protected by U.S. copyright.
window()
dictk.correlation.window
applies either taper to a 2D array. This reuses kernel from Cross
Correlation (CC) and the Fourier
Domain section of Correlation
Criteria — the same checkerboard0, p0, and kernel_margin — to show
what tapering actually does to an image before it's passed to an FFT:
import numpy as np
import matplotlib.pyplot as plt
from dictk.image import read, PixelCoordinate, subimage, write
from dictk.correlation import window, WindowingMethod

reference_image = read(path="checkerboard0.png")
p0 = PixelCoordinate(x=100, y=75)
kernel_margin = 25
kernel = subimage(
    image=reference_image,
    origin=PixelCoordinate(x=p0.x - kernel_margin, y=p0.y - kernel_margin),
    width=2 * kernel_margin,
    height=2 * kernel_margin,
)
write(arr=kernel, path="windowing_kernel_original.png")

kernel_hann = window(arr=kernel, method=WindowingMethod.HANN)
write(arr=kernel_hann.astype(np.uint8), path="windowing_kernel_hann.png")

kernel_hamming = window(arr=kernel, method=WindowingMethod.HAMMING)
write(arr=kernel_hamming.astype(np.uint8), path="windowing_kernel_hamming.png")

# window()'s own weights, isolated from kernel's content: windowing an
# all-ones array leaves exactly the 2D weight array behind. A single row
# at the kernel's mid-height cuts through the row axis's own peak (~1.0),
# so what's left is each method's column-axis taper alone.
mid_row = kernel.shape[0] // 2
ones = np.ones_like(kernel, dtype=np.float64)
weight_profiles = {
    "none": np.ones(kernel.shape[1]),
    "hann": window(arr=ones, method=WindowingMethod.HANN)[mid_row, :],
    "hamming": window(arr=ones, method=WindowingMethod.HAMMING)[mid_row, :],
}
for name, profile in weight_profiles.items():
    fig, ax = plt.subplots(figsize=(4, 2.5), constrained_layout=True)
    ax.plot(profile, color="black")
    ax.set_ylim(-0.05, 1.05)  # shared across all three, for a fair comparison
    ax.set_xlabel("x (pixels)")
    ax.set_ylabel("window weight")
    fig.savefig(f"windowing_kernel_cut_{name}.png", dpi=300)
    plt.close(fig)
Saved: windowing_kernel_original.png, windowing_kernel_hann.png, windowing_kernel_hamming.png, windowing_kernel_cut_none.png, windowing_kernel_cut_hann.png, windowing_kernel_cut_hamming.png
| none | Hann | Hamming |
|---|---|---|
 |  |  |
 | 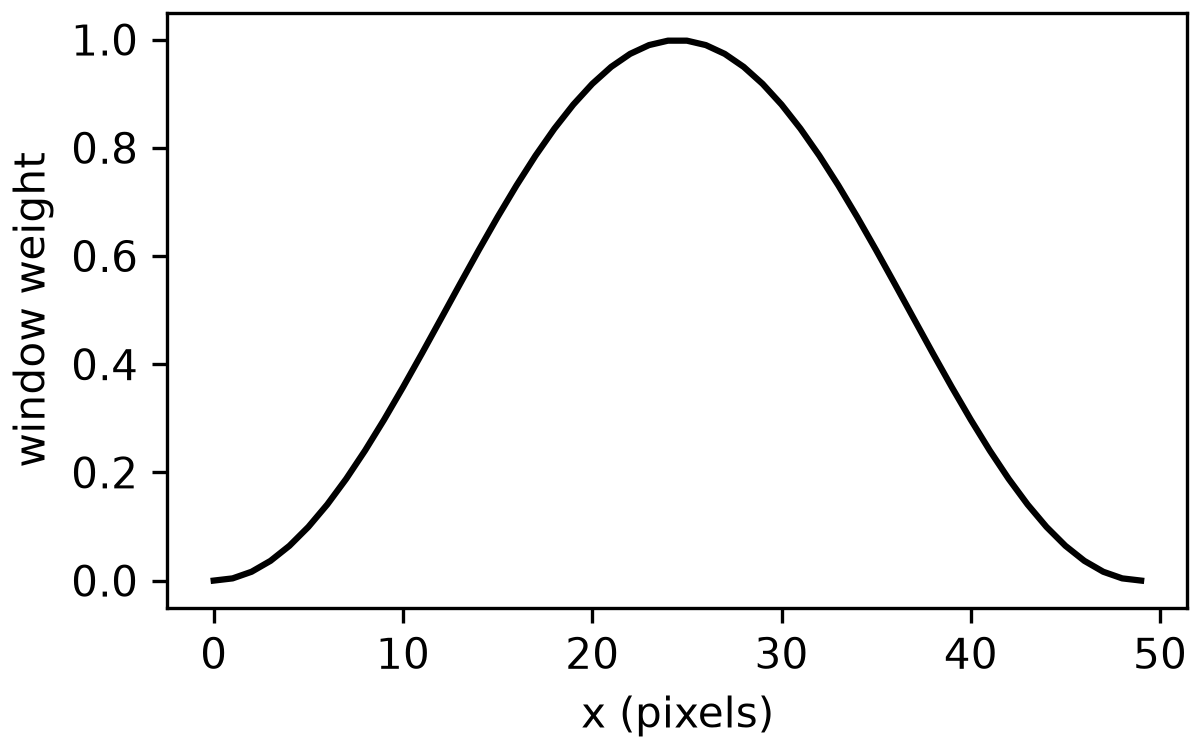 | 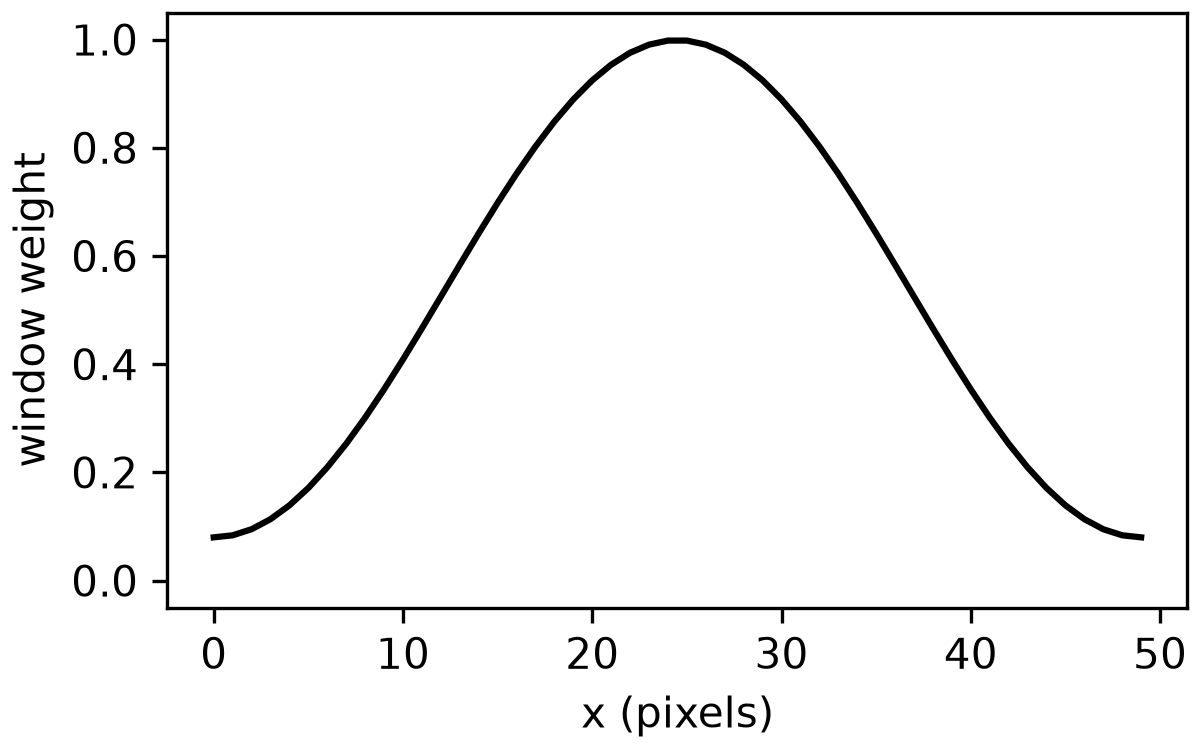 |
Every edge fades toward black; Hann's corners go fully black (tapers to exactly 0), while Hamming's stay a faint gray (tapers to of the original corner pixel, the product of both axes' own edge value).
The bottom row makes each method's own taper precise, independent of
checkerboard0's content: a horizontal cut through the window's weight
array at the kernel's mid-height, all three sharing the same -axis.
none is flat at everywhere -- no taper at all. Hann and Hamming
both peak at at that same mid-height (the row axis's own window is
near its own peak there), so this cut isolates the column axis's taper
alone: Hann reaches exactly at both edges, Hamming levels off at
-- not the smaller corner value above, since a corner is
where both axes are simultaneously at their own edge, and a mid-height
cut only ever passes through one axis's edge at a time.
See Correlation Visualization for windowing shown in action, tapering a real kernel and search area before they're compared.
Image Transformation
Image deformations, also called transformations in the computer vision literature (see Szeliski1), fall into the categories shown below:
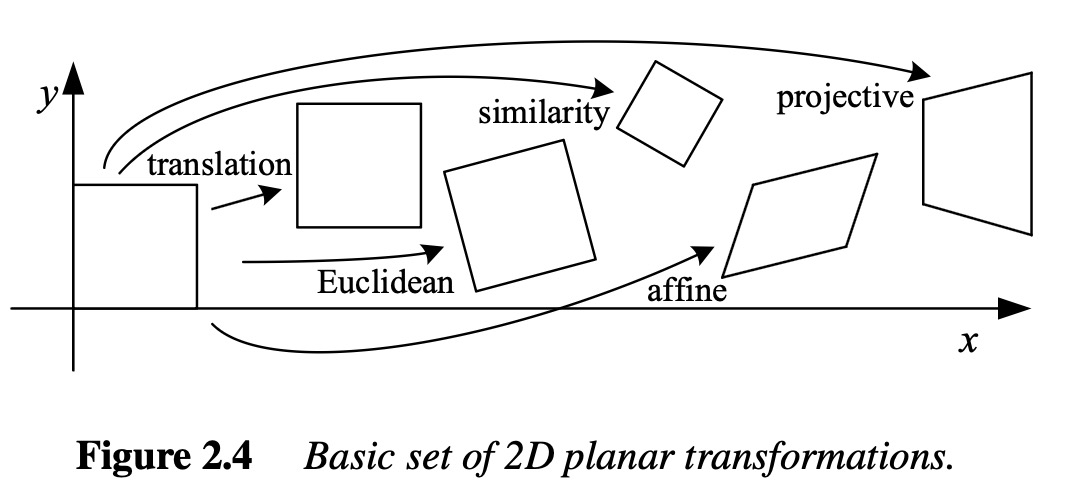
Each category preserves a different, nested set of geometric properties — every property a category preserves is also preserved by every more restrictive category to its left:
| Property | Translation | Euclidean | Similarity | Affine | Projective |
|---|---|---|---|---|---|
| Straight lines stay straight | Yes | Yes | Yes | Yes | Yes |
| Parallel lines stay parallel | Yes | Yes | Yes | Yes | No |
| Angles preserved | Yes | Yes | Yes | No | No |
| Lengths/distances preserved | Yes | Yes | No | No | No |
| Absolute orientation preserved (no rotation) | Yes | No | No | No | No |
Pure Translation (Rigid Body Motion)
As the simplest of the categories above — no change in shape or size —
dictk.image.translate shifts
every pixel by a fixed displacement. This example shifts the image by
dx=-60 pixels in x and dy=+80 pixels in y, representing rigid-body
motion where the material moves without deforming.
import dictk
from dictk.image import translate, write

photo = dictk.astronaut(width=300, height=300)
write(arr=photo, path="astronaut_translate_original.png")

translated = translate(arr=photo, dx=-60, dy=80)
write(arr=translated, path="astronaut_translate_rigid_body.png")
Saved: astronaut_translate_original.png, astronaut_translate_rigid_body.png
| Translation | Image |
|---|---|
| Original | 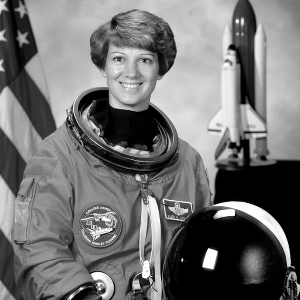 |
| dx=-60, dy=+80 | 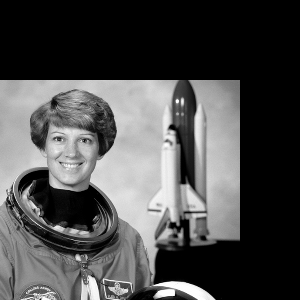 |
Pure Rotation
A 30° counterclockwise rotation, another rigid-body motion that preserves
distances and angles.
dictk.image.rotate pivots on the
image's top-left corner (0, 0), consistent with stretch and
translate's pivot choice in this codebase — unlike the more typical
"object spins in place" rotation about the center, most content swings
away from that fixed corner, similar to a door on a hinge.
import dictk
from dictk.image import rotate, write

photo = dictk.astronaut(width=300, height=300)
write(arr=photo, path="astronaut_rotate_original.png")

rotated = rotate(arr=photo, angle=30.0)
write(arr=rotated, path="astronaut_rotate_30deg.png")
Saved: astronaut_rotate_original.png, astronaut_rotate_30deg.png
| Rotation | Image |
|---|---|
| Original | 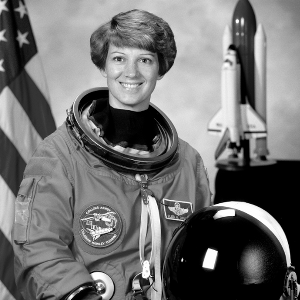 |
| 30° (origin-pivoted) | 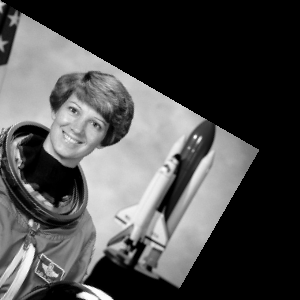 |
X-Axis Stretch (Extension)
As a concrete example of the similarity category above,
dictk.image.stretch applies a
uniaxial stretch along the x-axis: the image's top-left corner (x=0, y=0)
stays fixed, and content grows away from it, using backward mapping with
bilinear interpolation so the result has no gaps (unlike naively moving
each source pixel forward, which can leave holes). The two stretches
below range from a small, realistic deformation (5%, similar in magnitude
to a modest tensile strain in a materials test) up to a much larger one
(50%).
import dictk
from dictk.image import stretch, write

photo = dictk.astronaut(width=300, height=300)
write(arr=photo, path="astronaut_stretch_original.png")

stretch_5pct = stretch(arr=photo, factor_x=1.05)
write(arr=stretch_5pct, path="astronaut_stretch_x_5pct.png")

stretch_50pct = stretch(arr=photo, factor_x=1.50)
write(arr=stretch_50pct, path="astronaut_stretch_x_50pct.png")
Saved: astronaut_stretch_original.png, astronaut_stretch_x_5pct.png, astronaut_stretch_x_50pct.png
| Stretch | Image |
|---|---|
| Original | 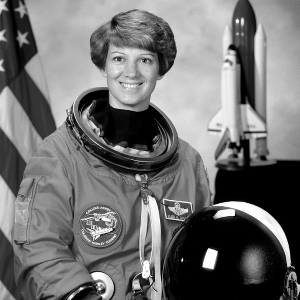 |
| 5% (factor_x=1.05) | 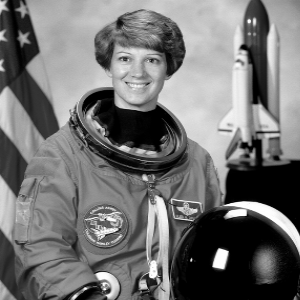 |
| 50% (factor_x=1.50) | 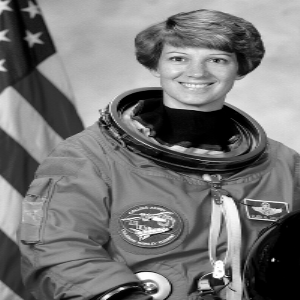 |
Y-Axis Stretch (Compression)
The same dictk.image.stretch
function compresses along the y-axis with factor_y < 1.0. Pivoting on
the origin means the top edge (y=0) stays fixed while content shrinks
toward it, leaving a black margin along the bottom — the mirror image of
the x-axis stretch case, where growth away from the origin never leaves a
gap.
import dictk
from dictk.image import stretch, write

photo = dictk.astronaut(width=300, height=300)
write(arr=photo, path="astronaut_compress_original.png")

compress_neg5pct = stretch(arr=photo, factor_y=0.95)
write(arr=compress_neg5pct, path="astronaut_compress_y_neg5pct.png")

compress_neg50pct = stretch(arr=photo, factor_y=0.50)
write(arr=compress_neg50pct, path="astronaut_compress_y_neg50pct.png")
Saved: astronaut_compress_original.png, astronaut_compress_y_neg5pct.png, astronaut_compress_y_neg50pct.png
| Compression | Image |
|---|---|
| Original | 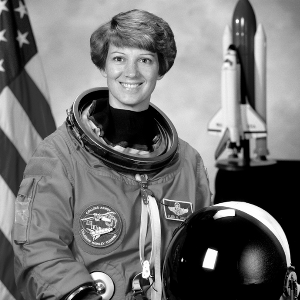 |
| -5% (factor_y=0.95) | 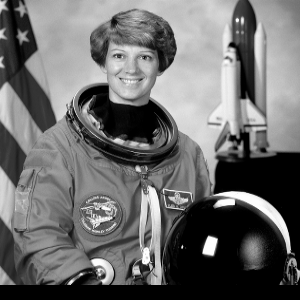 |
| -50% (factor_y=0.50) | 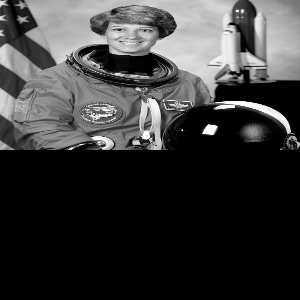 |
Simple Shear
A shear deformation with γ = 0.5, where horizontal planes slide relative
to each other by an amount proportional to their y-coordinate — the
higher up a row of pixels, the further it shifts sideways.
dictk.image.shear pivots on the
image's top-left corner (0, 0), consistent with the other transform
functions in this codebase.
import dictk
from dictk.image import shear, write

photo = dictk.astronaut(width=300, height=300)
write(arr=photo, path="astronaut_shear_original.png")

sheared = shear(arr=photo, shear_x=0.5)
write(arr=sheared, path="astronaut_shear_x_0.5.png")
Saved: astronaut_shear_original.png, astronaut_shear_x_0.5.png
| Shear | Image |
|---|---|
| Original | 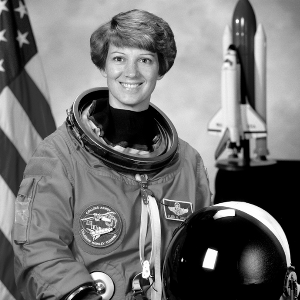 |
| γ = 0.5 (shear_x=0.5) | 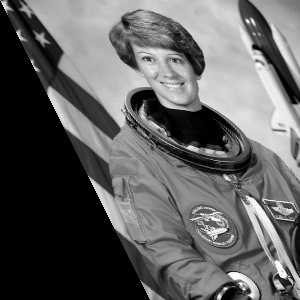 |
Complex Deformation
Combines rotation (15°) with anisotropic stretching (1.3x in x, 0.8x in
y) — realistic loading scenarios where materials experience multiple
simultaneous deformation modes, typically the hardest case for
correlation algorithms.
dictk.image.complex_deform
composes the two into a single deformation gradient (stretch applied
first, then rotation) and applies it in one backward-mapping pass, so
the result isn't blurred by interpolating twice as calling stretch
and then rotate separately would.
import dictk
from dictk.image import complex_deform, write

photo = dictk.astronaut(width=300, height=300)
write(arr=photo, path="astronaut_complex_original.png")

combined = complex_deform(arr=photo, factor_x=1.3, factor_y=0.8, angle=15.0)
write(arr=combined, path="astronaut_complex_deform.png")
Saved: astronaut_complex_original.png, astronaut_complex_deform.png
| Composed Deformation | Image |
|---|---|
| Original | 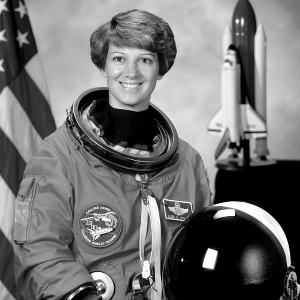 |
| factor_x=1.3, factor_y=0.8, angle=15° | 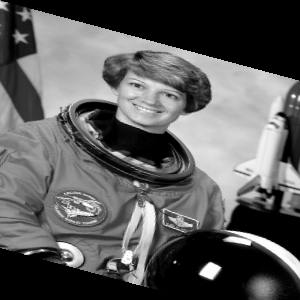 |
Crack Dislocation
A vertical crack splits the image at x = width/2: the left half shifts down 4 pixels and the right half shifts up 4 pixels, producing a displacement field that jumps discontinuously across the crack line — unlike every other example on this page, which deforms smoothly. Standard DIC assumes smooth displacements and cannot capture this jump; cases like this motivate the Heaviside finite-element formulation.
dictk's own y-axis points down the page, not up (see Multi-Point
Motion for this
same sign convention). So +4 here means the left half shifts down.
-4 means the right half shifts up.
import dictk
from dictk.image import crack_dislocation, write

photo = dictk.astronaut(width=300, height=300)
write(arr=photo, path="astronaut_crack_plain_original.png")

cracked_plain = crack_dislocation(arr=photo, offset=4.0)
write(arr=cracked_plain, path="astronaut_crack_plain_dislocation.png")
Saved: astronaut_crack_plain_original.png, astronaut_crack_plain_dislocation.png
| Crack Dislocation | Image |
|---|---|
| Original | 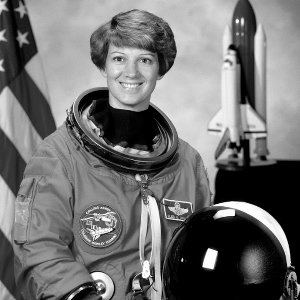 |
| offset=4 pixels | 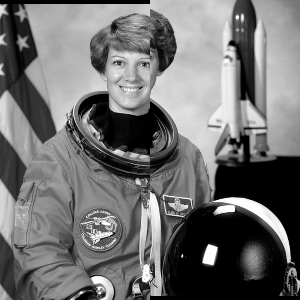 |
References
-
Szeliski R. Computer vision: algorithms and applications, 2nd Edition, Springer Nature; 2022 Jan 3. download (43 MB) ↩
Single Point Motion
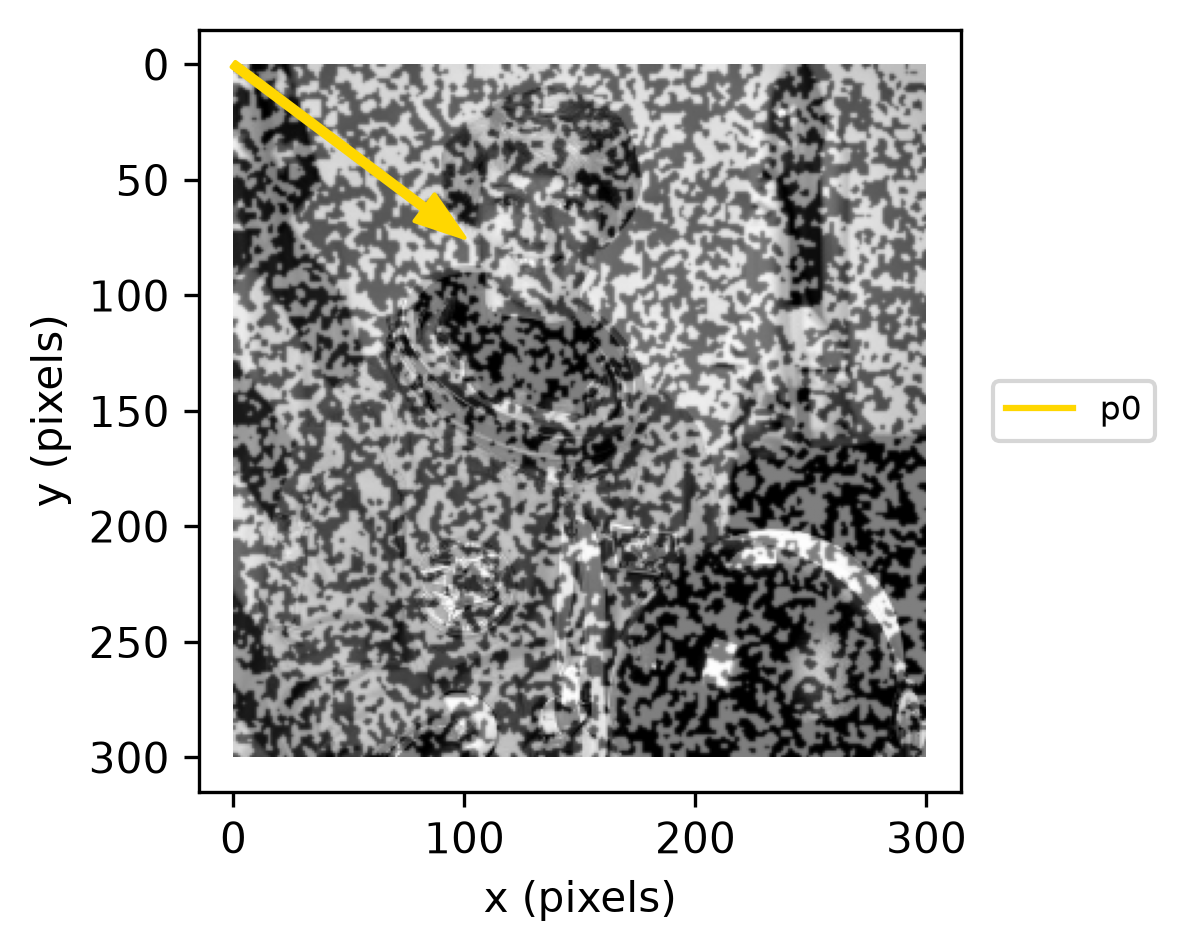
Consider a single point , fixed to a physical location on the object being imaged. In the reference image , this point is located at a known pixel location, for example pixels. This vector, from the origin of the reference image frame to the pixel point , locates the reference configuration. For brevity, we will use to denote the fully explicit vector .
Next, the object is moved (e.g., translated, rotated, stretched, or deformed — see Image Transformation). A second image , called the current image, is taken. Where is point from located in ? We label point 's found location in as . For brevity, we will use to denote the fully explicit vector .
Note that the camera itself has not moved, only the object and any point of interest on the object have moved. The origin and the reference frame are the same across the two images and .
The canonical problem solved by digital image correlation (DIC) is as follows:
- Given a point in image , find the location of that same point in image .
Below, we motivate this canonical problem with a simple example of a single
point translation. We first develop a manual solution to serve as the known
ground truth. Then, we illustrate how
dictk.translation.locate
solves this problem numerically via DIC.
Reference Configuration
The examples below reuse checkerboard0, the speckle pattern combined
with the checkerboard introduced in Image
Generation. This will be the
reference_image, matching locate's own parameter name:
from dictk.image import read, PixelCoordinate
from dictk.plot import point_plot, ArrowAnnotation

reference_image = read(path="checkerboard0.png")

p0 = PixelCoordinate(x=100, y=75)
point_plot(
    image=reference_image,
    arrows=[
        ArrowAnnotation(
            tail=PixelCoordinate(x=0, y=0), head=p0, color="orange", label=r"$\boldsymbol{p}_0$"
        )
    ],
    figsize=(6.4, 4.8),
    path="single_point_motion_p0.png",
)
Saved: single_point_motion_p0.png
Current Configuration and Displacement
For this page, the current image is generated with
dictk.image.translate (see Image
Transformation): every pixel of
reference_image shifts by the same (dx, dy), a rigid-body
translation. Because the whole
image moves together, point 's new location follows directly:
from dictk.image import translate

dx, dy = -6, 8
current_image = translate(arr=reference_image, dx=dx, dy=dy)
p1 = PixelCoordinate(x=p0.x + dx, y=p0.y + dy)  # ground truth, known here by construction
We define the displacement of the point as the relative motion between the reference configuration and the current configuration , such that
so with and ,
point_plot(
    image=current_image,
    arrows=[
        ArrowAnnotation(
            tail=PixelCoordinate(x=0, y=0), head=p0, color="orange", label=r"$\boldsymbol{p}_0$"
        ),
        ArrowAnnotation(
            tail=PixelCoordinate(x=0, y=0), head=p1, color="cyan", label=r"$\boldsymbol{p}_1$"
        ),
        ArrowAnnotation(
            tail=p0, head=p1, color="magenta", label=r"$\delta \boldsymbol{p}$"
        ),
    ],
    figsize=(6.4, 4.8),
    path="single_point_motion_p1_displacement.png",
)
Saved: single_point_motion_p1_displacement.png
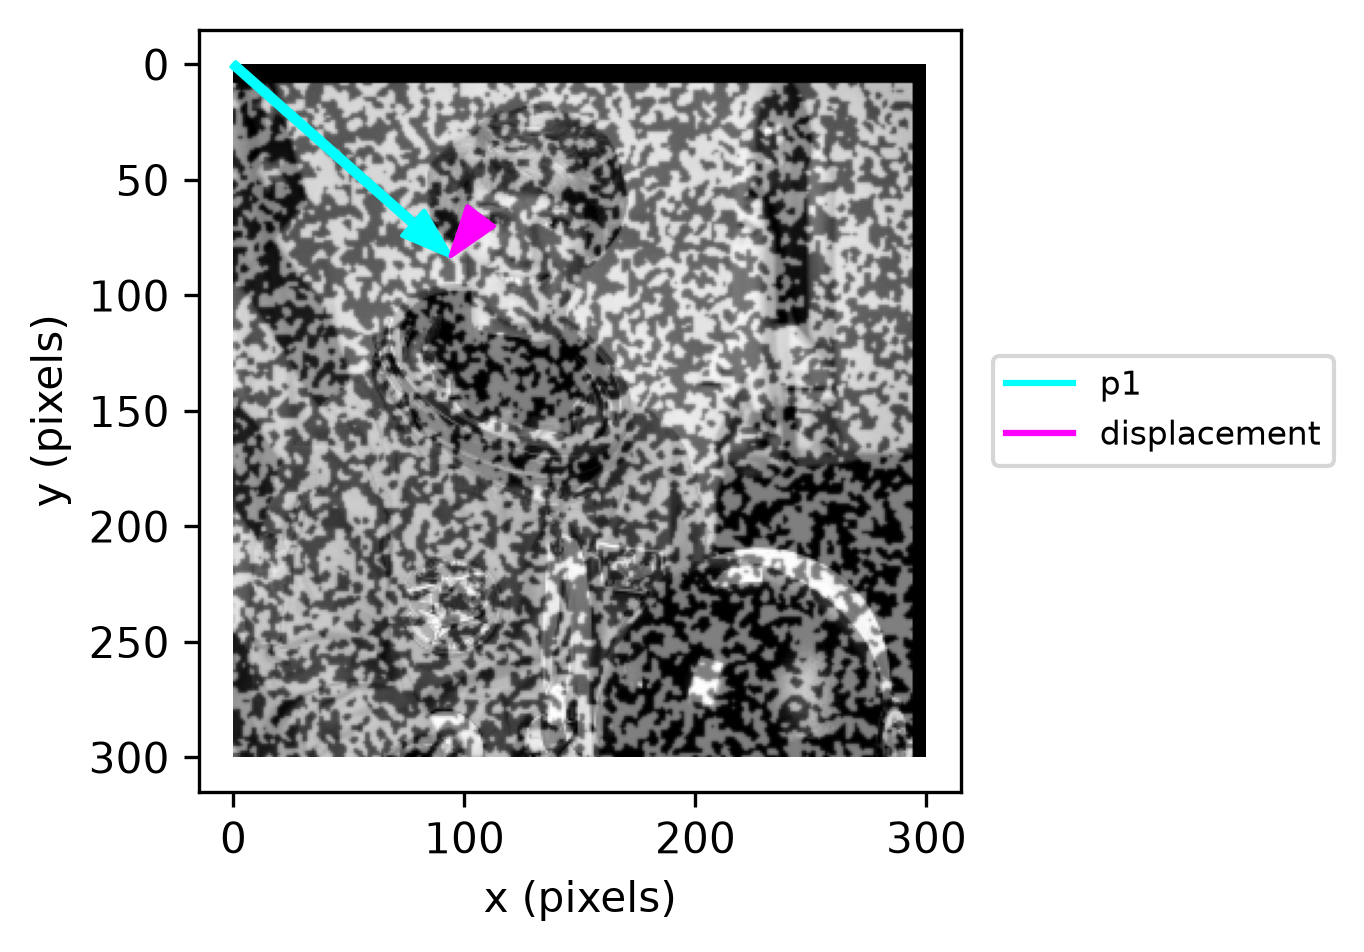
In the example above, p1 was only known in advance because we generated
current_image ourselves with a known translate. In practice, the
location is unknown and found via DIC of a pair of images.
Below, we illustrate the canonical DIC process:
- Given a in the
reference_image, find in thecurrent_image.
The next page, Cross Correlation (CC), shows how the
locate function calculates directly, using the
technique its name describes.
Cross Correlation (CC)
Cross-correlation can be used to find where point in the reference_image
can be found in the current_image.
There are many different implementations of cross-correlation. We discuss the varied implementations in Correlation Criteria. For now, it is sufficient to know only that cross-correlation is used to locate a point in a current image given a known location of that same point in a reference image. The current focus is to make the subordinate concepts underlying cross-correlation be well-defined and well-illustrated.
Let the kernel (also called a subset, filter, or
convolution matrix) be a rectangular region of reference_image centered on
, the vector that locates point from origin in the reference_image.
The kernel is a small, distinctive patch of the reference image
content that we want to locate within a subsequent image.
In the needle in a haystack idiom, the kernel is the needle, and the
haystack is current_image. To keep the search tractable, we don't
search the entire haystack — we constrain it to a search area (also
called the area of interest (AOI), search window, or scanning zone).
The search area is a subimage of the current_image, centered on a search_center, which is a guess of roughly where ended up, not the answer
itself.
While there are techniques derived from macro deformation metrics that can
provide a good first guess for the search_center, for simplicity, and since
the deformations are small, we reuse itself as the search_center
in this example.
Because the kernel and search area are themselves subimages of a larger image (see Subimage Generation), each subimage has its own local frame:
- Let be the reference frame of the kernel subimage.
- Let be the reference frame of the search area subimage.
reference_image, p0, current_image, and p1 are the same as in
Single Point Motion:
from dictk.image import read, translate, PixelCoordinate

reference_image = read(path="checkerboard0.png")
p0 = PixelCoordinate(x=100, y=75)
dx, dy = -6, 8
current_image = translate(arr=reference_image, dx=dx, dy=dy)
p1 = PixelCoordinate(x=p0.x + dx, y=p0.y + dy)
Kernel
From reference_image, extract the kernel surrounding ,
with a 25-pixel margin on every side (50x50 total):
from dictk.plot import subimage_comparison_plot

kernel_margin = 25
kernel_origin = PixelCoordinate(x=p0.x - kernel_margin, y=p0.y - kernel_margin)
subimage_comparison_plot(
    image=reference_image,
    origin=kernel_origin,
    width=2 * kernel_margin,
    height=2 * kernel_margin,
    point=p0,
    point_color="orange",
    point_label="$P$",
    subimage_label="kernel",
    color="green",
    origin_label="$K$",
    source_origin_label="$O$",
    figsize=(6.4, 4.8),
    path="single_point_motion_kernel.png",
)
Saved: single_point_motion_kernel.png
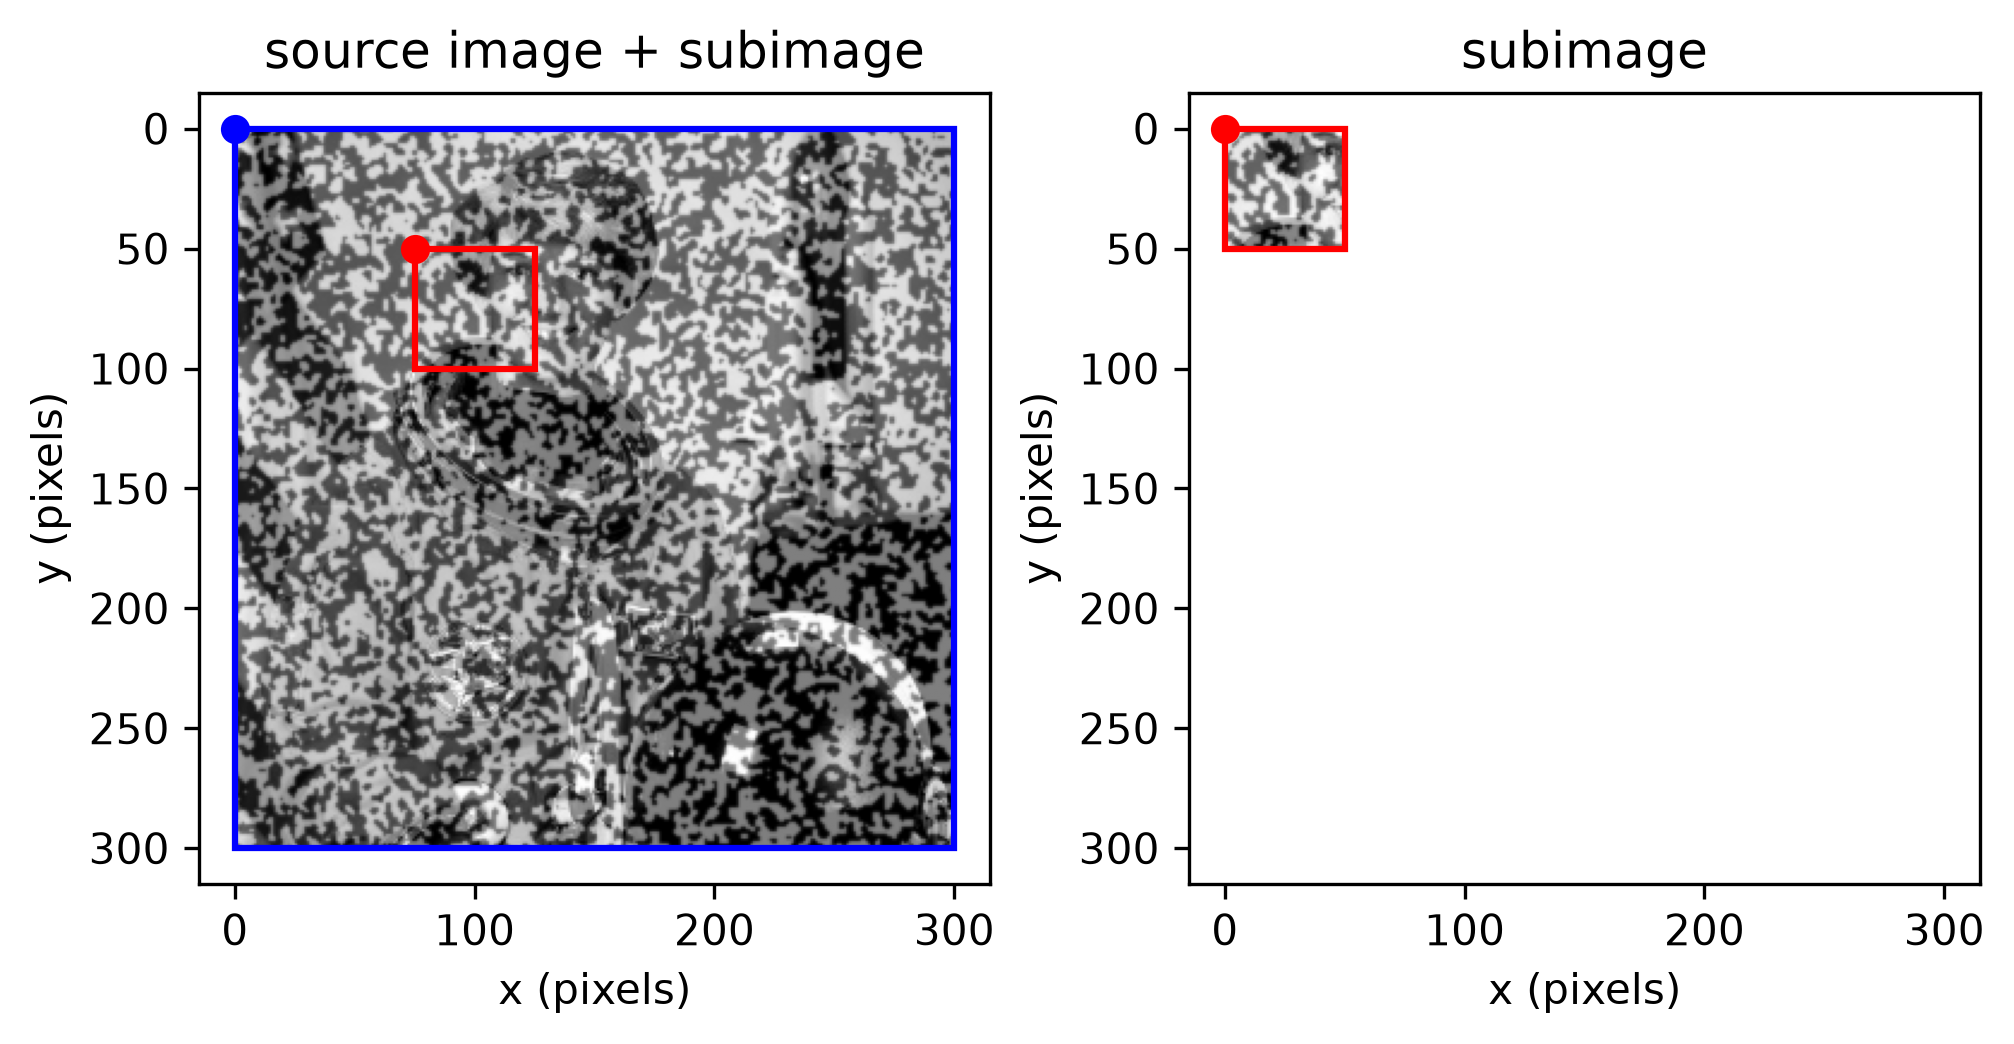
reference_image centered on , with origin pixels (green dot); point itself is the orange dot at . Right: the extracted kernel, in its own local reference frame ; the same point (orange dot) is now at pixels.The kernel has its own local coordinate system , with origin at its top-left corner. Point 's position is the same in both frames, just expressed relative to a different origin:
Since the kernel is centered on with a 25-pixel margin,
pixels. Point always
sits at (kernel_margin_width, kernel_margin_height) within the kernel's
own frame, regardless of where the kernel came from in reference_image.
Search Area
From current_image, extract the search area surrounding
search_center (here, again, since it is currently our best guess), with a 50-pixel margin
on every side (100x100 total):
search_margin = 50
search_center = p0
search_origin = PixelCoordinate(
    x=search_center.x - search_margin, y=search_center.y - search_margin
)
subimage_comparison_plot(
    image=current_image,
    origin=search_origin,
    width=2 * search_margin,
    height=2 * search_margin,
    subimage_label="search area",
    origin_label="$S$",
    source_origin_label="$O$",
    figsize=(6.4, 4.8),
    path="single_point_motion_search.png",
)
Saved: single_point_motion_search.png
current_image centered on search_center, with origin pixels (red dot); the source image's own origin is labeled , the search area's origin is labeled . Right: the extracted search area on its own, in its own local reference frame , with origin .The search area likewise has its own local frame , origin
at its top-left corner. The location of in the current_image is given by:
The goal of the DIC process is to locate by solving for the quantity . The location of in the search area's local frame is the single unknown; all other vectors are known.
Solution
The insight into the solution is to further decompose into the sum of two additional vectors:
The second term, , is a known constant. The first term, , is unknown and can be calculated using cross-correlation. When the kernel and search area subimages align, their cross-correlation is maximized. We find the maximum cross-correlation to determine and thus calculate .
This is exactly what
dictk.translation.locate computes
internally — via
skimage.registration.phase_cross_correlation
for .
The locate function returns directly (one does not assemble the
vector chain manually).
phase_cross_correlation is a Fourier-domain computation — every locate
call in this book takes that route under the hood, rather than sliding
the kernel across the search area one position at a time. Correlation
Criteria examines that
Fourier-domain implementation in greater depth, alongside the
spatial-domain CC, NCC, ZCC, and ZNCC criteria it complements.
Locating the Point
from dictk.translation import locate

found = locate(
    reference_image=reference_image,
    current_image=current_image,
    reference_point=p0,
    search_center=search_center,
    kernel_margin_width=kernel_margin,
    kernel_margin_height=kernel_margin,
    search_margin_width=search_margin,
    search_margin_height=search_margin,
)
print(f"found = {found}")
print(f"displacement = ({found.x - p0.x}, {found.y - p0.y})")
found = PixelCoordinate(x=94, y=83)
displacement = (-6, 8)
found matches the ground-truth pixels from
earlier, recovering the known displacement
pixels using only the two images and — exactly the
information available for a real (not synthetically generated) image
pair.
Visualizing the Solution
For illustration, we can back out — the
one quantity locate finds via cross-correlation, everything else here
being known geometry — from found and the boxed equation above, and
draw the full chain on
current_image:
from dictk.plot import point_plot, ArrowAnnotation, BoxAnnotation, PointAnnotation

r_sk = PixelCoordinate(
    x=found.x - search_origin.x - kernel_margin,
    y=found.y - search_origin.y - kernel_margin,
)
kernel_found_origin = PixelCoordinate(
    x=search_origin.x + r_sk.x, y=search_origin.y + r_sk.y
)
image_height, image_width = current_image.shape
point_plot(
    image=current_image,
    boxes=[
        BoxAnnotation(
            origin=PixelCoordinate(x=0, y=0),
            width=image_width,
            height=image_height,
            color="blue",
            label="source image",
        ),
        BoxAnnotation(
            origin=search_origin,
            width=2 * search_margin,
            height=2 * search_margin,
            color="red",
            label="search area",
        ),
        BoxAnnotation(
            origin=kernel_found_origin,
            width=2 * kernel_margin,
            height=2 * kernel_margin,
            color="green",
            label="kernel",
        ),
    ],
    points=[
        PointAnnotation(position=PixelCoordinate(x=0, y=0), label="$O$", color="blue"),
        PointAnnotation(position=search_origin, label="$S$", color="red"),
        PointAnnotation(position=kernel_found_origin, label="$K$", color="green"),
        PointAnnotation(position=found, label="$P$", color="black"),
    ],
    arrows=[
        ArrowAnnotation(
            tail=PixelCoordinate(x=0, y=0),
            head=found,
            color="cyan",
            label=r"$\boldsymbol{r}_{OP'/\mathcal{F}}$",
        ),
        ArrowAnnotation(
            tail=PixelCoordinate(x=0, y=0),
            head=search_origin,
            color="blue",
            label=r"$\boldsymbol{r}_{OS/\mathcal{F}}$: search area origin",
        ),
        ArrowAnnotation(
            tail=search_origin,
            head=kernel_found_origin,
            color="red",
            label=r"$\boldsymbol{r}_{SK/\mathcal{S}}$: kernel found in search area",
        ),
        ArrowAnnotation(
            tail=kernel_found_origin,
            head=found,
            color="green",
            label=r"$\boldsymbol{r}_{KP/\mathcal{K}}$: point within kernel",
        ),
    ],
    figsize=(6.4, 4.8),
    path="single_point_motion_solution_vectors.png",
)
Saved: single_point_motion_solution_vectors.png
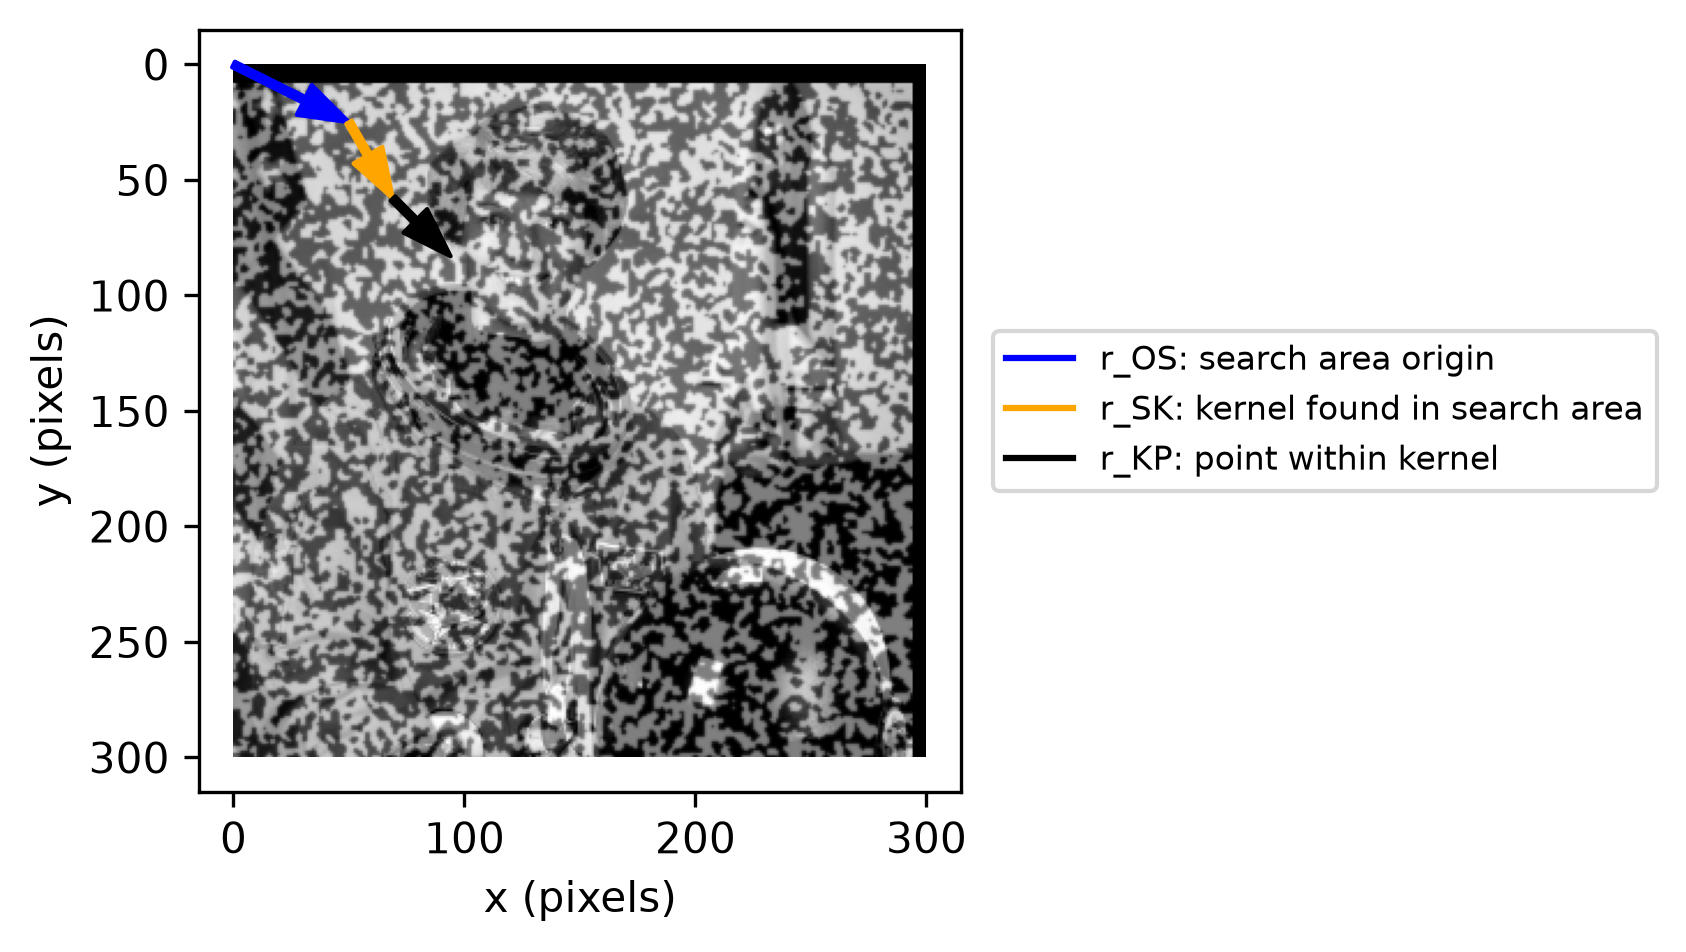
current_image — with the source image (blue box), search area (red box), and the kernel as found within it (green box) shown behind the arrows, each origin labeled: , , , and the found point .| vector, value | description |
|---|---|
| + | origin of the search area (blue arrow) |
| + | kernel located within the search area, from cross-correlation (red arrow) |
| = | point's fixed position within the kernel (green arrow) |
current position , matching found above (cyan arrow) |
NOTE: Cross-correlation may be conceptualized as the sliding dot product of pixel values from the kernel with pixel values from the search area. In this discussion we have described sliding the kernel across a stationary search area. The reverse, sliding the search area across a stationary kernel, is conceptually different but mathematically identical. Both approaches yield the same result: , which locates the kernel frame in the search area frame.
Next: Correlation Criteria defines the four
cross-correlation formulas and explains the Fourier-domain route locate
actually takes, and Correlation
Visualization visualizes each of them on
this same kernel and search area.
Correlation Criteria
Cross-correlation itself can be computed two ways: directly in the
spatial domain — literally sliding the kernel over the search area and
summing a per-position inner product, as shown below — or in the Fourier
domain via the fast Fourier transform (FFT), which is what locate
actually does (see Fourier Domain, below). Both compute
the same underlying quantity, but at very different cost: for the
sliding sum, evaluated at every candidate offset, against
for the FFT, with the number of pixels — a gap that widens sharply as
images grow beyond this page's small teaching examples.
Spatial Domain
Cross Correlation (CC) walks through the geometry of locating a point: the kernel/search-area vector chain, solved by finding where their cross-correlation is maximized. This page covers what "cross-correlation" actually means as a formula — several related criteria are used in the spatial domain, differing in how each responds to brightness and contrast differences between the kernel and a candidate window — a same-sized window of the search area at one particular offset — summed pixelwise over index :
-
Cross-Correlation (CC)
-
Normalized Cross-Correlation (NCC)
-
Zero-mean Cross-Correlation (ZCC)
where and likewise for .
-
Zero-mean Normalized Cross-Correlation (ZNCC)
where and .
Invariance and Robustness
Invariance describes whether or not a correlation is robust or insensitive to changes in brightness and/or contrast.
- For brightness, which is additive, subtracting each side's own mean cancels any constant added to that side, making "Zero-mean" approaches effective.
- For contrast, which is multiplicative, dividing by each side's own norm cancels any constant scaling of that side, making "Normalized" approaches effective.
Whether a criterion performs each of those two cancellations determines its invariance:
| Method | Invariant to brightness (additive) | Invariant to contrast (multiplicative) | Robustness |
|---|---|---|---|
| CC | ❌ No | ❌ No | Least robust — neither cancellation |
| NCC | ❌ No | ✅ Yes | Only robust to contrast changes |
| ZCC | ✅ Yes | ❌ No | Only robust to brightness changes |
| ZNCC | ✅ Yes | ✅ Yes | Most robust |
ZNCC combines ZCC's mean-subtraction (brightness invariance) with NCC's
norm-division (contrast invariance), which is why it's the standard choice
in most DIC implementations — including dictk.translation.locate's own
underlying skimage.registration.phase_cross_correlation call (see
Fourier Domain, below).
Neither cancellation helps against nonlinear or spatially-varying brightness/contrast (a shadow crossing part of the kernel, sensor saturation) — none of the four criteria above address that.
Brightness and Contrast Invariance in Practice
The table above is a formula-level guarantee, verified here on
astronaut0 — the
speckle-over-photograph image used from Multi-Point
Motion onward — rather than taken on faith.
Extract a kernel from astronaut0 unmodified, then compare it against a
search area from a translated and brightness-shifted copy of the same
image, using dictk.image.brightness
with a small enough factor that no pixel clips at 255 (clipping is a
genuine loss of information no correlation criterion can see past, and
would contaminate this test):
from dictk.image import read, translate, brightness, PixelCoordinate, subimage
from dictk.correlation import cc, ncc, zcc, zncc

astronaut0 = read(path="astronaut0.png")
p0 = PixelCoordinate(x=100, y=100)
kernel_margin, search_margin = 25, 50
kernel = subimage(image=astronaut0, origin=PixelCoordinate(x=p0.x - kernel_margin, y=p0.y - kernel_margin), width=2 * kernel_margin, height=2 * kernel_margin)

dx, dy = -6, 8
current_baseline = translate(arr=astronaut0, dx=dx, dy=dy)
current_bright = brightness(arr=current_baseline, factor=1.01)  # +1.275 per pixel, no clipping here

search_origin = PixelCoordinate(x=p0.x - search_margin, y=p0.y - search_margin)
baseline_search = subimage(image=current_baseline, origin=search_origin, width=2 * search_margin, height=2 * search_margin)
bright_search = subimage(image=current_bright, origin=search_origin, width=2 * search_margin, height=2 * search_margin)

for name, fn in [("CC", cc), ("NCC", ncc), ("ZCC", zcc), ("ZNCC", zncc)]:
    baseline_peak = fn(kernel=kernel, search=baseline_search).max()
    bright_peak = fn(kernel=kernel, search=bright_search).max()
    pct_change = (bright_peak - baseline_peak) / abs(baseline_peak) * 100
    print(f"{name}: peak value change under brightness shift = {pct_change:+.4f}%")
CC: peak value change under brightness shift = +0.6431%
NCC: peak value change under brightness shift = -0.0007%
ZCC: peak value change under brightness shift = +0.0000%
ZNCC: peak value change under brightness shift = +0.0000%
ZCC and ZNCC come back at exactly +0.0000% — bit-for-bit unchanged, as
the formula guarantees for any brightness shift small enough to avoid
clipping. CC and NCC both drift, confirming they are not brightness
invariant — even though, on astronaut0's strong, distinctive texture,
that drift isn't large enough to move where the peak lands, only its
value. That value-only distinction still matters in practice: it's what
makes CC's raw magnitude unsafe to compare across different points or
lighting conditions in a Multi-Point Motion
grid, even on images where its peak still happens to land in the right
place for any one point in isolation.
A parallel contrast test — dictk.image.contrast
instead of brightness, same astronaut0 kernel/search pair — shows the
other pairing:
CC: peak value change under contrast shift = +0.2194%
NCC: peak value change under contrast shift = -0.0052%
ZCC: peak value change under contrast shift = +1.8999%
ZNCC: peak value change under contrast shift = -0.0021%
NCC drifts about 40x less than CC does (-0.0052% vs +0.2194%), and ZNCC
about 900x less than ZCC does (-0.0021% vs +1.8999%). Not perfectly
bit-exact like the brightness case, because contrast scales around the
image's own mean rather than performing a pure multiplicative gain,
which mixes in a small secondary additive term — but the qualitative
result matches the table: contrast invariance belongs to NCC and ZNCC, not
CC or ZCC.
See Pan B, Xie H, Wang Z. "Equivalence of digital image correlation criteria for pattern matching." Applied Optics 2010;49(28):5501-9. [download]
dictk.correlation implements all four as
standalone functions (cc, ncc, zcc, zncc), each returning the full
correlation surface rather than just its peak — see Correlation
Visualization for what those surfaces
look like on the kernel and search area established in Cross Correlation
(CC).
Next: Correlation Visualization
visualizes these four correlation criteria in detail; the Fourier Domain
section below explains the route locate itself actually takes.
Fourier Domain
Correlation Visualization computes CC
directly in the spatial domain: a literal sliding sum, one value per
candidate offset. The
convolution theorem gives an equivalent route: multiplying the two
images' Fourier transforms (one of them conjugated) and inverse-transforming
the product yields that same correlation, all at once, for every offset —
without ever explicitly sliding a window. This is exactly what
dictk.translation.locate does
internally, via
skimage.registration.phase_cross_correlation.
The appeal isn't a different answer — it's speed: a fast Fourier transform
(FFT) costs per image, against the sliding sum's
per candidate offset — decisive once images grow beyond this page's small
teaching example.
reference_image, p0, current_image, kernel, and search are the
same as in Correlation Visualization:
from dictk.image import read, translate, PixelCoordinate, subimage

reference_image = read(path="checkerboard0.png")
p0 = PixelCoordinate(x=100, y=75)
current_image = translate(arr=reference_image, dx=-6, dy=8)

kernel_margin = 25
kernel = subimage(
    image=reference_image,
    origin=PixelCoordinate(x=p0.x - kernel_margin, y=p0.y - kernel_margin),
    width=2 * kernel_margin,
    height=2 * kernel_margin,
)

search_margin = 50
search_center = p0
search = subimage(
    image=current_image,
    origin=PixelCoordinate(
        x=search_center.x - search_margin, y=search_center.y - search_margin
    ),
    width=2 * search_margin,
    height=2 * search_margin,
)
locate pads kernel to search's own shape before comparing them,
though not quite with the padding used here — see the note below:
import numpy as np

pad_height = search.shape[0] - kernel.shape[0]
pad_width = search.shape[1] - kernel.shape[1]
kernel_padded = np.pad(kernel.astype(np.float64), ((0, pad_height), (0, pad_width)))

image_product = np.fft.fft2(search.astype(np.float64)) * np.fft.fft2(kernel_padded).conj()
fft_surface = np.fft.ifft2(image_product).real

dy, dx = np.unravel_index(np.argmax(fft_surface), fft_surface.shape)
print(f"FFT-domain peak offset (dx, dy) = ({dx}, {dy})")
FFT-domain peak offset (dx, dy) = (19, 33)
That peak, , matches exactly —
the same offset Correlation Visualization's
cc() surface and locate itself both find. That agreement is about the
peak's location only. fft_surface here and locate's own computation
differ in three ways, none of which change where the peak lands here,
on this page's small, comfortably-within-bounds displacement:
- Shape.
fft_surfaceis the circular correlation over the full padded extent (search's own shape,100x100).cc()returns valid positions only (a smaller51x51array, no wraparound). The two arrays don't share a shape, sonp.allclosebetween them wouldn't be meaningful. - Normalization.
fft_surfaceis a raw, unnormalized cross-power spectrum.locateinstead passesnormalization="phase"tophase_cross_correlation, dividing that spectrum by its own magnitude at every frequency before inverting it (see the extensive comment inlocate's source for why). - Padding anchor.
kernel_paddedabove keepskernel's content anchored at the padded array's top-left corner (np.pad's own default), matchingcc()'s corner-offset convention above.locatecenters it instead — a reason worth knowing once you've worked withlocatea bit more: see Recoverable Displacement Range.
Correlation Visualization
This page visualizes each of the four spatial-domain correlation criteria
from Correlation Criteria — CC, NCC, ZCC, and
ZNCC — one at a time, in a four-panel composite reproducing a reference
composite-figure layout used in prior DIC tooling, via
dictk.plot.spatial_correlation_quadrant_plot:
the search area with the found kernel marked (Fixed Image), the kernel
itself zero-padded to the search area's shape (Moving Image), the full
correlation surface, and a zoomed Solution Vicinity around its peak —
closer to how a single registration result is typically inspected in
practice than a side-by-side comparison of criteria.
reference_image, p0, current_image, kernel_margin, search_margin,
kernel, and search are the same as in Cross Correlation
(CC):
from dictk.image import read, translate, PixelCoordinate, subimage

reference_image = read(path="checkerboard0.png")
p0 = PixelCoordinate(x=100, y=75)
current_image = translate(arr=reference_image, dx=-6, dy=8)

kernel_margin = 25
kernel = subimage(
    image=reference_image,
    origin=PixelCoordinate(x=p0.x - kernel_margin, y=p0.y - kernel_margin),
    width=2 * kernel_margin,
    height=2 * kernel_margin,
)

search_margin = 50
search_center = p0
search = subimage(
    image=current_image,
    origin=PixelCoordinate(
        x=search_center.x - search_margin, y=search_center.y - search_margin
    ),
    width=2 * search_margin,
    height=2 * search_margin,
)
The Fixed Image panel below plots the search area in its own pixel frame
, with a yellow dashed box marking where the kernel was found
and red/green dashed guide lines through that box's origin — the same
quantity Cross Correlation
(CC) solves for by hand. The Correlation
Surface panel plots that same quantity as candidate offset and marks the peak with a red circle of radius
vicinity_margin (4 pixels by default) — exactly the region the Solution
Vicinity panel zooms into, so the same circle reappears there too, now
clipped by that panel's own edges.
Cross-Correlation (CC)
from dictk.correlation import cc
from dictk.plot import spatial_correlation_quadrant_plot

spatial_correlation_quadrant_plot(
    kernel=kernel,
    search=search,
    correlation_surface=cc(kernel=kernel, search=search),
    title="Cross-Correlation (CC)",
    path="correlation_visualization_cc.png",
)
Saved: correlation_visualization_cc.png
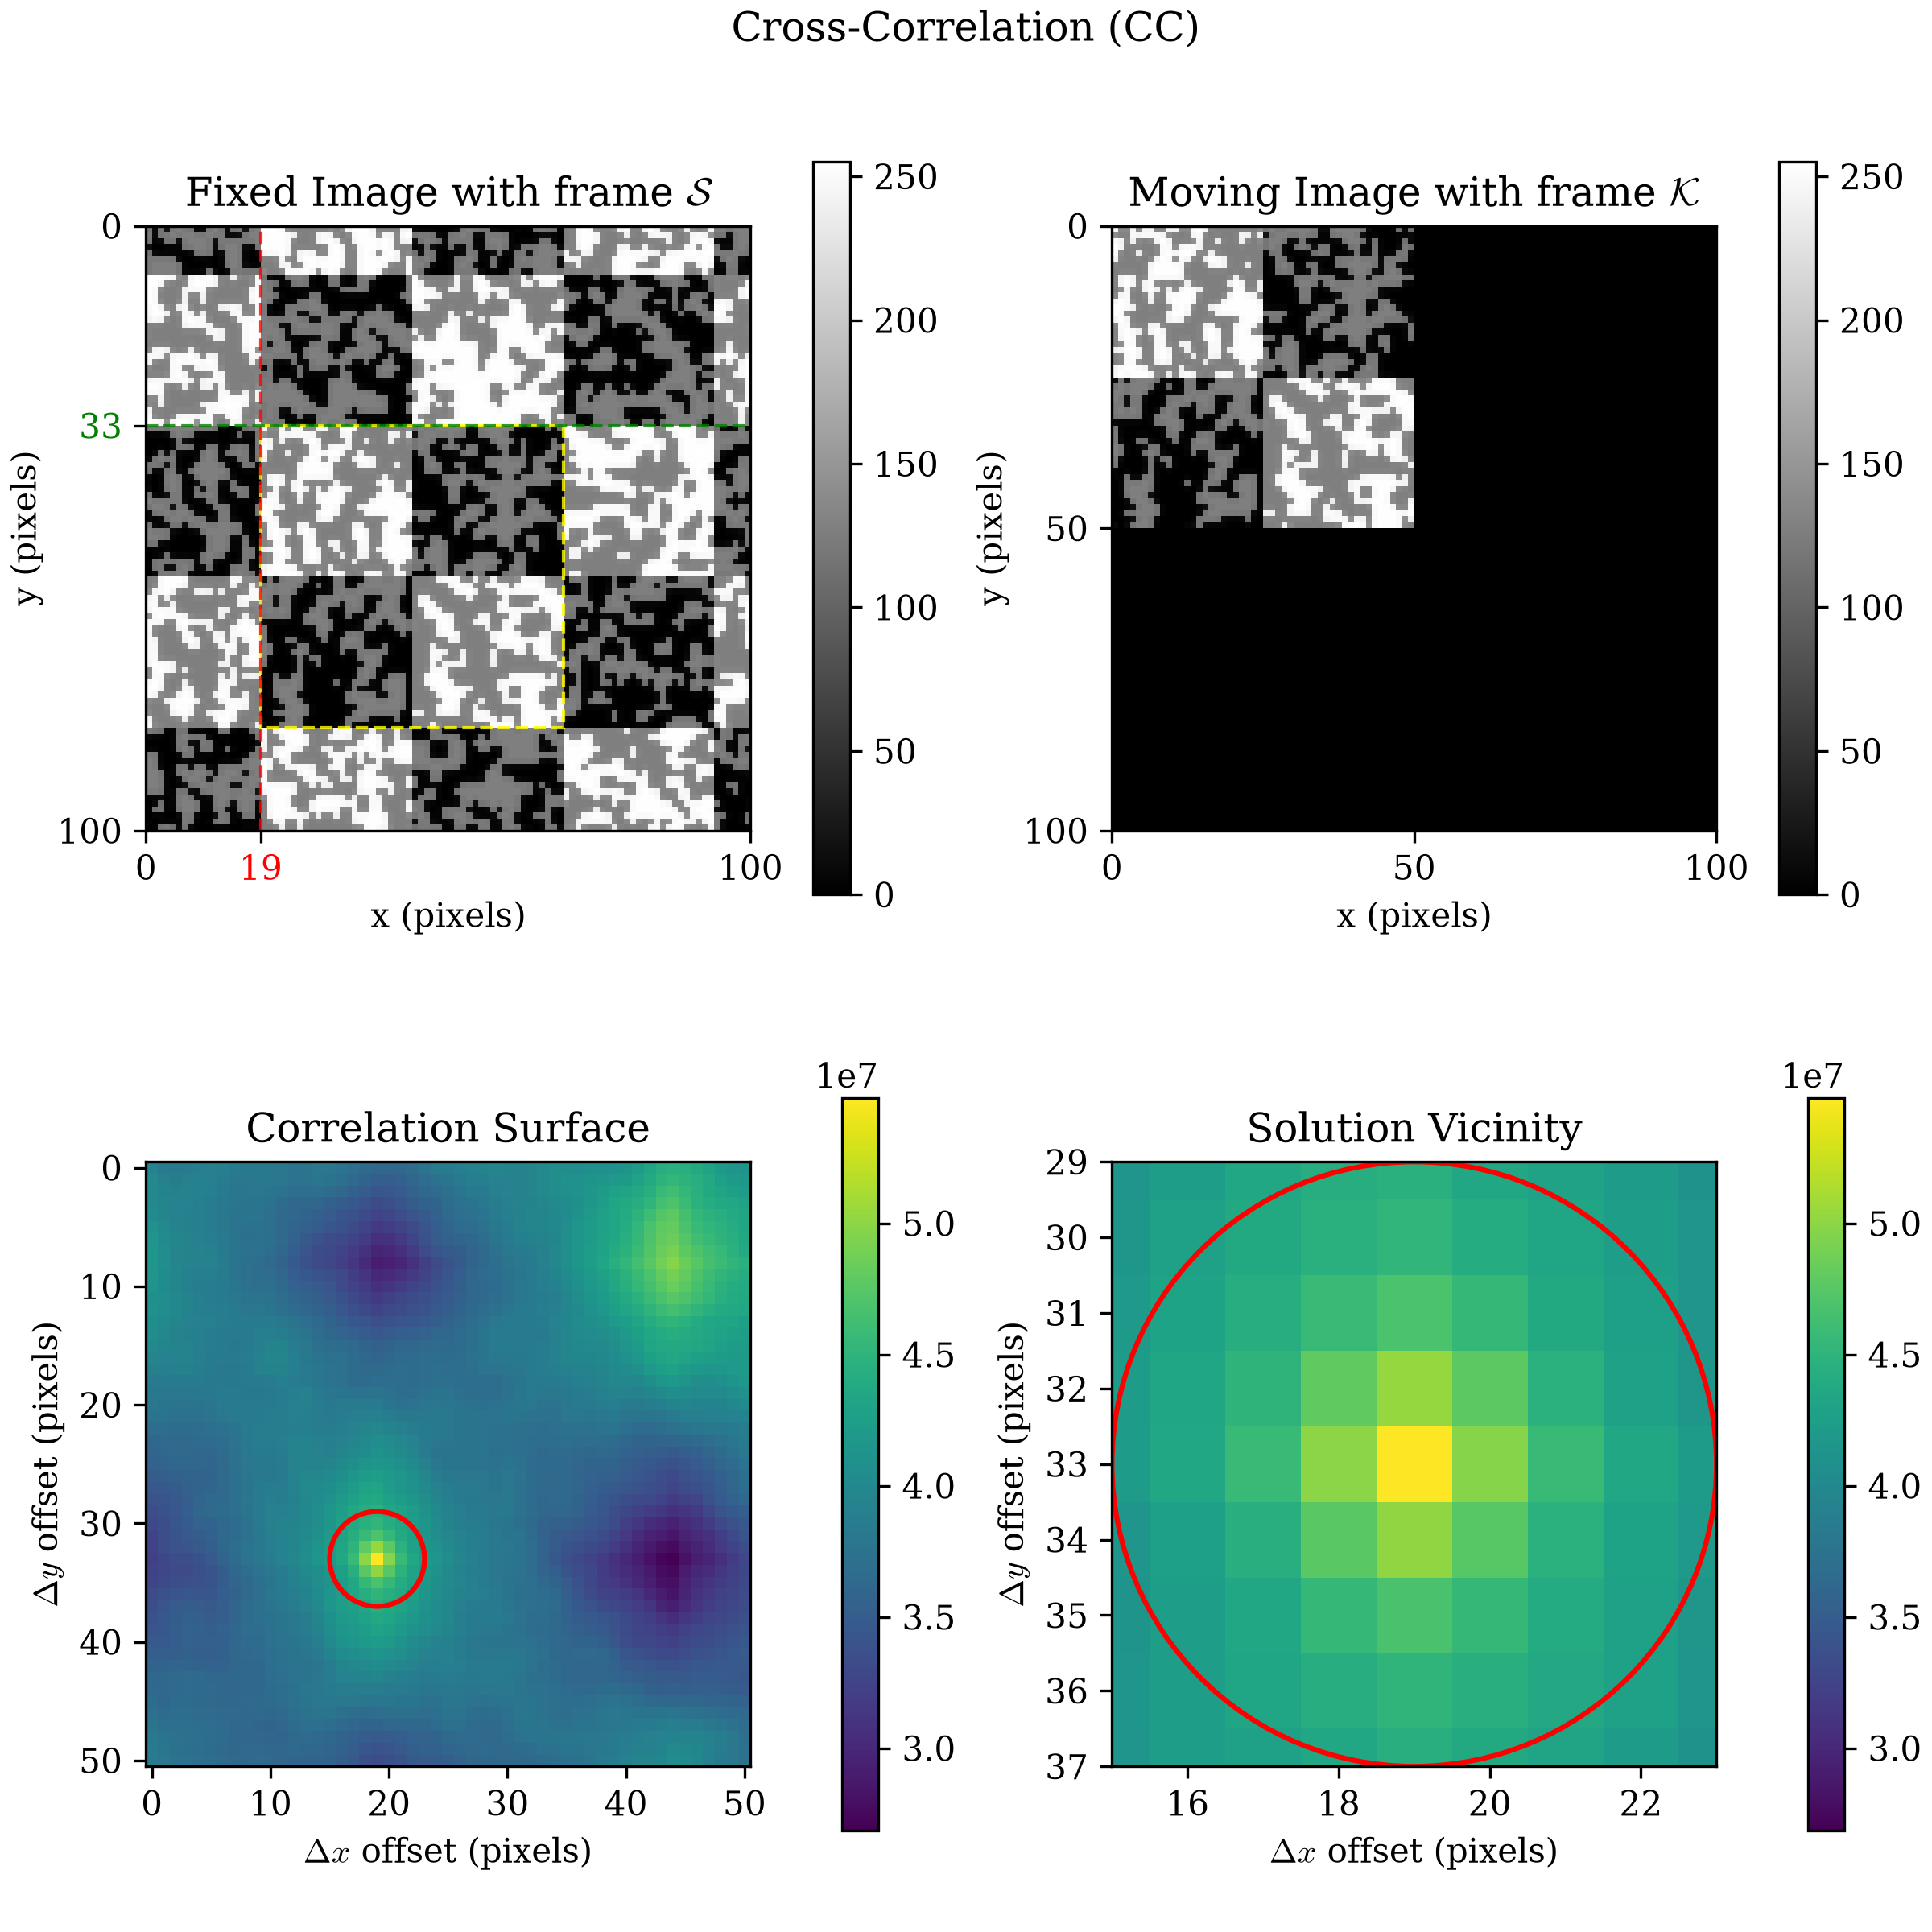
locate in Cross Correlation (CC).Normalized Cross-Correlation (NCC)
from dictk.correlation import ncc

spatial_correlation_quadrant_plot(
    kernel=kernel,
    search=search,
    correlation_surface=ncc(kernel=kernel, search=search),
    title="Normalized Cross-Correlation (NCC)",
    path="correlation_visualization_ncc.png",
)
Saved: correlation_visualization_ncc.png
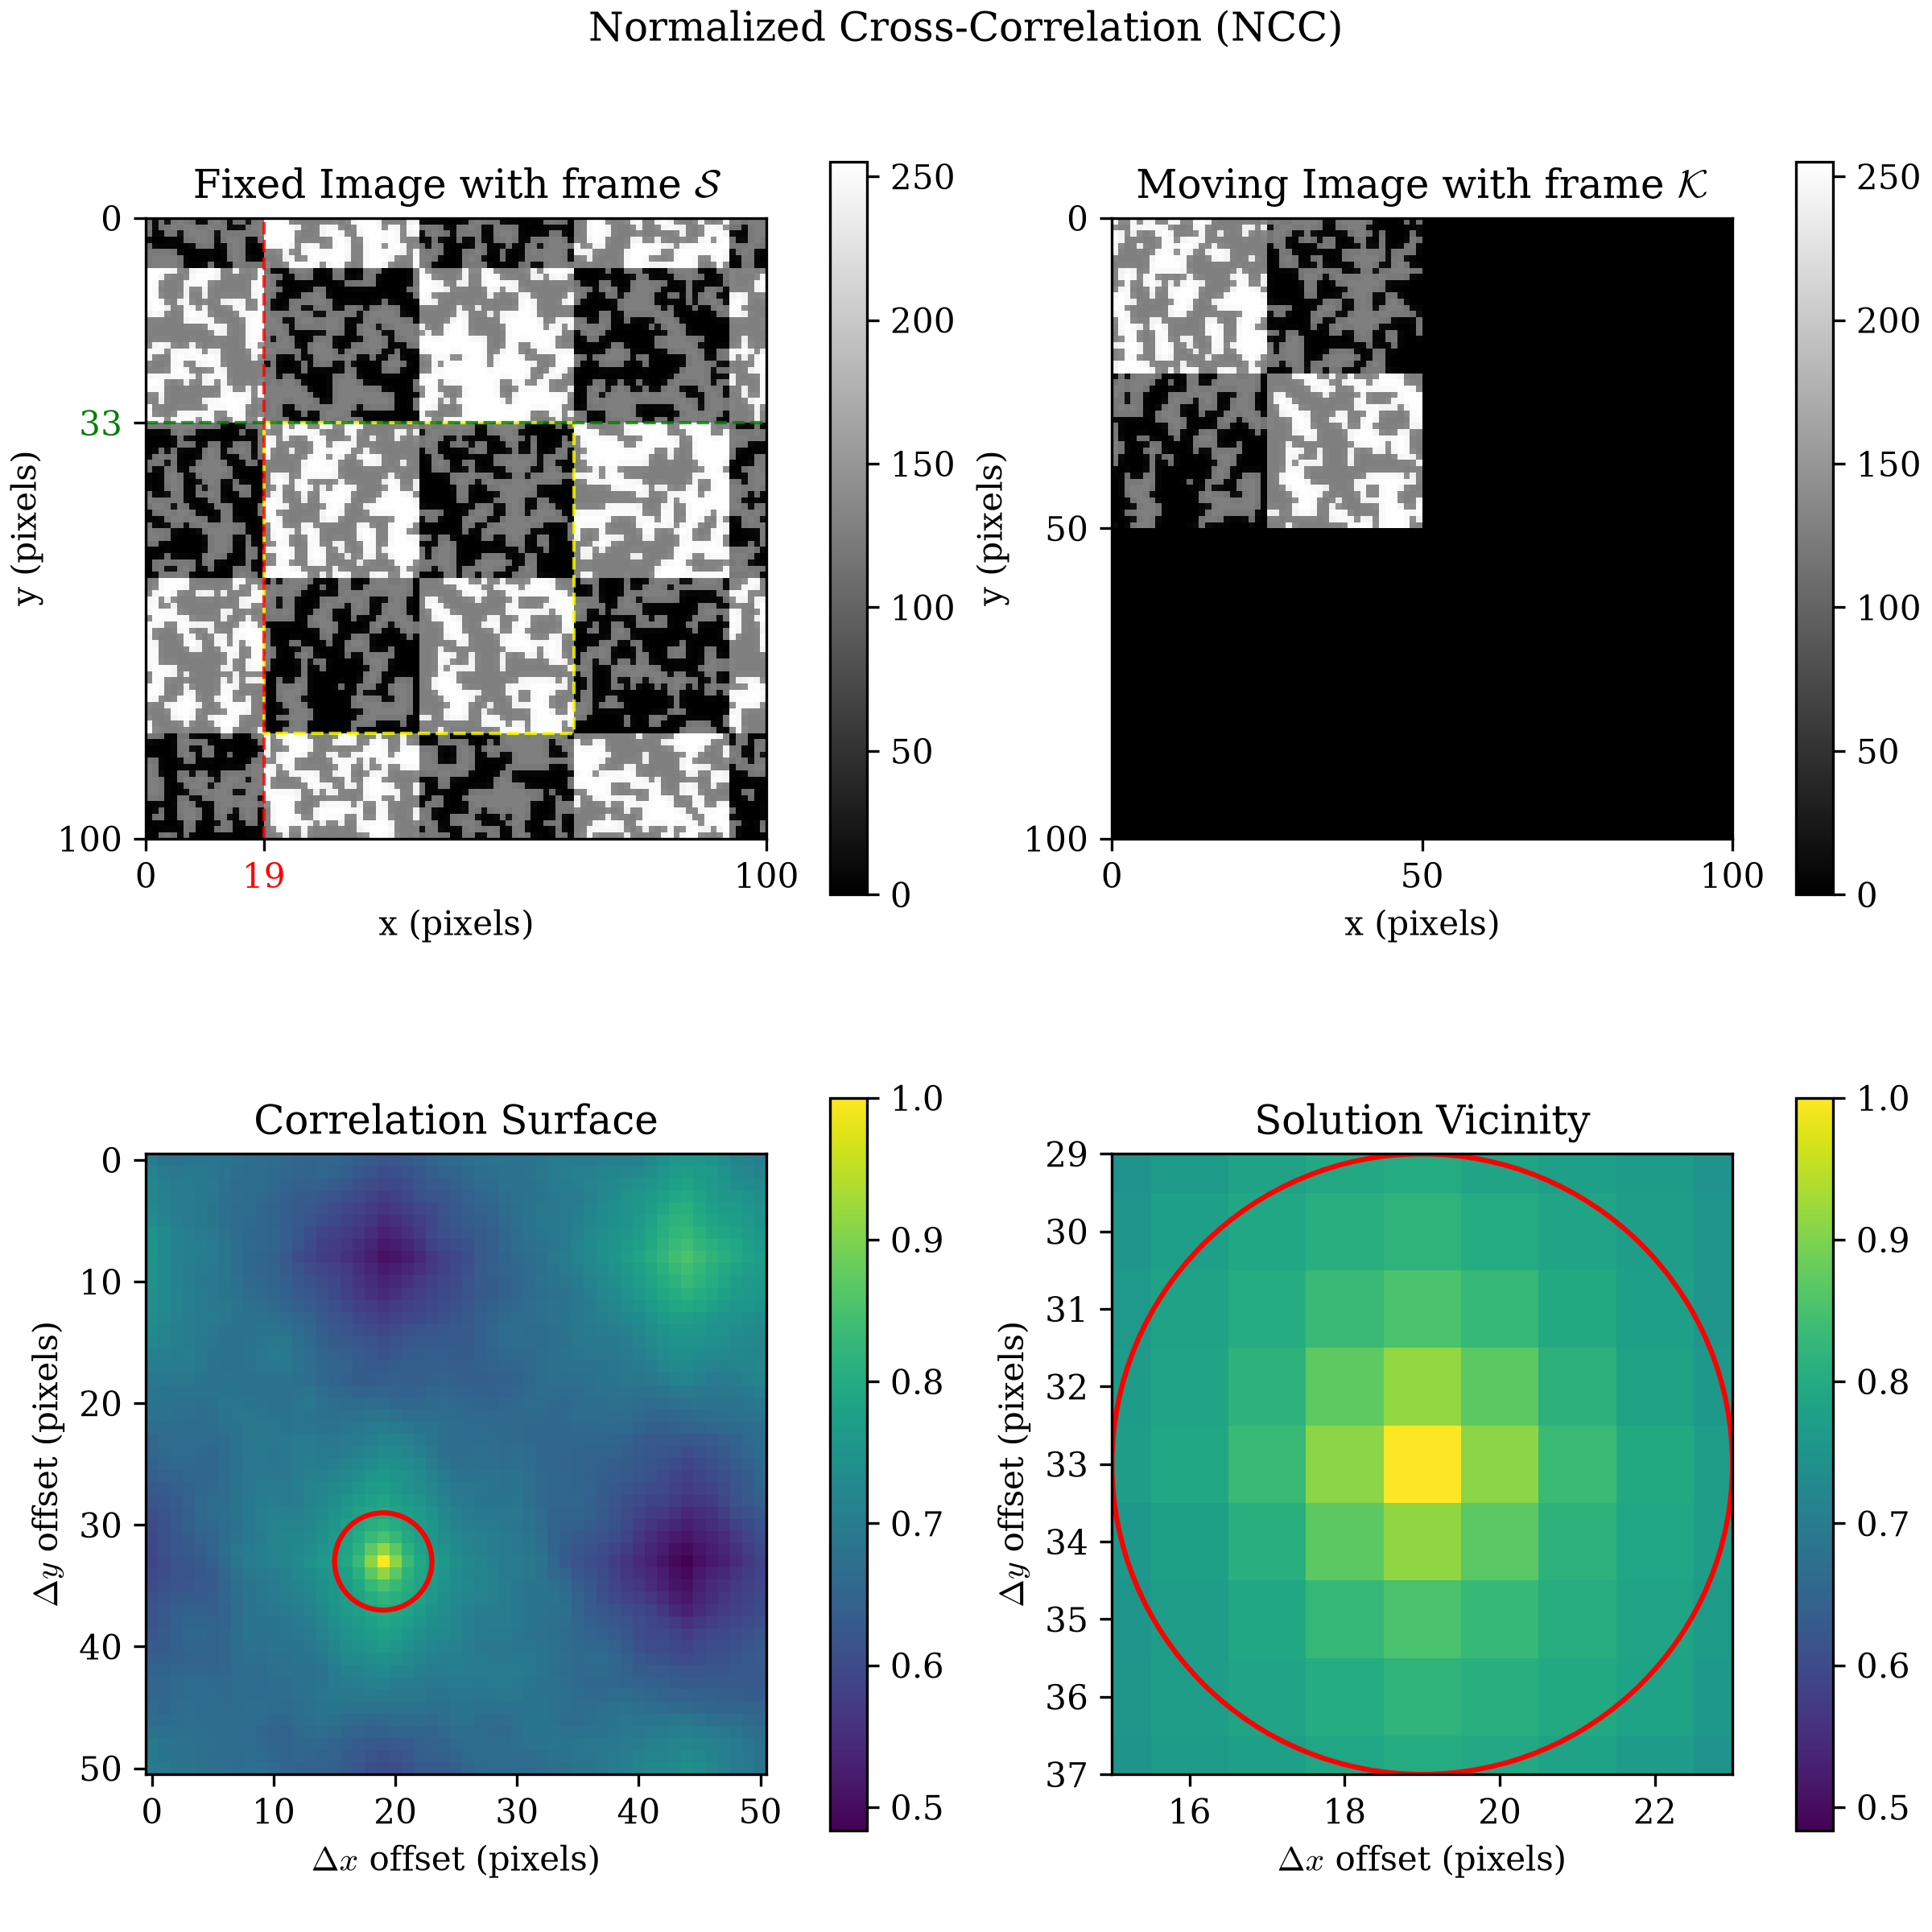
locate in Cross Correlation (CC).Zero-mean Cross-Correlation (ZCC)
from dictk.correlation import zcc

spatial_correlation_quadrant_plot(
    kernel=kernel,
    search=search,
    correlation_surface=zcc(kernel=kernel, search=search),
    title="Zero-mean Cross-Correlation (ZCC)",
    path="correlation_visualization_zcc.png",
)
Saved: correlation_visualization_zcc.png
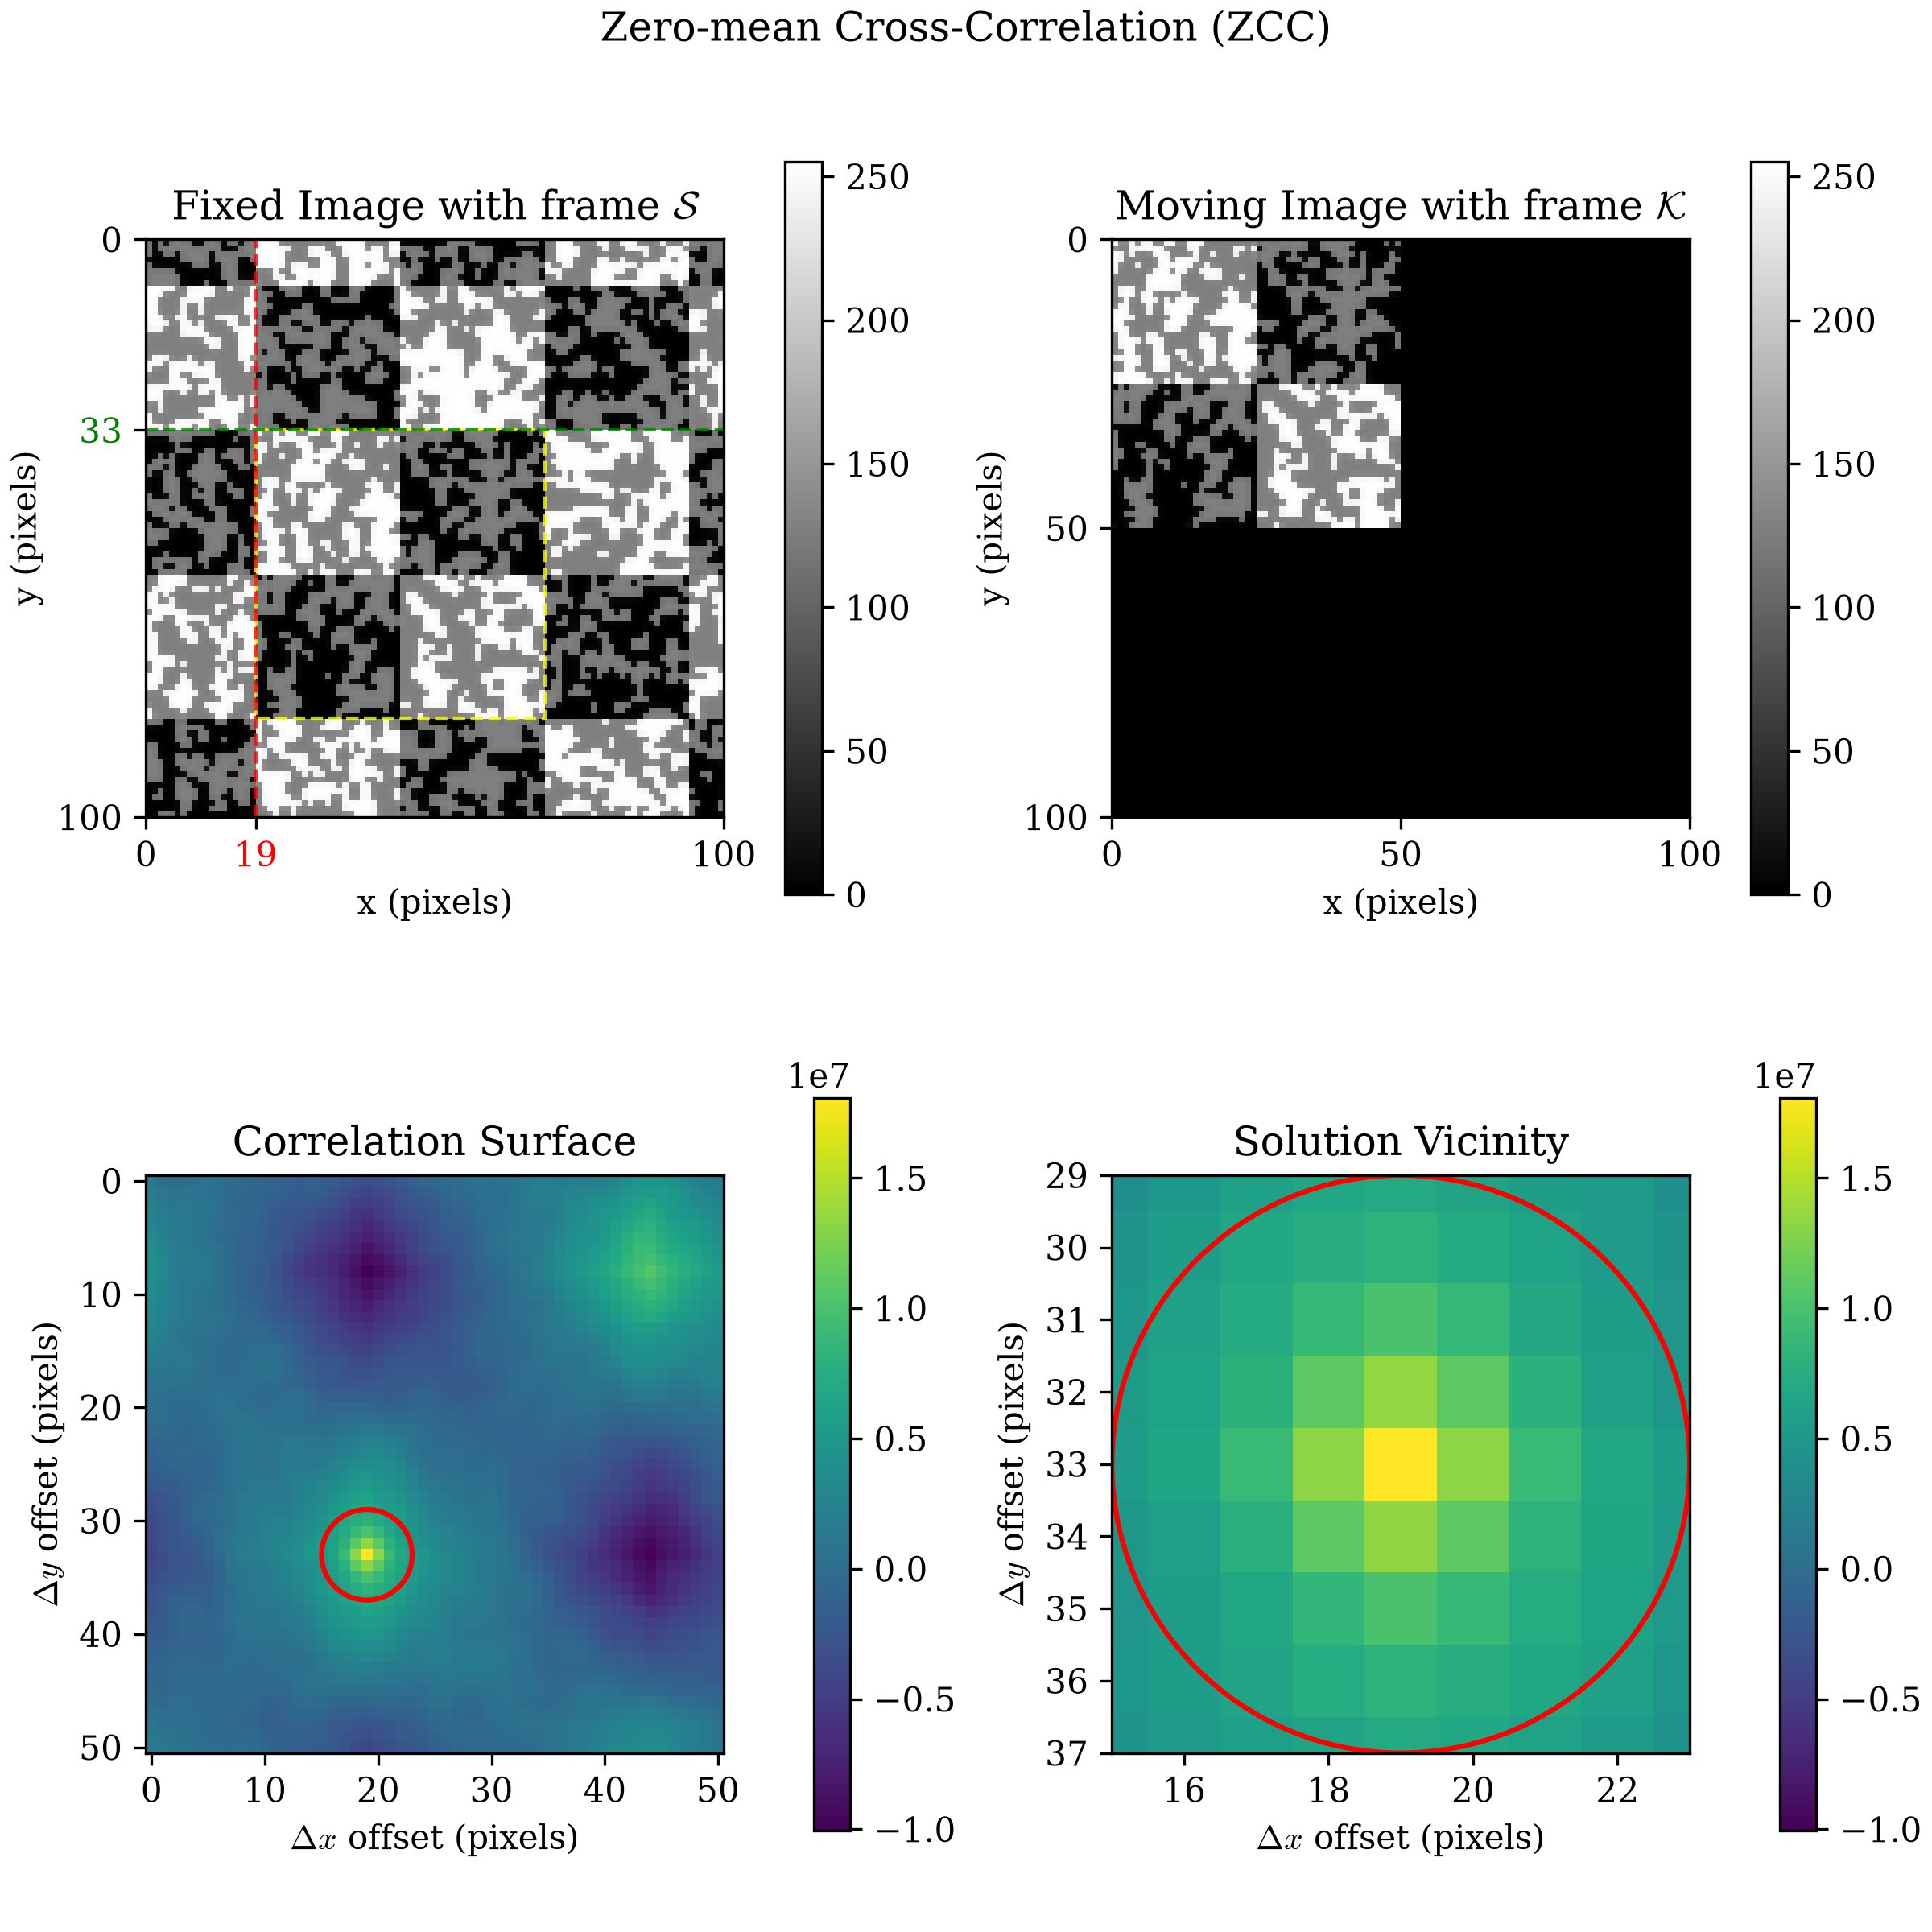
locate already found in Cross Correlation (CC).Zero-mean Normalized Cross-Correlation (ZNCC)
from dictk.correlation import zncc

spatial_correlation_quadrant_plot(
    kernel=kernel,
    search=search,
    correlation_surface=zncc(kernel=kernel, search=search),
    title="Zero-mean Normalized Cross-Correlation (ZNCC)",
    path="correlation_visualization_zncc.png",
)
Saved: correlation_visualization_zncc.png
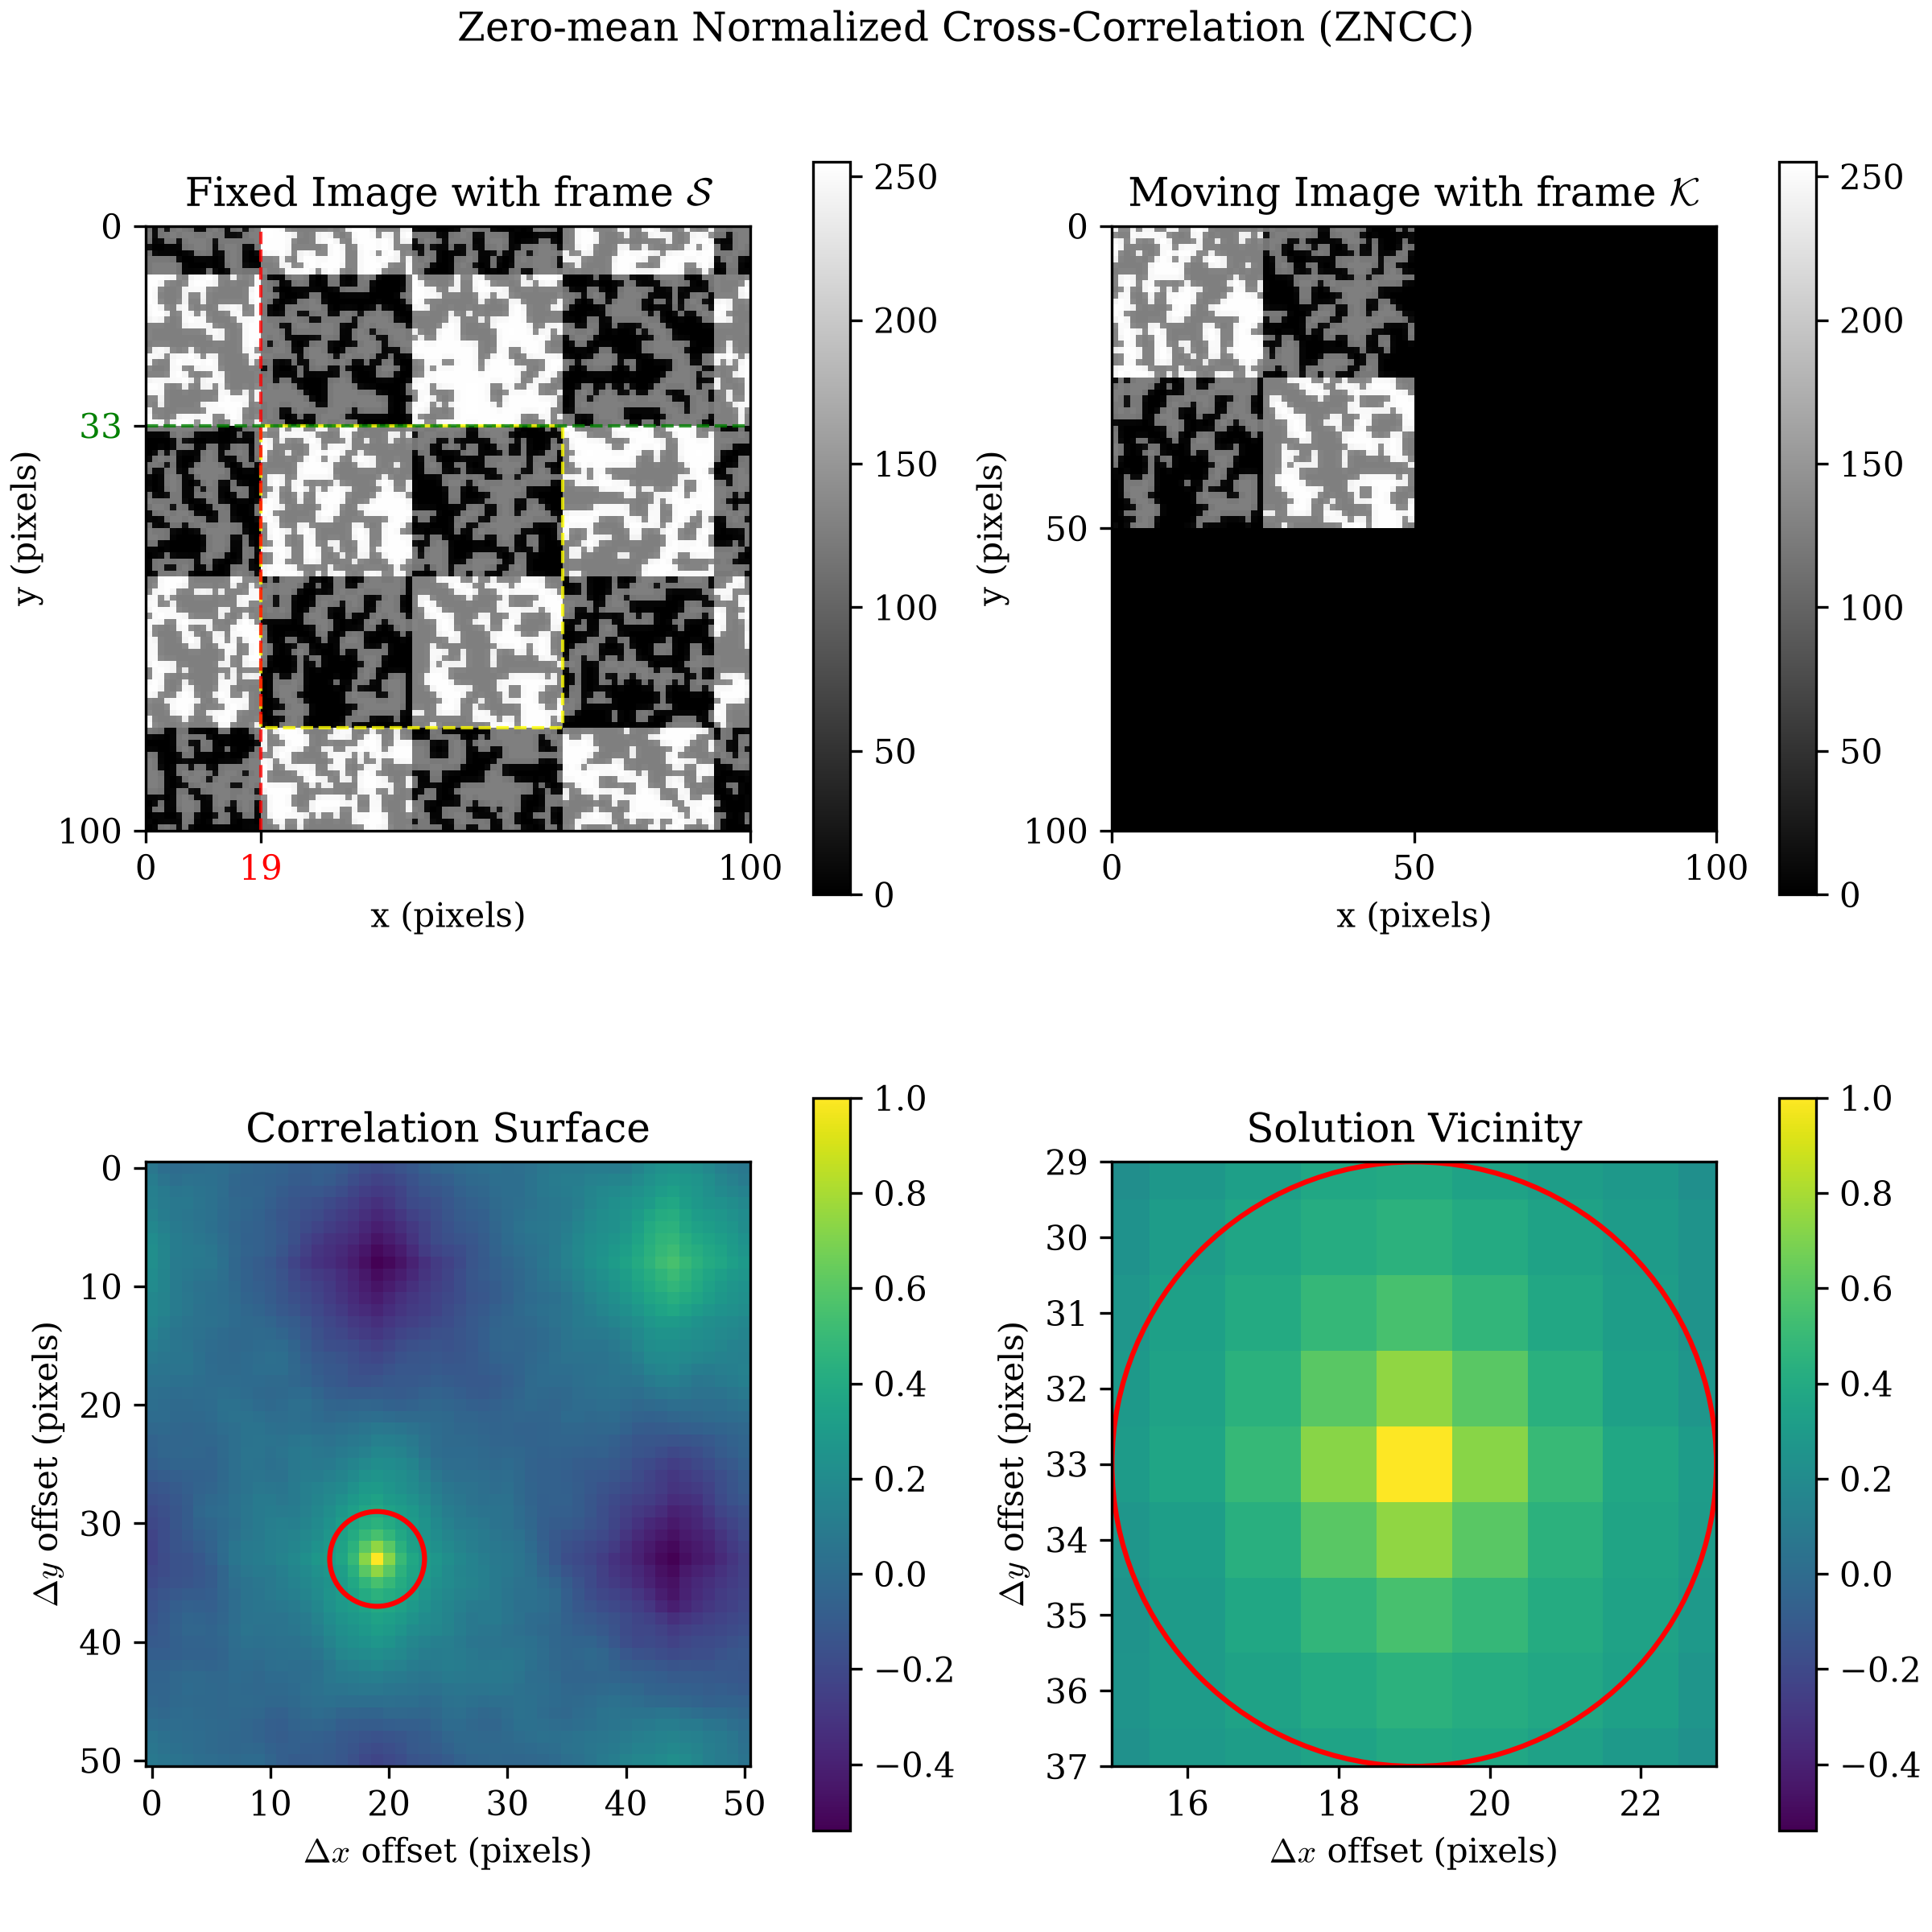
dictk.translation.locate's own underlying skimage.registration.phase_cross_correlation call is built on the same combination (see Correlation Criteria). Its Correlation Surface panel is likewise 51×51, "valid" positions only. Peak still at pixels, matching locate's own result in Cross Correlation (CC).All four land on the same peak, pixels, since kernel and search here share identical brightness
and contrast (both come from checkerboard0.png, only translated). What
differs between the four is what each panel's colorbar reveals about how
safely that peak can be trusted once brightness or contrast do differ, as
Correlation Criteria
covers in detail.
Phase Correlation
Every panel above comes from a spatial-domain criterion —
dictk.correlation's cc/ncc/zcc/
zncc, sliding kernel over search one window at a time. There's a
second way to get an equivalent answer: all at once, in the Fourier
domain, via
dictk.correlation.phase_correlation
— the same computation
dictk.translation.locate already
runs internally via skimage.registration.phase_cross_correlation. Unlike
its spatial-domain siblings, there's only one Fourier-domain flavor here,
so phase_correlation_quadrant_plot
takes kernel/search directly rather than a pre-computed surface — no
method to choose, nothing to compute beforehand. It does, however, take
an optional windowing parameter (see Windowing): the
three subsections below run this same kernel/search pair through no
windowing, Hann windowing, and Hamming windowing in turn, so the effect
is directly comparable rather than just described.
No Windowing (default)
windowing defaults to None, applying no tapering — this reproduces
exactly what every earlier page in this book that calls
phase_correlation/locate already does.
from dictk.plot import phase_correlation_quadrant_plot

phase_correlation_quadrant_plot(
    kernel=kernel,
    search=search,
    title="Phase Correlation (No Windowing)",
    path="correlation_visualization_phase_none.png",
)
Saved: correlation_visualization_phase_none.png
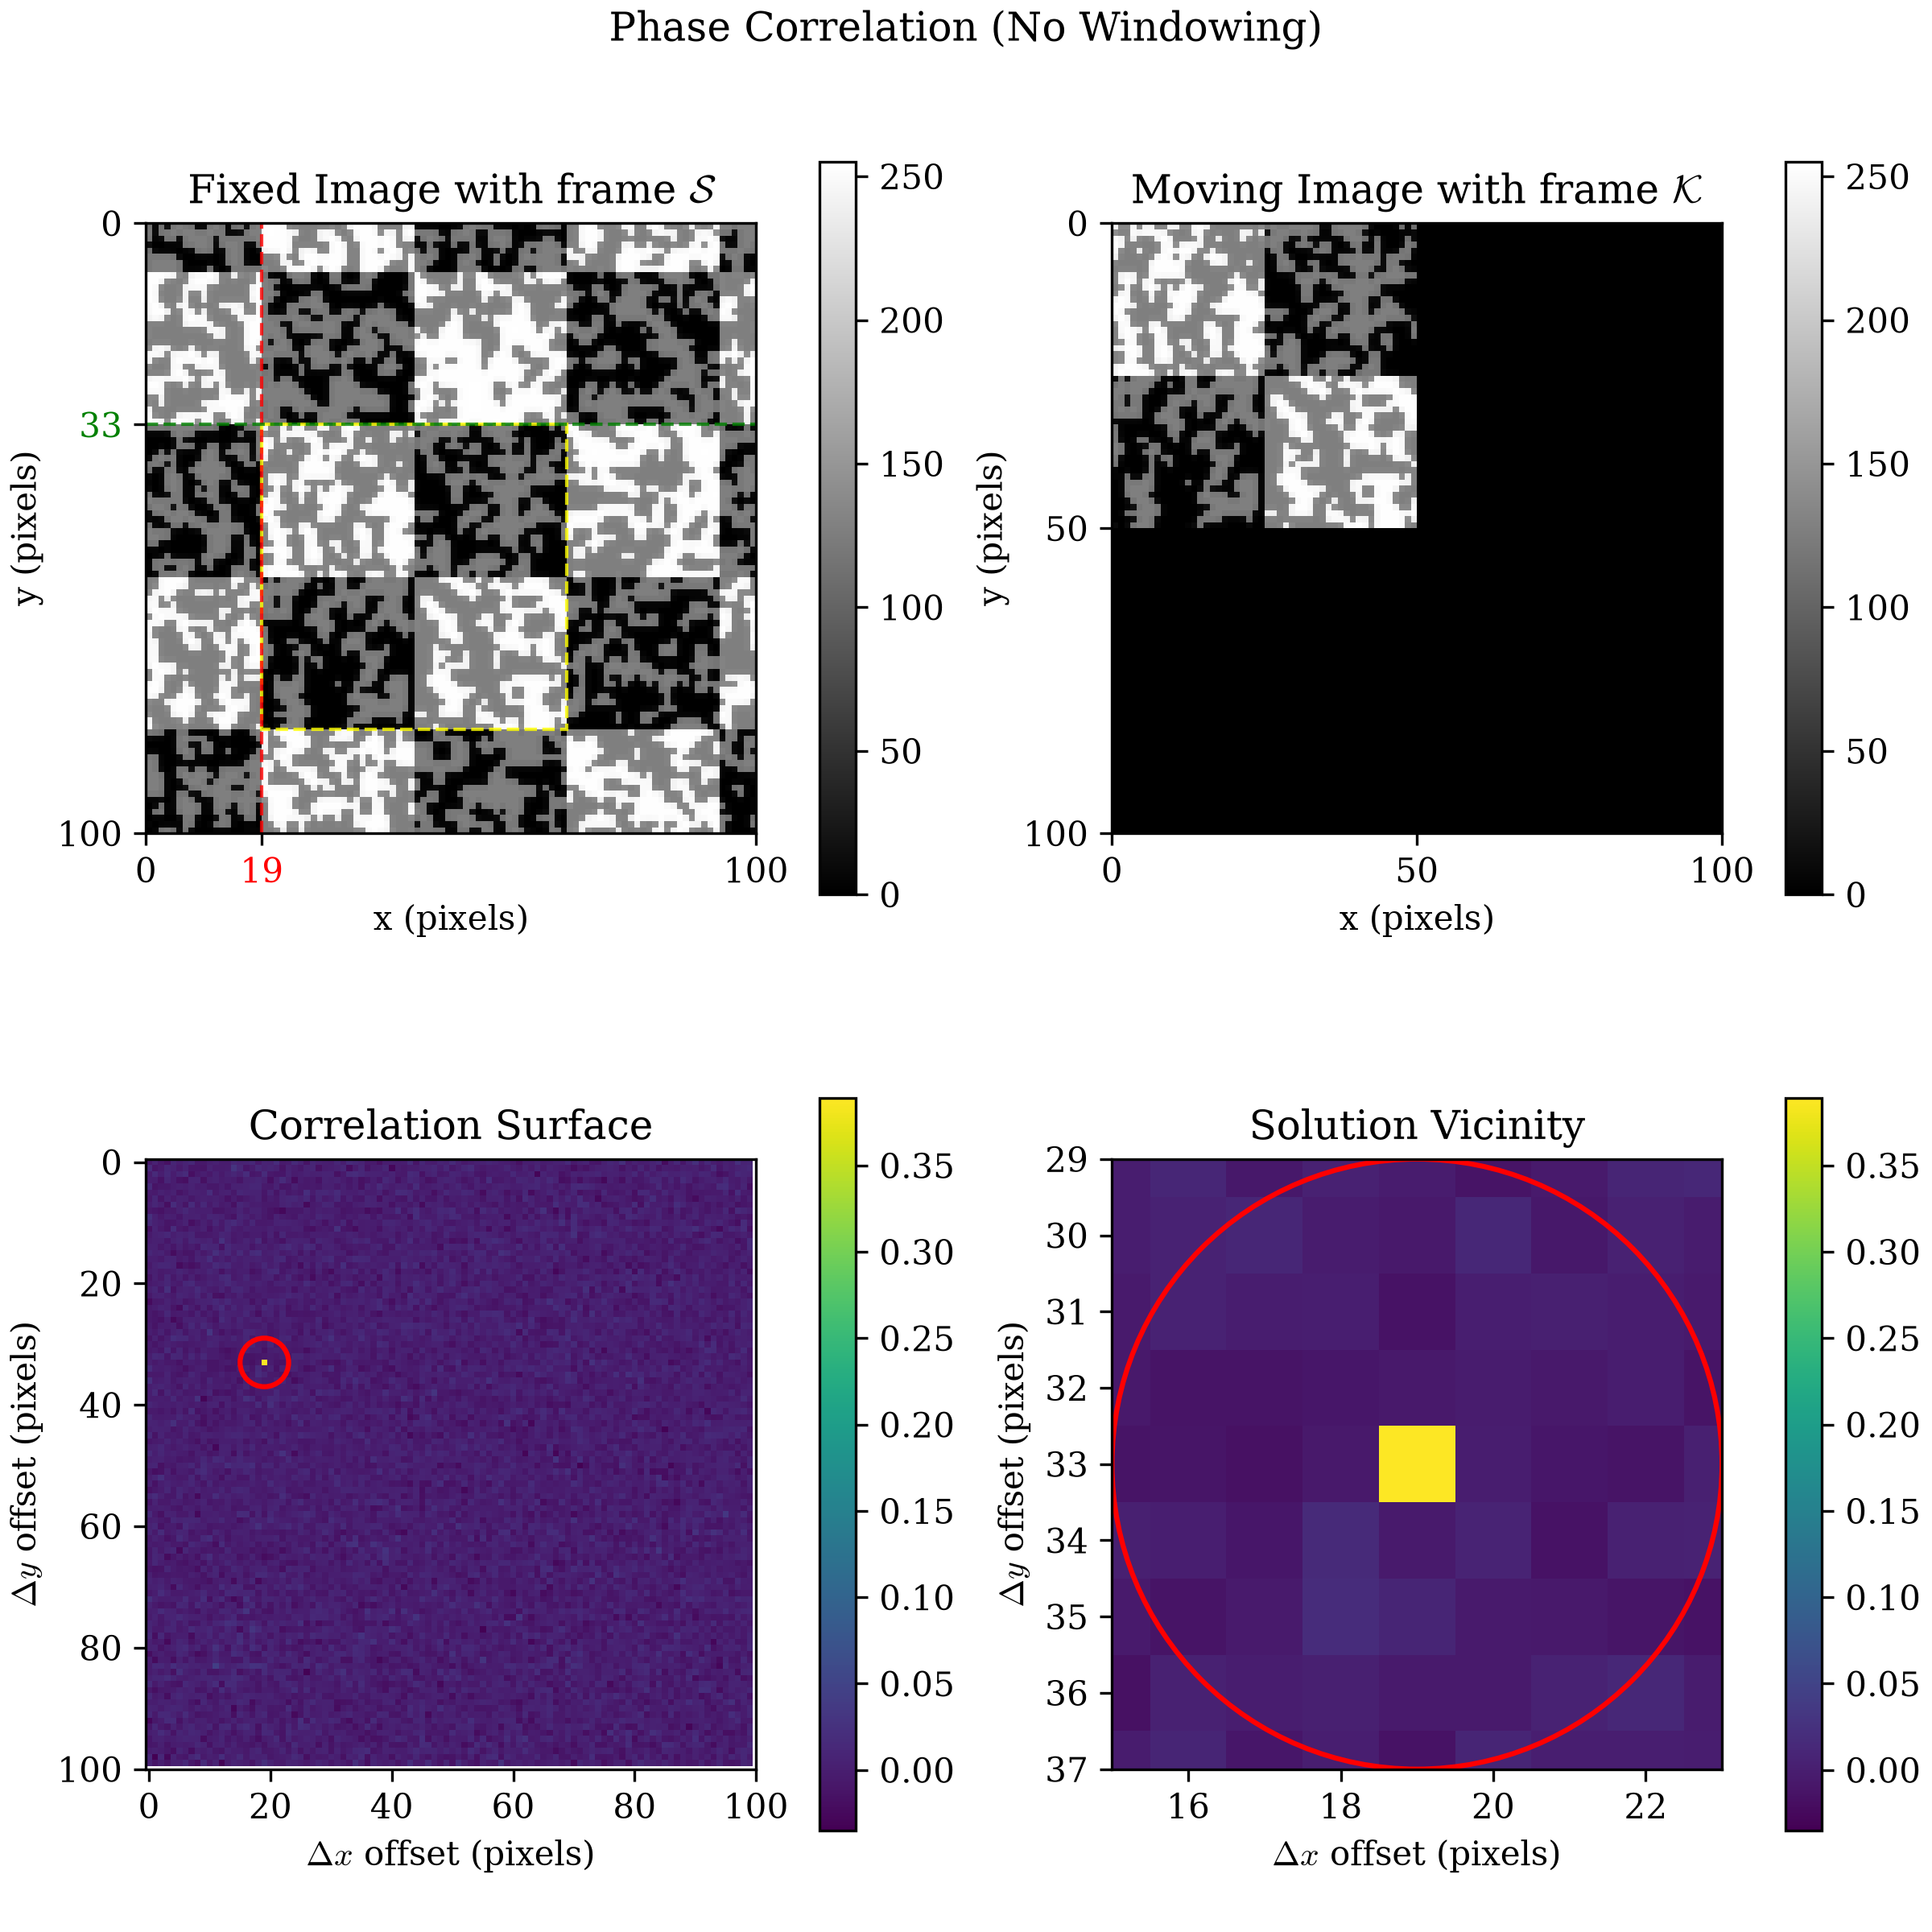
search itself, since kernel is zero-padded up to search's shape before the FFT rather than restricted to "valid" positions — every candidate offset, including circular wraparound ones, gets a value. Same peak, pixels — matching the value already found by locate in Cross Correlation (CC) — as every criterion above, but the correlation-surface panel looks nothing like them: essentially flat/uniform everywhere except one crisp, isolated cell, rather than the broader, multi-peaked terrain CC/NCC/ZCC/ZNCC show on this same tiled checkerboard0.png.Hann Windowing
from dictk.correlation import WindowingMethod

phase_correlation_quadrant_plot(
    kernel=kernel,
    search=search,
    windowing=WindowingMethod.HANN,
    title="Phase Correlation (Hann Windowing)",
    path="correlation_visualization_phase_hann.png",
)
Saved: correlation_visualization_phase_hann.png
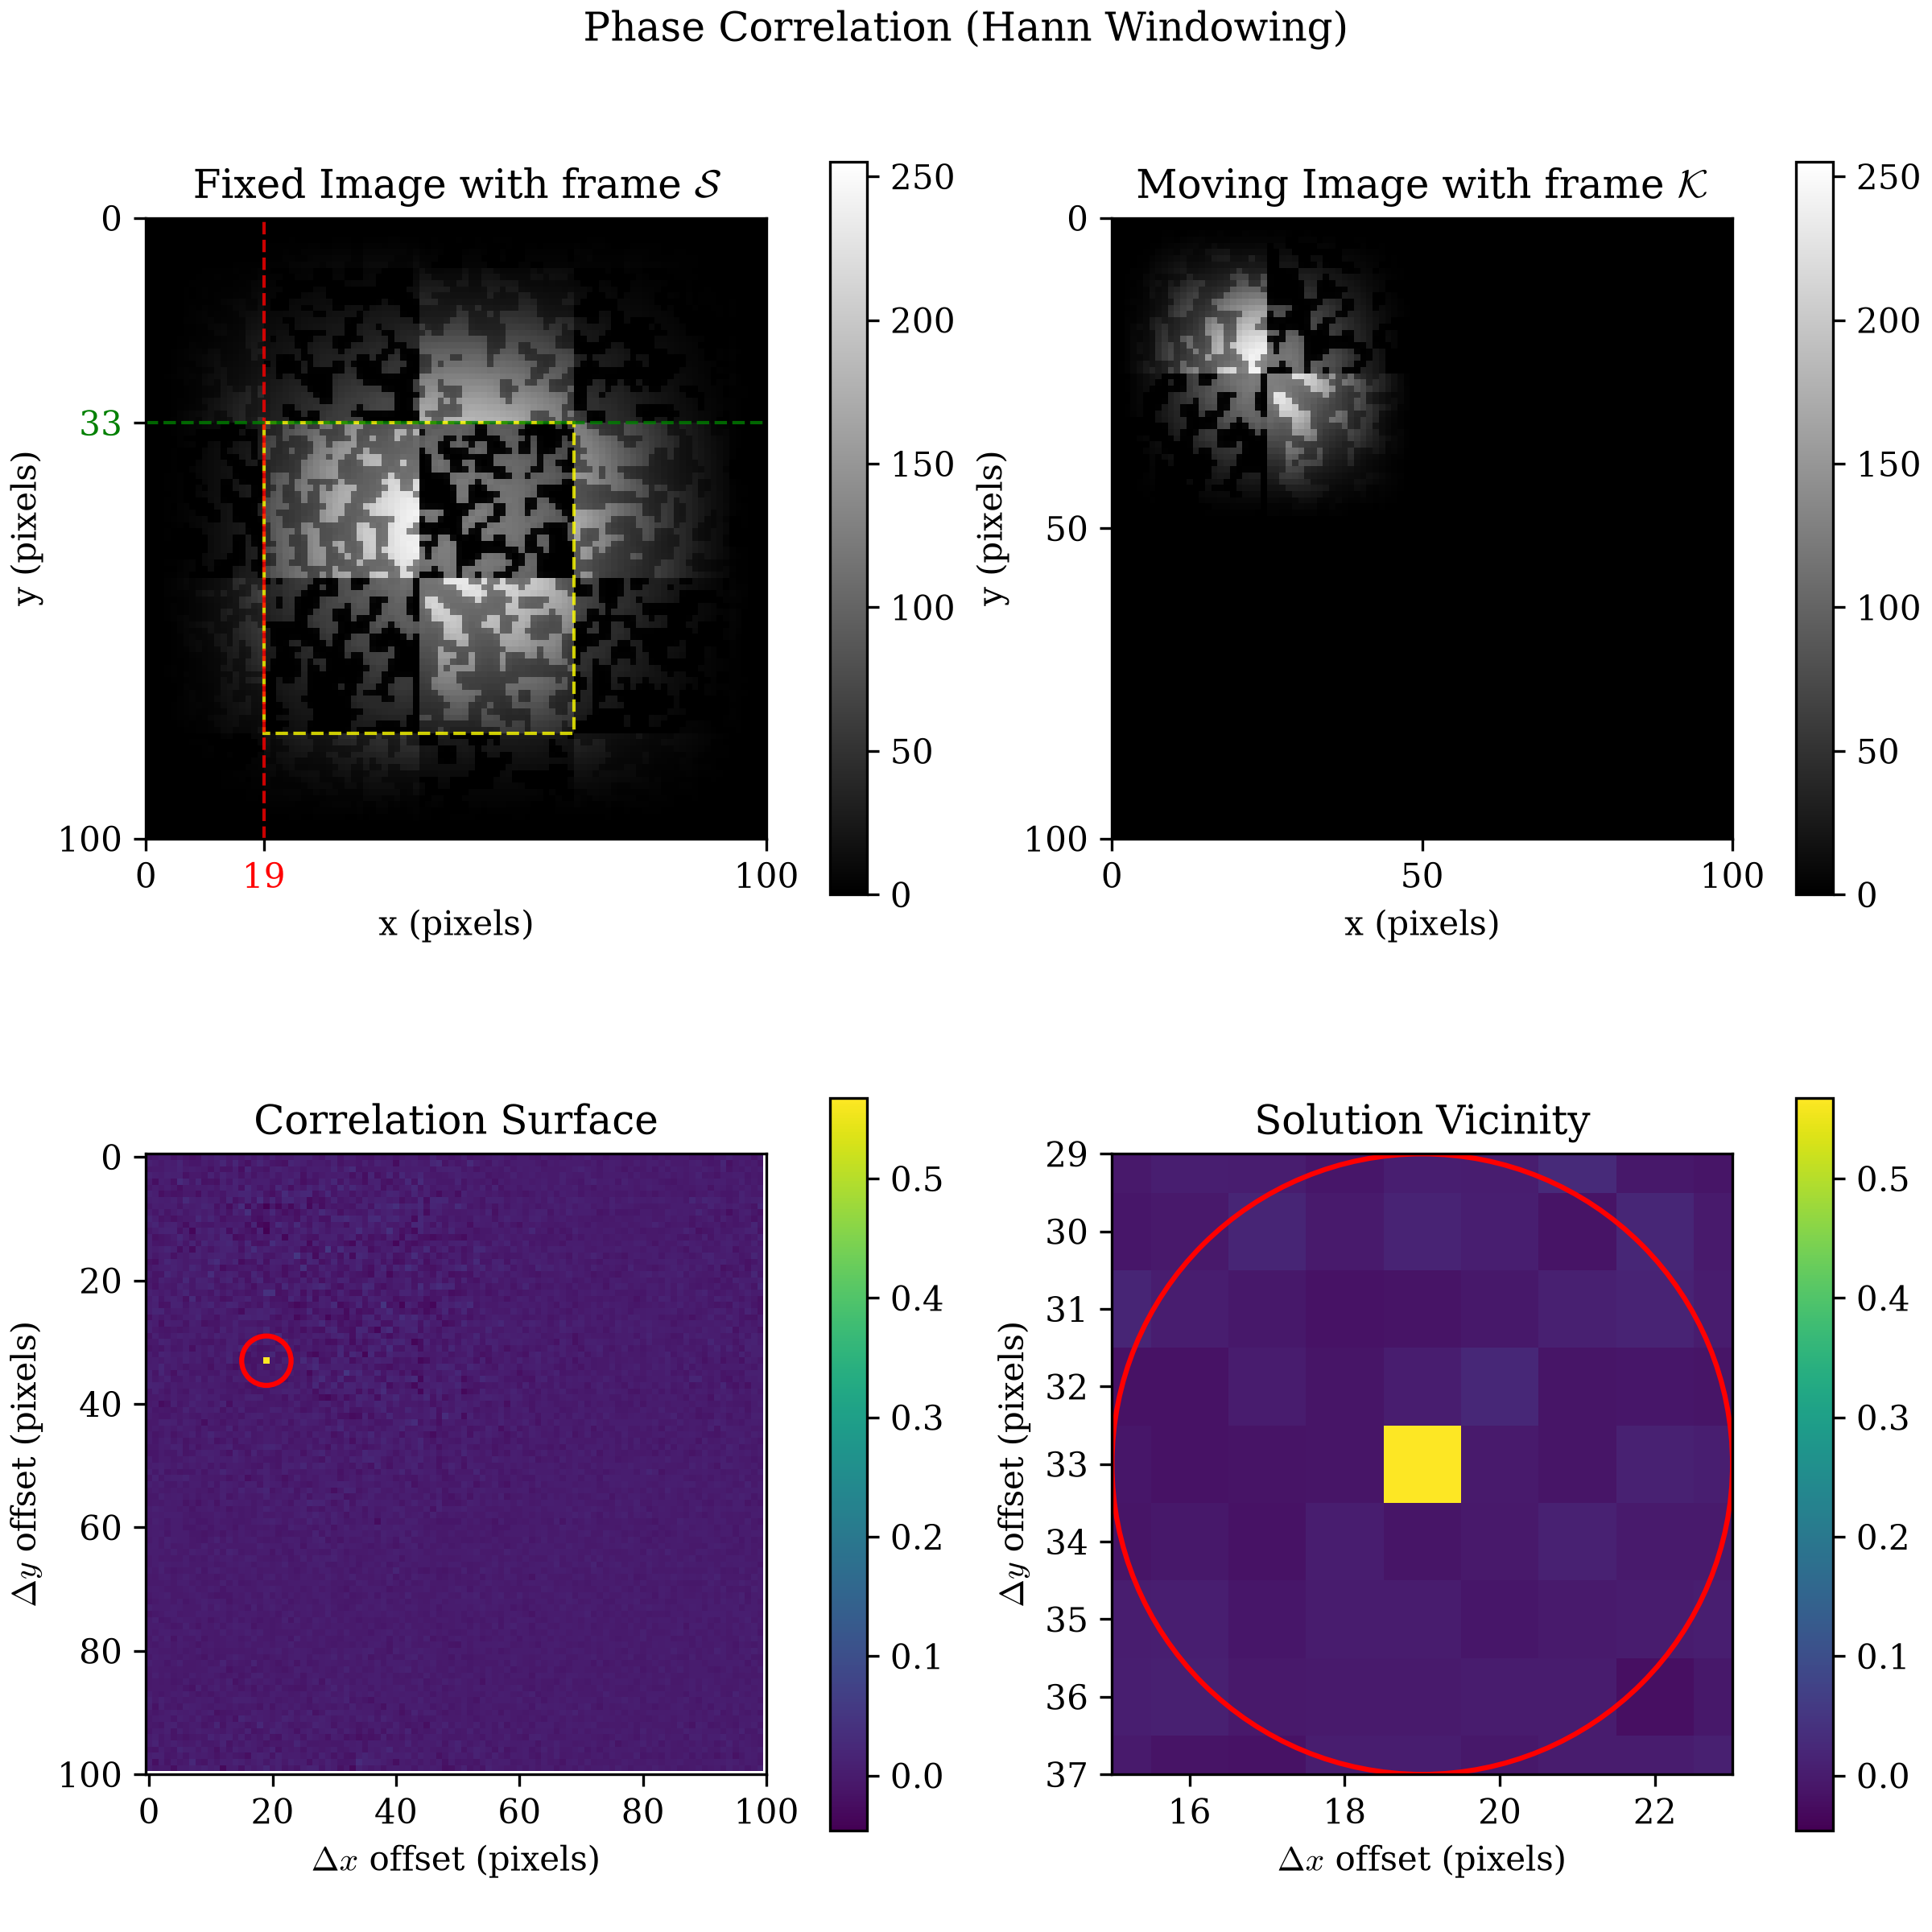
window() only tapers kernel/search before the FFT, it doesn't change the surface's shape or relocate the peak. Unlike No Windowing's panels, though, the Fixed Image and Moving Image panels here darken toward their own edges too — the same Hann taper Windowing shows on this exact kernel, now applied to what's actually fed into the FFT rather than left as a stale, untapered view next to a surface that no longer matches it. What windowing changes numerically is the surface's own values — see Peak Prominence below for how much.Hamming Windowing
phase_correlation_quadrant_plot(
    kernel=kernel,
    search=search,
    windowing=WindowingMethod.HAMMING,
    title="Phase Correlation (Hamming Windowing)",
    path="correlation_visualization_phase_hamming.png",
)
Saved: correlation_visualization_phase_hamming.png
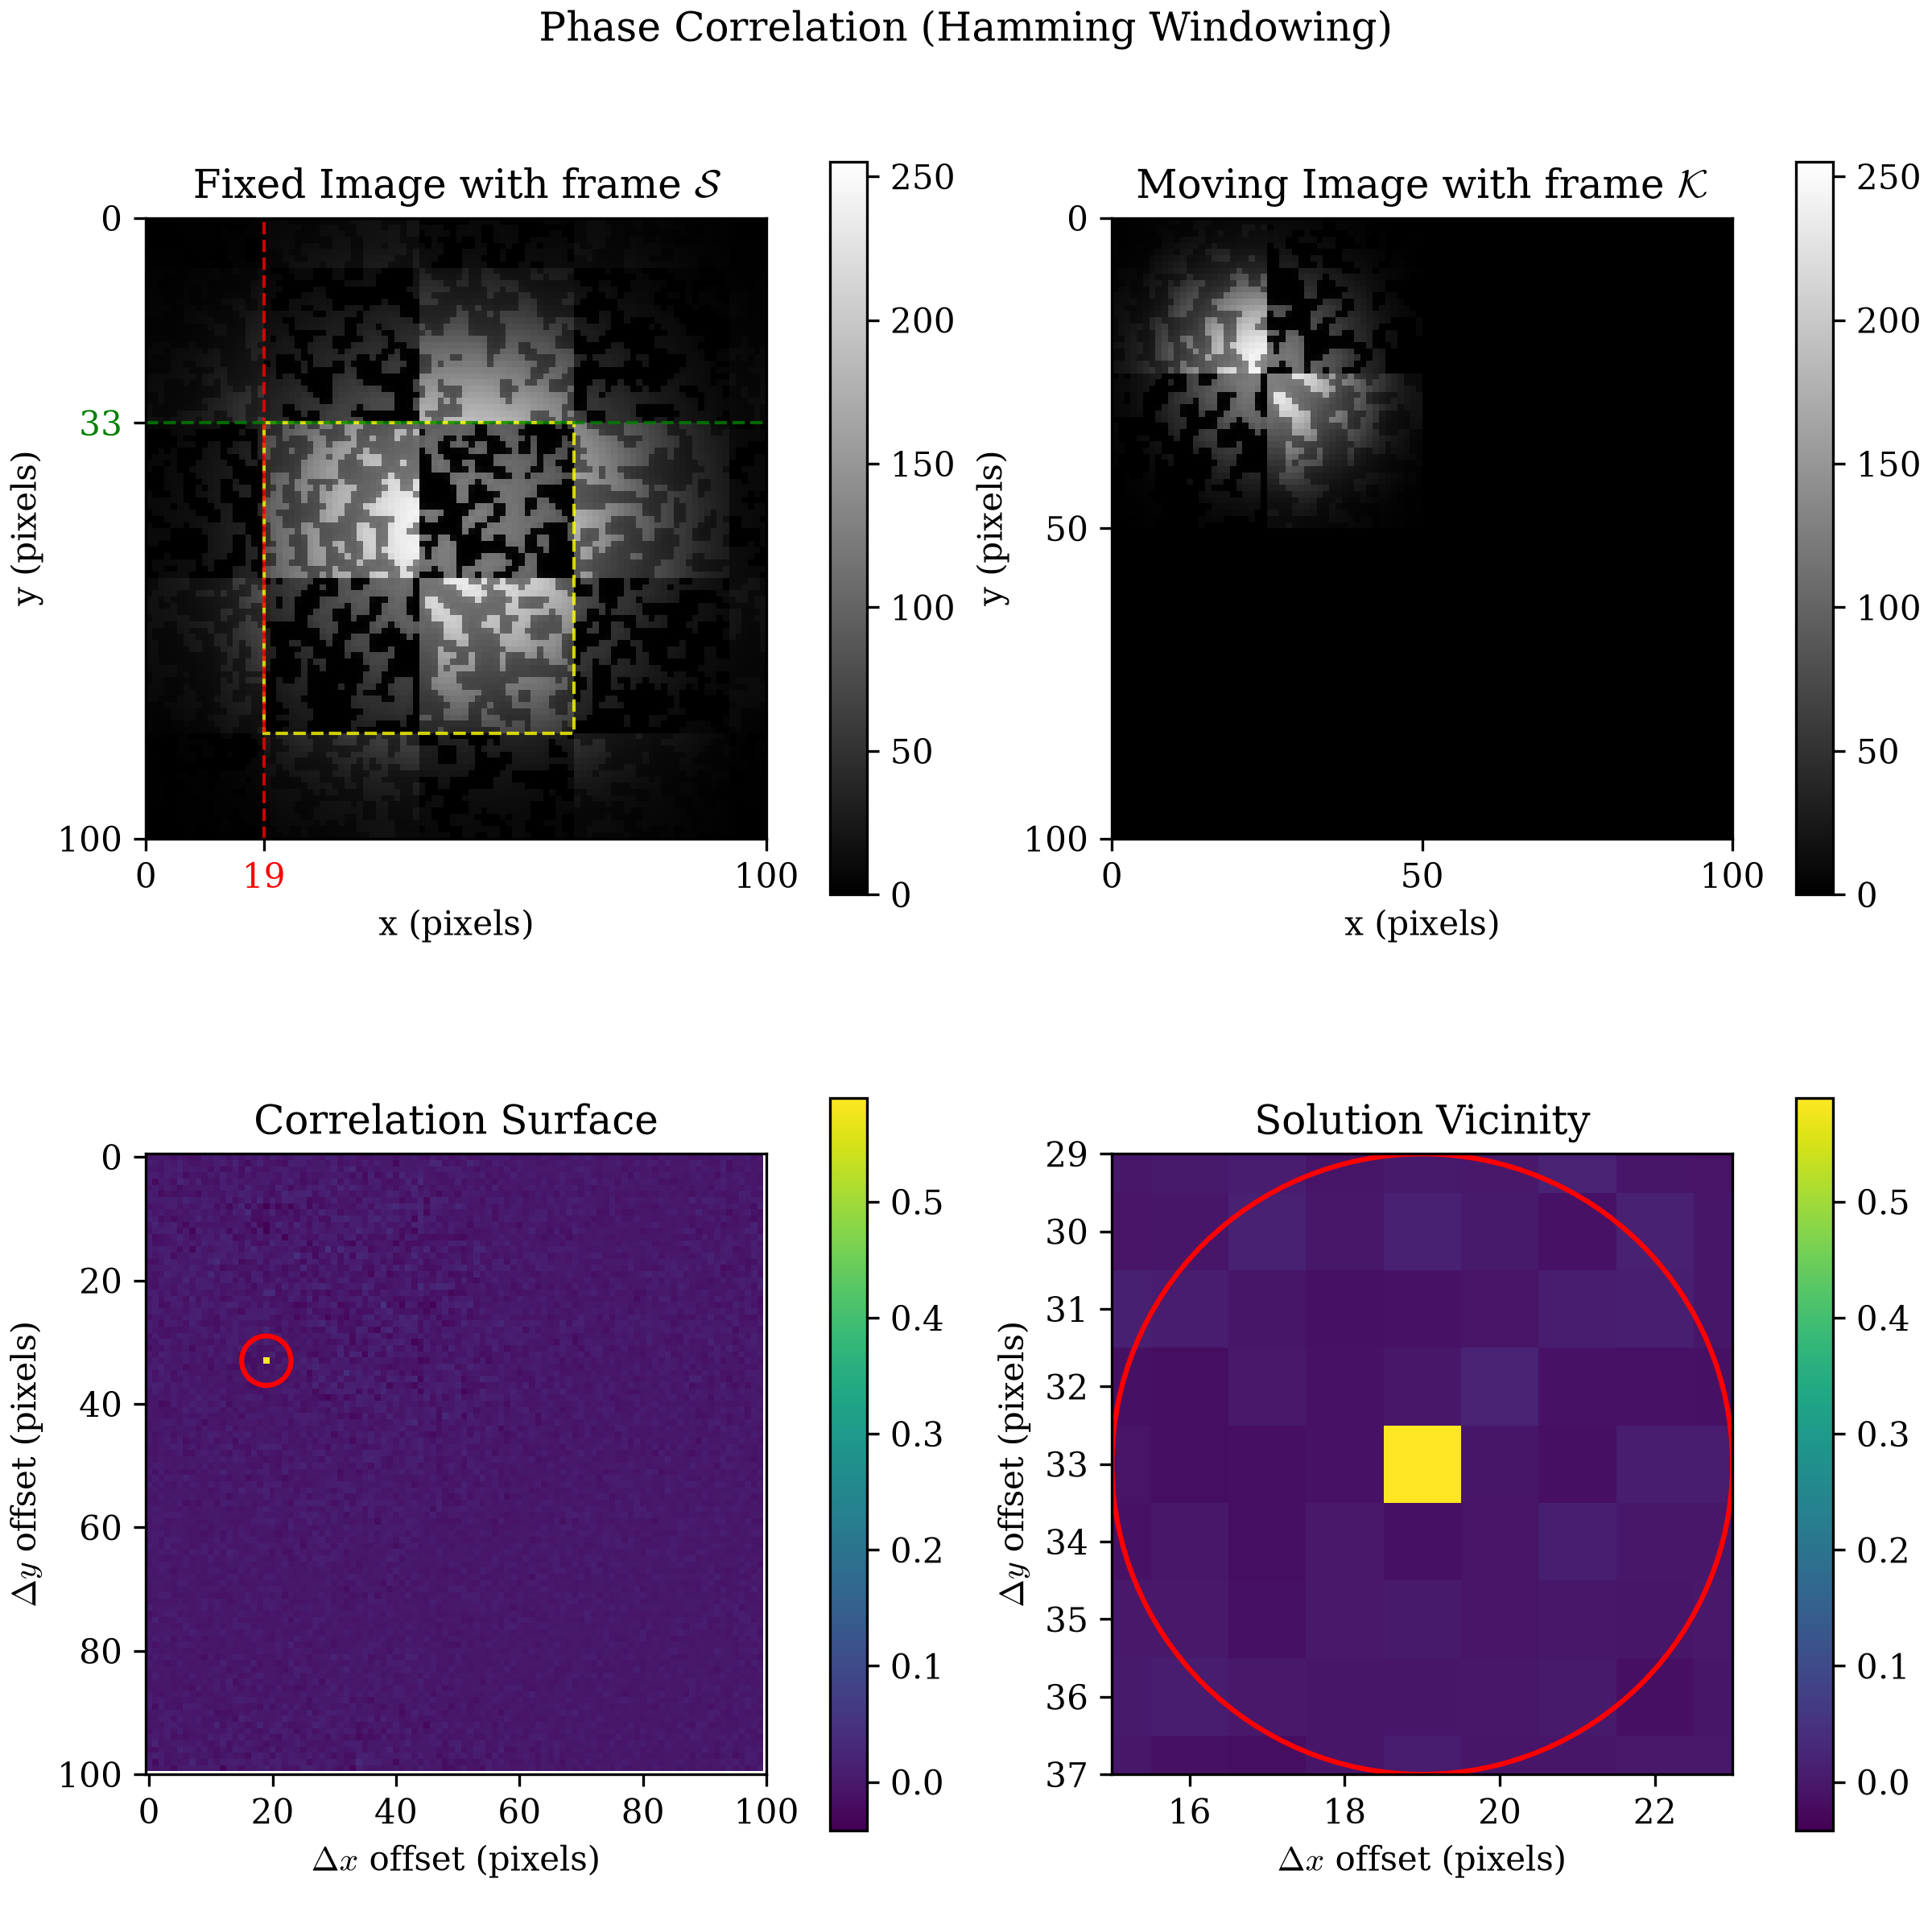
Peak Prominence
That sharpness isn't just a visual impression. Define a correlation surface's peak prominence as how many standard deviations above its own mean the peak sits — a scale-independent way to compare surfaces with very different raw units (CC's arbitrary sums, NCC/ZNCC's -bounded values, phase correlation's own normalized range):
for a correlation surface flattened to its values. By this measure, all three phase correlation surfaces above are dramatically higher than any spatial-domain criterion — and windowing raises that further still, even on this book's clean, noise-free synthetic images:
CC: prominence P = 4.93
NCC: prominence P = 5.60
ZCC: prominence P = 5.48
ZNCC: prominence P = 5.60
Phase correlation (no windowing): prominence P = 38.91
Phase correlation (Hann): prominence P = 56.76
Phase correlation (Hamming): prominence P = 58.95
A histogram of each surface's own values makes the same result visual: each panel's dashed red line is that surface's peak, at the value computed above.
import matplotlib.pyplot as plt
from dictk.correlation import cc, ncc, zcc, zncc, phase_correlation, WindowingMethod

surfaces = {
    "CC": cc(kernel=kernel, search=search),
    "NCC": ncc(kernel=kernel, search=search),
    "ZCC": zcc(kernel=kernel, search=search),
    "ZNCC": zncc(kernel=kernel, search=search),
    "Phase correlation\n(no windowing)": phase_correlation(kernel=kernel, search=search),
    "Phase correlation\n(Hann)": phase_correlation(kernel=kernel, search=search, windowing=WindowingMethod.HANN),
    "Phase correlation\n(Hamming)": phase_correlation(kernel=kernel, search=search, windowing=WindowingMethod.HAMMING),
}

plt.rcParams.update({"font.family": "serif", "mathtext.fontset": "cm"})
fig, axes = plt.subplots(4, 2, figsize=(11, 16), constrained_layout=True)
for ax, (name, surface) in zip(axes.flat, surfaces.items()):
    flat = surface.ravel()
    prominence = (flat.max() - flat.mean()) / flat.std()
    ax.hist(flat, bins=60, color="black", alpha=0.7)
    ax.axvline(flat.max(), color="red", linestyle="--", linewidth=1.5)
    ax.set_yscale("log")
    ax.set_title(f"{name}: $P = {prominence:.1f}$")
    ax.set_xlabel("surface value")
    ax.set_ylabel("frequency")
axes.flat[-1].axis("off")  # 7 panels in a 4x2 grid -- last slot stays empty
fig.savefig("correlation_visualization_prominence.png", dpi=300)
Saved: correlation_visualization_prominence.png
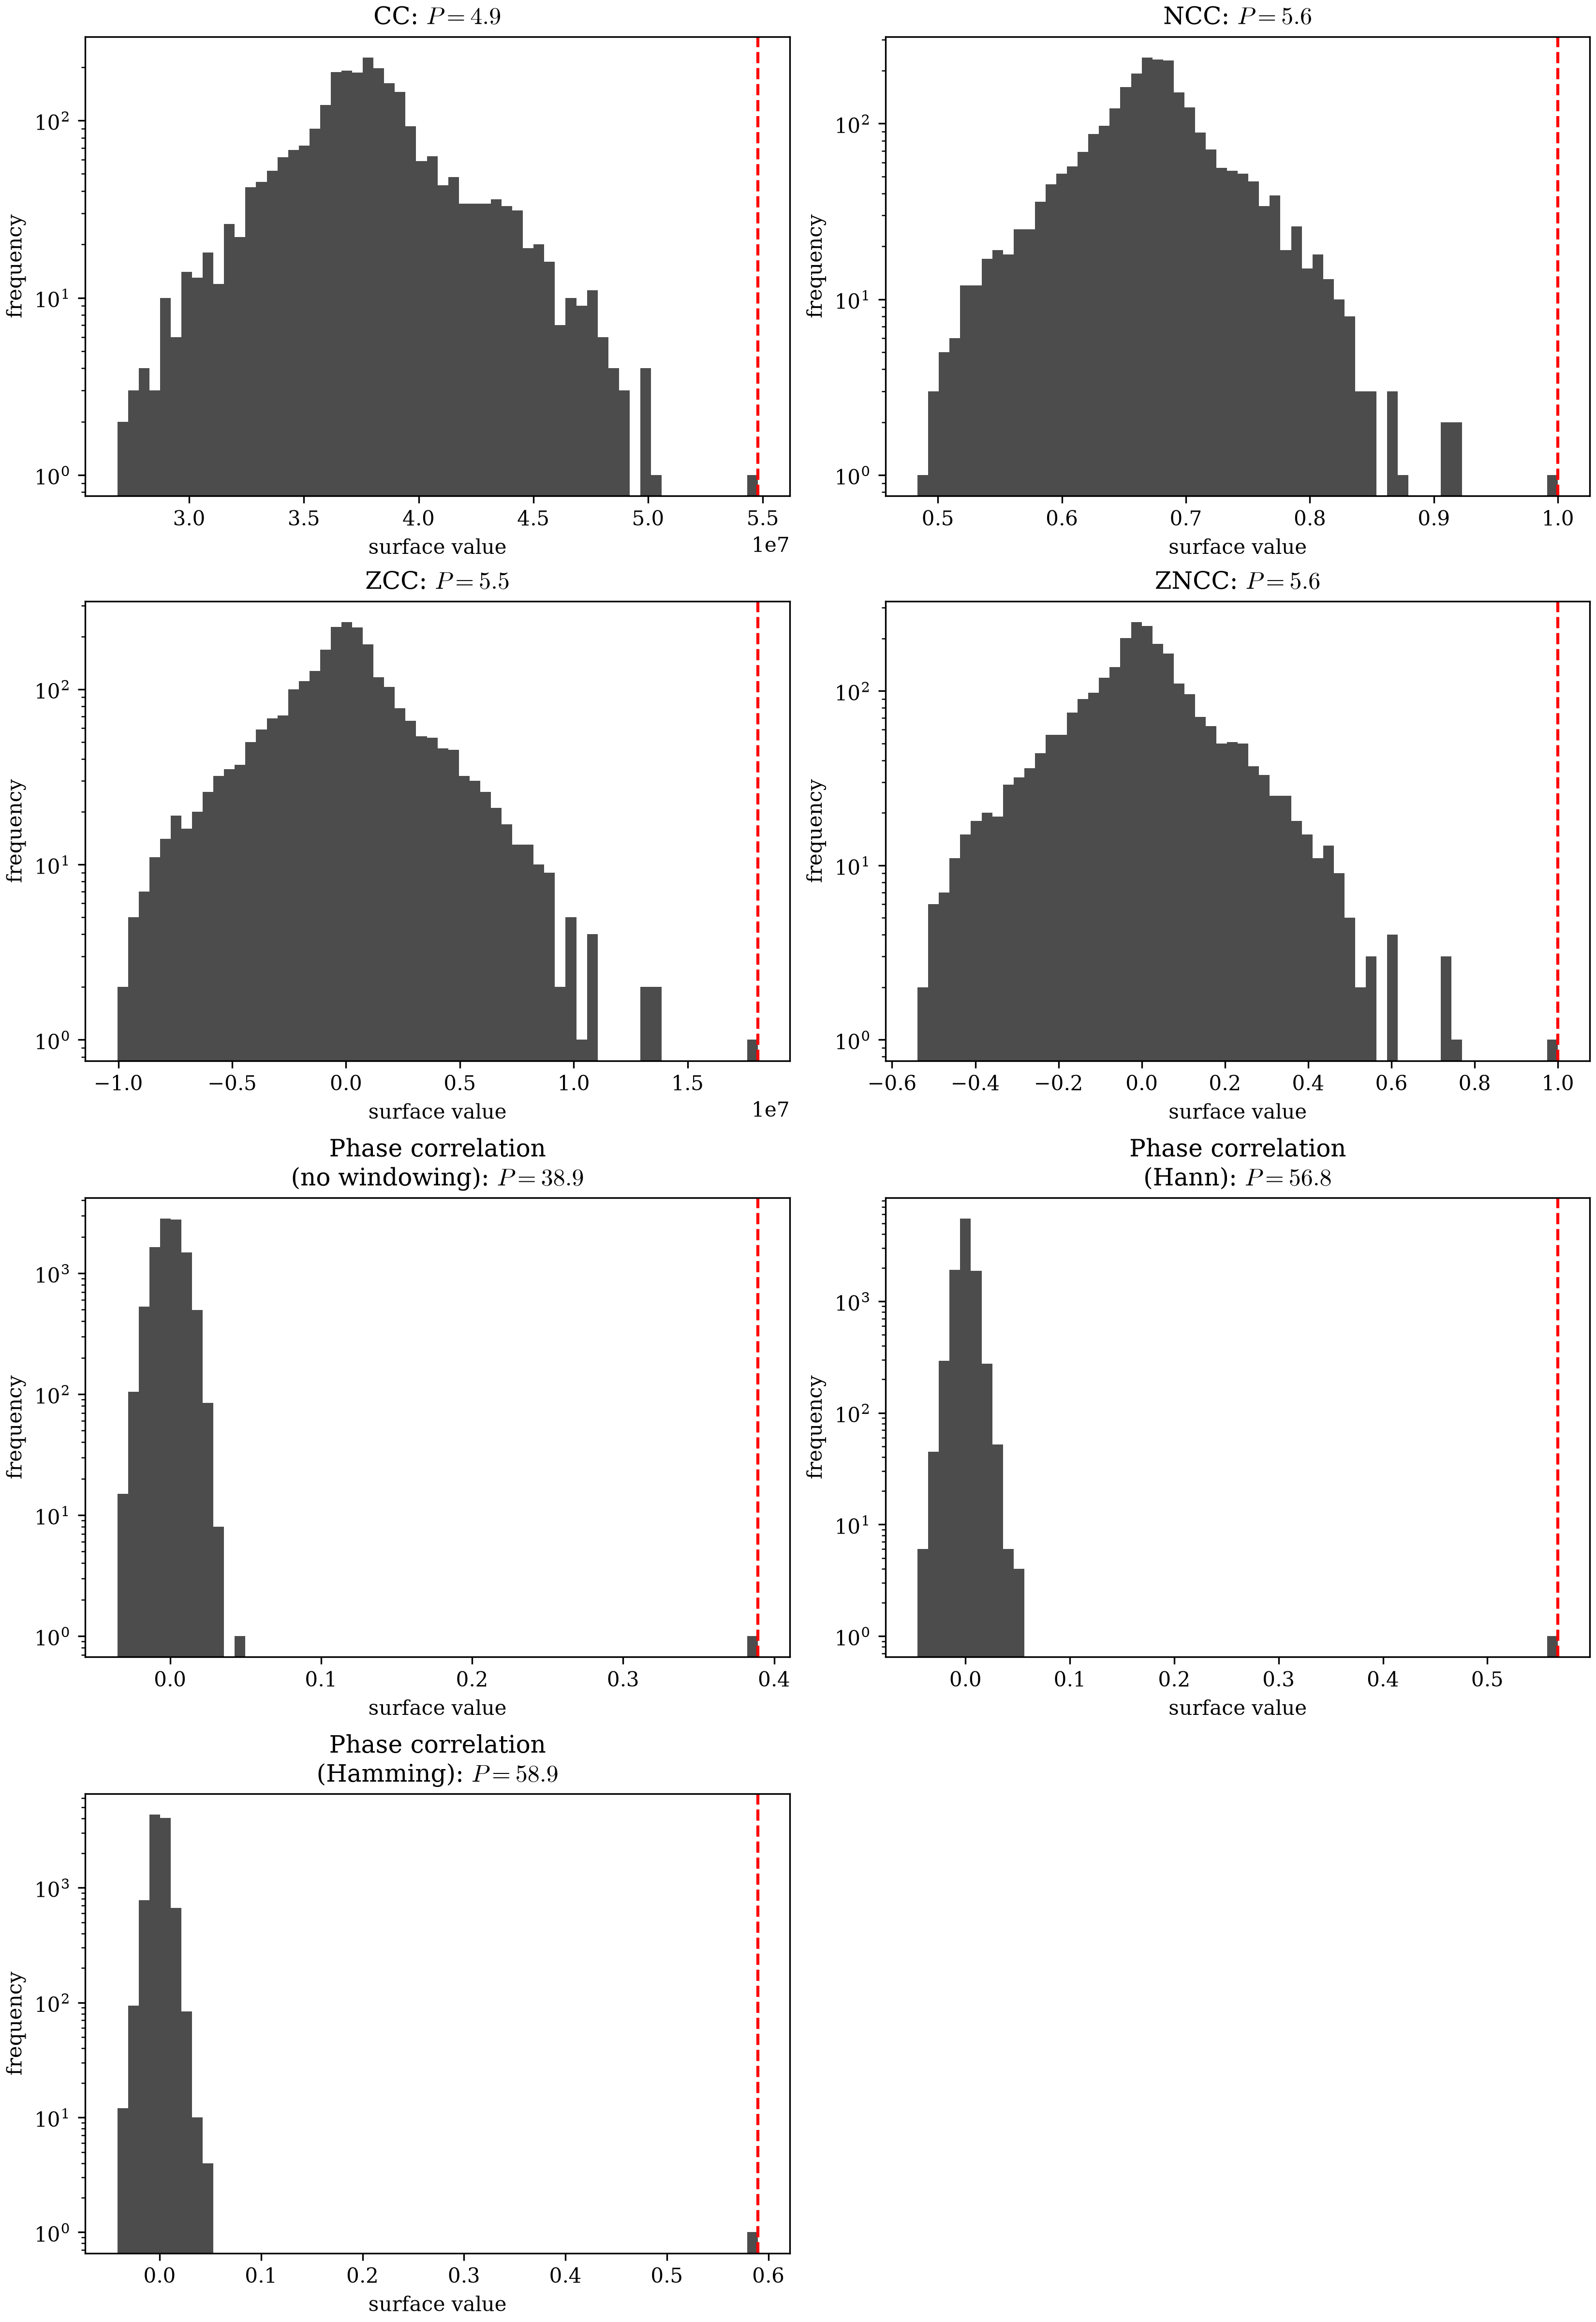
locate already found in Cross Correlation (CC), just plotted by value here rather than position. CC/NCC/ZCC/ZNCC's peaks sit a short, visible distance beyond their own bulk. All three phase correlation panels sit in a class of their own — an empty gap separates each peak from every other value its surface takes on — and windowing (Hann, Hamming) narrows that surface's own bulk further still, widening the gap even more.Windowing's effect here isn't about relocating the peak — all seven surfaces, spatial and Fourier alike, land on the same -pixel offset — it's about how far above the rest of the surface that peak stands. No-windowing phase correlation already beats every spatial criterion by a wide margin (prominence 38.91 vs. ZNCC's 5.60, the best of the four); Hann windowing raises that to 56.76 and Hamming to 58.95, by lowering the energy the leaking, untapered edges were contributing everywhere else on the surface, so the same peak stands out further above that now-lower background. Hann and Hamming land close to each other, both clearly above no windowing — a real, measurable benefit even before considering the noisier, less-clean real-world images this book's synthetic ones deliberately simplify away.
Phase correlation's peak already stands roughly seven times taller above
its own background, relative to the surface's own spread, than even
ZNCC — the most robust of the four spatial criteria — before windowing is
even applied. That sharpness, not just brightness/contrast invariance, is
a second, independent reason dictk.translation.locate is built on phase
correlation rather than a spatial-domain criterion: a sharper peak is
easier to locate with confidence and precision, and harder to confuse
with a nearby runner-up. locate accepts the same windowing parameter
too (see Windowing) — the prominence gain above isn't
unique to the surface phase_correlation() exposes for visualization;
it applies wherever the same FFT-based comparison runs, locate
included.
Multi-Point Motion
Single Point Motion tracked exactly one point, , between a reference and current image. Digital image correlation was illustrated in the context of that single point. Now, we turn to consider many points at once. A collection of tracked points will serve as the nodes of a finite element mesh. This page shows how to track many points simultaneously, and motivates the connection to the Finite Element Method (FEM).
Commercial DIC Context
Commercial DIC software sets up a measurement in a specific order, and
it runs opposite to order presented on this page.
The reversal is a deliberate choice because we have not yet introduced
subpixel accuracy. After subpixel accuracy is
discussed, dictk will follow the same order used by commerical DIC software,
described next:
Kernel size comes first. A kernel must contain enough distinctive texture to correlate reliably. An image will contain features (e.g., a speckle pattern feature such as a corner or edge). The goal is to get enough (but not too many) pixels to describe a feature. Too few pixels cause the kernel contents to be ambiguous. Too many pixels cause the kernel to be saturated with pixels that do not participate in the feature, resulting in poor-to-no correlation. Too many pixels also can also increase computational cost beyond what is necessary for a successful correlation.
Ultimately, the size of the kernel is based on the speckle pattern's own feature size and the camera's resolution, which dictates the number of pixels per unit length present in the image.
Point spacing comes second. Once kernel size is fixed, point spacing (where to place each kernel center) follows from it.
- Some practitioners deliberately overlap neighboring kernels: A common convention is 50-75% overlap. So spacing works out to roughly a quarter to a half of the kernel's own side length — to oversample the field for a smoother reconstruction.
- Others keep kernels non-overlapping, so each point's own measurement stays independent of its neighbors': No two points ever look at the same underlying pixels.
Either way, the same tradeoff governs the choice: Too close, and neighboring kernels duplicate each other's content; too far apart, and the measurement undersamples the field.
The point grid becomes FEA nodes afterward, not before. Once tracking finishes, the resulting grid of measured points is what gets used as finite-element nodes. The mapping between DIC points and mesh points can be direct or indirect. Direct build a mesh directly from the DIC point cloud. Indirect uses the point cloud as an interpolation basis for a separately designed mesh. The FE mesh's density inherits the kernel-and-spacing choice for the correlation.
Let's continue with this example with a rather large choice for a pixel
size. Let kernel_margin_width=20 pixel and kernel_margin_height=20 pixel.
The kernel's side length is twice its margin: pixels.
This kernel is enough to contain plenty of distinctive texture
on astronaut0's uniformly-speckled, synthetic surface,
where no single location demands special care over another.
Heuristically, we typically use kernel sizes of 25 x 25 pixel, up to
35 x 35 pixel (considerably smaller than the 40 x 40 pixel used in this
example).
A common rule of thumb (no hard requirement behind it) is to keep a
kernel's own side length comfortably inside the point spacing —
the geometric floor for zero overlap is exact: with an isotropic
kernel (kernel_margin_width=kernel_margin_height), two neighboring
kernels start overlapping once the kernel's own full side length
exceeds the spacing between their center points. For this example,
spacing has to reach
at least 40 pixels in both directions to clear that floor; right at
exactly 40 pixels, neighboring kernels would touch with zero gap
between them.
For now, we choose a point spacing not based on kernel size, but on locations that, given a prescribed stretch factor, will land exactly on an integer location in the deformed configuration. We need integer positions for now because we have not yet introduced subpixel accuracy.
Let spacing_x=50 px, spacing_y=55 px be the point spacing for
this page's example, keeping kernels non-overlapping (the second
convention named above) — both comfortably above that 40-pixel floor:
a 10-pixel gap in and a 15-pixel gap in , so every kernel's own
boundary will read as visibly separate from its neighbors', not merely
non-overlapping.
The following figure illustrates point spacing in the context the kernel's size:
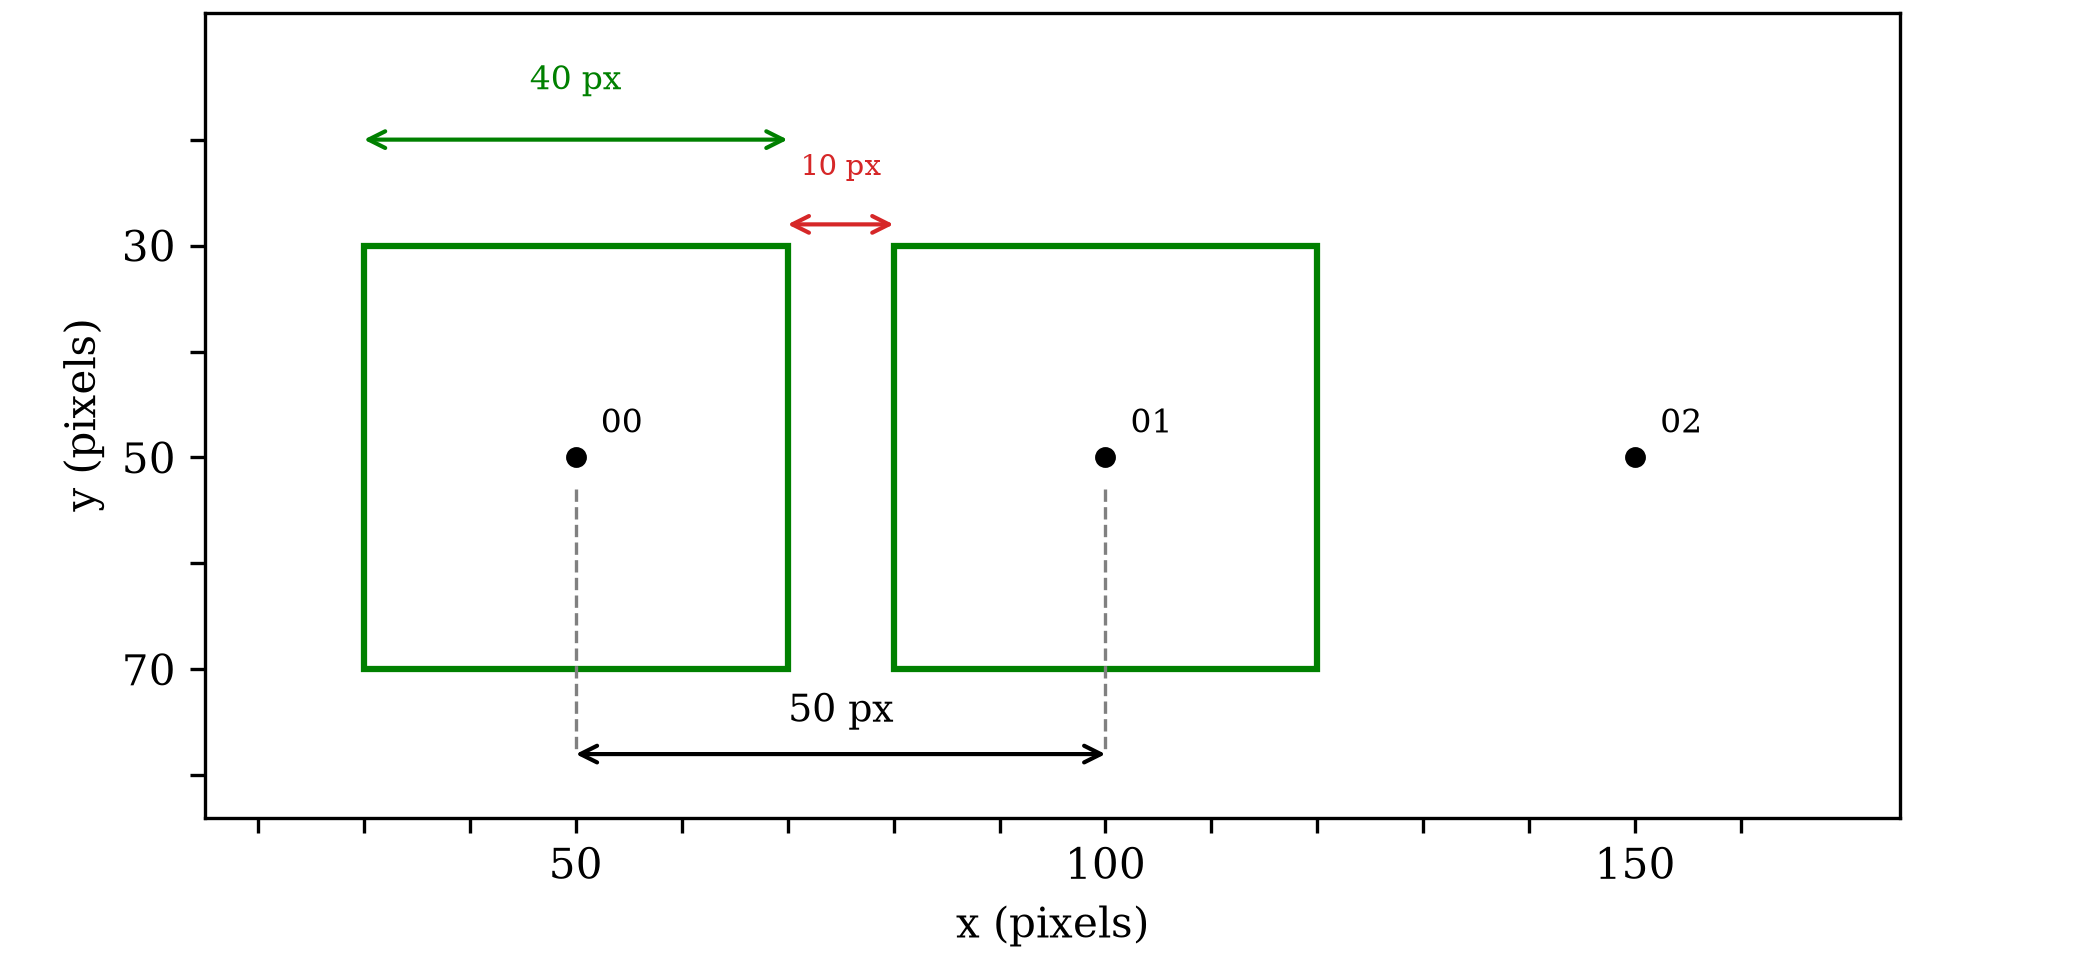
Show the figure-generating code
import matplotlib.pyplot as plt
import matplotlib.patches as patches
from dictk.image import PixelCoordinate

p0, p1, p2 = PixelCoordinate(x=50, y=50), PixelCoordinate(x=100, y=50), PixelCoordinate(x=150, y=50)
kernel_margin = 20

plt.rcParams.update({"font.family": "serif", "mathtext.fontset": "cm"})
fig, ax = plt.subplots(figsize=(7, 3.2), constrained_layout=True)

for p, label in [(p0, "00"), (p1, "01"), (p2, "02")]:
    ax.plot(p.x, p.y, "o", color="black", markersize=4)
    ax.annotate(label, (p.x, p.y), textcoords="offset points", xytext=(6, 6), fontsize=8)

for p in (p0, p1):
    ax.add_patch(patches.Rectangle(
        (p.x - kernel_margin, p.y - kernel_margin),
        2 * kernel_margin, 2 * kernel_margin,
        edgecolor="green", facecolor="none", linewidth=1.5,
    ))

box_top = p0.y - kernel_margin      # 30
box_bottom = p0.y + kernel_margin   # 70

# 50-pixel point spacing. The dashed guide lines start near each point
# (nearly touching its marker) and run down through its kernel box to
# the dimension line just below the boxes. Arrow flush with the dashed
# lines (shrinkA/shrinkB=0); label centered at the true midpoint between
# the box bottom and the dimension line.
dim_y = box_bottom + 8
for p in (p0, p1):
    ax.plot([p.x, p.x], [p.y + 3, dim_y], color="gray", linestyle="--", linewidth=0.8)
ax.annotate("", xy=(p0.x, dim_y), xytext=(p1.x, dim_y), arrowprops=dict(arrowstyle="<->", color="black", shrinkA=0, shrinkB=0))
ax.text((p0.x + p1.x) / 2, (box_bottom + dim_y) / 2, "50 px", ha="center", va="center", fontsize=9)

# 40-pixel kernel width, flush with the box's own left/right edges
# (shrinkA/shrinkB=0 so the arrow isn't inset from those edges).
top_y = box_top - 10
ax.annotate("", xy=(p0.x - kernel_margin, top_y), xytext=(p0.x + kernel_margin, top_y), arrowprops=dict(arrowstyle="<->", color="green", shrinkA=0, shrinkB=0))
ax.text(p0.x, top_y - 4, "40 px", ha="center", va="bottom", fontsize=8, color="green")

# 10-pixel gap between the two kernels' facing edges, moved up to the
# boxes' shared top edge, flush with the box's own edges (shrinkA/
# shrinkB=0), with the label on top of the dimension line.
gap_y = box_top - 2
ax.annotate("", xy=(p0.x + kernel_margin, gap_y), xytext=(p1.x - kernel_margin, gap_y), arrowprops=dict(arrowstyle="<->", color="tab:red", shrinkA=0, shrinkB=0))
ax.text(p0.x + kernel_margin + (p1.x - kernel_margin - (p0.x + kernel_margin)) / 2, gap_y - 4, "10 px", ha="center", va="bottom", fontsize=7, color="tab:red")

ax.set_xlim(15, 175)
ax.set_ylim(84, 8)

# Tick marks: 50/100/150 in x (the point positions), 40 pixels apart
# starting at 20; every 10 pixels in y, but text labels only at
# 30/50/70 (the box's top edge, the point row, and the box's bottom
# edge) -- a tight range with no dead space below the boxes, since the
# dimension line sits just beneath them.
xticks = list(range(20, 161, 10))
ax.set_xticks(xticks)
ax.set_xticklabels([str(v) if v in (50, 100, 150) else "" for v in xticks])
yticks = list(range(20, 81, 10))
ax.set_yticks(yticks)
ax.set_yticklabels([str(v) if v in (30, 50, 70) else "" for v in yticks])

ax.set_xlabel("x (pixels)")
ax.set_ylabel("y (pixels)")
ax.set_aspect("equal")
fig.savefig("multi_point_motion_spacing.png", dpi=300)
Saved: multi_point_motion_spacing.png
With kernel size and the point spacing it implies both settled, the point grid can be generated next.
Point Grid
A grid is an ordered, sequential collection of points, arranged in a rectilinear
pattern.
The function dictk.grid.generate creates
a grid that spans some number of points along and along ,
with some spacing between adjacent points along each axis.
The count of points along and along need not be equal, and the
spacing along and along need not be equal either. The grid is a
general rectangular collection of points, not necessarily a square or
uniformly-spaced one. spacing_x and spacing_y are in pixels.
This page uses astronaut0, the speckle pattern combined with the
astronaut photograph introduced in Image
Generation.
from dictk.image import read, PixelCoordinate
from dictk.plot import point_grid_plot
from dictk.grid import generate

reference_image = read(path="astronaut0.png")

points = generate(
    origin=PixelCoordinate(x=50, y=50),
    count_x=3,
    count_y=4,
    spacing_x=50,
    spacing_y=55,
)
point_grid_plot(
    image=reference_image,
    points=points,
    color="orange",
    figsize=(6.4, 4.8),
    path="multi_point_motion_grid.png",
)
Saved: multi_point_motion_grid.png
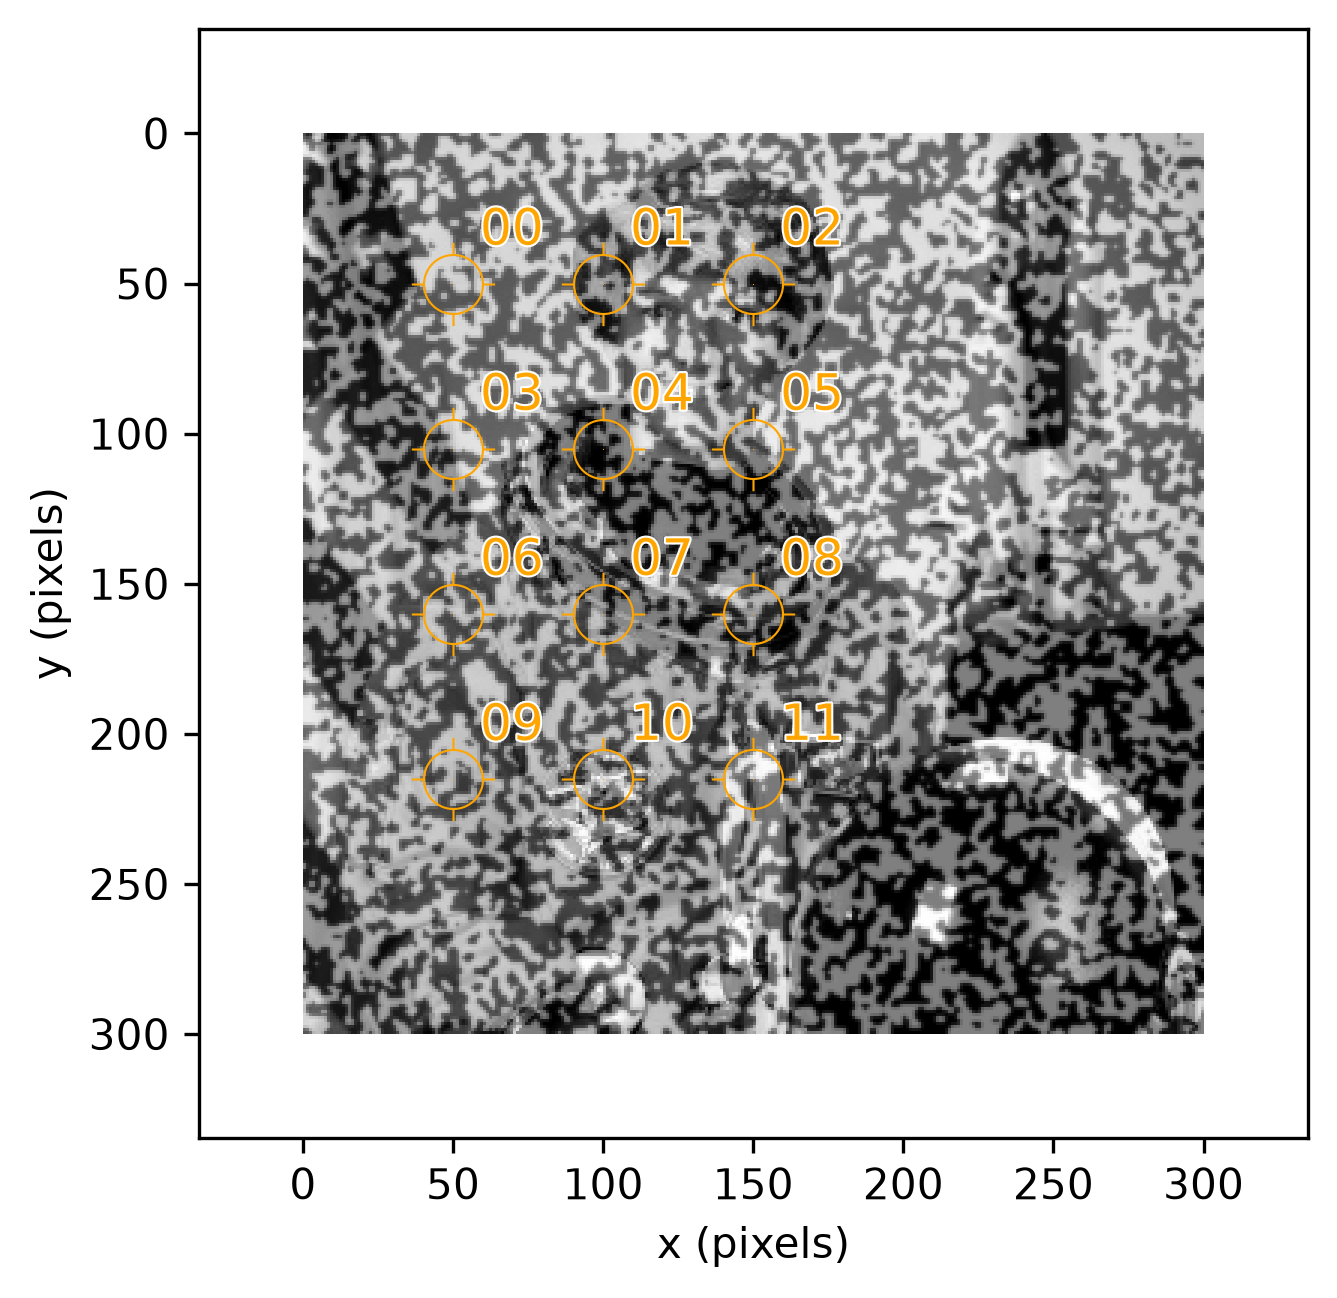
astronaut0 with a 3x4 grid of 12 points (count_x=3, count_y=4), spaced 50 pixels apart along and 55 pixels apart along (spacing_x=50, spacing_y=55), labeled 00-11 in row-major order (top-left to bottom-right).The reference coordinates in pixels for each point follow:
| Point | Reference Configuration | |
|---|---|---|
| (pixels) | (pixels) | |
| 00 | 50 | 50 |
| 01 | 100 | 50 |
| 02 | 150 | 50 |
| 03 | 50 | 105 |
| 04 | 100 | 105 |
| 05 | 150 | 105 |
| 06 | 50 | 160 |
| 07 | 100 | 160 |
| 08 | 150 | 160 |
| 09 | 50 | 215 |
| 10 | 100 | 215 |
| 11 | 150 | 215 |
from dictk.image import translate

dx, dy = -6, 8
current_image = translate(arr=reference_image, dx=dx, dy=dy)
Tracking the Grid
Every point's own kernel and search area, using the kernel size chosen
above, look like this.
dictk.plot.point_grid_boxes_plot
draws one box type per call, so kernel and search area each get their own
figure — each point's own box gets its own color and its own legend
entry (kernel 00, kernel 01, ..., kernel 11), cycling through a
12-color palette (using matplotlib's Tableau colormap):
from dictk.plot import point_grid_boxes_plot

point_grid_boxes_plot(
    image=reference_image,
    points=points,
    margin_width=20,
    margin_height=20,
    label_prefix="kernel",
    figsize=(6.4, 4.8),
    path="multi_point_motion_kernels.png",
)
Saved: multi_point_motion_kernels.png
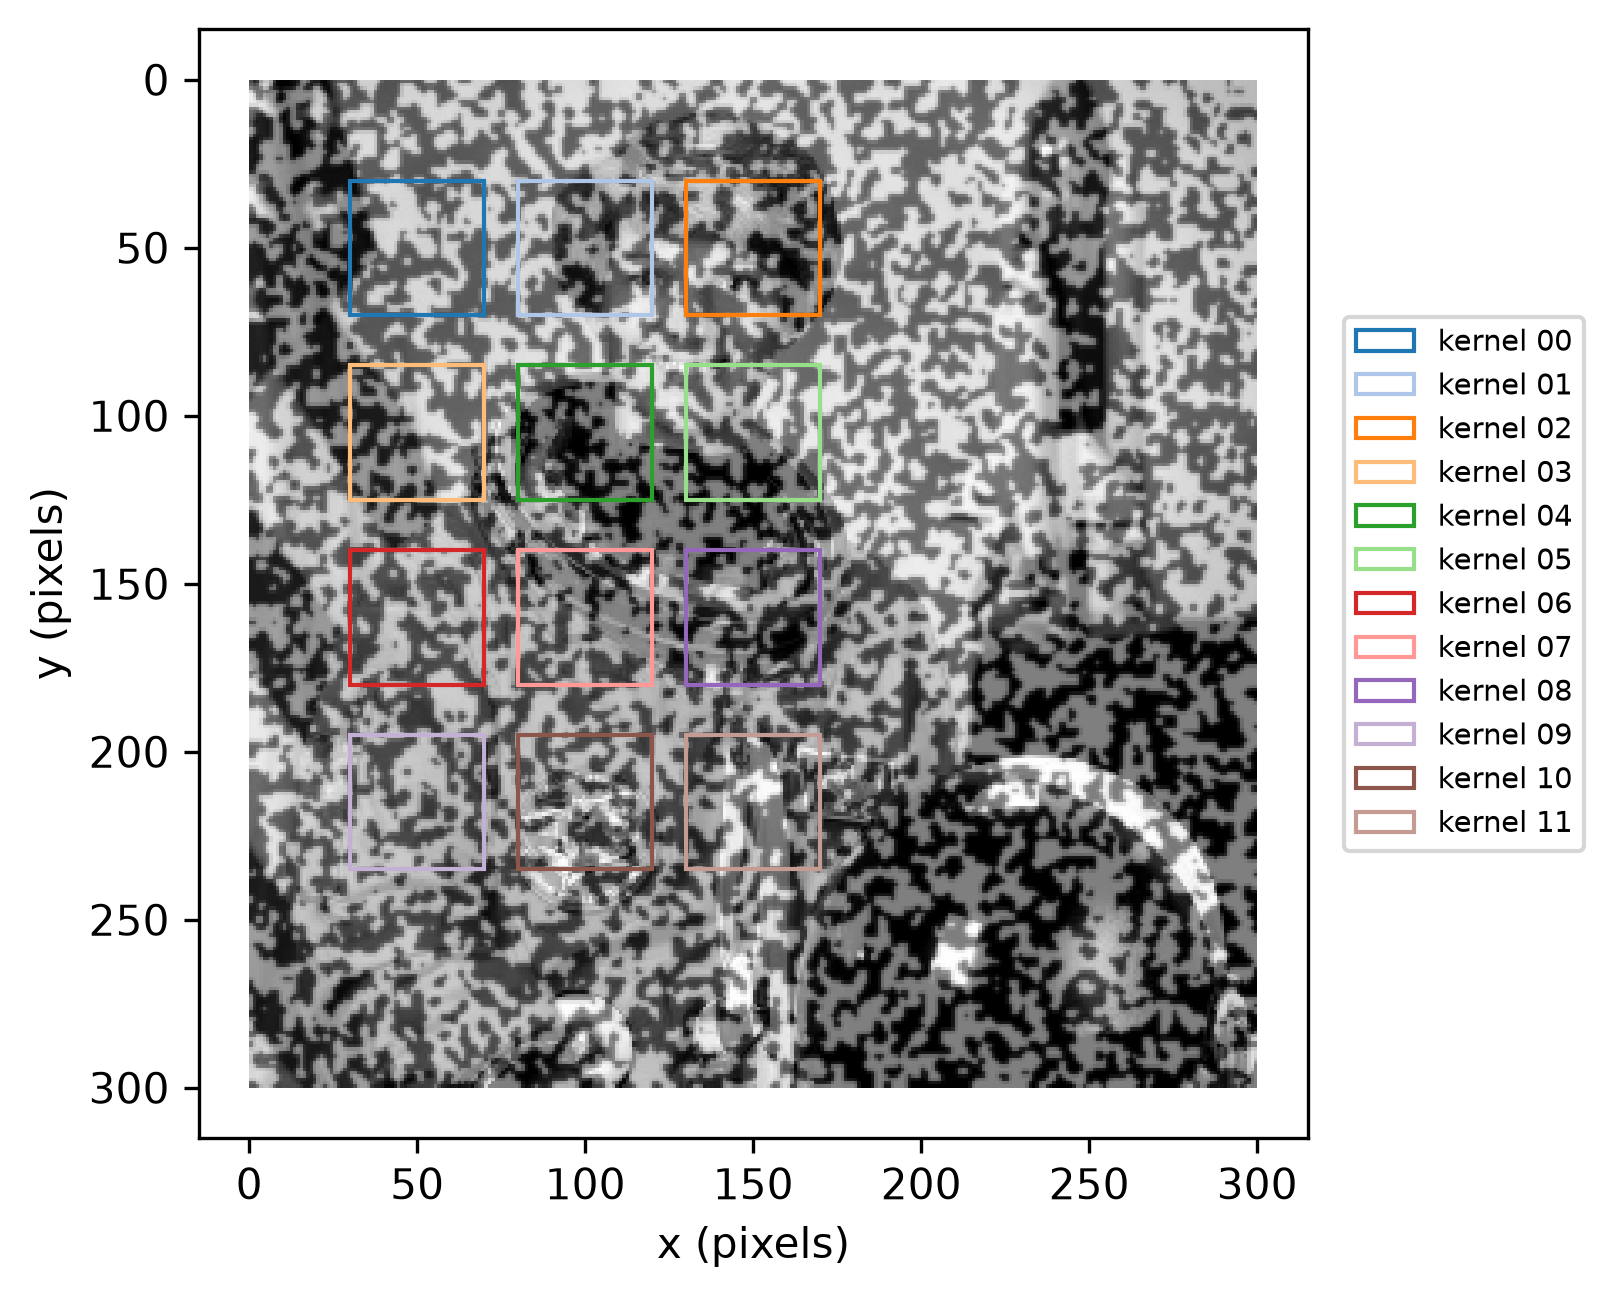
margin_width=20, margin_height=20).The kernel comes from reference_image. The search area comes from
current_image instead — still centered on each point's reference
position (search_centers defaults to reference_points), since the
point's true displacement is exactly what tracking is trying to find:
point_grid_boxes_plot(
    image=current_image,
    points=points,
    margin_width=48,
    margin_height=52,
    label_prefix="search area",
    figsize=(6.4, 4.8),
    path="multi_point_motion_search.png",
)
Saved: multi_point_motion_search.png
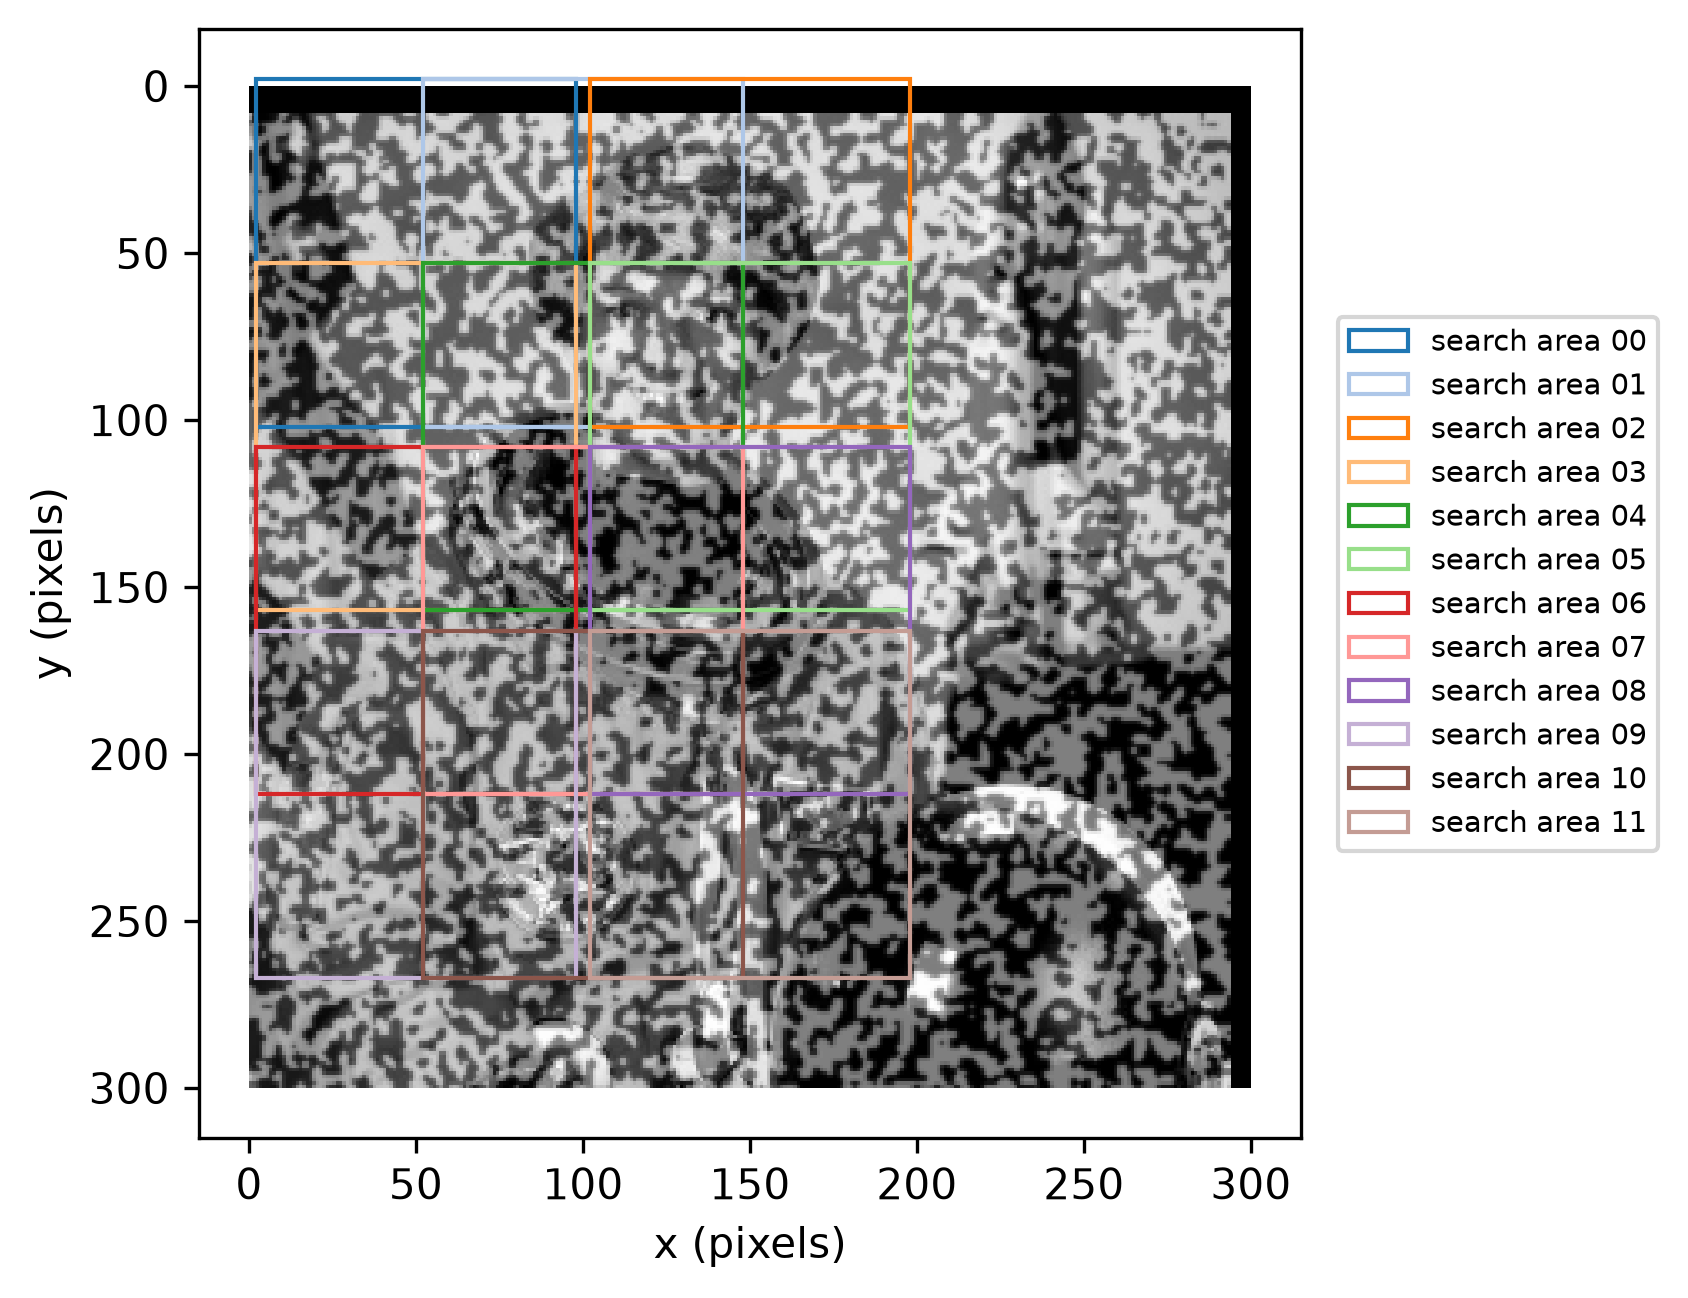
margin_width=48, margin_height=52), drawn on current_image — the region actually searched — and still centered on each point's reference position.Nothing requires the kernel to be isotropic — dictk supports an
independent margin per axis just as easily. The equal 20/20 above is
a deliberate choice to illustrate that dictk supports both isotropic and
non-isotropic margins, not a consequence of spacing_x and spacing_y
being unequal forcing one shape or the other.
The search area, by contrast, keeps a clearly
non-isotropic shape: search_margin_width=48, search_margin_height=52
— just under the point spacing itself, comfortably containing the known
-pixel displacement with plenty of room to spare, while staying
just shy of spacing_x/spacing_y rather than matching them outright.
That much slack still means search areas overlap their neighbors heavily
and run off the image at the edges, which is harmless:
subimage zero-pads whatever falls
outside current_image. Unlike kernels, search areas that overlap cost
nothing aside from redundant computation; there's no accuracy downside to
searching the same region for two different points.
One important practical detail: phase_cross_correlation
requires the kernel and search area to be exactly the same shape. So
dictk.translation.locate doesn't
crop the search area down to the kernel's size; rather, it zero-pads the kernel up to match the search area's size. Here a
40x40 kernel is zero-padded up to the search area's 96x104 size.
Note: In practice, kernel size has little effect on FFT runtime once a search area is chosen — the transform zero-pads the kernel up to match the search area's own size. Shrinking an already-small kernel further doesn't make the correlation any faster.
Single Point Motion
confirmed that a single point's found position matches a known
displacement exactly. Reuse current_image from Point
Grid — the same -pixel
displacement. The same idea, applied to all 12 points in the grid at
once, is exactly what a real DIC workflow looks like.
dictk.grid.locate tracks all 12 points
in one call. It doesn't do the correlation itself — it calls
dictk.translation.locate once
per point, and that function is dictk's actual FFT-based DIC engine: for
each point it extracts a kernel from reference_image and a search area
from current_image, then locates the kernel within the search area via
skimage.registration.phase_cross_correlation — FFT-based phase
cross-correlation, not a spatial-domain sliding-window search (see
Correlation Criteria for the
single-point version of this same technique).
Twelve points means twelve independent calls into that engine, using the
same kernel and search-area sizes visualized above:
from dictk.grid import locate

found = locate(
    reference_image=reference_image,
    current_image=current_image,
    reference_points=points,
    kernel_margin_width=20,
    kernel_margin_height=20,
    search_margin_width=48,
    search_margin_height=52,
)
Point  found        expected     match
00      44,58       44,58       True
01      94,58       94,58       True
02     144,58      144,58       True
03      44,113      44,113      True
04      94,113      94,113      True
05     144,113     144,113      True
06      44,168      44,168      True
07      94,168      94,168      True
08     144,168     144,168      True
09      44,223      44,223      True
10      94,223      94,223      True
11     144,223     144,223      True
Every one of the 12 found positions matches reference_points[i] + (dx, dy) exactly — not approximately, the same exact-integer-pixel guarantee
Single Point Motion established for one point,
now confirmed across the whole grid at once:
from dictk.plot import point_grid_plot

point_grid_plot(
    image=current_image,
    points=found,
    color="orange",
    figsize=(6.4, 4.8),
    path="multi_point_motion_found.png",
)
Saved: multi_point_motion_found.png
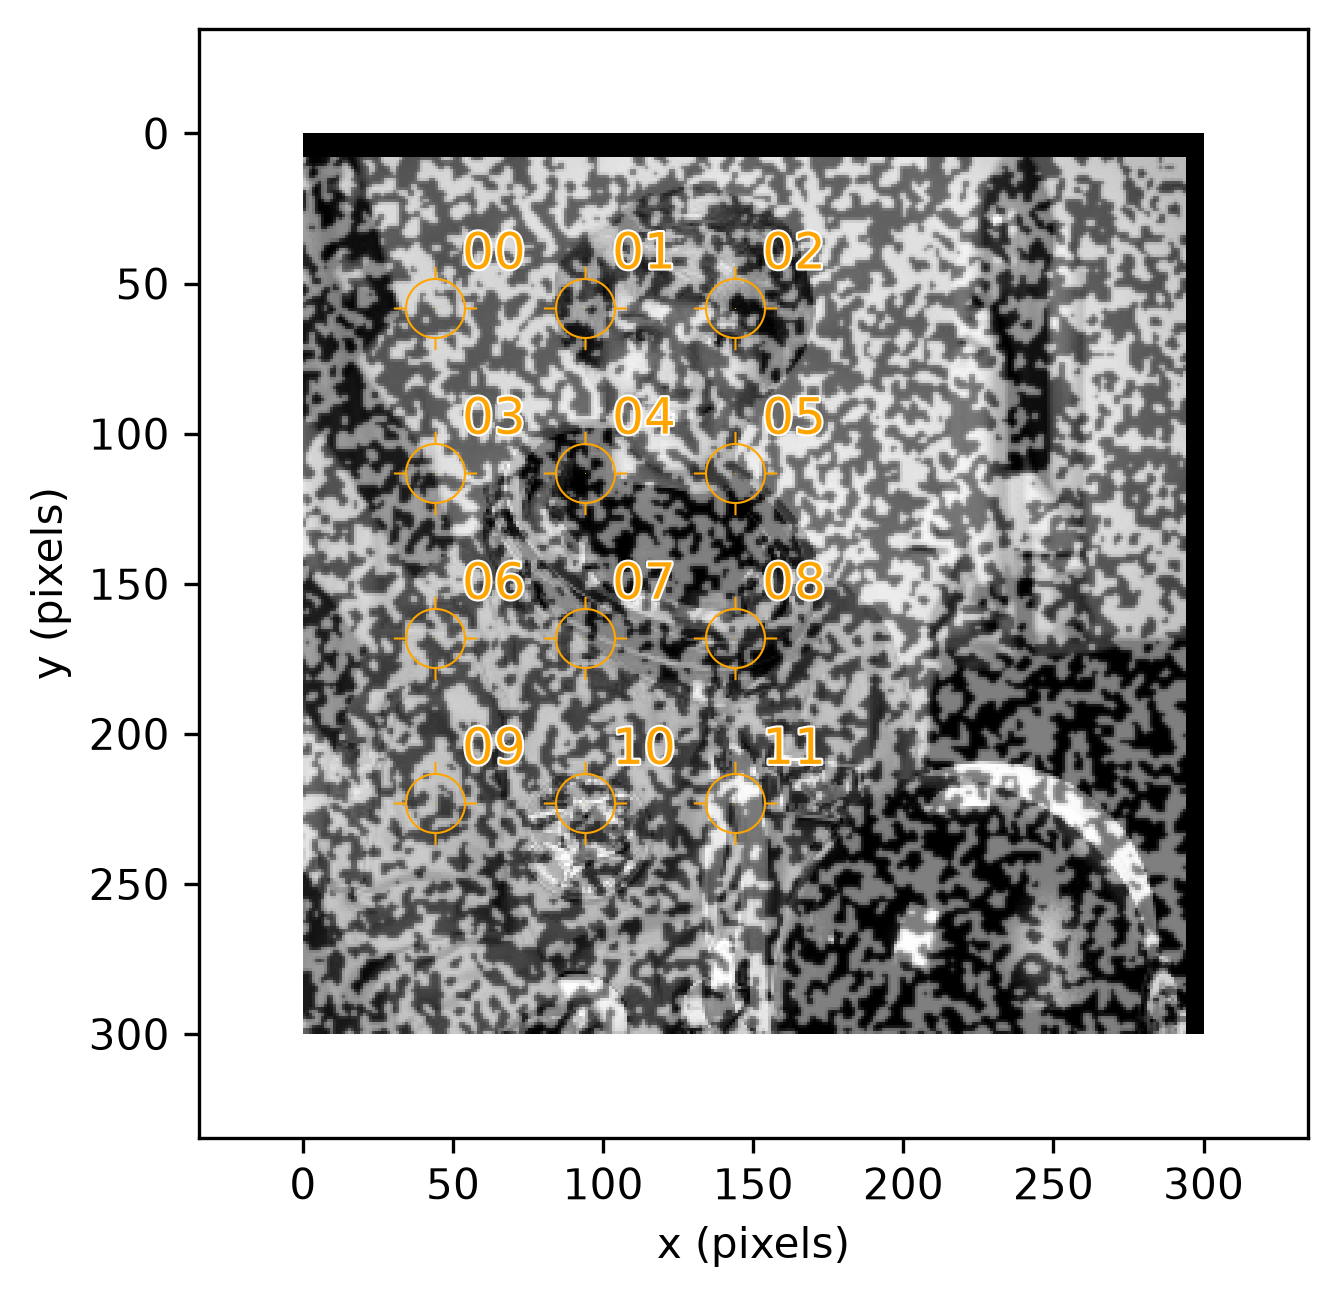
That every point was found exactly is expected, not a coincidence: the
kernel margins above were chosen to roughly follow the rule of thumb, not
to violate it. What the rule of thumb actually buys is robustness, not
correctness on an easy case like this one — a kernel needs enough
distinctive texture to locate reliably, and astronaut0 is a clean,
synthetic image with strong texture everywhere and no noise. A smaller,
more aggressively undersized kernel would likely still have worked here
too; it's on real, noisier imagery, or content with repetitive texture,
that a larger kernel's extra context resolves an ambiguity a smaller one
can't.
Data Download
Every image this page used is downloadable below, as a TIFF. Download files individually, or all at once: one compressed zip file bundles every full image (reference and current), every kernel, and every search area.
import zipfile
import imageio.v3 as iio

images = {"astronaut0.tiff": reference_image, "astronaut1.tiff": current_image}
for i, point in enumerate(points):
    origin = PixelCoordinate(x=point.x - kernel_margin, y=point.y - kernel_margin)
    images[f"kernel_{i:02d}.tiff"] = subimage(
        image=reference_image, origin=origin, width=2 * kernel_margin, height=2 * kernel_margin
    )
for i, point in enumerate(points):
    origin = PixelCoordinate(x=point.x - search_margin_width, y=point.y - search_margin_height)
    images[f"search_area_{i:02d}.tiff"] = subimage(
        image=current_image, origin=origin, width=2 * search_margin_width, height=2 * search_margin_height
    )

with zipfile.ZipFile("multi_point_motion_data.zip", "w", zipfile.ZIP_DEFLATED) as zf:
    for name, arr in images.items():
        zf.writestr(name, iio.imwrite("<bytes>", arr, extension=".tiff"))
Download all: multi_point_motion_data.zip (26 files, 291 KB)
Full Images
astronaut0.tiffisreference_image.astronaut1.tiffiscurrent_image—reference_imagedisplaced down and to the left by pixels, the same displacement Tracking the Grid tracked:
from dictk.image import write

write(arr=reference_image, path="astronaut0.tiff")
write(arr=current_image, path="astronaut1.tiff")
| File | Description |
|---|---|
| astronaut0.tiff | Reference image, 300x300 pixels |
| astronaut1.tiff | Current image, displaced by (dx, dy) = (-6, 8) pixels |
Kernels
Every point's kernel, extracted from reference_image — the same 12
boxes shown in Tracking the Grid (kernel_margin_width=20,
kernel_margin_height=20, 40x40 pixels each):
from dictk.image import subimage, write

kernel_margin = 20
for i, point in enumerate(points):
    origin = PixelCoordinate(x=point.x - kernel_margin, y=point.y - kernel_margin)
    kernel = subimage(image=reference_image, origin=origin, width=2 * kernel_margin, height=2 * kernel_margin)
    write(arr=kernel, path=f"kernel_{i:02d}.tiff")
| File | Point | Origin (pixels) |
|---|---|---|
| kernel_00.tiff | 00 | (30, 30) |
| kernel_01.tiff | 01 | (80, 30) |
| kernel_02.tiff | 02 | (130, 30) |
| kernel_03.tiff | 03 | (30, 85) |
| kernel_04.tiff | 04 | (80, 85) |
| kernel_05.tiff | 05 | (130, 85) |
| kernel_06.tiff | 06 | (30, 140) |
| kernel_07.tiff | 07 | (80, 140) |
| kernel_08.tiff | 08 | (130, 140) |
| kernel_09.tiff | 09 | (30, 195) |
| kernel_10.tiff | 10 | (80, 195) |
| kernel_11.tiff | 11 | (130, 195) |
Search Areas
Every point's search area, extracted from current_image — not
reference_image, since a search area is always a region of the current
image (see Tracking the Grid). The same 12 boxes shown there
(search_margin_width=48, search_margin_height=52, 96x104 pixels
each), still centered on each point's reference position:
search_margin_width, search_margin_height = 48, 52
for i, point in enumerate(points):
    origin = PixelCoordinate(x=point.x - search_margin_width, y=point.y - search_margin_height)
    search_area = subimage(image=current_image, origin=origin, width=2 * search_margin_width, height=2 * search_margin_height)
    write(arr=search_area, path=f"search_area_{i:02d}.tiff")
| File | Point | Origin (pixels) |
|---|---|---|
| search_area_00.tiff | 00 | (2, -2) |
| search_area_01.tiff | 01 | (52, -2) |
| search_area_02.tiff | 02 | (102, -2) |
| search_area_03.tiff | 03 | (2, 53) |
| search_area_04.tiff | 04 | (52, 53) |
| search_area_05.tiff | 05 | (102, 53) |
| search_area_06.tiff | 06 | (2, 108) |
| search_area_07.tiff | 07 | (52, 108) |
| search_area_08.tiff | 08 | (102, 108) |
| search_area_09.tiff | 09 | (2, 163) |
| search_area_10.tiff | 10 | (52, 163) |
| search_area_11.tiff | 11 | (102, 163) |
Verification Against VIC-2D
In this section, we run this page's own dx = -6, dy = 8 example through
VIC-2D (Correlated Solutions, Inc.),
a widely used commercial DIC package, to verify agreement with dictk.
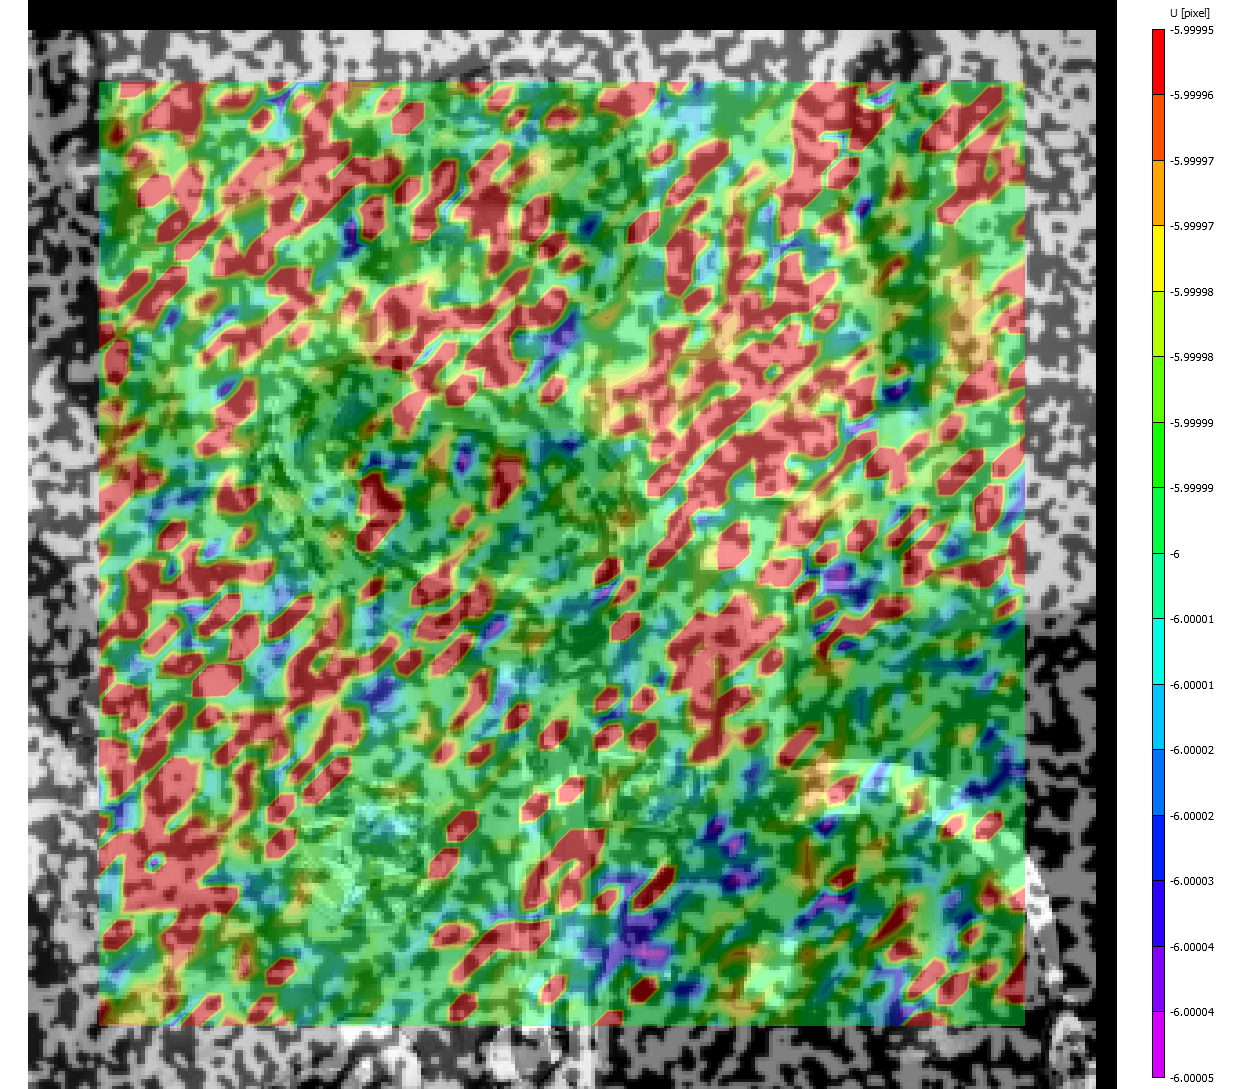
dx = -6, dy = 8 example (click either image for the full-size version): U, the x-axis displacement, uniformly -6 pixels (left, multi_point_motion_U); V, the y-axis displacement, uniformly -8 pixels (right, multi_point_motion_V) — VIC-2D's own -axis points opposite dictk's, so its sign is flipped from this page's dy = 8 even though both describe the identical physical motion.Across the 2861 subsets VIC-2D correlated successfully (109 more, all
along the image's outer edge, fell outside the shifted current image and
were masked out rather than reported), U ranges from exactly
to px and V from to px, in VIC-2D's own
columns (u_c/v_c in the raw output below). VIC-2D's own V
is measured with positive pointing up the page, opposite dictk's
downward-positive -axis. Once that sign difference is reconciled,
VIC-2D's result matches dictk's own / px ground truth exactly.
The full, subset-by-subset VIC-2D output,
multi_point_motion_vic_out.csv,
is available for closer inspection: every subset's position, displacement,
strain, and correlation quality metrics, not just the two summary fields
shown above. It carries two displacement column pairs: u_c/v_c
(VIC-2D's own convention, matching the two figures above exactly) and a
second u/v pair already expressed with v's sign flipped to match
dictk's downward-positive — u/v land on / px directly,
with no sign reconciliation needed to compare against dictk's ground
truth.
Next Steps
This page tracked rigid-body translation. Every point moved by the same amount. Simple Stretch is next. It tracks a stretching deformation, where each point moves by a different amount in the direction.
Simple Stretch
Multi-Point Motion tracked a grid of points under rigid-body translation — every point moves by the same , so Single Point Motion's known-integer-pixel trick (choosing so the ground truth is exact, not a sub-pixel estimate) carried over for free. A stretch is the next step up in complexity: a genuine deformation, not just a rigid shift, where different points move by different amounts. Getting the same exact-integer ground truth here takes more care.
dictk.image.stretch applies a uniaxial
or biaxial stretch pivoting at the image's origin : a point at moves to . Fixing
isolates the stretch to alone, so every point's
stays exactly as-is — the only question is which
values keep every point's new an integer too, rather than landing
between pixels.
Choosing an Integer-Safe Stretch Factor
Point Grid's 12 points span only three distinct values: 50, 100, and 150. Writing the stretch as a percentage , , and the new is:
For , this is just — always an integer, for any integer . But and both carry a factor of once divided by 100, so itself must be even for those points to land on an integer — which means must be even. Odd percentages (1%, 3%, 5%, ...) always leave and on a half-pixel.
That parity argument is exact in real-number math, but factor_x is a
64-bit float at runtime, and not every value that's mathematically an
integer survives that arithmetic unscathed — 1.1, for example, has no exact
binary floating-point representation, so 50 * 1.1 doesn't land on exactly
55.0 even though the true product is. Checking every even percentage
directly against dictk's actual points, rather than trusting the parity
argument alone:
from dictk.image import PixelCoordinate
from dictk.grid import generate

points = generate(
    origin=PixelCoordinate(x=50, y=50),
    count_x=3,
    count_y=4,
    spacing_x=50,
    spacing_y=55,
)
xs = sorted({point.x for point in points})

for p in range(1, 21):
    factor = (100 + p) / 100
    exact = all((x * factor).is_integer() for x in xs)
    print(f"{p:2d}%  factor={factor!r}  all-integer={exact}")
 1%  factor=1.01  all-integer=False
 2%  factor=1.02  all-integer=True
 3%  factor=1.03  all-integer=False
 4%  factor=1.04  all-integer=True
 5%  factor=1.05  all-integer=False
 6%  factor=1.06  all-integer=True
 7%  factor=1.07  all-integer=False
 8%  factor=1.08  all-integer=True
 9%  factor=1.09  all-integer=False
10%  factor=1.1  all-integer=False
11%  factor=1.11  all-integer=False
12%  factor=1.12  all-integer=False
13%  factor=1.13  all-integer=False
14%  factor=1.14  all-integer=False
15%  factor=1.15  all-integer=False
16%  factor=1.16  all-integer=False
17%  factor=1.17  all-integer=False
18%  factor=1.18  all-integer=True
19%  factor=1.19  all-integer=False
20%  factor=1.2  all-integer=True
The parity argument is necessary but not sufficient: every odd percentage
fails as predicted, but so do several even ones (10%, 12%, 14%, 16%) purely
from floating-point representation error, not the underlying math. Of the
percentages that survive both checks, 2% is the smallest — the least
aggressive stretch that still keeps every point's ground-truth position an
exact pixel, with factor_x = 1.02 giving new values of 51, 102, and
153.
Applying the Stretch
Reuse points and reference_image from Point
Grid.
dictk.image.stretch builds current_image:
from dictk.image import read, stretch, PixelCoordinate

reference_image = read(path="astronaut0.png")
factor_x = 1.02
current_image = stretch(arr=reference_image, factor_x=factor_x)
factor_y defaults to 1.0. Every point's stays fixed. Only
changes, and by a different amount for each point:
expected = [
    PixelCoordinate(x=int(point.x * factor_x), y=point.y)
    for point in points
]
| Point | Reference Configuration | Expected | ||
|---|---|---|---|---|
| (pixels) | (pixels) | (pixels) | (pixels) | |
| 00 | 50 | 50 | 51 | 50 |
| 01 | 100 | 50 | 102 | 50 |
| 02 | 150 | 50 | 153 | 50 |
| 03 | 50 | 105 | 51 | 105 |
| 04 | 100 | 105 | 102 | 105 |
| 05 | 150 | 105 | 153 | 105 |
| 06 | 50 | 160 | 51 | 160 |
| 07 | 100 | 160 | 102 | 160 |
| 08 | 150 | 160 | 153 | 160 |
| 09 | 50 | 215 | 51 | 215 |
| 10 | 100 | 215 | 102 | 215 |
| 11 | 150 | 215 | 153 | 215 |
This is a real deformation, not a rigid shift. Multi-Point Motion moved every point by the same . A stretch moves each point by a different amount. A point at moves 1 pixel. A point at moves 3 pixels. The grid spreads apart under the stretch. It does not translate as one block.
Locating the Stretched Grid
dictk.grid.locate tracks the stretched
grid the same way it tracked the translated one in Tracking the
Grid. Reuse the same kernel
and search-area margins:
from dictk.grid import locate

found = locate(
    reference_image=reference_image,
    current_image=current_image,
    reference_points=points,
    kernel_margin_width=20,
    kernel_margin_height=20,
    search_margin_width=48,
    search_margin_height=52,
)
Point  found        expected     match
00       51,50       51,50     True
01      102,50      102,50     True
02      153,50      153,50     True
03       51,105      51,105    True
04      102,105     102,105    True
05      153,105     153,105    True
06       51,160      51,160    True
07      102,160     102,160    True
08      153,160     153,160    True
09       51,215      51,215    True
10      102,215     102,215    True
11      153,215     153,215    True
from dictk.plot import point_grid_plot

point_grid_plot(
    image=current_image,
    points=found,
    color="orange",
    figsize=(6.4, 4.8),
    path="simple_stretch_current.png",
)
Saved: simple_stretch_current.png
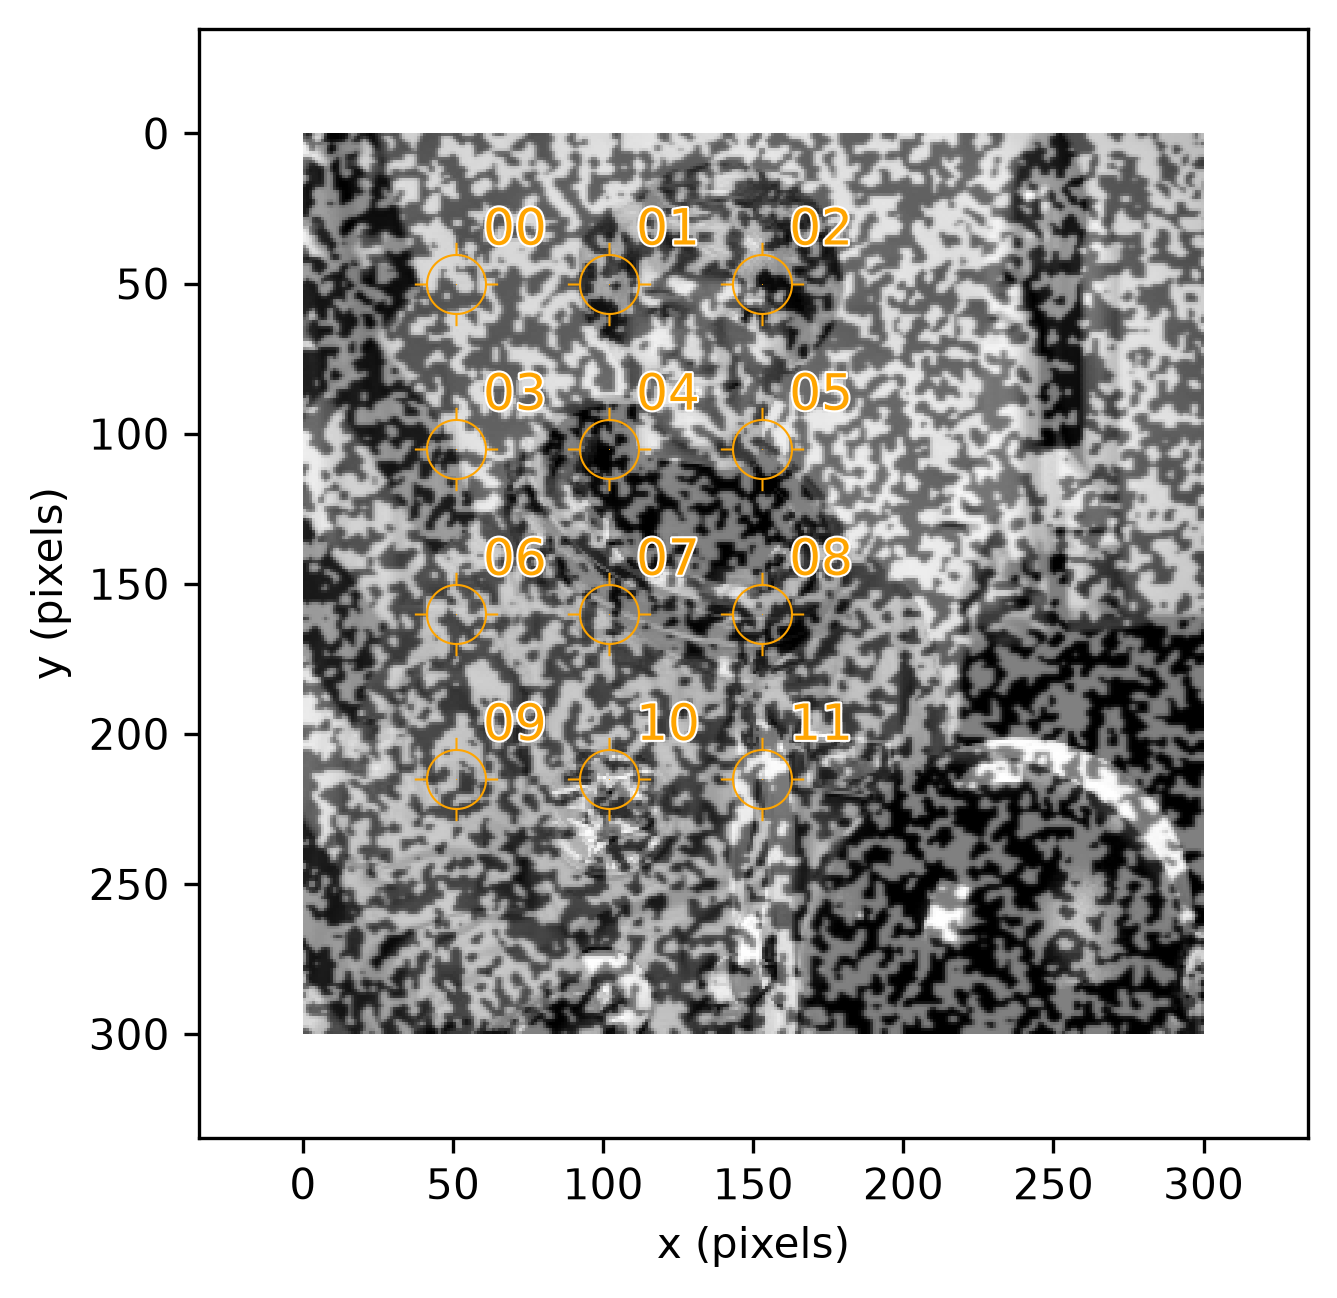
Every found position matches the expected stretched position exactly. The stretch introduces no sub-pixel error at these 12 points. Multi-Point Motion established this exact-integer guarantee for rigid translation. This page confirms it holds under a real deformation too.
Twelve points, twelve independent correlations, whether the underlying motion is a rigid shift or a stretch: Recoverable Displacement Range picks up from here.
Strain
Visualizing strain results is a combination of mathematical accuracy and visual clarity. One might want to plot the "raw" data at the Gauss points, since that is the location within the element where the FEA solver actually calculates strain, making it the most accurate. However, this manner of visualization causes jumps (discontinuities) at element boundaries.
The professional standard is to calculate strain at the Gauss points, extrapolate the results to the nodes, and then report the nodal average from all adjacent elements to create a smooth contour plot.
For now, let's report the strain at the Gauss points.
12-Point Sample
dictk.grid.elements turns the
tracked grid's 12 points into 6 Q4 elements, then
dictk.element.gauss_point_log_strains
and
dictk.element.gauss_point_coordinates
compute each element's 4 Gauss points' logarithmic (Hencky) strain and
their own global position, in the current (found) configuration.
Logarithmic strain, matching the Verification Against
VIC-2D section below, which reports
VIC-2D's own logarithmic/Euler strain:
from dictk.element import gauss_point_coordinates, gauss_point_log_strains
from dictk.grid import elements
from dictk.plot import element_strain_plot

element_indices = elements(count_x=3, count_y=4)
values = []
coordinates = []
for element in element_indices:
    reference_corners = [points[i] for i in element]
    current_corners = [found[i] for i in element]
    strains = gauss_point_log_strains(
        reference_points=reference_corners, current_points=current_corners
    )
    values.extend(strain[0, 0] for strain in strains)
    coordinates.extend(gauss_point_coordinates(points=current_corners))

element_strain_plot(
    points=found,
    elements=element_indices,
    coordinates=coordinates,
    values=values,
    label=r"Log Strain, $E_{11}$",
    show_node_numbers=True,
    path="simple_stretch_strain_gauss_points.png",
)
element_strain_plot(
    points=found,
    elements=element_indices,
    coordinates=coordinates,
    values=values,
    label=r"Log Strain, $E_{11}$",
    image=current_image,
    show_node_numbers=True,
    path="simple_stretch_strain_on_current.png",
)
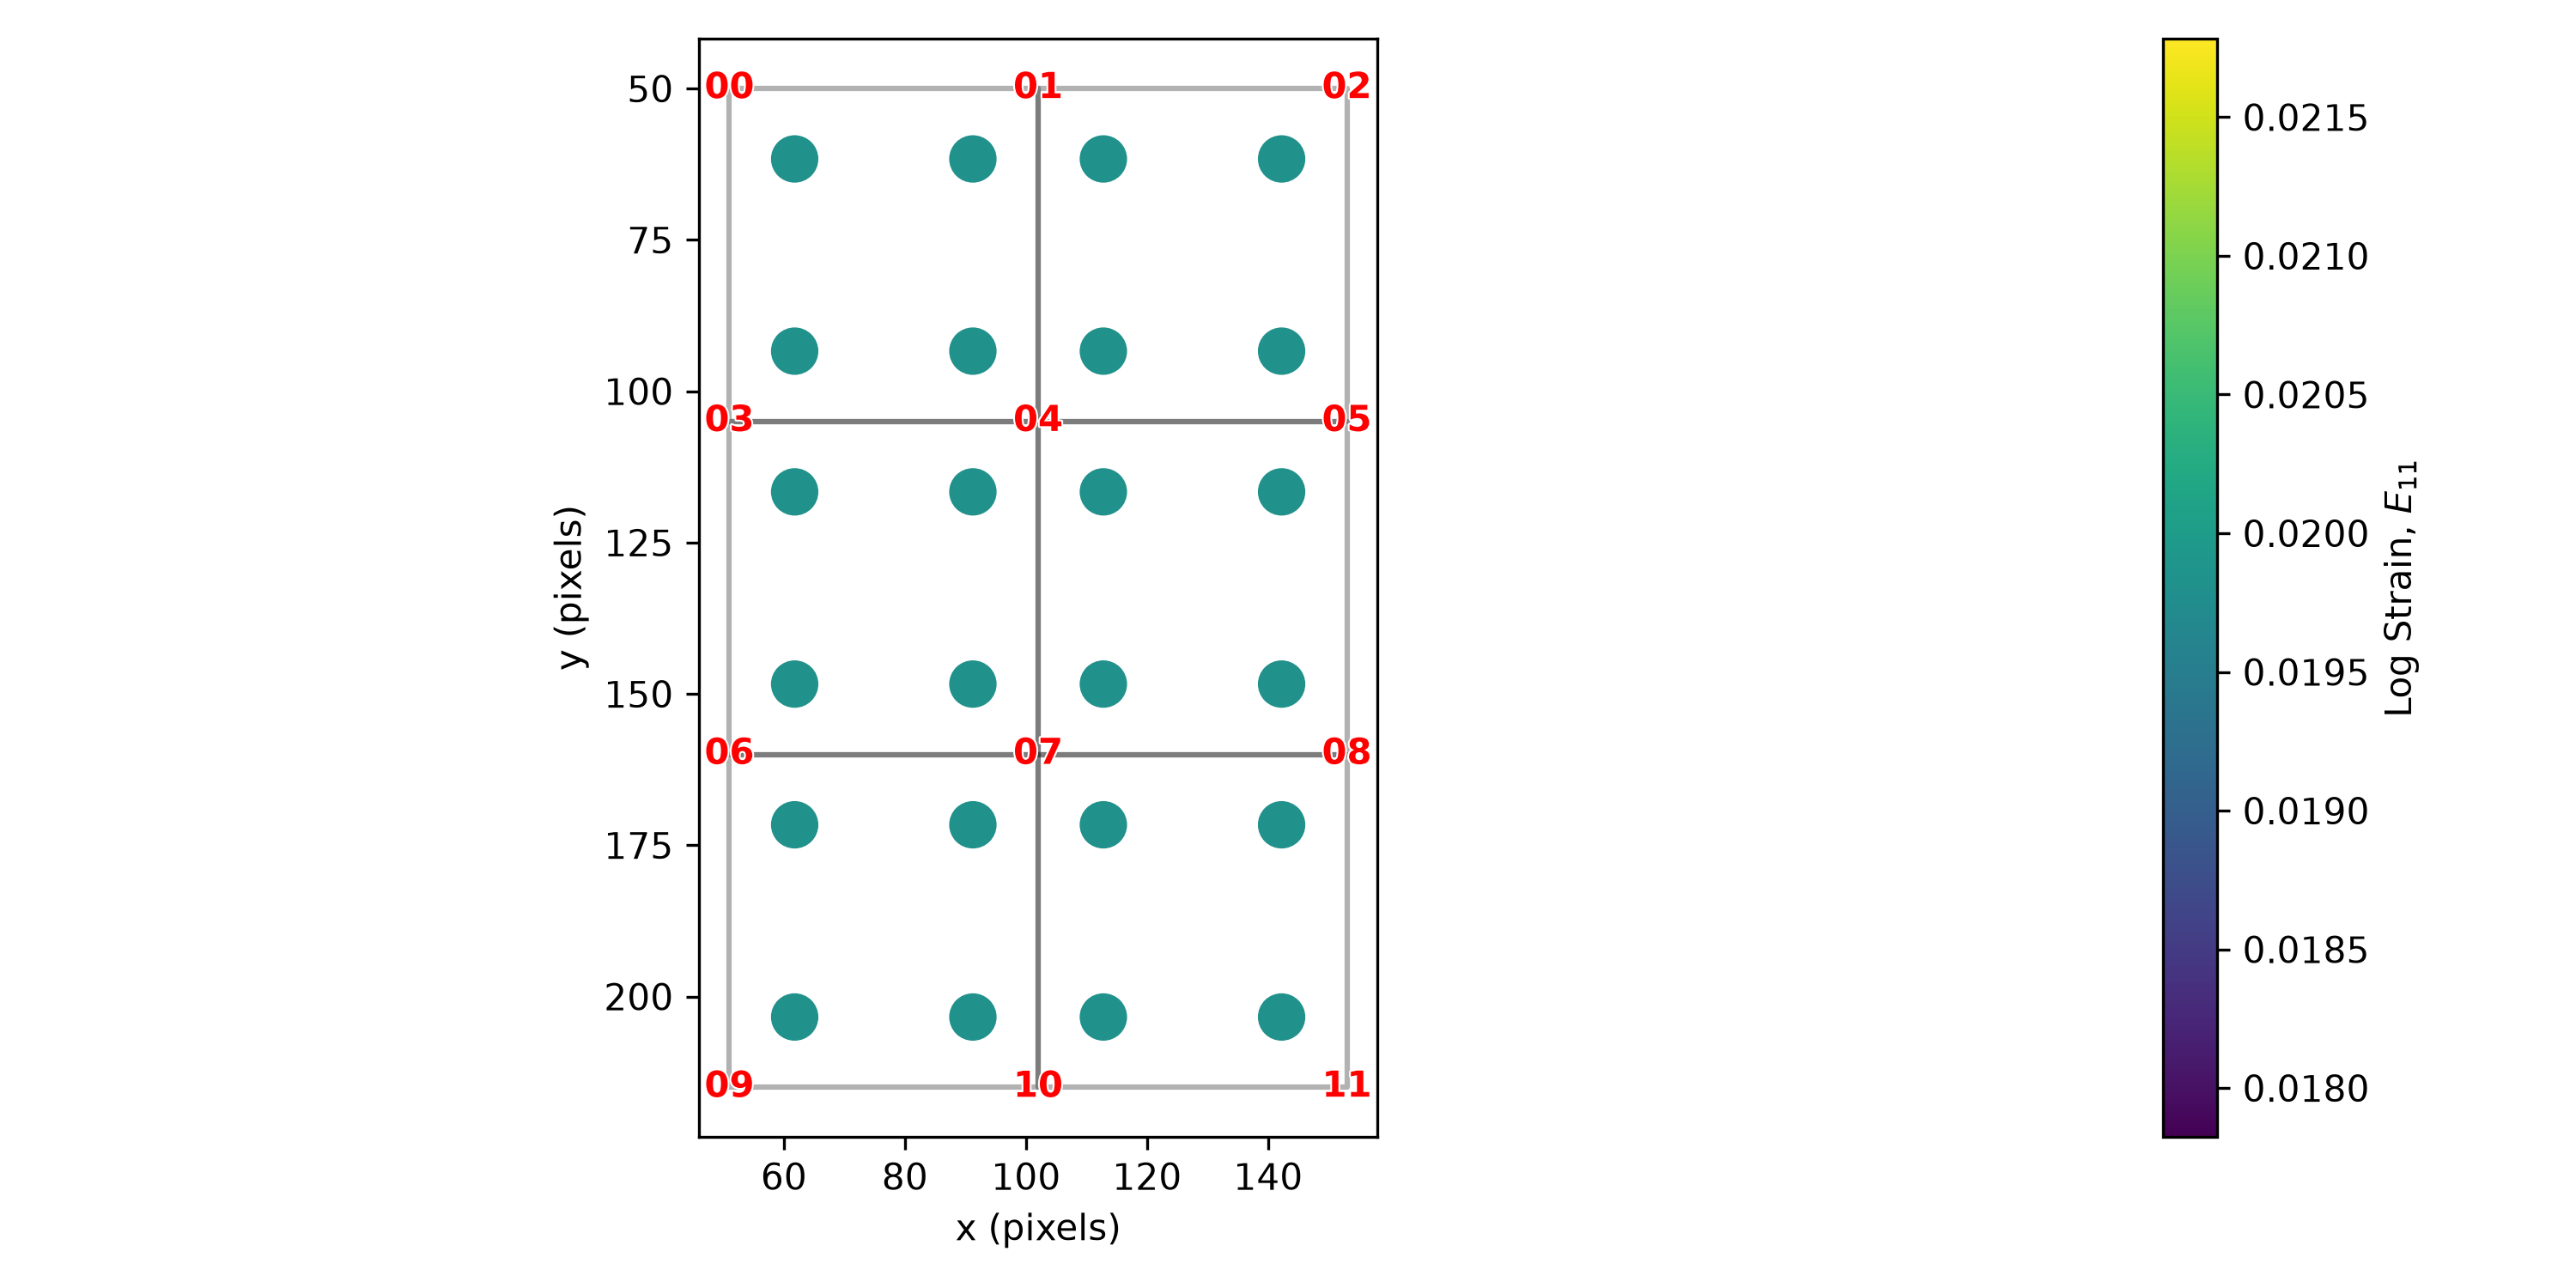
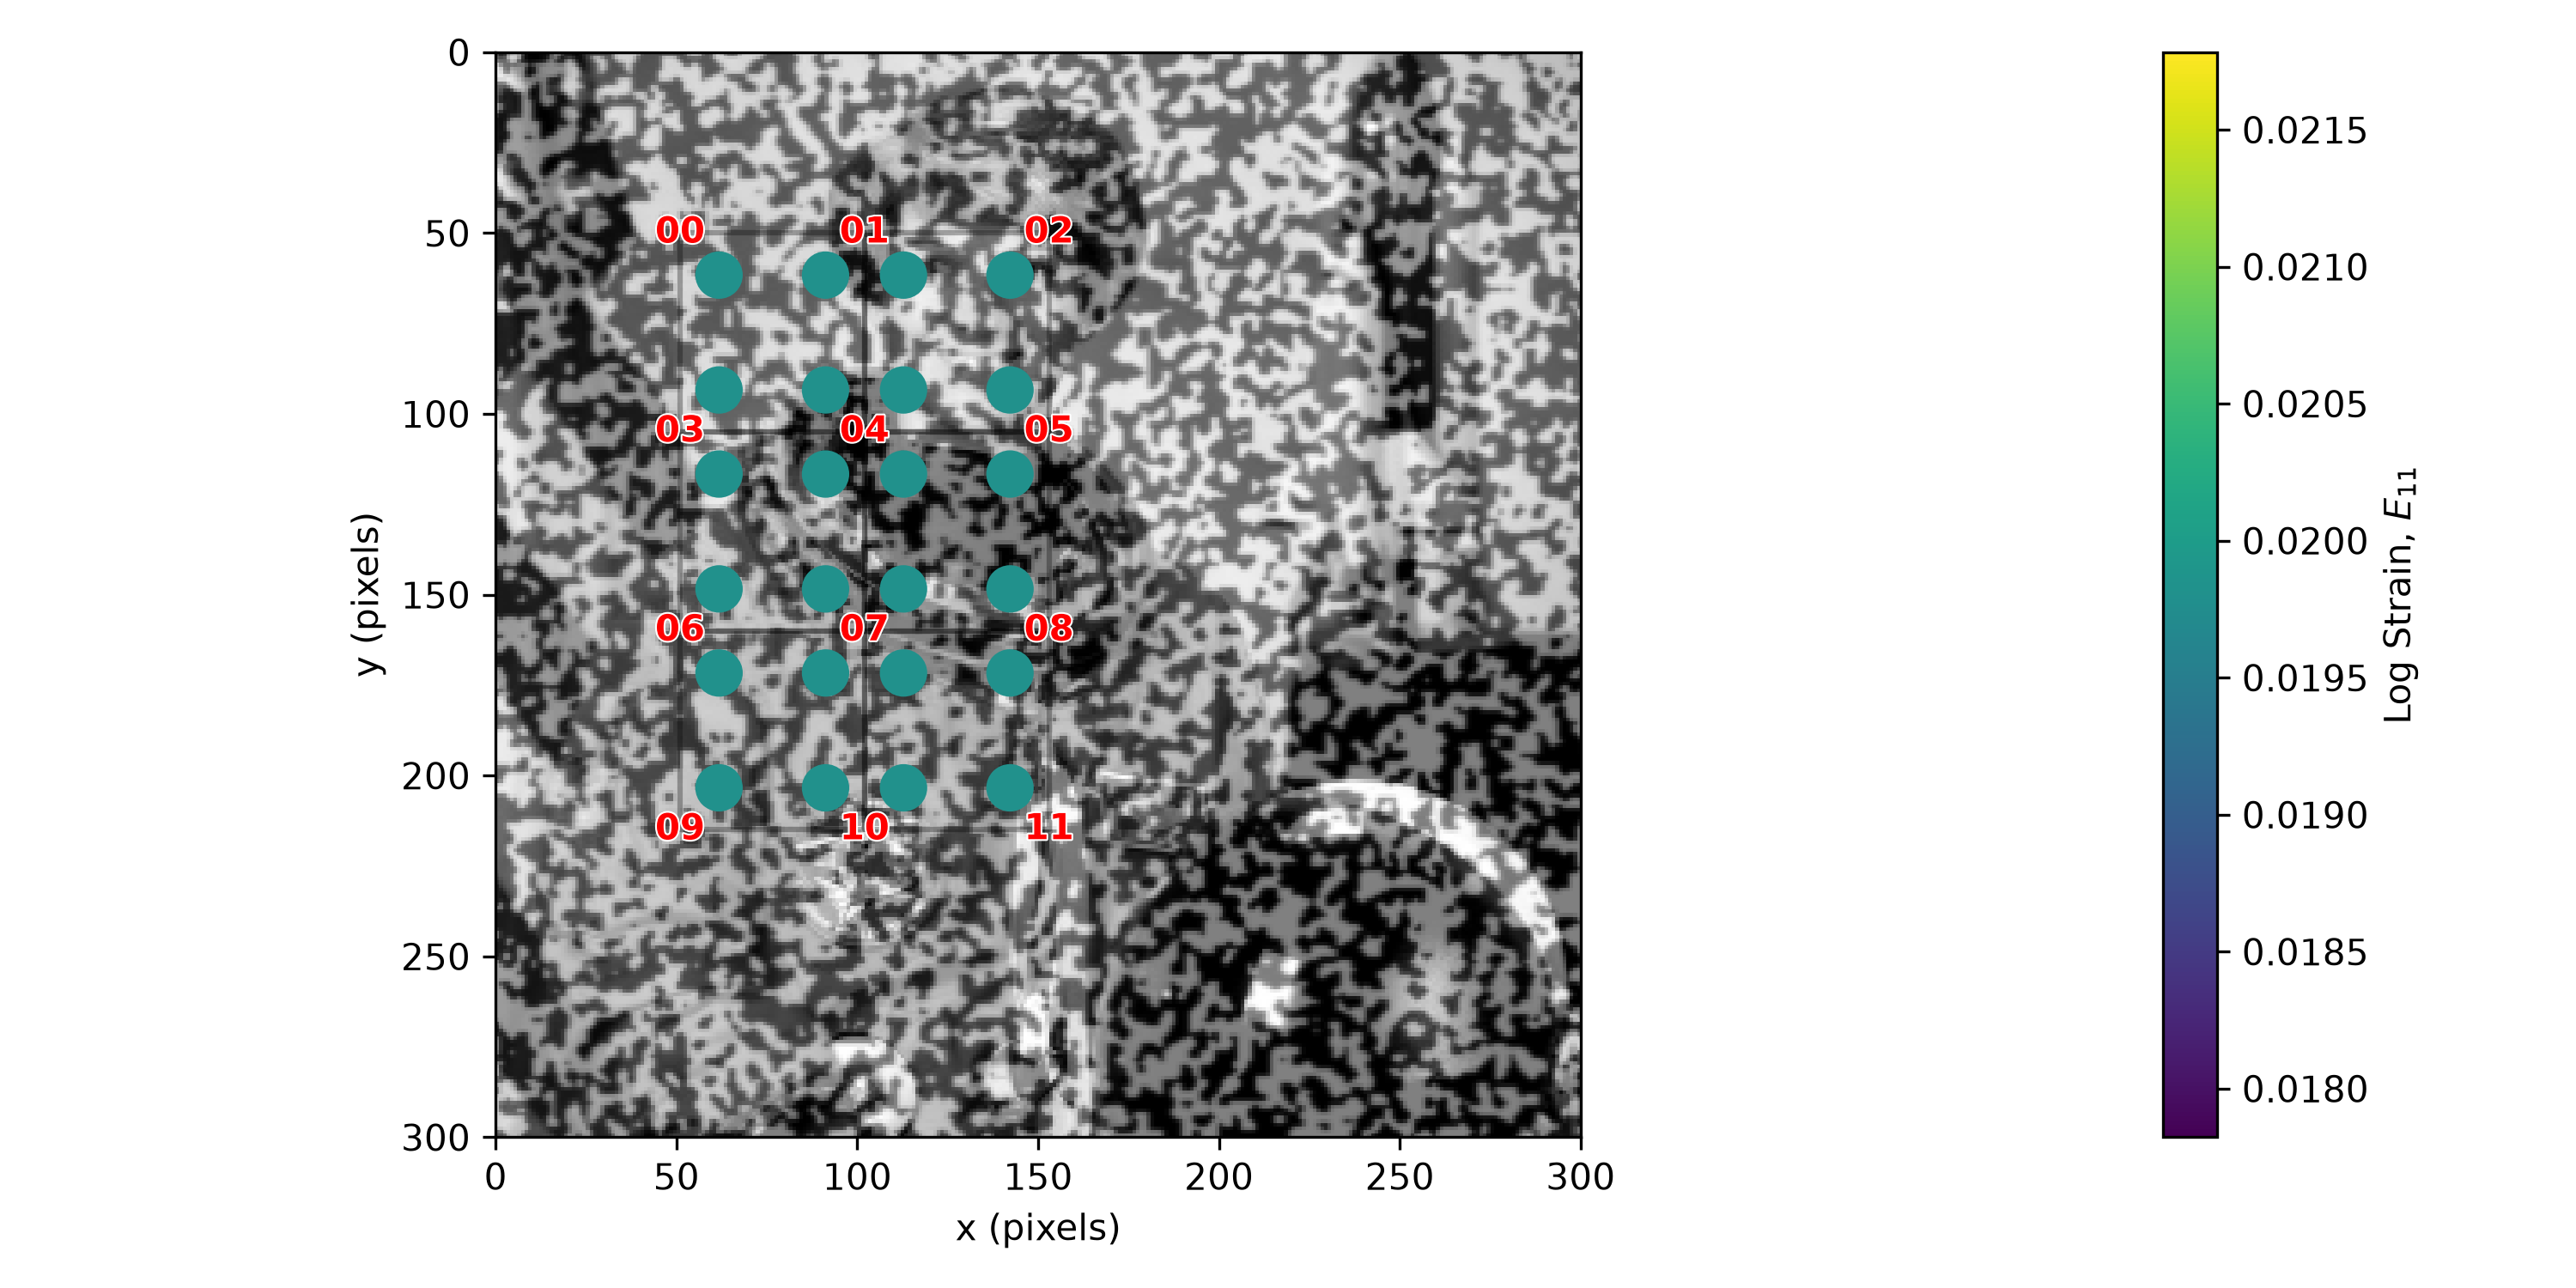
current_image.Strain Component: E11
----------------------------------------
Element 0 | GP (xi=-0.577, eta=-0.577) | E11: 1.980263e-02
Element 0 | GP (xi=+0.577, eta=-0.577) | E11: 1.980263e-02
Element 0 | GP (xi=+0.577, eta=+0.577) | E11: 1.980263e-02
Element 0 | GP (xi=-0.577, eta=+0.577) | E11: 1.980263e-02
Element 1 | GP (xi=-0.577, eta=-0.577) | E11: 1.980263e-02
Element 1 | GP (xi=+0.577, eta=-0.577) | E11: 1.980263e-02
Element 1 | GP (xi=+0.577, eta=+0.577) | E11: 1.980263e-02
Element 1 | GP (xi=-0.577, eta=+0.577) | E11: 1.980263e-02
Element 2 | GP (xi=-0.577, eta=-0.577) | E11: 1.980263e-02
Element 2 | GP (xi=+0.577, eta=-0.577) | E11: 1.980263e-02
Element 2 | GP (xi=+0.577, eta=+0.577) | E11: 1.980263e-02
Element 2 | GP (xi=-0.577, eta=+0.577) | E11: 1.980263e-02
Element 3 | GP (xi=-0.577, eta=-0.577) | E11: 1.980263e-02
Element 3 | GP (xi=+0.577, eta=-0.577) | E11: 1.980263e-02
Element 3 | GP (xi=+0.577, eta=+0.577) | E11: 1.980263e-02
Element 3 | GP (xi=-0.577, eta=+0.577) | E11: 1.980263e-02
Element 4 | GP (xi=-0.577, eta=-0.577) | E11: 1.980263e-02
Element 4 | GP (xi=+0.577, eta=-0.577) | E11: 1.980263e-02
Element 4 | GP (xi=+0.577, eta=+0.577) | E11: 1.980263e-02
Element 4 | GP (xi=-0.577, eta=+0.577) | E11: 1.980263e-02
Element 5 | GP (xi=-0.577, eta=-0.577) | E11: 1.980263e-02
Element 5 | GP (xi=+0.577, eta=-0.577) | E11: 1.980263e-02
Element 5 | GP (xi=+0.577, eta=+0.577) | E11: 1.980263e-02
Element 5 | GP (xi=-0.577, eta=+0.577) | E11: 1.980263e-02
----------------------------------------
All 24 Gauss points report the identical value,
— expected here, since factor_x = 1.02 is a uniform, axis-aligned
stretch, a globally affine map that Q4's bilinear interpolation
reproduces exactly everywhere, not just at element corners. In the
general case, where the deformation isn't perfectly uniform, each Gauss
point's strain would differ.
Data Download
Every image this page used is downloadable below, as a TIFF. Download files individually, or all at once: one compressed zip file bundles every full image (reference and current), every kernel, and every search area.
import zipfile
import imageio.v3 as iio

images = {"astronaut0.tiff": reference_image, "astronaut2.tiff": current_image}
for i, point in enumerate(points):
    origin = PixelCoordinate(x=point.x - kernel_margin, y=point.y - kernel_margin)
    images[f"kernel_{i:02d}.tiff"] = subimage(
        image=reference_image, origin=origin, width=2 * kernel_margin, height=2 * kernel_margin
    )
for i, point in enumerate(points):
    origin = PixelCoordinate(x=point.x - search_margin_width, y=point.y - search_margin_height)
    images[f"search_area_stretch_{i:02d}.tiff"] = subimage(
        image=current_image, origin=origin, width=2 * search_margin_width, height=2 * search_margin_height
    )

with zipfile.ZipFile("simple_stretch_data.zip", "w", zipfile.ZIP_DEFLATED) as zf:
    for name, arr in images.items():
        zf.writestr(name, iio.imwrite("<bytes>", arr, extension=".tiff"))
Download all: simple_stretch_data.zip (26 files, 299 KB)
Full Images
astronaut0.tiff is reference_image — identical to Multi-Point
Motion's copy, since both pages
reuse the same reference image. astronaut2.tiff is current_image,
stretched by factor_x=1.02 — named astronaut2, not astronaut1, to
stay distinct from Multi-Point Motion's translated current image,
which is a different file with different content:
from dictk.image import write

write(arr=reference_image, path="astronaut0.tiff")
write(arr=current_image, path="astronaut2.tiff")
| File | Description |
|---|---|
| astronaut0.tiff | Reference image, 300x300 pixels (same as Multi-Point Motion) |
| astronaut2.tiff | Current image, stretched by factor_x=1.02 |
Kernels
Kernels are unchanged from Multi-Point
Motion: the stretch only ever moves
current_image, and a kernel always comes from reference_image.
Regenerated here, byte-for-byte identical, for a self-contained download
set:
from dictk.image import subimage, write

kernel_margin = 20
for i, point in enumerate(points):
    origin = PixelCoordinate(x=point.x - kernel_margin, y=point.y - kernel_margin)
    kernel = subimage(image=reference_image, origin=origin, width=2 * kernel_margin, height=2 * kernel_margin)
    write(arr=kernel, path=f"kernel_{i:02d}.tiff")
| File | Point | Origin (pixels) |
|---|---|---|
| kernel_00.tiff | 00 | (30, 30) |
| kernel_01.tiff | 01 | (80, 30) |
| kernel_02.tiff | 02 | (130, 30) |
| kernel_03.tiff | 03 | (30, 85) |
| kernel_04.tiff | 04 | (80, 85) |
| kernel_05.tiff | 05 | (130, 85) |
| kernel_06.tiff | 06 | (30, 140) |
| kernel_07.tiff | 07 | (80, 140) |
| kernel_08.tiff | 08 | (130, 140) |
| kernel_09.tiff | 09 | (30, 195) |
| kernel_10.tiff | 10 | (80, 195) |
| kernel_11.tiff | 11 | (130, 195) |
Search Areas
Search areas, unlike kernels, are different from Multi-Point Motion's:
they come from this page's current_image — the stretched one, not the
translated one. Named search_area_stretch_* to keep the two sets of
files distinct, still centered on each point's reference position:
search_margin_width, search_margin_height = 48, 52
for i, point in enumerate(points):
    origin = PixelCoordinate(x=point.x - search_margin_width, y=point.y - search_margin_height)
    search_area = subimage(image=current_image, origin=origin, width=2 * search_margin_width, height=2 * search_margin_height)
    write(arr=search_area, path=f"search_area_stretch_{i:02d}.tiff")
| File | Point | Origin (pixels) |
|---|---|---|
| search_area_stretch_00.tiff | 00 | (2, -2) |
| search_area_stretch_01.tiff | 01 | (52, -2) |
| search_area_stretch_02.tiff | 02 | (102, -2) |
| search_area_stretch_03.tiff | 03 | (2, 53) |
| search_area_stretch_04.tiff | 04 | (52, 53) |
| search_area_stretch_05.tiff | 05 | (102, 53) |
| search_area_stretch_06.tiff | 06 | (2, 108) |
| search_area_stretch_07.tiff | 07 | (52, 108) |
| search_area_stretch_08.tiff | 08 | (102, 108) |
| search_area_stretch_09.tiff | 09 | (2, 163) |
| search_area_stretch_10.tiff | 10 | (52, 163) |
| search_area_stretch_11.tiff | 11 | (102, 163) |
Verification Against VIC-2D
Path Forward names a direction worth
pursuing: running this book's own synthetic datasets through established
DIC software, and comparing directly against dictk's own results. This
page's own factor_x = 1.02 stretch was run through
VIC-2D (Correlated
Solutions, Inc.), independently of dictk.
2682-Point Sample
VIC-2D placed its own kernels (each kernel sized 25 x 25 px) on a regular grid,
5 pixels apart in both
directions — 53x54, 2862 candidate positions across the image. 180 of
them sit close enough to the image's outer edge that their own
correlation window would run off-canvas, so VIC-2D masks those out,
leaving 2682 valid subsets.
from dictk.image import read, PixelCoordinate
from dictk.grid import generate
from dictk.plot import point_grid_plot

reference_image = read(path="astronaut0.png")
points = generate(
    origin=PixelCoordinate(x=18, y=16), count_x=53, count_y=54, spacing_x=5, spacing_y=5
)

# Marks exactly the region the zoomed-in figure below crops to -- same
# center and radius drawn there too, where it exactly touches all four
# edges of that figure's own extent.
crop_origin = PixelCoordinate(x=10, y=8)
crop_width, crop_height = 30, 30
circle_center = PixelCoordinate(
    x=crop_origin.x + crop_width // 2, y=crop_origin.y + crop_height // 2
)
circle_radius = crop_width / 2

point_grid_plot(
    image=reference_image,
    points=points,
    color="orange",
    show_node_numbers=False,
    dot_size=0.8,
    circle_center=circle_center,
    circle_radius=circle_radius,
    circle_linewidth=0.8,
    path="simple_stretch_2862_overview.png",
)
Saved: simple_stretch_2862_overview.png
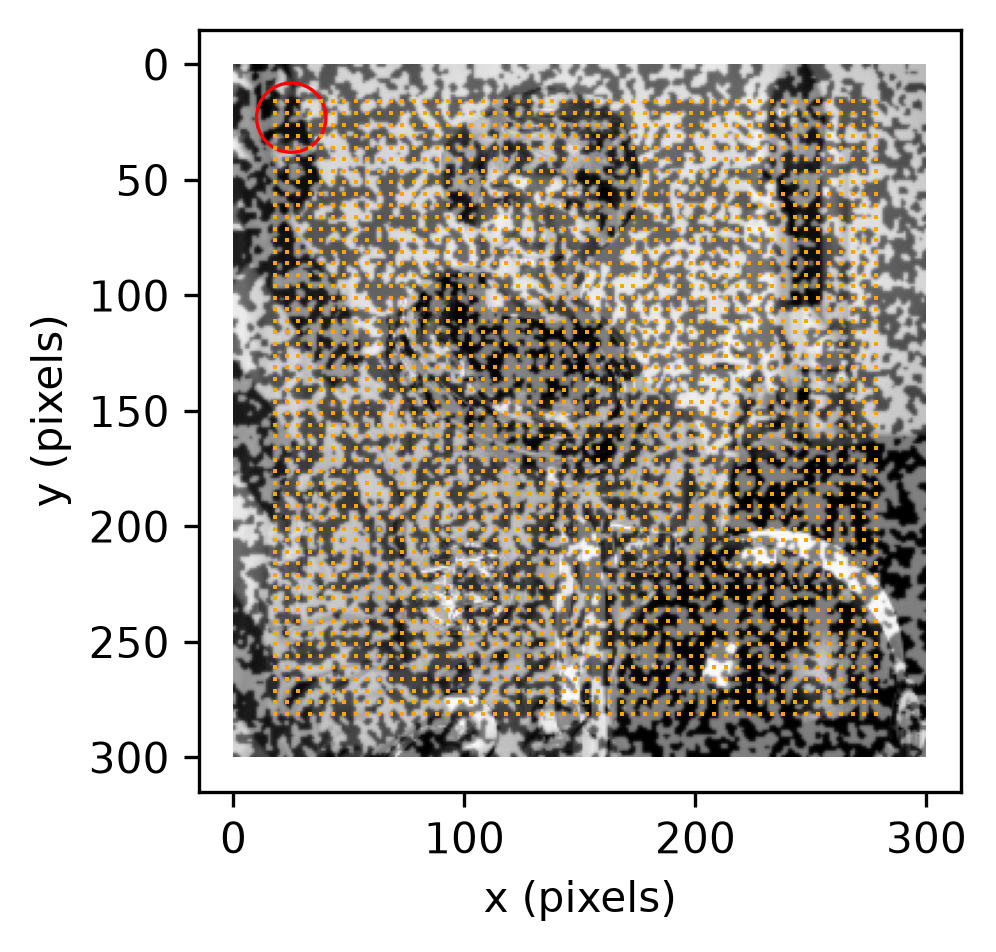
A zoomed-in corner shows the same 5px grid at true scale, the same red circle now exactly touching all four edges of the crop:
from dictk.image import read, PixelCoordinate, subimage
from dictk.grid import generate
from dictk.plot import point_grid_plot

reference_image = read(path="astronaut0.png")
points = generate(
    origin=PixelCoordinate(x=18, y=16), count_x=53, count_y=54, spacing_x=5, spacing_y=5
)

crop_origin = PixelCoordinate(x=10, y=8)
crop_width, crop_height = 30, 30
circle_center = PixelCoordinate(
    x=crop_origin.x + crop_width // 2, y=crop_origin.y + crop_height // 2
)
circle_radius = crop_width / 2

cropped = subimage(
    image=reference_image, origin=crop_origin, width=crop_width, height=crop_height
)
# points stays in the full image's own frame -- origin=crop_origin tells
# point_grid_plot where cropped sits within it, so the saved figure's
# axes read astronaut0's own pixel numbers, not the crop's local 0-based
# ones. The same point (and the same circle) reads identically here and
# in the overview above.
sample_points = [
    p
    for p in points
    if crop_origin.x <= p.x < crop_origin.x + crop_width
    and crop_origin.y <= p.y < crop_origin.y + crop_height
]
point_grid_plot(
    image=cropped,
    points=sample_points,
    origin=crop_origin,
    color="orange",
    show_node_numbers=False,
    dot_size=6,
    circle_center=circle_center,
    circle_radius=circle_radius,
    circle_linewidth=0.8,
    figsize=(4, 4),
    path="simple_stretch_2862_zoom.png",
)
Saved: simple_stretch_2862_zoom.png
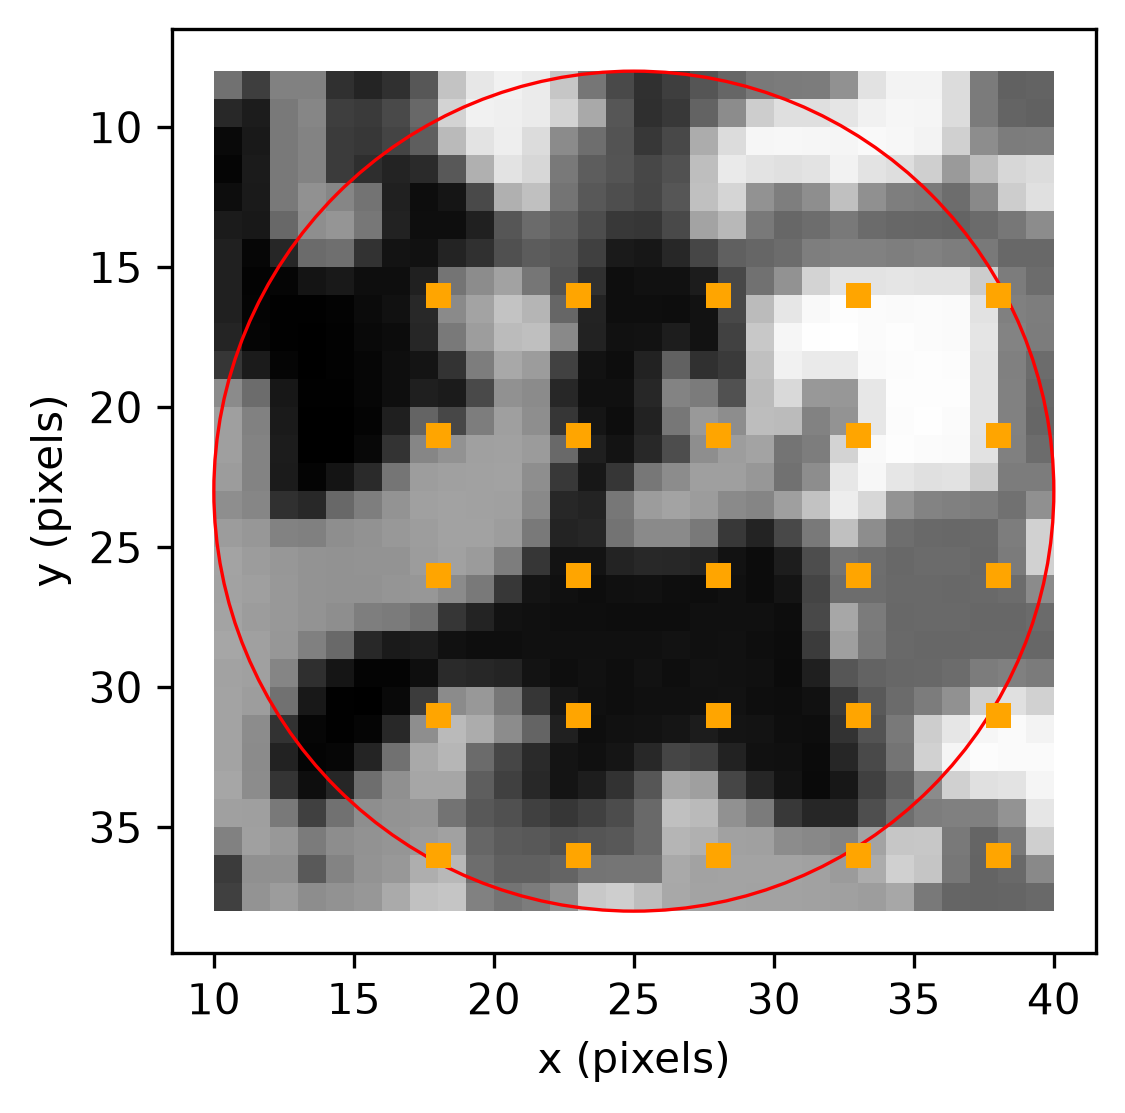
astronaut0's own pixel coordinates, not the crop's local 0-based ones, so a point here reads identically in the overview above -- e.g. the top-left point is (18, 16) in both figures. The same red circle marked in the overview above appears here too, now exactly touching all four edges of this figure's own extent -- the same visual correspondence Correlation Visualization's Solution Vicinity panel uses.VIC-2D reports logarithmic (Euler) strain, so it's compared here
against the Strain section above's own dictk-computed log
strain. Across those 2682 valid subsets, averages
19875.8 microstrain — close to, but noisier than,
Multi-Point Motion's
displacement match, since strain is a spatial derivative of already-noisy
per-point displacement data, not a directly measured quantity:
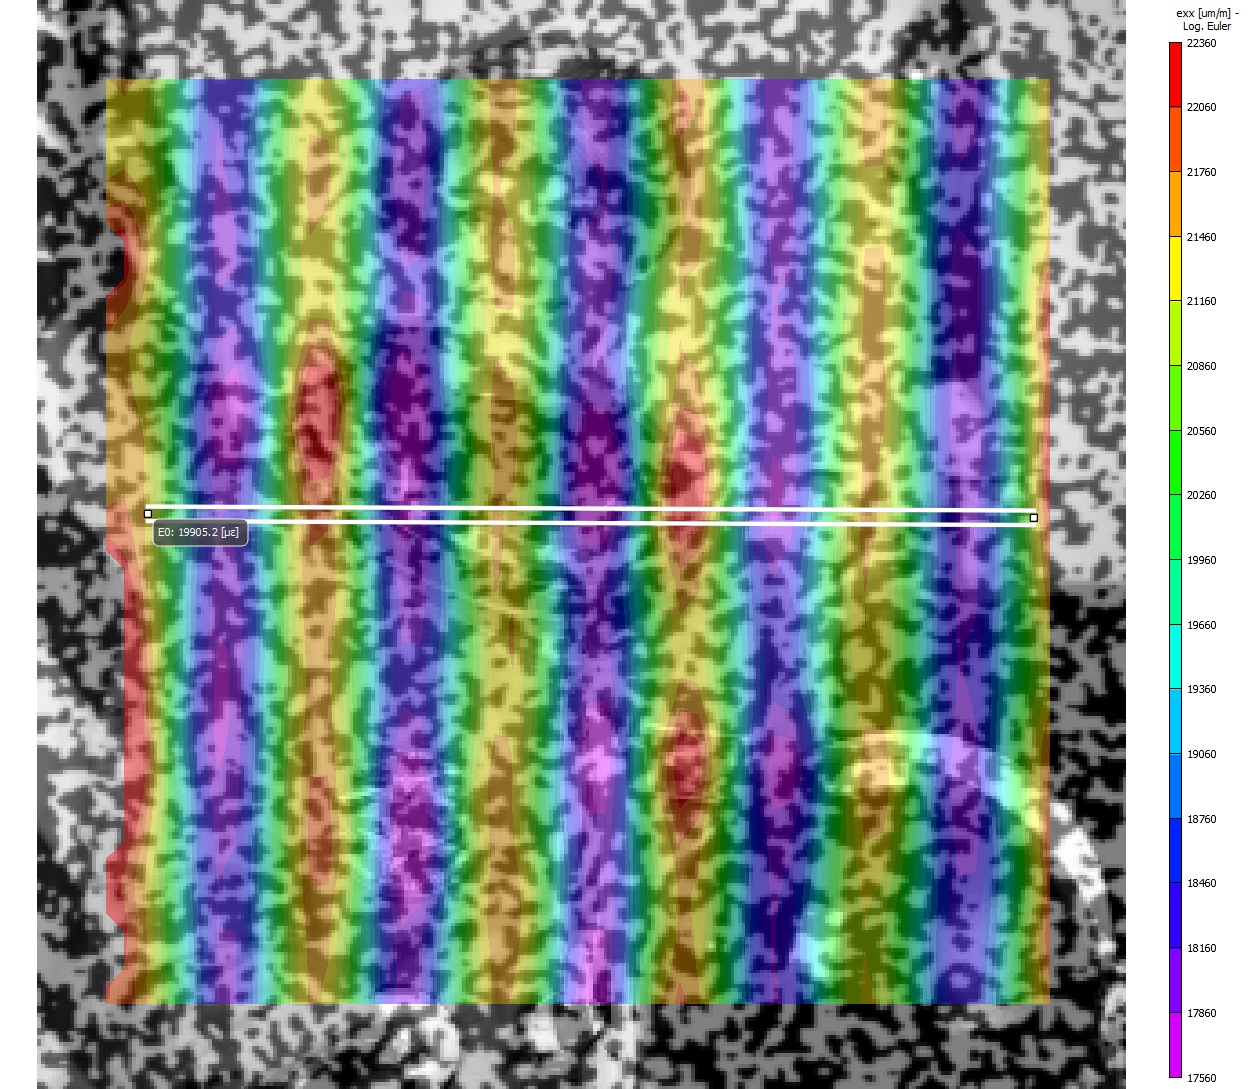
factor_x = 1.02 stretch (click to enlarge). The horizontal line is VIC-2D's own extensometer annotation, reading 19905.2 microstrain along that path.The full distribution, not just its mean, shows how noisy those 2682 subsets really are:
import csv
import numpy as np
import matplotlib.pyplot as plt

with open("../verification/simple_stretch_vic_out.csv") as f:
    rows = [{k.strip(' "'): v for k, v in row.items()} for row in csv.DictReader(f)]
exx = np.array([float(r["exx"]) * 1e6 for r in rows if float(r["sigma"]) != -1])
analytical = np.log(1.02) * 1e6

plt.rcParams.update({"font.family": "serif", "mathtext.fontset": "cm"})
fig, ax = plt.subplots(figsize=(7, 4), constrained_layout=True)
ax.hist(exx, bins=60, color="gray", alpha=0.8)
ax.axvline(analytical, color="red", linestyle="--", linewidth=1.5)
ax.set_xlabel(r"Log strain $e_{xx}$ (microstrain)")
ax.set_ylabel("frequency")
fig.savefig("simple_stretch_vic_exx_histogram.png", dpi=300)
Saved: simple_stretch_vic_exx_histogram.png
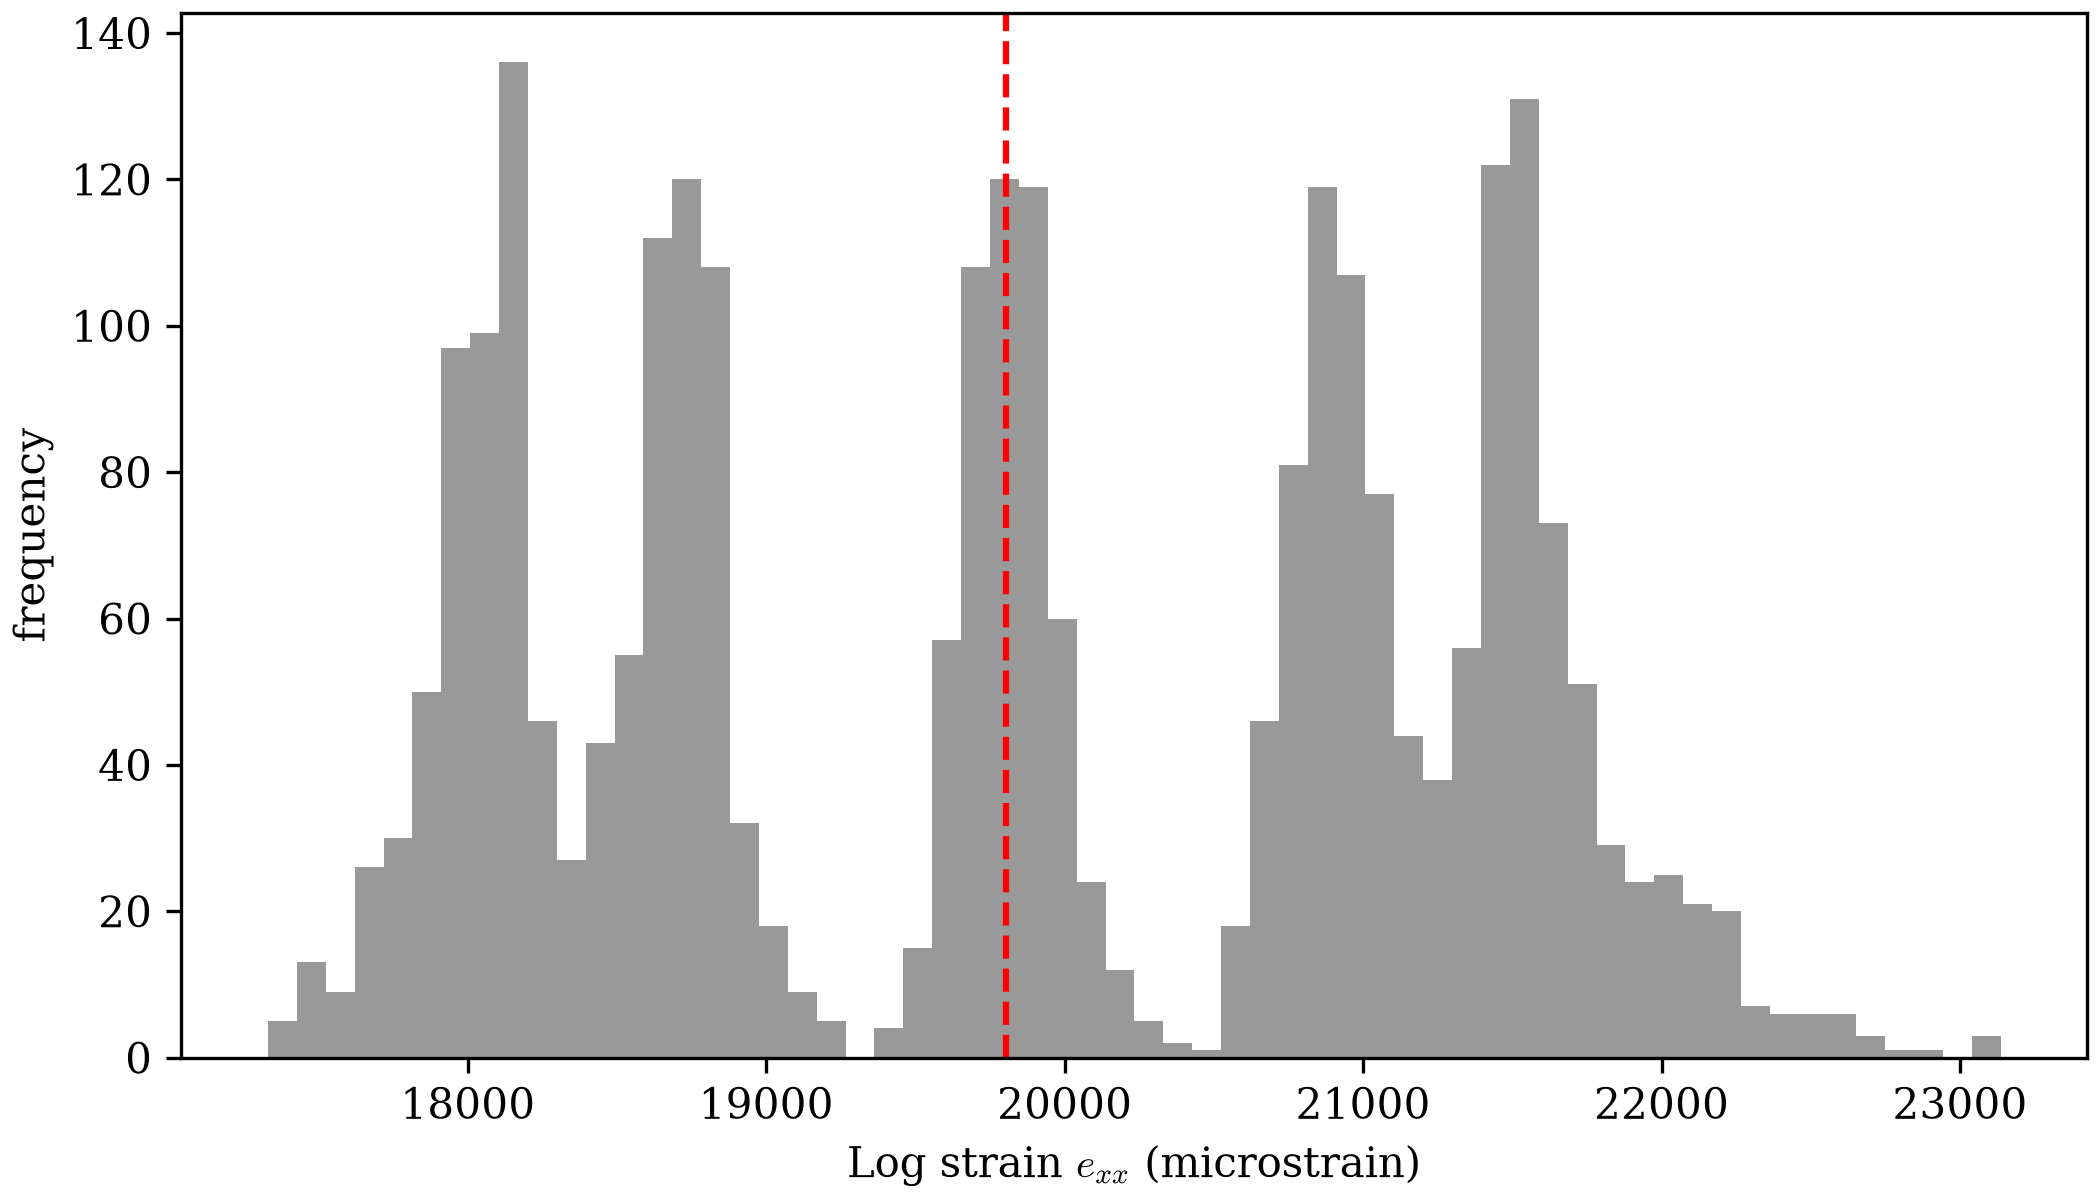
Three values agree closely: VIC-2D's own measured mean, 19875.8
microstrain; dictk's own computed from the Strain section
above, 19803.0 microstrain (identical at all 24 Gauss points, since
this page's stretch is exact and uniform); and the analytical
logarithmic (true/Euler) strain a factor_x = 1.02 stretch implies,
microstrain.
dictk's own value lands within 0.02% of the analytical one — it's
derived from the exact-integer tracked positions established earlier
on this page, not a separately measured quantity, so it agrees almost
exactly. VIC-2D's own mean, measured from real correlated subsets
rather than exact tracked points, lands within 0.4% of the same
analytical value.
The full, subset-by-subset VIC-2D output —
simple_stretch_vic_out.csv
— is available for closer inspection: every subset's position,
displacement, strain, and correlation quality metrics, not just the
summary field shown above.
VIC-2D sampled this deformation at far higher density than dictk
has tried. Simple Stretch Revisited takes
that cue next, pushing dictk's own tracked grid past twelve points
for the first time.
Simple Stretch Revisited
Every point tracked so far on this page has landed on an exact integer pixel in the deformed configuration. That only works because of how the 12-point grid's own values were chosen. is . A point's stretched only comes out as a whole number when itself is a multiple of 50 — , exactly, but , not exactly. The grid's three distinct values, 50, 100, and 150, are all multiples of 50. That's not a coincidence — it's the same integer-safety check Choosing an Integer-Safe Stretch Factor already ran, just not stated in exactly these terms yet.
A much denser grid doesn't automatically keep that property. Spacing points 5 pixels apart, matching VIC-2D's own subset grid, mostly lands on values that aren't multiples of 50 — most of those points' true stretched position isn't an integer at all, so nothing can land on it exactly, no matter how the tracking works.
250-Point Sample
has no such restriction — every stays fixed,
so spacing is free. That leaves one real lever: keep restricted
to multiples of 50, and pack the direction as densely as space
allows. Within this image, — 5
values, still 50 pixels apart, and (with search_margin_width=48) all
comfortably clear of the image's own edges. A much larger, still fully
integer-safe grid follows directly:
from dictk.grid import generate

points = generate(
    origin=PixelCoordinate(x=50, y=52),
    count_x=5,
    count_y=50,
    spacing_x=50,
    spacing_y=4,
)
250 points, x values: [50, 100, 150, 200, 250], y range: 52-248
Tracked the same way as every other grid on this page:
from dictk.grid import locate

found = locate(
    reference_image=reference_image,
    current_image=current_image,
    reference_points=points,
    kernel_margin_width=20,
    kernel_margin_height=20,
    search_margin_width=48,
    search_margin_height=52,
)
250/250 points land on their expected integer pixel exactly
Every one of them lands exactly, the same as the 12-point grid — this grid is 20x larger, entirely by choosing values that stay integer-safe, not by luck.
Strain follows the same recipe as the Strain section above:
dictk.grid.elements for
connectivity, then
dictk.element.gauss_point_log_strains
and
dictk.element.gauss_point_coordinates
at each of the resulting 196 elements' Gauss points. Node numbers are
left off this time — 250 labels would be clutter, not information, at
this density:
from dictk.element import gauss_point_coordinates, gauss_point_log_strains
from dictk.grid import elements
from dictk.plot import element_strain_plot

element_indices = elements(count_x=5, count_y=50)
values = []
coordinates = []
for element in element_indices:
    reference_corners = [points[i] for i in element]
    current_corners = [found[i] for i in element]
    strains = gauss_point_log_strains(
        reference_points=reference_corners, current_points=current_corners
    )
    values.extend(strain[0, 0] for strain in strains)
    coordinates.extend(gauss_point_coordinates(points=current_corners))

element_strain_plot(
    points=found,
    elements=element_indices,
    coordinates=coordinates,
    values=values,
    label=r"Log Strain, $E_{11}$",
    path="simple_stretch_revisited_strain_gauss_points.png",
)
element_strain_plot(
    points=found,
    elements=element_indices,
    coordinates=coordinates,
    values=values,
    label=r"Log Strain, $E_{11}$",
    image=current_image,
    path="simple_stretch_revisited_strain_on_current.png",
)
current_image.is still exactly at all 784 Gauss points — a uniform stretch is still a uniform stretch, regardless of how finely it's sampled. What's new here isn't the number, it's that the method now scales cleanly to a grid closer to VIC-2D's own density, with no tracking failures anywhere in it.
Point count was the free variable throughout this section — 250 here,
chosen for exactness, not for speed. How dictk's own tracking time
scales as point count grows much larger, and how that scaling compares
across sequential, threaded, and multi-process execution, is
Parallelization's own question, not this one.
Two things this section deliberately leaves open. Every point here still has to land on an exact integer pixel — real displacements won't. Recovering those is Subpixel Accuracy's own job, not this section's — it picks up exactly this constraint, using this same scenario. And the timing question just raised — how tracking time actually scales once point count grows past 250 — is Parallelization's to answer, not this page's.
Recoverable Displacement Range
Simple Stretch raised a natural follow-up
question: how far can astronaut0 be stretched, or compressed, before
locate stops finding the exact expected position? The investigation
that followed didn't answer that question directly. It found something
more fundamental first — a real, silent bug in locate itself, now
fixed. This page chronicles how.
The First Sweep
The rest of this page traces a real, silent bug in locate: the kernel
content it correlates against gets padded asymmetrically, capping how
far a point can move and still be found. Here it is, directly. A point
at px, a 60x60 px kernel (kernel_margin = 30), moved by
a series of dx values, tracked with a deliberately pre-fix version of
locate.
locate_uncentered —
introduced properly, with the reasoning behind it, in Isolating the
Real Variable below — reproduces exactly
the padding this page's real, shipped locate no longer has. The fixed
version wouldn't reproduce this collapse at all:
from dictk.image import PixelCoordinate, read, translate
from recoverable_displacement_range_uncentered_demo import locate_uncentered

reference_image = read(path="astronaut0.png")
p0 = PixelCoordinate(x=150, y=150)
kernel_margin = 30
search_margin = 150  # generous -- per Root Cause, size won't help here --
# and exactly half of astronaut0's 300px canvas, so the search reads the
# whole image with no extraction margin of its own

for dx in [0, 10, 20, 25, 29, 30, 31, 35, 40, 50]:
    current_image = translate(arr=reference_image, dx=dx, dy=0)
    expected = PixelCoordinate(x=p0.x + dx, y=p0.y)
    found = locate_uncentered(reference_image, current_image, p0, p0, kernel_margin, search_margin)
    print(f"dx={dx}  expected={expected}  found={found}  match={found == expected}")
expected/found below appear in two reference frames side by side:
current_image's own absolute frame (what locate_uncentered actually
returns, same as the code above), and the local frame of search
itself -- labeled "Fixed Image, frame ", matching Seeing
the Cliff's quadrant figures just below exactly.
expected there always equals the correlation surface's own true peak
(that section's yellow box); found always equals what
locate_uncentered actually reports (its magenta box):
| dx | current_image (absolute) | Fixed Image, frame | match | ||
|---|---|---|---|---|---|
| expected | found | expected | found | ||
| 0 | (150,150) | (150,150) | (120,120) | (120,120) | True |
| 10 | (160,150) | (160,150) | (130,120) | (130,120) | True |
| 20 | (170,150) | (170,150) | (140,120) | (140,120) | True |
| 25 | (175,150) | (175,150) | (145,120) | (145,120) | True |
| 29 | (179,150) | (179,150) | (149,120) | (149,120) | True |
| 30 | (180,150) | (180,150) | (150,120) | (150,120) | True |
| 31 | (181,150) | (-119,150) | (151,120) | (-149,120) | False |
| 35 | (185,150) | (-115,150) | (155,120) | (-145,120) | False |
| 40 | (190,150) | (-110,150) | (160,120) | (-140,120) | False |
| 50 | (200,150) | (-100,150) | (170,120) | (-130,120) | False |
A sharp cliff, right at dx = kernel_margin + 1. search_margin = 150
— five times kernel_margin — makes no difference past that point at
all. The rest of this page explains why, and fixes it.
Seeing the Cliff
The correlation surface behind this is never actually wrong -- its own
peak lands at the correct position for both dx = 30 and dx = 31,
confirmed separately. The bug is downstream: locate_uncentered's
skimage-based conversion of that surface into a signed shift, which
misreads the answer only past the cliff. recoverable_displacement_range_first_sweep_quadrant.py
marks both positions on the same Fixed Image panel
phase_correlation_quadrant_plot
already draws elsewhere in this book -- the surface's own true peak
(yellow, dashed, unchanged from every other use of that function) and
where locate_uncentered actually reports the point (magenta). search
here reads the entire astronaut0 canvas -- search_margin = 150 is
exactly half its 300px width -- so the extraction itself adds no black
margin of its own; the only black left is dx's own left-side gap from
shifting the image right:
Saved: recoverable_displacement_range_first_sweep_quadrant_dx30.png
Saved: recoverable_displacement_range_first_sweep_quadrant_dx31.png
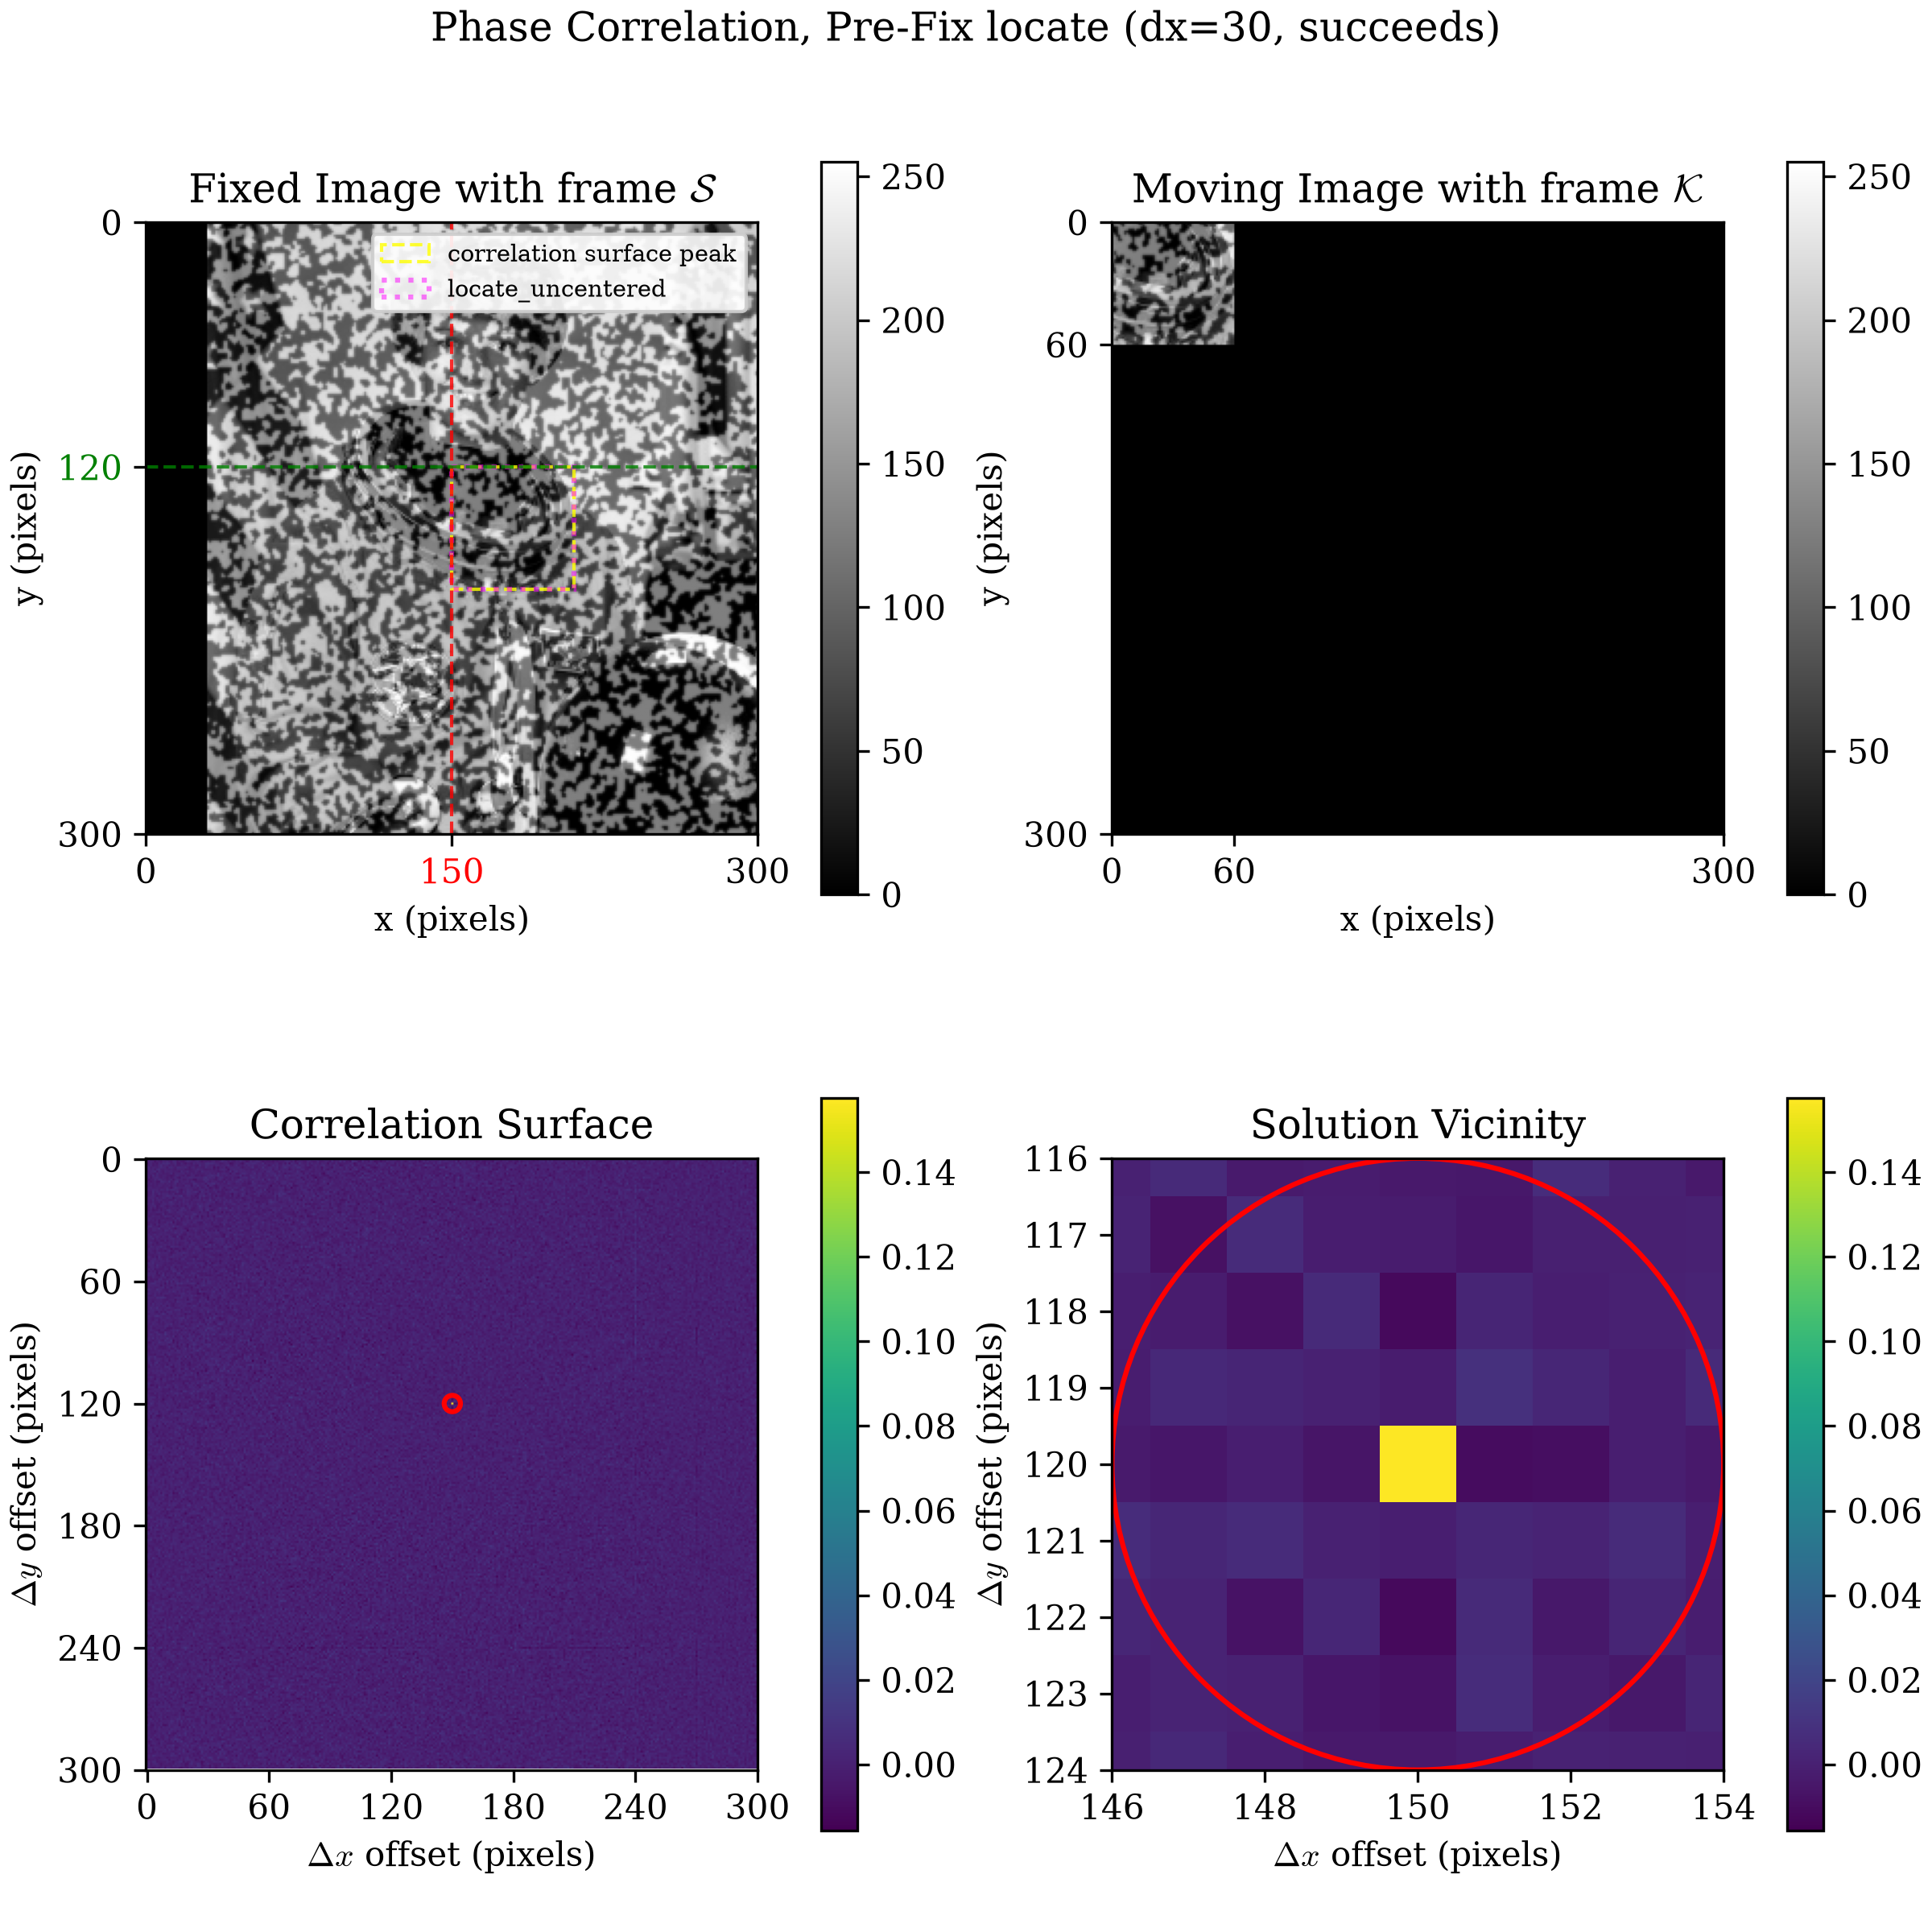
dx = 30: the black margin on the left is exactly 30px wide -- dx itself, visible directly, not just computed. The two boxes coincide: locate_uncentered reports the same position the surface actually peaks at.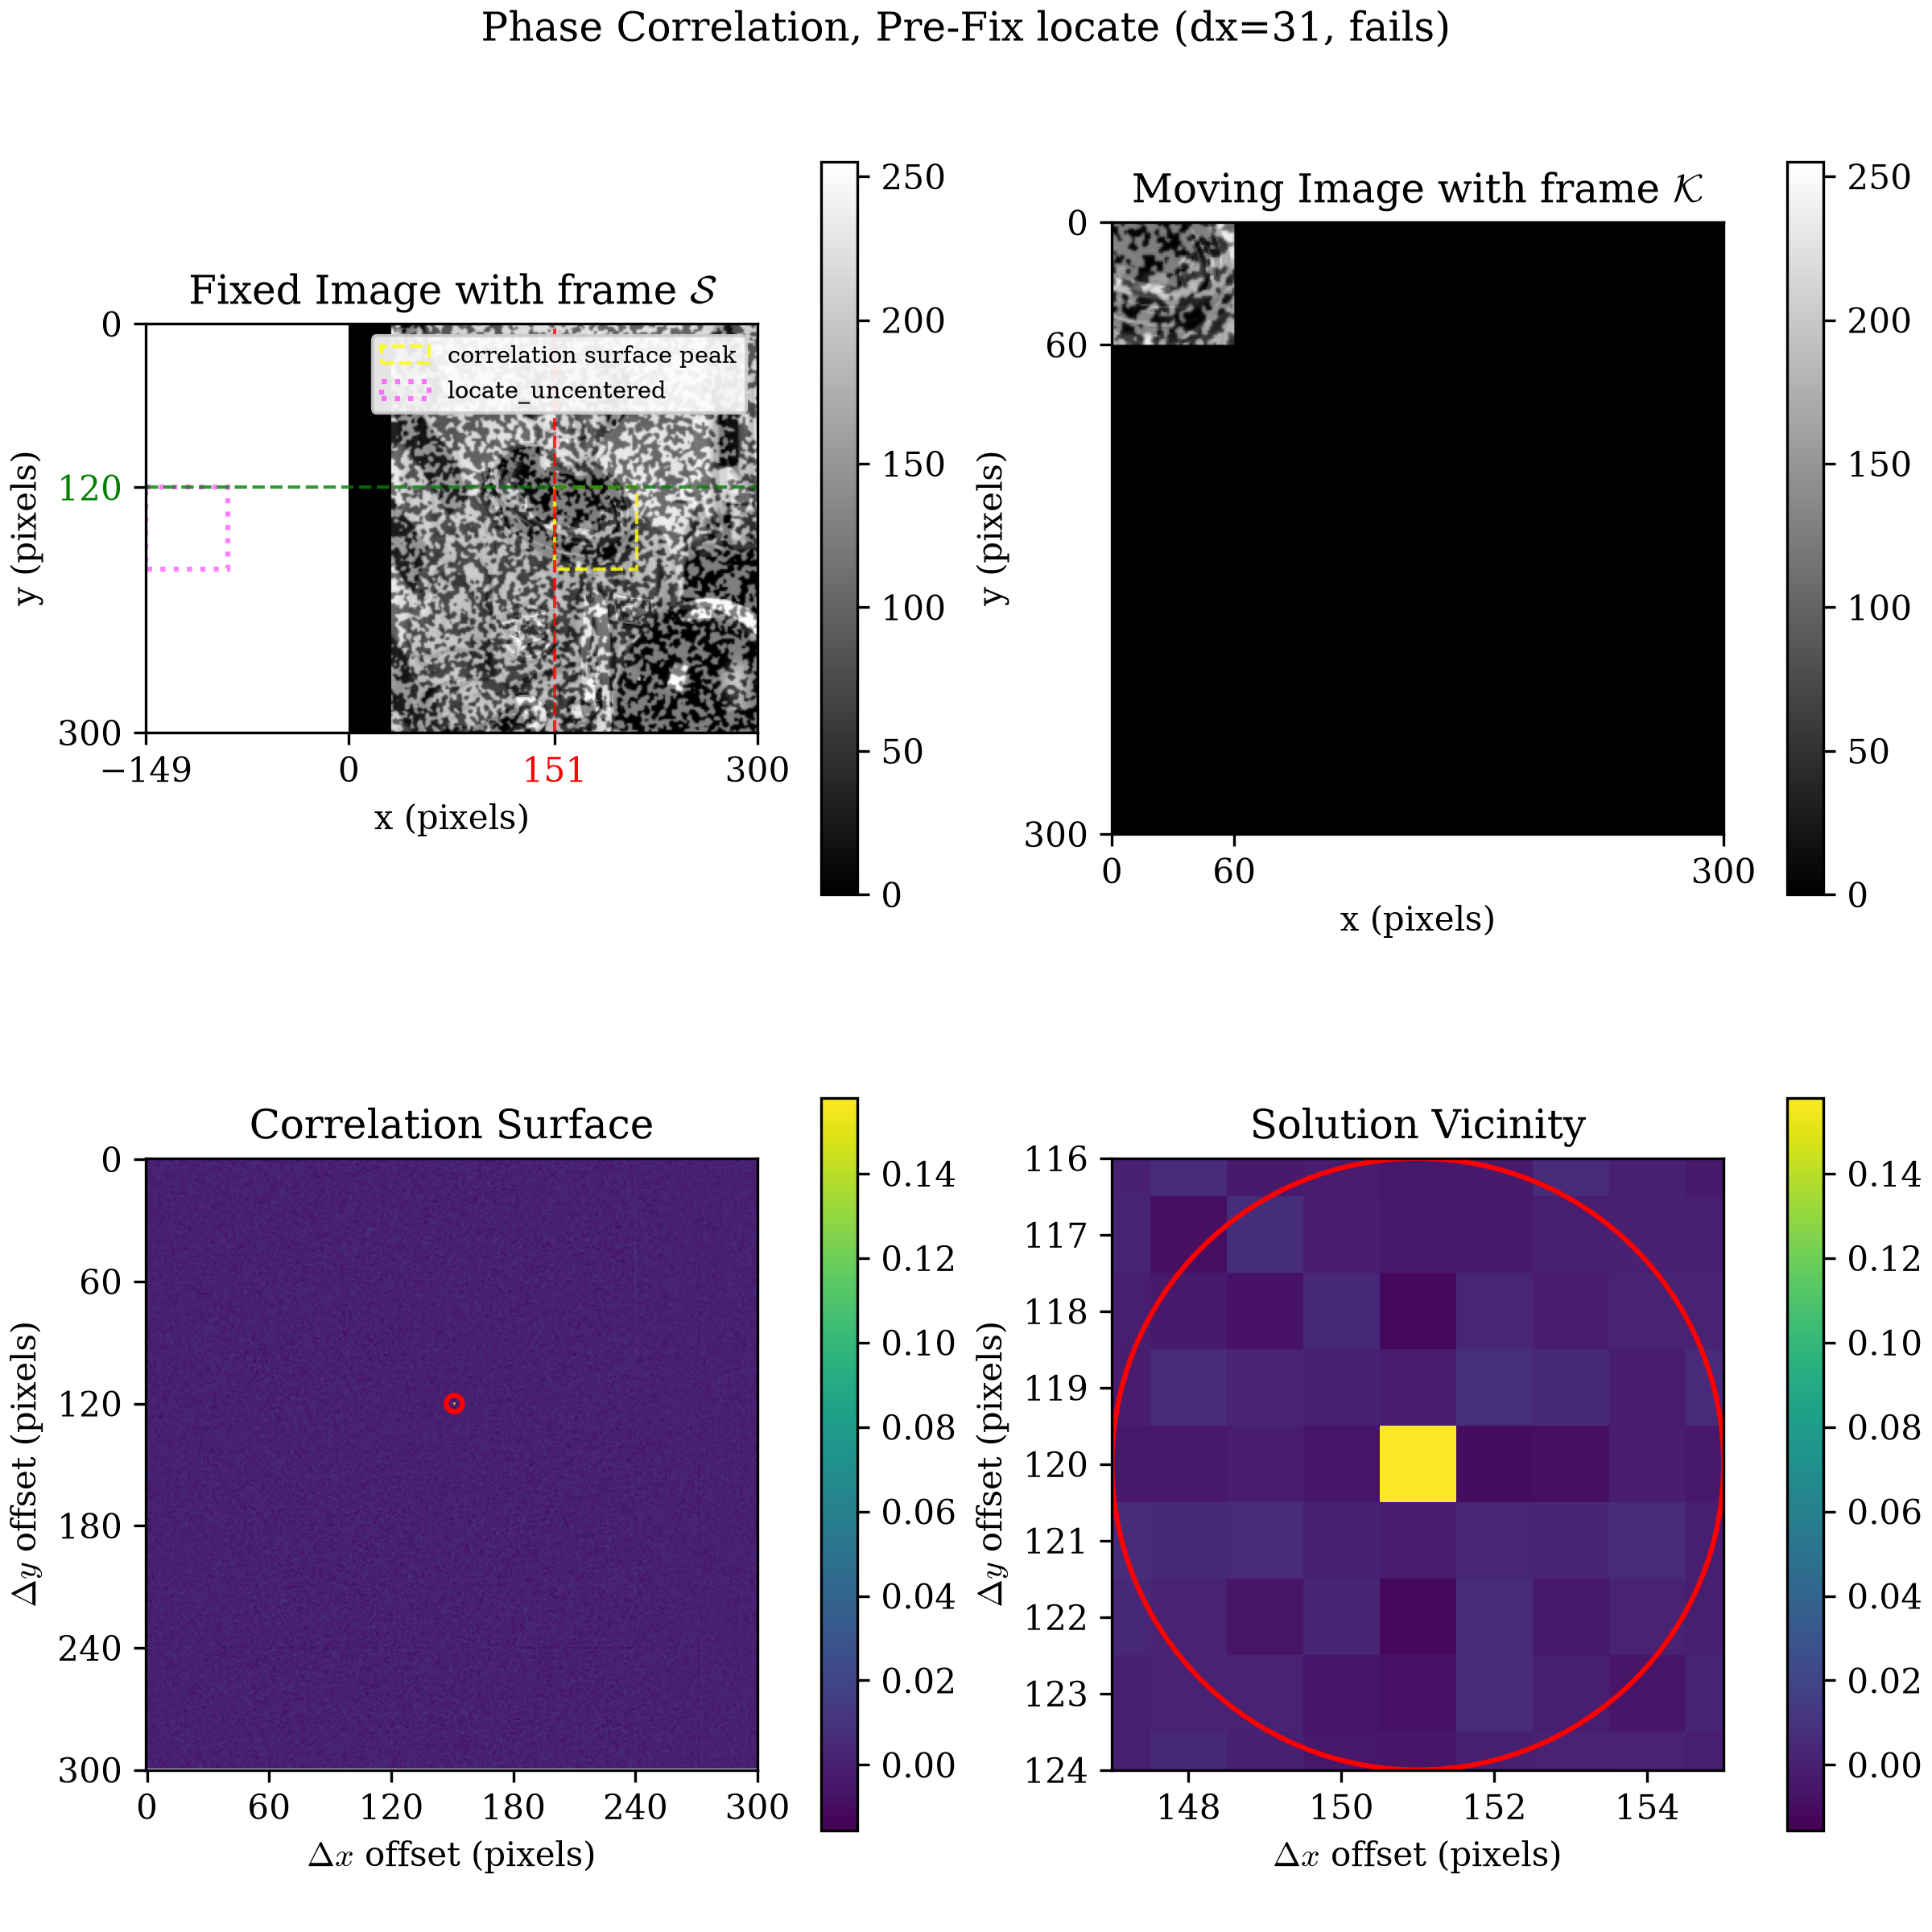
dx = 31: the yellow box still marks the surface's true (correct) peak. The magenta box -- where locate_uncentered actually reports the point -- lands entirely outside the visible search frame, off by exactly the padded array's own width.Fixing locate
recoverable_displacement_range_fixing_locate.py
(full source at the bottom of this page) re-runs The First Sweep's
exact scenario and dx values against the real, shipped
dictk.translation.locate --
not locate_uncentered -- before this page walks through why the fix
was needed. Same two reference frames as The First Sweep's own table
above:
| dx | current_image (absolute) | Fixed Image, frame | match | ||
|---|---|---|---|---|---|
| expected | found | expected | found | ||
| 0 | (150,150) | (150,150) | (120,120) | (120,120) | True |
| 10 | (160,150) | (160,150) | (130,120) | (130,120) | True |
| 20 | (170,150) | (170,150) | (140,120) | (140,120) | True |
| 25 | (175,150) | (175,150) | (145,120) | (145,120) | True |
| 29 | (179,150) | (179,150) | (149,120) | (149,120) | True |
| 30 | (180,150) | (180,150) | (150,120) | (150,120) | True |
| 31 | (181,150) | (181,150) | (151,120) | (151,120) | True |
| 35 | (185,150) | (185,150) | (155,120) | (155,120) | True |
| 40 | (190,150) | (190,150) | (160,120) | (160,120) | True |
| 50 | (200,150) | (200,150) | (170,120) | (170,120) | True |
Every row matches now, cliff included.
recoverable_displacement_range_fixing_locate_quadrant.py
draws dx = 31 -- the cliff itself -- the same way Seeing the Cliff
did, but with centered=True:
phase_correlation_quadrant_plot
pads the Moving Image panel's kernel the same way locate now does
internally, instead of the permanent bottom-right-only padding
phase_correlation itself always keeps. Compare the two Moving Image
panels directly: Seeing the Cliff's dx = 31
figure shows the kernel's content pinned to the
top-left corner of an otherwise-black canvas; this one shows the exact
same content centered within it, black on all four sides evenly. That
single difference is the entire fix:
Saved: recoverable_displacement_range_fixing_locate_quadrant_dx31.png
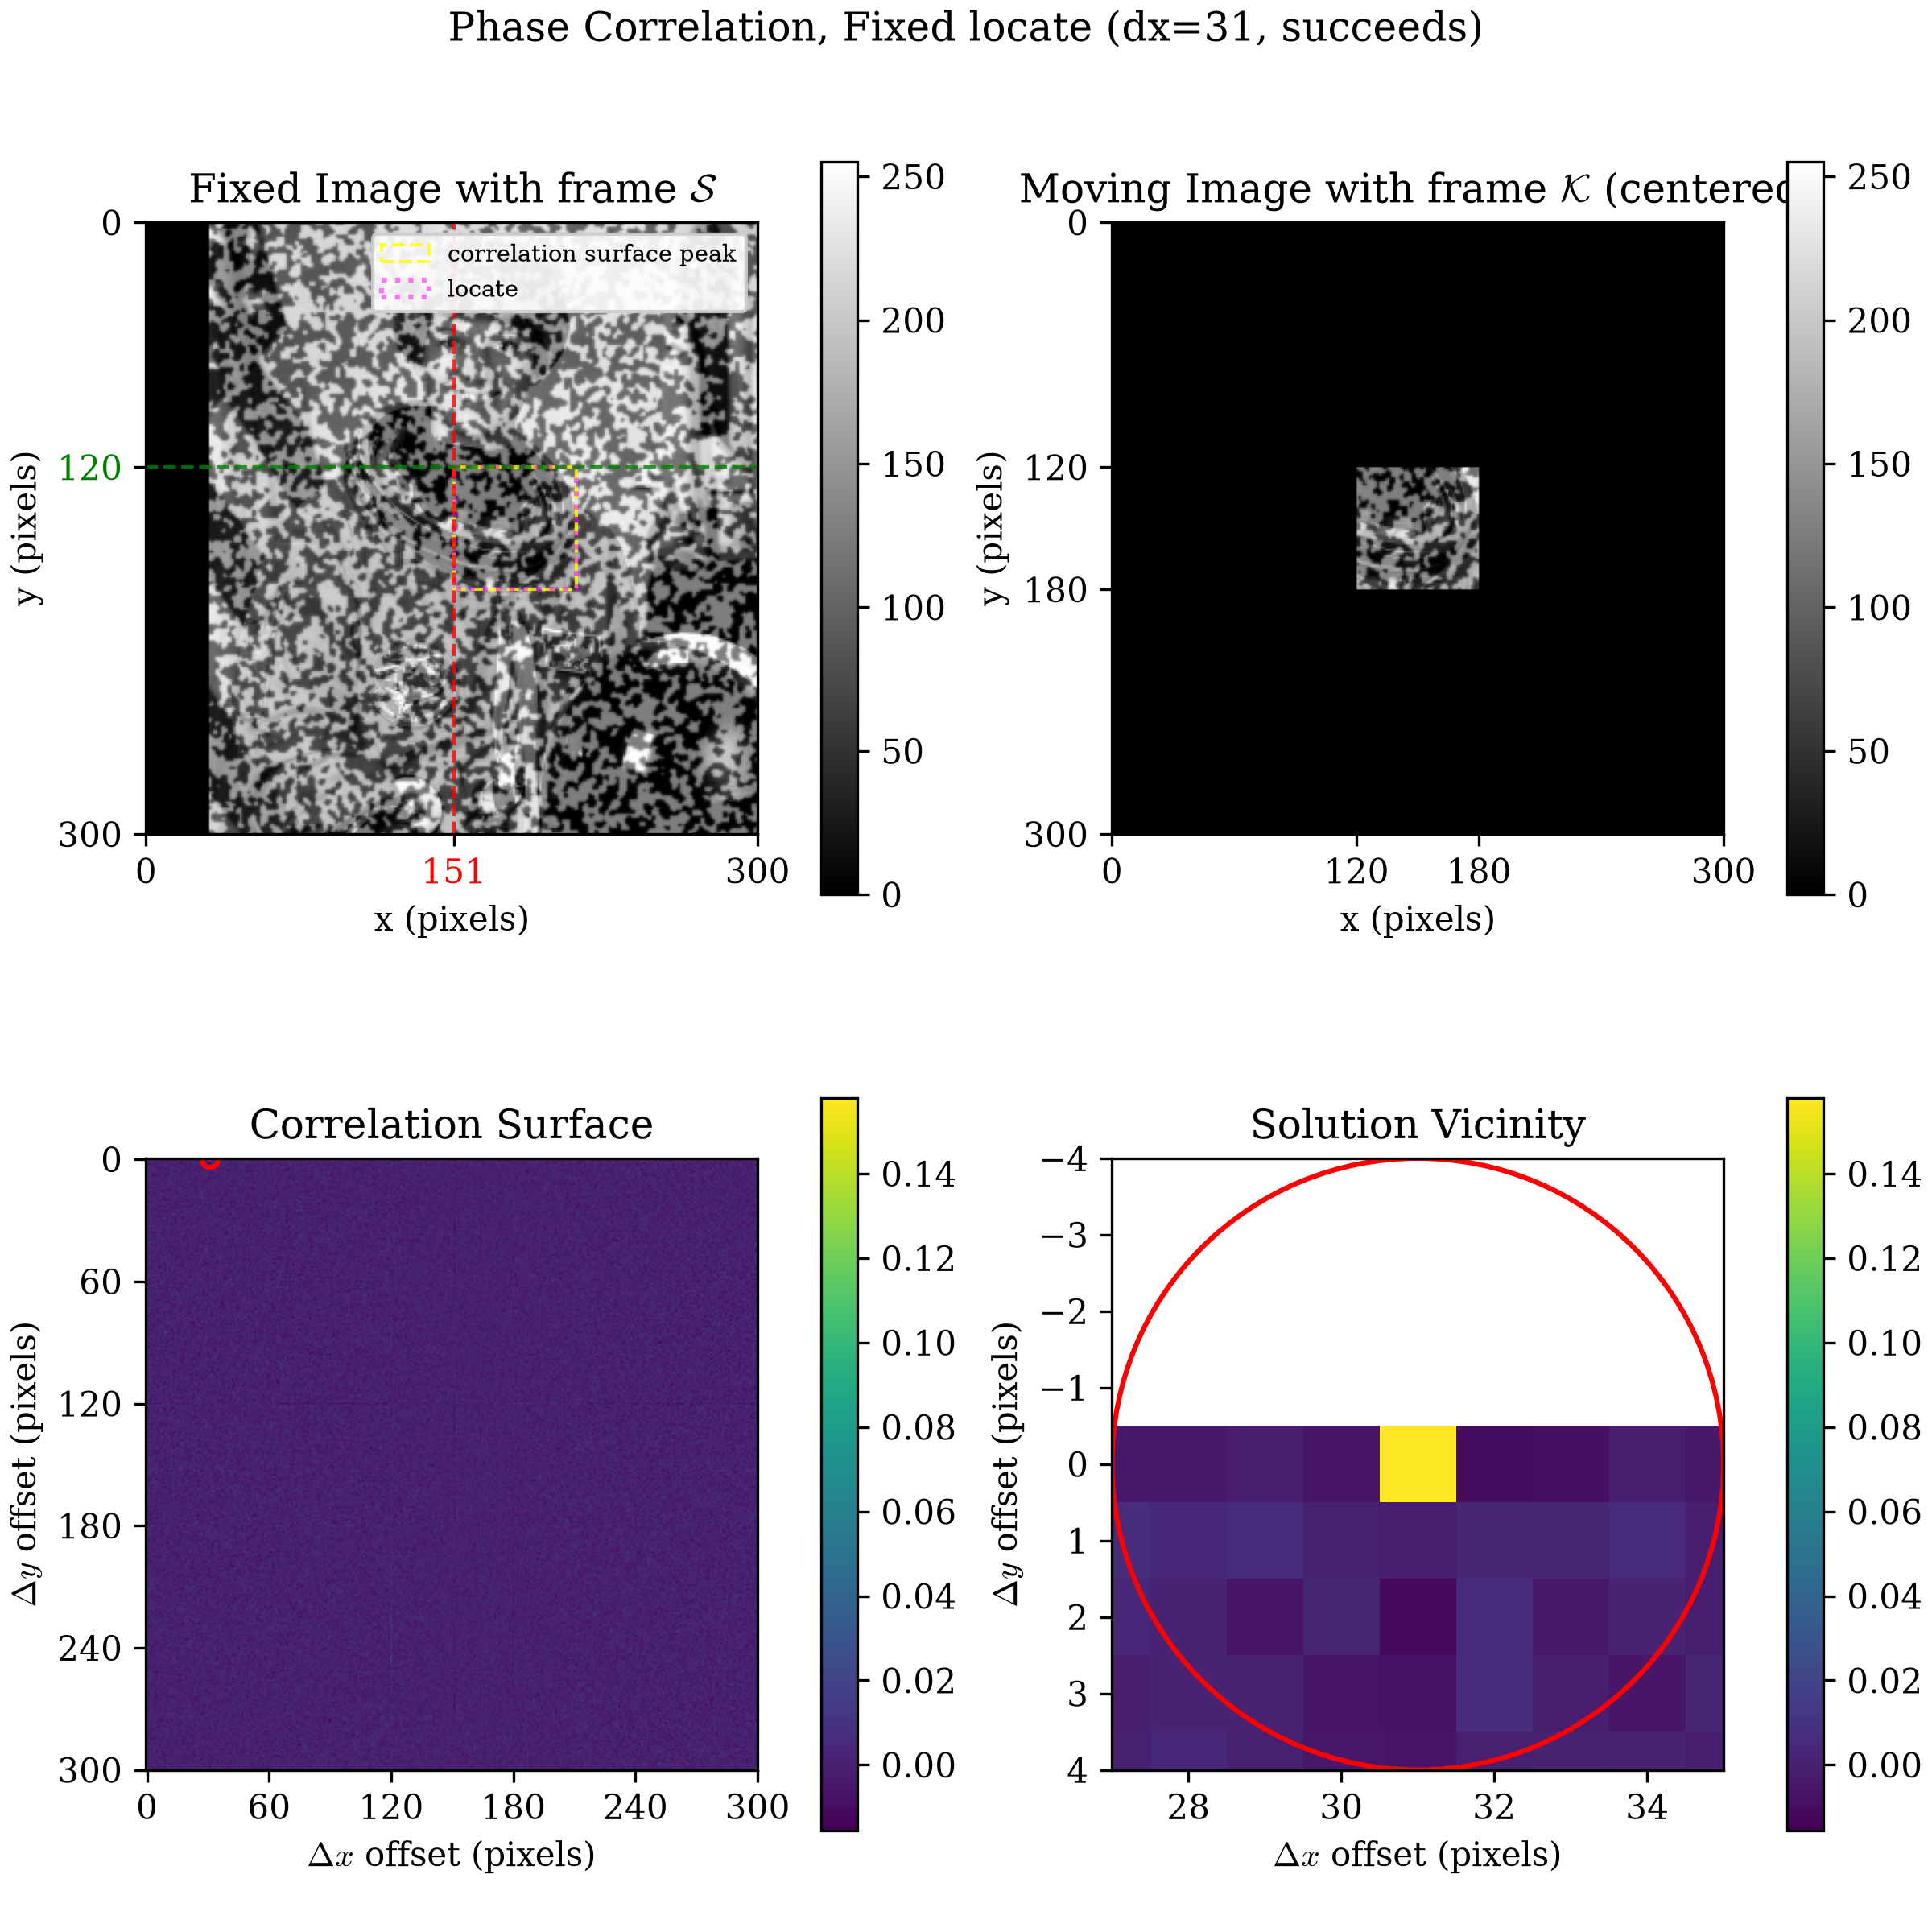
dx = 31, post-fix. The Moving Image panel's kernel content is centered, not pinned to the top-left corner -- compare directly against Seeing the Cliff's dx = 31 figure above. On the Fixed Image panel, the two boxes coincide again: locate now reports the same position the surface actually peaks at, past the old cliff.The rest of this page takes a step back and walks through the investigation in full -- the hypotheses that turned out not to explain it, the confound that had to be set aside, isolating the real variable, and exactly why the kernel's padding needed to be centered to fix this.
The Original Stretch Question
That cliff is the real bug this page fixes, but it isn't how the
investigation actually started. It began from a different angle:
Simple Stretch's own question, how far can
astronaut0 be stretched, or compressed, before locate stops finding
the exact expected position? Reuse Point
Grid's 12 points and sweep
factor_x upward, sizing search_margin_width per factor so it always
comfortably contains the largest point's displacement — wide enough
that "the window was too small" can't explain a failure:
from dictk.image import read, stretch, PixelCoordinate
from dictk.grid import generate, locate

reference_image = read(path="astronaut0.png")
points = generate(
    origin=PixelCoordinate(x=50, y=50), count_x=3, count_y=4, spacing_x=50, spacing_y=55
)
kernel_margin = 20

for p in [2, 4, 6, 8, 18, 20, 40, 80]:
    factor_x = 1 + p / 100
    current_image = stretch(arr=reference_image, factor_x=factor_x)
    max_disp = max(abs(pt.x * (factor_x - 1)) for pt in points)
    search_margin_width = max(int(max_disp) + 15, kernel_margin + 10)
    found = locate(
        reference_image=reference_image, current_image=current_image, reference_points=points,
        kernel_margin_width=kernel_margin, kernel_margin_height=kernel_margin,
        search_margin_width=search_margin_width, search_margin_height=52,
    )
    expected = [PixelCoordinate(x=int(pt.x * factor_x), y=pt.y) for pt in points]
    n_match = sum(1 for f, e in zip(found, expected) if f == e)
    print(f"{p:3d}%  search_margin_width={search_margin_width:4d}  matched={n_match:2d}/12")
| Stretch | factor_x | search_margin_width | Matched |
|---|---|---|---|
| 2% | 1.02 | 30 | 12/12 |
| 4% | 1.04 | 30 | 12/12 |
| 6% | 1.06 | 30 | 10/12 |
| 8% | 1.08 | 30 | 6/12 |
| 18% | 1.18 | 41 | 1/12 |
| 20% | 1.20 | 44 | 1/12 |
| 40% | 1.40 | 74 | 0/12 |
| 80% | 1.80 | 135 | 0/12 |
Matching collapses almost immediately — well before 20% stretch. That's surprising: at this book's own 40-pixel kernel scale, a real degradation-driven failure shouldn't set in this early.
This table already runs against locate's real, fixed version — it's
live, re-run on every book build. Path
Forward already checked whether the fix
above changed it, and it doesn't: search_margin_width here is always
sized larger than the true displacement, so this sweep never actually
hits the cliff bug The First Sweep demonstrated. Something else
explains this particular collapse.
Two Hypotheses, Both Ruled Out
Two mechanisms seemed possible: blur or canvas exit.
Hypothesis 1: Blur
stretch uses bilinear interpolation, sampling an increasingly small
crop of the original image to fill the same canvas. Whole-image
contrast does drop as factor_x grows — but only mildly, from a
standard deviation of 63.8 at factor_x=1.0 to 58.1 even at
factor_x=3.0. Not a collapse.
That claim is a whole-image statistic. Seeing it directly, side by side with the image it's measuring, makes it concrete rather than just asserted:
import matplotlib.pyplot as plt
from dictk.image import read, stretch

reference_image = read(path="astronaut0.png")
factors = [1.0, 1.5, 2.0, 3.0]

plt.rcParams.update({"font.family": "serif", "mathtext.fontset": "cm"})
fig, axes = plt.subplots(2, len(factors), figsize=(11, 5.8), constrained_layout=True)
for col, factor_x in enumerate(factors):
    img = stretch(arr=reference_image, factor_x=factor_x)
    mean, std = img.mean(), img.std()

    axes[0, col].imshow(img, cmap="gray", vmin=0, vmax=255)
    axes[0, col].set_title(f"factor_x={factor_x:.1f}\nstd={std:.1f}", fontsize=10)
    axes[0, col].set_xticks([])
    axes[0, col].set_yticks([])

    ax_hist = axes[1, col]
    counts, _, _ = ax_hist.hist(img.ravel(), bins=50, range=(0, 255), color="black", alpha=0.7)
    y_bracket = counts.max() * 1.12
    ax_hist.axvline(mean - std, color="tab:red", linestyle="--", linewidth=1)
    ax_hist.axvline(mean + std, color="tab:red", linestyle="--", linewidth=1)
    ax_hist.annotate(
        "",
        xy=(mean - std, y_bracket),
        xytext=(mean + std, y_bracket),
        arrowprops=dict(arrowstyle="<->", color="tab:red"),
    )
    ax_hist.text(mean, y_bracket * 1.06, f"±1 std = {std:.1f}", ha="center", va="bottom", fontsize=8, color="tab:red")
    ax_hist.set_ylim(0, y_bracket * 1.35)
    ax_hist.set_xlim(0, 255)
    ax_hist.set_xlabel("pixel value", fontsize=8)
fig.savefig("recoverable_displacement_range_blur.png", dpi=300)
Saved: recoverable_displacement_range_blur.png
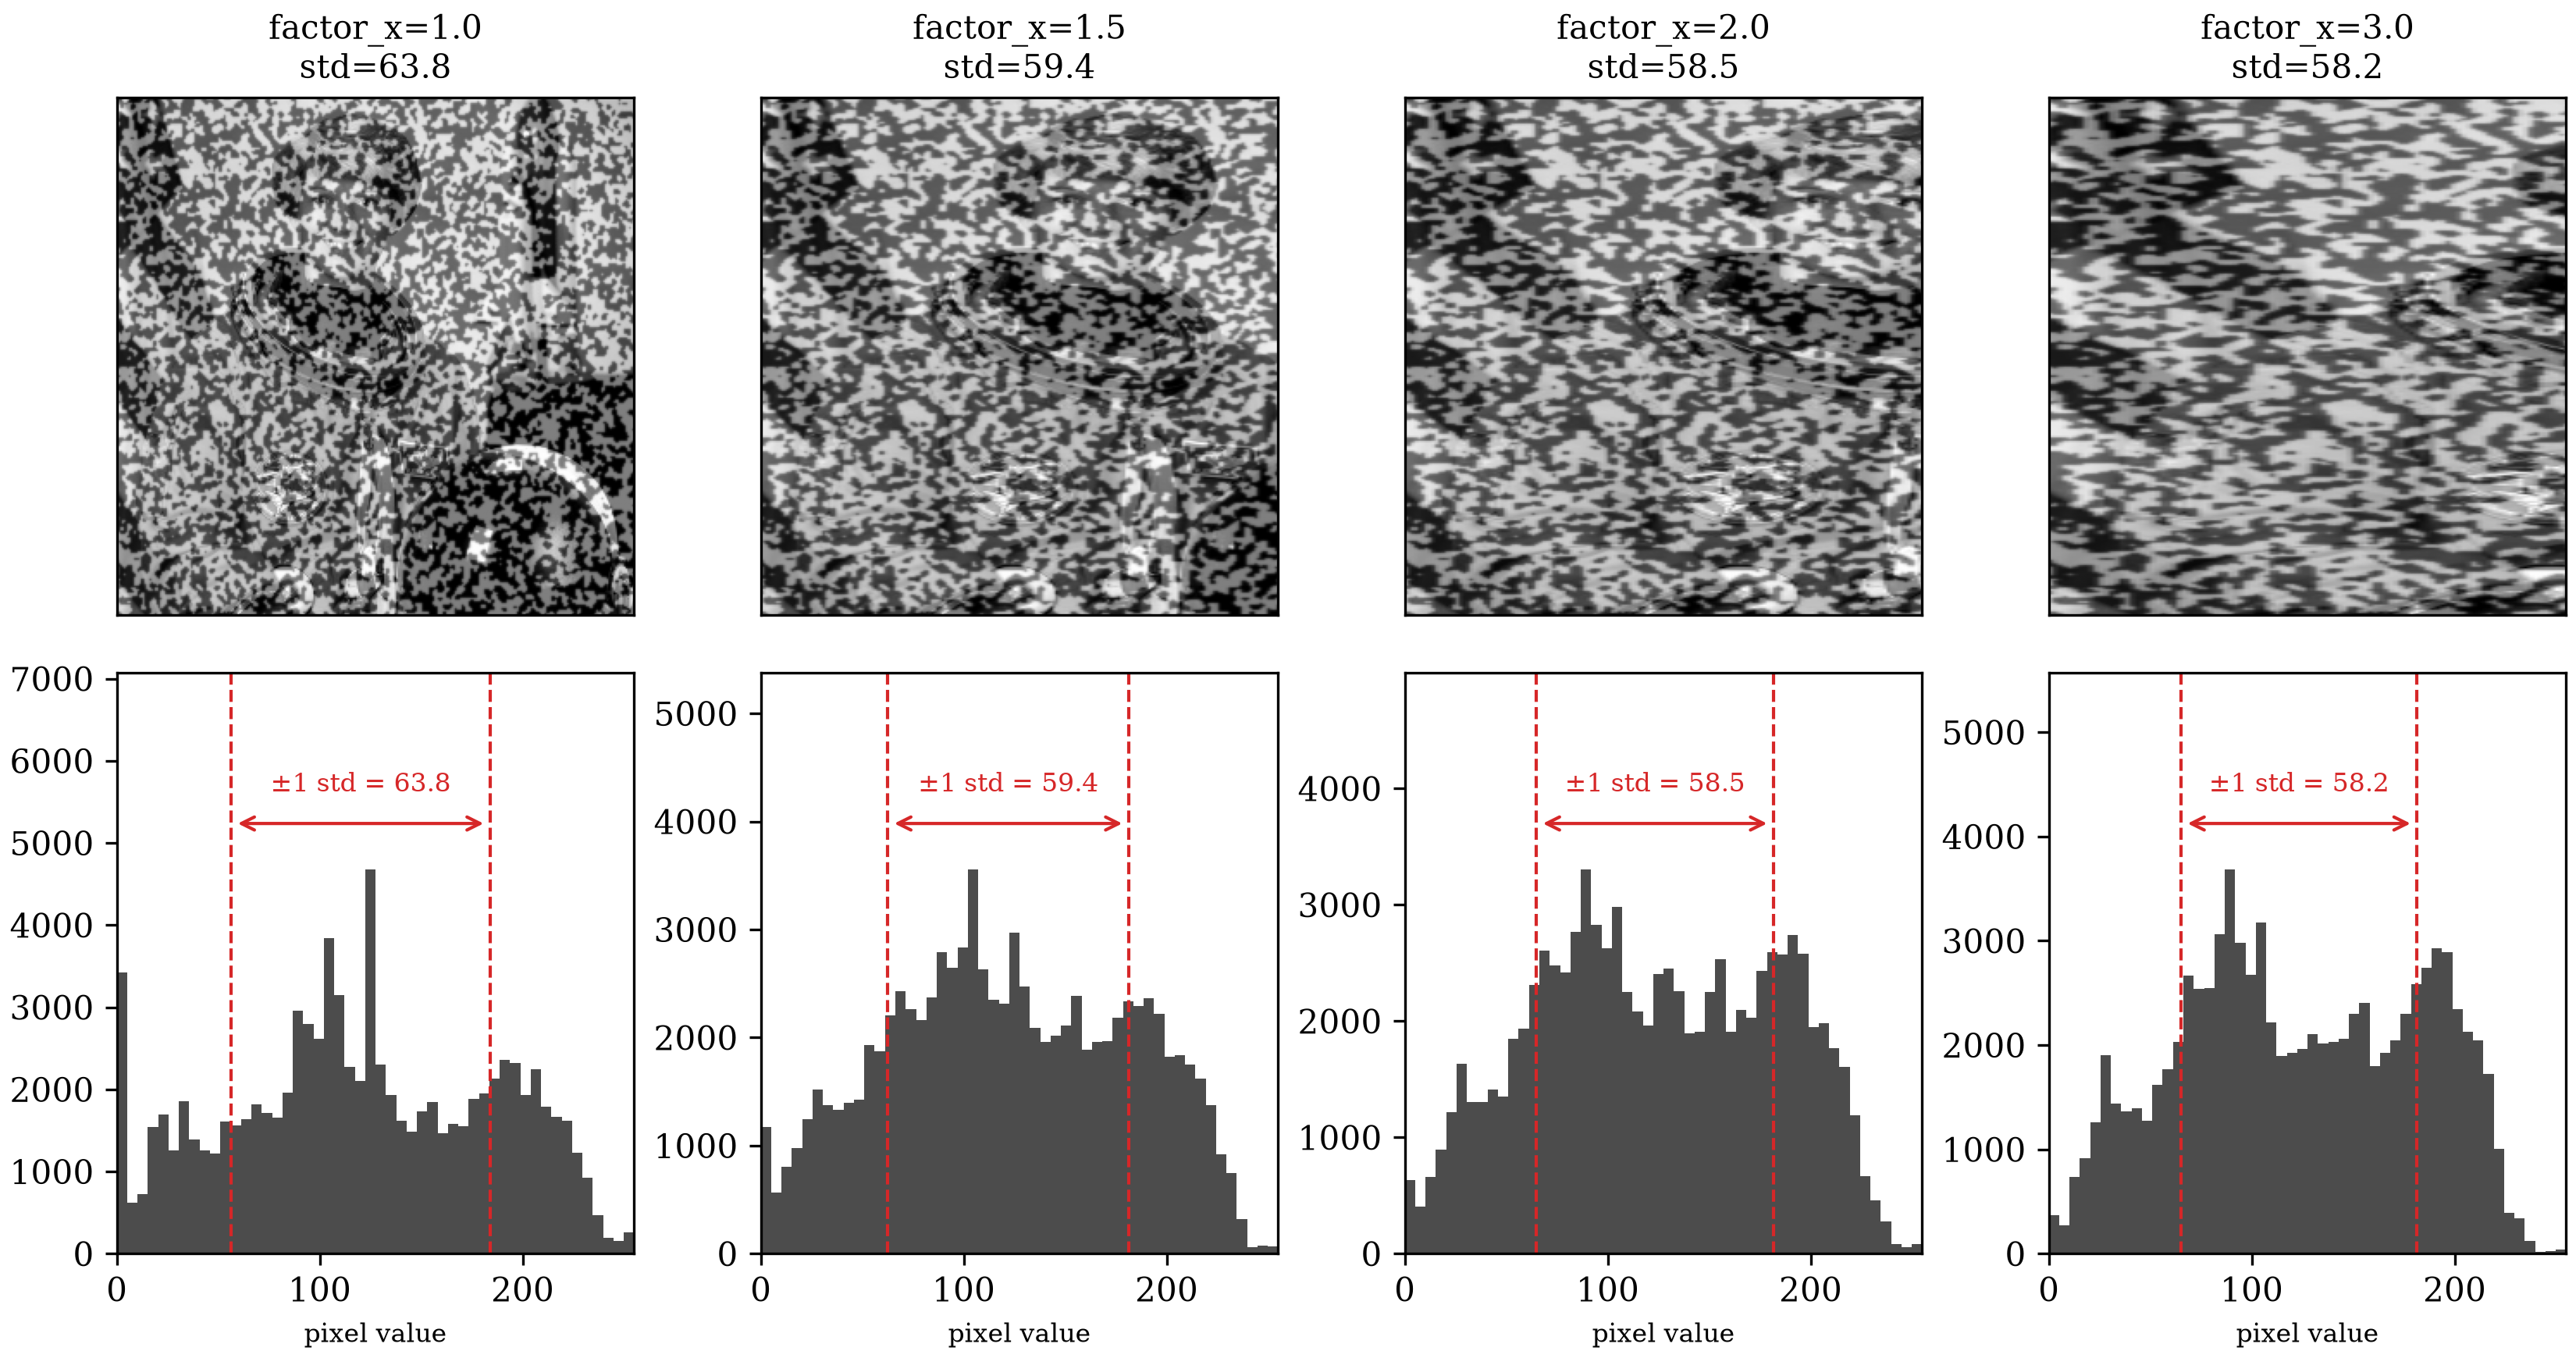
astronaut0 stretched at four factors. Bottom: each one's own pixel-value histogram, with a red bracket marking the ±1 standard deviation span. The images show where the blur comes from — horizontal streaking, since stretch only resamples along — but the bracket confirms it's mild: the span narrows only slightly as standard deviation drops from 63.8 to 58.2, nowhere near the collapse the first sweep showed at just 6-8%.There's also a theoretical reason this mild blur shouldn't move the peak
at all. locate's phase normalization
divides out signal strength at every frequency and keeps only direction.
Blurring changes strength, not direction — the same property that already
makes locate insensitive to contrast. Only heavy blur eventually breaks
that guarantee in practice, since real images pad and round at their
edges instead of matching the idealized math exactly. stretch never
reaches that regime at these factors.
Hypothesis 2: Canvas Exit
stretch pivots at the origin, so a point far enough from it can be
pushed past the image's fixed 300-pixel edge. For (this grid's
maximum dimension) that doesn't happen until factor_x=2.0 — 100%
stretch, long after the matching collapse above.
Plotting that point's expected position directly on each stretched image makes the exit itself visible, not just computed:
import matplotlib.pyplot as plt
from dictk.image import read, stretch

reference_image = read(path="astronaut0.png")
height, width = reference_image.shape
p_x, p_y = 150, 50  # the grid's farthest point from the origin
factors = [1.0, 1.5, 2.0, 2.5]

plt.rcParams.update({"font.family": "serif", "mathtext.fontset": "cm"})
fig, axes = plt.subplots(1, len(factors), figsize=(11, 3.4), constrained_layout=True)
for ax, factor_x in zip(axes, factors):
    img = stretch(arr=reference_image, factor_x=factor_x)
    x_expected = p_x * factor_x
    on_canvas = x_expected < width

    ax.imshow(img, cmap="gray", vmin=0, vmax=255, extent=[0, width, height, 0])
    ax.axvline(width, color="tab:red", linestyle="--", linewidth=1)
    ax.plot(x_expected, p_y, marker="+", color="tab:orange", markersize=10, markeredgewidth=2.5)
    ax.set_xlim(-20, 400)
    ax.set_ylim(height + 20, -20)
    status = "on canvas" if on_canvas else "OFF CANVAS"
    ax.set_title(f"factor_x={factor_x:.1f}\nx={x_expected:.0f}  ({status})", fontsize=10)
    ax.set_xticks([])
    ax.set_yticks([])
fig.savefig("recoverable_displacement_range_canvas_exit.png", dpi=300)
Saved: recoverable_displacement_range_canvas_exit.png
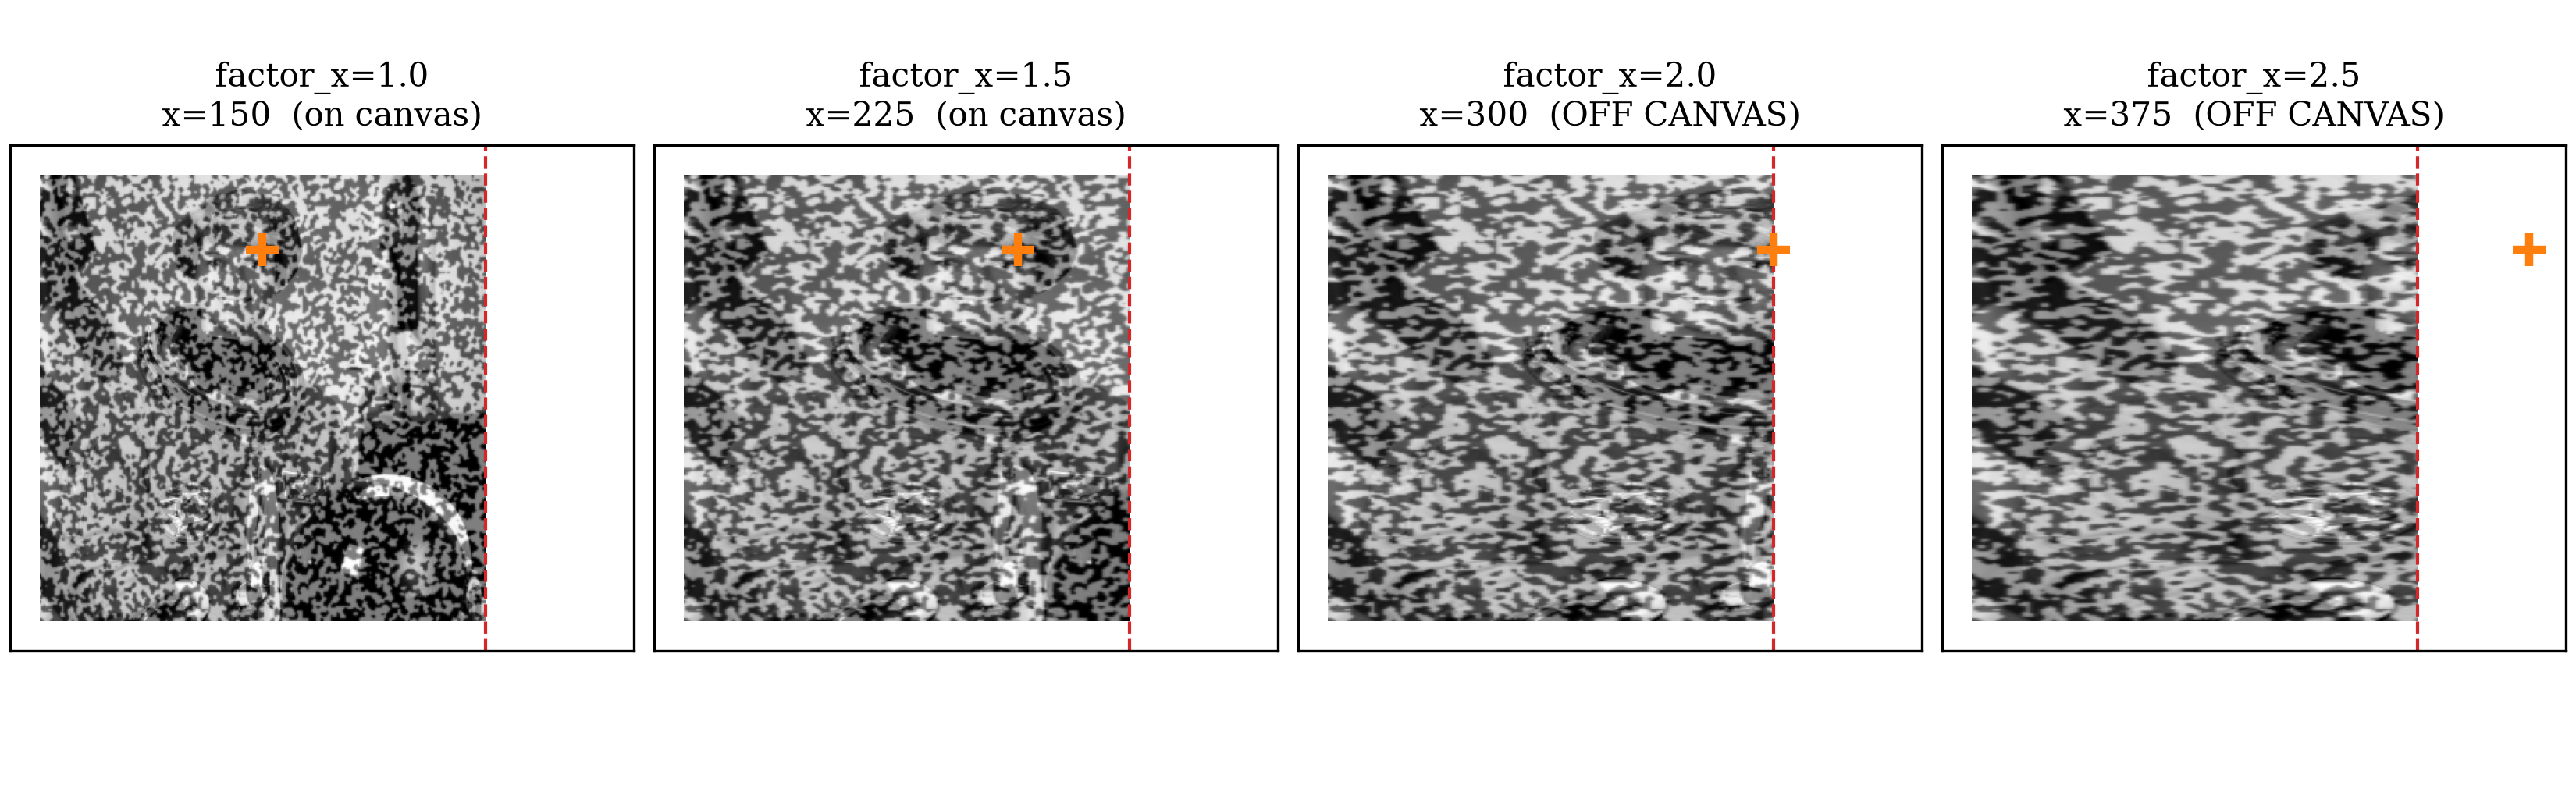
factor_x=2.0 — the threshold the text above states — and floats clearly outside the image by factor_x=2.5. That threshold sits far past the collapse the first sweep showed at just 6-8%, ruling canvas exit out too.Neither blur nor canvas exit explains a collapse at 6-8%. Something else is going on, and it isn't image degradation.
An Interpolation Confound, Set Aside
Chasing the real cause directly through stretch turned out to be the
wrong tool: even at a percentage chosen so a point's center pixel
lands on an exact integer, bilinear interpolation still resamples
every other pixel in that point's kernel from a fractional source
coordinate. The center matches; the kernel's surrounding texture is
subtly blurred anyway, in a way that grows with factor_x. That's a
real phenomenon — related to Path Forward's Postponed subpixel-accuracy
item — but a second, separate one from
whatever is causing the sharp, early collapse above. Isolating the real
cause means removing this confound entirely: pure integer-pixel
translate instead of stretch,
where every pixel maps from an exact integer source coordinate and
bilinear interpolation never activates at all.
Isolating the Real Variable
Consider a point in the reference configuration with coordinate px in astronaut0.
It moves a displacement of px — 10 px
to the right — landing at px in the current configuration.
Now consider four kernel margins ( px, small to large)
and, for each one, two search margins (kernel_margin + 15 and
kernel_margin + 80 px) — eight combinations in total.
- Question: Does the ratio of kernel size to search-window size explain anything?
- Answer: It does not.
All eight combinations find the exact expected point — from a comfortable ratio of 0.67 down to a razor-thin 0.10:
from dictk.image import read, translate, PixelCoordinate
from dictk.translation import locate

reference_image = read(path="astronaut0.png")
p0 = PixelCoordinate(x=150, y=150)
dx = 10
current_image = translate(arr=reference_image, dx=dx, dy=0)
expected = PixelCoordinate(x=p0.x + dx, y=p0.y)

for kernel_margin in [15, 20, 25, 30]:
    for search_margin in [kernel_margin + 15, kernel_margin + 80]:
        found = locate(
            reference_image=reference_image, current_image=current_image,
            reference_point=p0, search_center=p0,
            kernel_margin_width=kernel_margin, kernel_margin_height=kernel_margin,
            search_margin_width=search_margin, search_margin_height=search_margin,
        )
        ratio = kernel_margin / search_margin
        print(f"kernel_margin={kernel_margin:2d}  search_margin={search_margin:3d}  ratio={ratio:.2f}  match={found == expected}")
| kernel_margin | search_margin | ratio | match |
|---|---|---|---|
| 15 | 30 | 0.50 | True |
| 15 | 95 | 0.16 | True |
| 20 | 35 | 0.57 | True |
| 20 | 100 | 0.20 | True |
| 25 | 40 | 0.62 | True |
| 25 | 105 | 0.24 | True |
| 30 | 45 | 0.67 | True |
| 30 | 110 | 0.27 | True |
Ratio genuinely doesn't matter. But, raw displacement does matter.
locate compares that raw displacement against kernel_margin alone.
search_margin plays no role here, no matter how large it is.
The rest of this section demonstrates that failure directly, using
recoverable_displacement_range_uncentered_demo.py,
a Python script listed at the bottom of this page. That script
contains a (now understood to be buggy) version of locate, called
locate_uncentered. It calls _kernel_pad(..., centered=False), where the
centered=False is the crucial bug-inducing parameter. This
script exists because the real, shipped locate has already been
fixed to center-pad the kernel. It would no longer reproduce the
cliff bug, shown next.
Consider again a point in the reference configuration at px.
Let kernel_margin = 30 px, a reasonable size.
Let search_margin = 180 px, a generous size (and this size shouldn't matter, per the result above).
Now investigate a series of dx values: kernel_margin ,
which is . Each dx produces one candidate current
configuration. The (right-hand side) cliff appears the moment dx crosses one pixel past
kernel_margin, at kernel_margin . There, the found location is
predicted at px, not the expected px value.
The tabular output from recoverable_displacement_range_uncentered_demo.py follows:
| dx | kernel_margin offset | expected | found | match |
|---|---|---|---|---|
| 27 | -3 | (177,150) | (177,150) | True |
| 29 | -1 | (179,150) | (179,150) | True |
| 30 | +0 | (180,150) | (180,150) | True |
| 31 | +1 | (181,150) | (-179,150) | False |
| 33 | +3 | (183,150) | (-177,150) | False |
A sharp (right-side) cliff, exactly at dx == kernel_margin. The search_margin=180,
six times larger than kernel_margin, makes no difference at all.
Root Cause
dictk.translation.locate
zero-pads the kernel up to the search area's own size before the FFT
(see Correlation Criteria).
Until this page, that padding placed the kernel's real content at the
padded array's top-left corner — everything else, zero. FFT-based phase
correlation is circular: the shift it reports is only meaningful modulo
the array's own size, wrapping silently past that.
With the kernel
anchored at the corner instead of centered, the safe half of that
circle landed almost entirely on the negative side. The positive side
had almost none of it to spare — capped at exactly kernel_margin,
regardless of how large search_margin was set. Past that cap, locate
didn't fail visibly. It confidently returned a wrong PixelCoordinate,
offset from the true one by exactly the padded array's own width.
The Fix
Now let's use the fixed (updated/shipped) version of locate, which
centers the kernel's content within the padded array.
Consider again a point with reference configuration px.
Let kernel_margin = 30 and let search_margin = 45.
The recoverable range is now symmetric, bounded by search_margin in
both directions, exactly as the parameter's own name implies it
always should have been:
| dx | expected | found | match |
|---|---|---|---|
| 30 | (180,150) | (180,150) | True |
| 40 | (190,150) | (190,150) | True |
| 44 | (194,150) | (194,150) | True |
| 45 | (195,150) | (195,150) | True |
| 46 | (196,150) | (106,150) | False |
| -44 | (106,150) | (106,150) | True |
| -45 | (105,150) | (195,150) | False |
We now have success right up to the search_margin on the right:
- With
dx = 45,locatesuccessfully finds the correct value. - With
dx = 46,locatecycles back thesearch_margin, px, predicting , not the expected .
Similarly, on the left side of the search_margin:
- With
dx = -44,locatesuccessfully finds the correct value. - With
dx = -45,locatecycles forward thesearch_margin, px, predicting , not the expected .
Look closely at dx = 45 and dx = -45. One succeeds; the other fails.
That is not a contradiction of the symmetry claimed above — it is a
single, unavoidable edge case. In this circular system, and
land on the exact same point: they are px apart, and px is
the whole width of the padded array. locate cannot tell them apart.
It must pick one interpretation, and it happens to pick the positive
one. This one-pixel ambiguity is a property of representing a circle
with discrete arithmetic. It is not a bug.
The whole picture — point, kernel, search window, and the two
positions one pixel past the edge where locate wraps — drawn by
recoverable_displacement_range_the_fix_cliff.py
(full source at the bottom of this page):
Saved: recoverable_displacement_range_the_fix_cliff.png
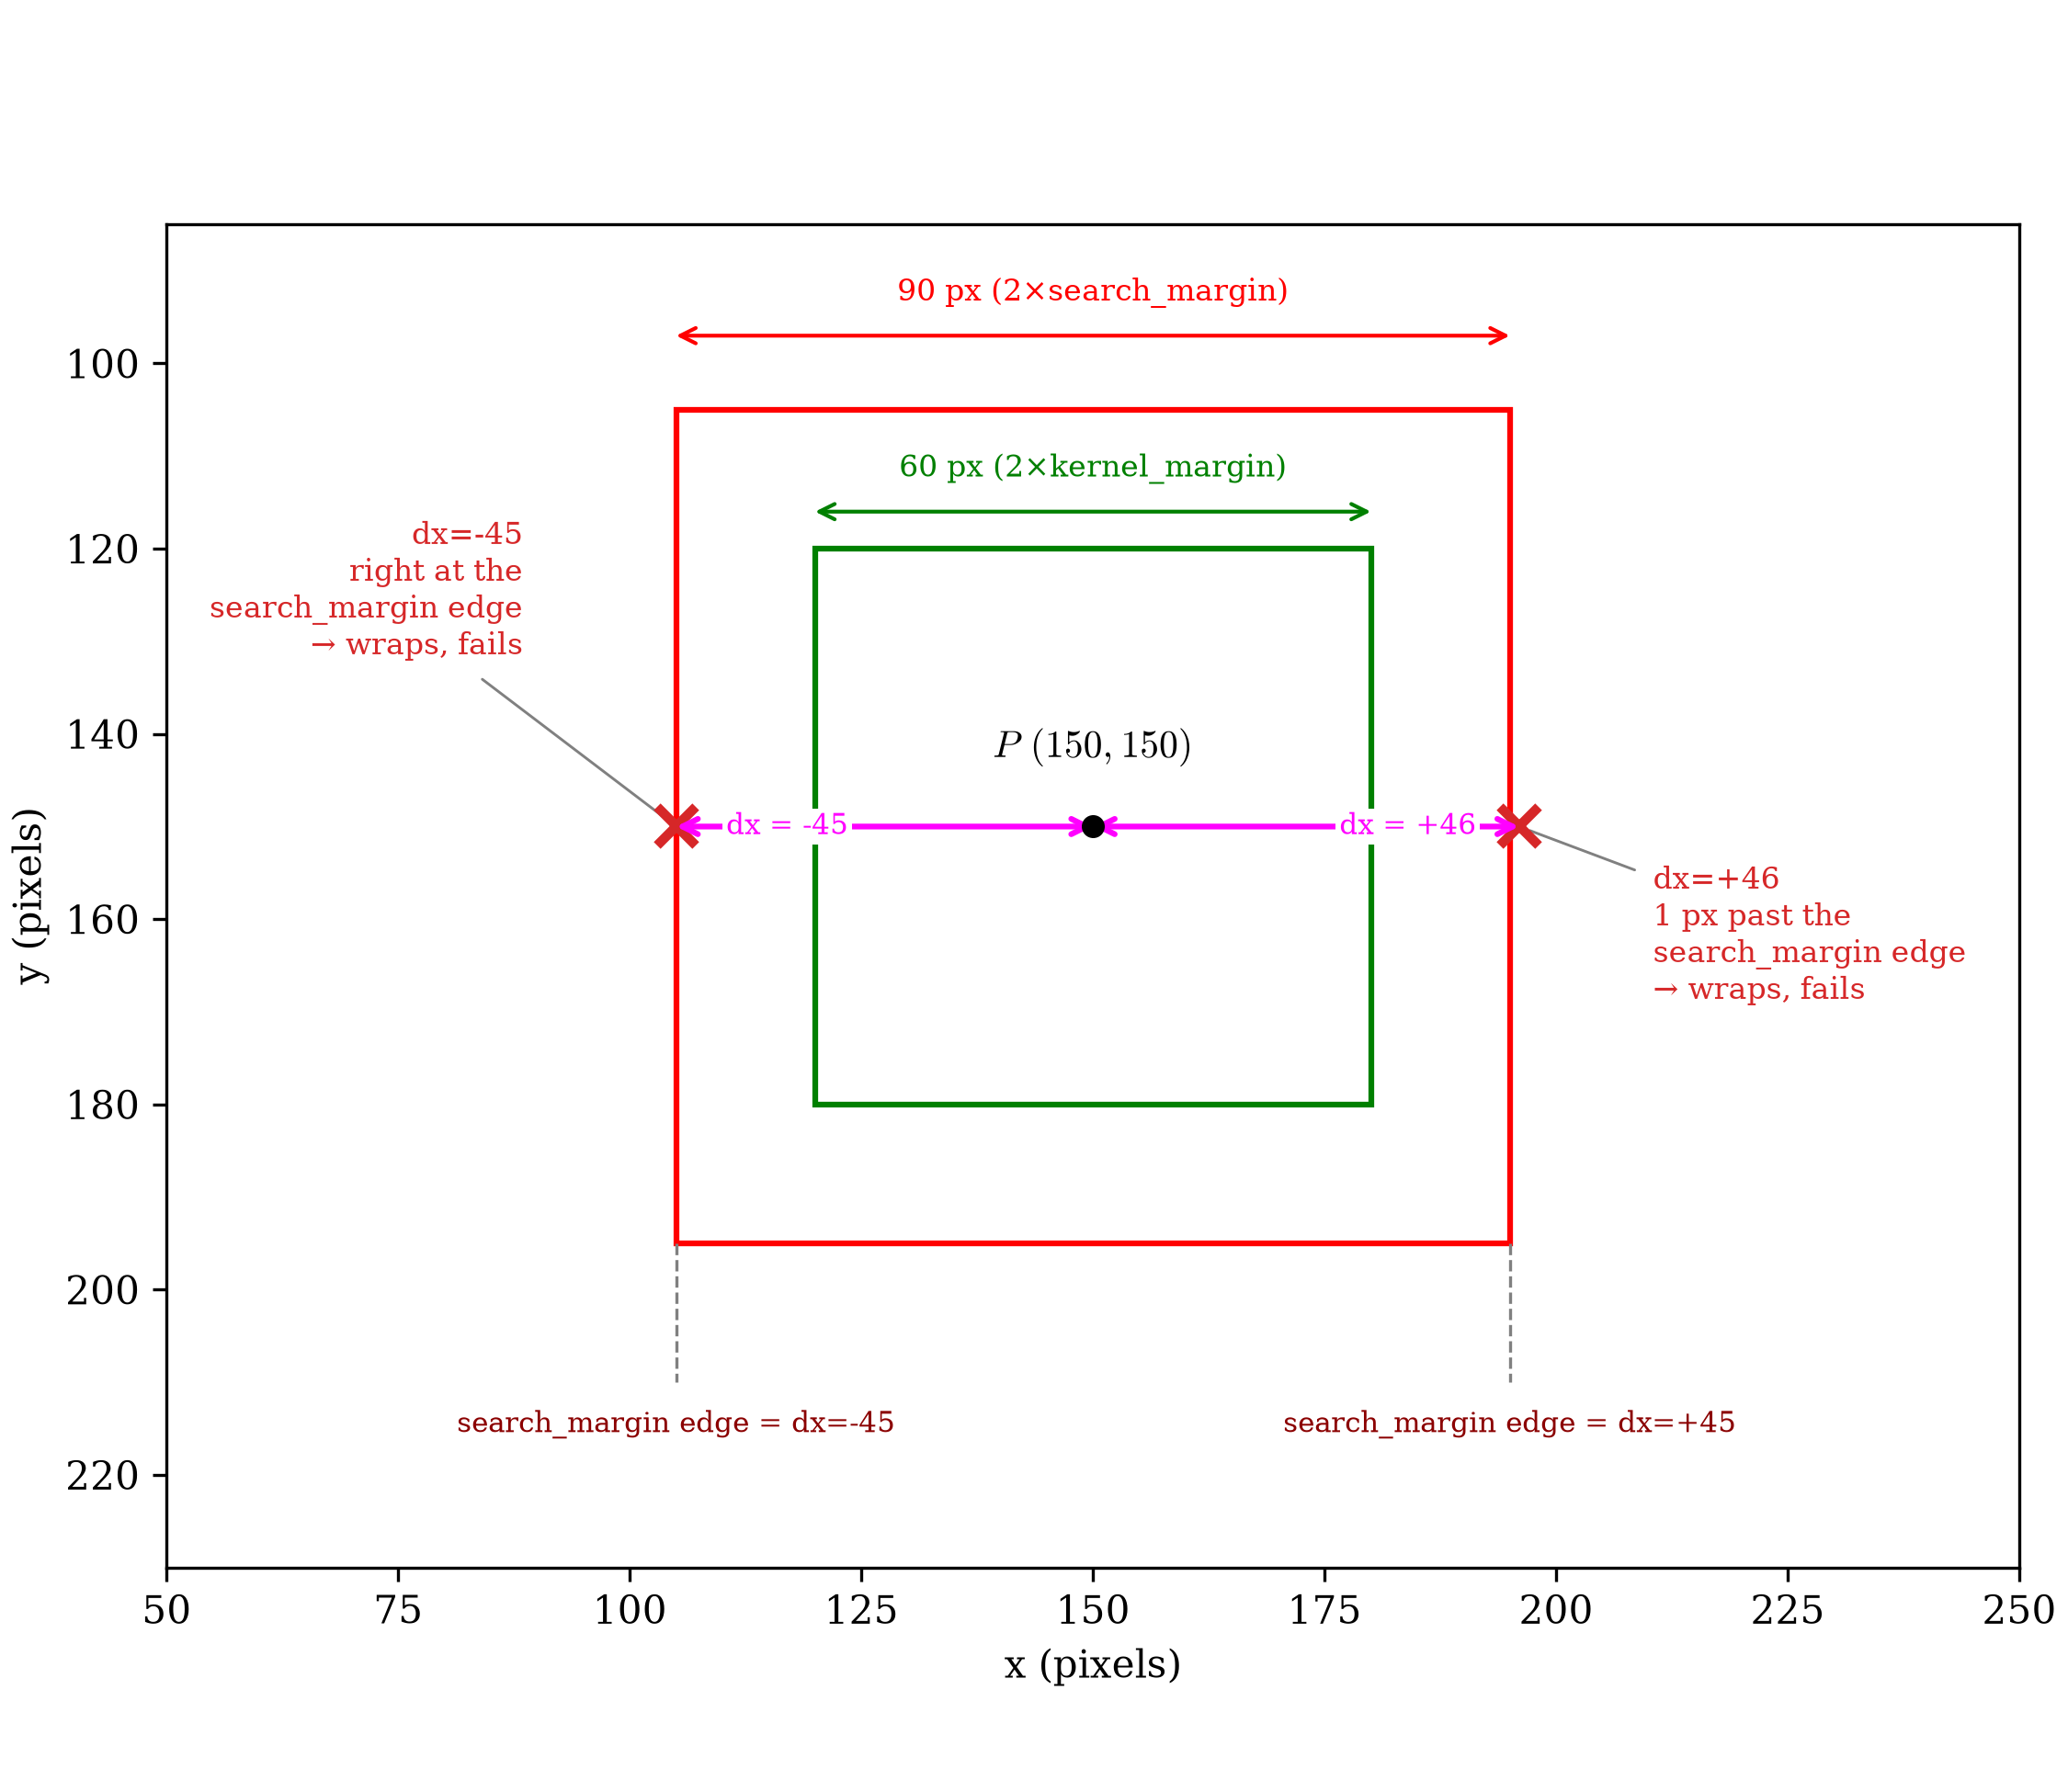
dx = -45 on the left, exactly at the search window's edge, and dx = +46 on the right, one pixel past it. At both (the red × marks), locate wraps and fails.Scope of the Fix
The old, single _window_and_pad helper did two separable jobs at
once: taper kernel/search toward zero (if windowing was given),
then zero-pad kernel up to search's own shape. Only the first job
ever needed the full search array; the second only ever read its
shape. Splitting them makes that honest: _window tapers both arrays
(unchanged from before), and _kernel_pad grows kernel up to a given
(height, width) — never search itself — gaining the centered
parameter this page is about. locate calls _kernel_pad with
centered=True.
phase_correlation —
the surface-visualization function behind every figure in Correlation
Visualization — keeps the old,
uncentered default. Every peak position already published there, all
well within the old safe range regardless of which convention computed
it, stays exactly as documented; nothing needed regenerating.
Correlation Criteria notes
the difference where its own teaching example reimplements this same
padding step.
What This Means in Practice
search_margin now means what it always should have: the full range a
true displacement can fall within, safely, in every direction. That's
progress, but it doesn't remove the underlying cost — a bigger unknown
displacement still needs a bigger search_margin, and a bigger
search_margin still means a bigger FFT at every point. Search Center
Predictions picks up exactly here: a
better initial guess than "zero displacement" shrinks how much
search_margin has to cover in the first place.
The original question — how far astronaut0 can actually be stretched
or compressed before locate breaks — is still open. This page didn't
answer it; it found and fixed something that had to be fixed first. The
interpolation confound flagged above is still there too. Both are
follow-up work, not resolved here.
recoverable_displacement_range_uncentered_demo.py
"""Reproduces `dictk.translation.locate`'s behavior before the fix
documented in Recoverable Displacement Range: kernel content anchored at
the padded array's top-left corner, not centered.

Runs live on every book build, not from a committed snapshot.
"""

from dictk.correlation import _kernel_pad, _window
from dictk.image import PixelCoordinate, read, subimage, translate
from skimage.registration import phase_cross_correlation


def locate_uncentered(
    reference_image,
    current_image,
    reference_point,
    search_center,
    kernel_margin,
    search_margin,
):
    kernel_origin = PixelCoordinate(
        x=reference_point.x - kernel_margin, y=reference_point.y - kernel_margin
    )
    kernel = subimage(
        image=reference_image,
        origin=kernel_origin,
        width=2 * kernel_margin,
        height=2 * kernel_margin,
    )
    search_origin = PixelCoordinate(
        x=search_center.x - search_margin, y=search_center.y - search_margin
    )
    search = subimage(
        image=current_image,
        origin=search_origin,
        width=2 * search_margin,
        height=2 * search_margin,
    )
    kernel, search = _window(kernel=kernel, search=search, windowing=None)
    kernel_padded, _, _ = _kernel_pad(kernel=kernel, shape=search.shape, centered=False)
    shift, _, _ = phase_cross_correlation(
        reference_image=search, moving_image=kernel_padded, normalization="phase"
    )
    return PixelCoordinate(
        x=search_origin.x + int(shift[1]) + kernel_margin,
        y=search_origin.y + int(shift[0]) + kernel_margin,
    )


if __name__ == "__main__":
    reference_image = read(path="astronaut0.png")
    p0 = PixelCoordinate(x=150, y=150)
    kernel_margin = 30
    search_margin = (
        180  # generous, fixed -- shouldn't matter, per the ratio result above
    )

    print("| dx | kernel_margin offset | expected | found | match |")
    print("|---|---|---|---|---|")
    for dx in [
        kernel_margin - 3,
        kernel_margin - 1,
        kernel_margin,
        kernel_margin + 1,
        kernel_margin + 3,
    ]:
        current_image = translate(arr=reference_image, dx=dx, dy=0)
        expected = PixelCoordinate(x=p0.x + dx, y=p0.y)
        found = locate_uncentered(
            reference_image, current_image, p0, p0, kernel_margin, search_margin
        )
        print(
            f"| {dx} | {dx - kernel_margin:+d} | ({expected.x},{expected.y}) | "
            f"({found.x},{found.y}) | {found == expected} |"
        )
recoverable_displacement_range_the_fix_cliff.py
"""Draws the reference point, its kernel (green), and its search window
(red) from The Fix in Recoverable Displacement Range, along with the
two positions one pixel past the search_margin edge where `locate`
wraps and fails.

Runs live on every book build, not from a committed snapshot.
"""

import matplotlib.patches as patches
import matplotlib.pyplot as plt

p0_x, p0_y = 150, 150
kernel_margin = 30
search_margin = 45

plt.rcParams.update({"font.family": "serif", "mathtext.fontset": "cm"})
fig, ax = plt.subplots(figsize=(7.5, 6.5), constrained_layout=True)

ax.plot(p0_x, p0_y, "o", color="black", markersize=5, zorder=8)
ax.annotate(
    "$P\\ (150, 150)$",
    (p0_x, p0_y),
    textcoords="offset points",
    xytext=(0, 18),
    ha="center",
    fontsize=10,
    zorder=9,
)

# kernel (green) and search window (red), same colors as cross_correlation.md
ax.add_patch(
    patches.Rectangle(
        (p0_x - kernel_margin, p0_y - kernel_margin),
        2 * kernel_margin,
        2 * kernel_margin,
        edgecolor="green",
        facecolor="none",
        linewidth=1.5,
        zorder=3,
    )
)
ax.add_patch(
    patches.Rectangle(
        (p0_x - search_margin, p0_y - search_margin),
        2 * search_margin,
        2 * search_margin,
        edgecolor="red",
        facecolor="none",
        linewidth=1.5,
        zorder=2,
    )
)

# two dx displacement lines, each with arrowheads at both its own ends,
# right at y=150 -- P's own row. Left: P to the dx=-45 marker. Right: P
# to the dx=+46 marker. Labels sit right on the line, in the gap between
# the kernel box and each marker, clear of the kernel box itself.
dx_y = p0_y
for x_start, x_end, label, label_x in [
    (p0_x - 45, p0_x, "dx = -45", 117),
    (p0_x, p0_x + 46, "dx = +46", 184),
]:
    ax.annotate(
        "",
        xy=(x_end, dx_y),
        xytext=(x_start, dx_y),
        arrowprops=dict(
            arrowstyle="<->", color="magenta", linewidth=1.5, shrinkA=0, shrinkB=0
        ),
        zorder=6,
    )
    ax.text(
        label_x,
        dx_y,
        label,
        ha="center",
        va="center",
        fontsize=7.5,
        color="magenta",
        zorder=7,
        bbox=dict(facecolor="white", edgecolor="none", pad=1),
    )

# one pixel past the search_margin edge, both sides -- where locate wraps
ax.plot(
    p0_x + 46, p0_y, "x", color="tab:red", markersize=10, markeredgewidth=2.5, zorder=4
)
ax.plot(
    p0_x - 45, p0_y, "x", color="tab:red", markersize=10, markeredgewidth=2.5, zorder=4
)
ax.annotate(
    "dx=+46\n1 px past the\nsearch_margin edge\n→ wraps, fails",
    (p0_x + 46, p0_y),
    textcoords="offset points",
    xytext=(35, -45),
    fontsize=8,
    ha="left",
    color="tab:red",
    arrowprops=dict(arrowstyle="-", color="gray", linewidth=0.7, shrinkA=3, shrinkB=3),
)
ax.annotate(
    "dx=-45\nright at the\nsearch_margin edge\n→ wraps, fails",
    (p0_x - 45, p0_y),
    textcoords="offset points",
    xytext=(-40, 45),
    fontsize=8,
    ha="right",
    color="tab:red",
    arrowprops=dict(arrowstyle="-", color="gray", linewidth=0.7, shrinkA=3, shrinkB=3),
)

# dimension arrows for both boxes -- kdim_y sits close to the kernel
# box's own top edge; sdim_y stays further out, above the search box
kdim_y, sdim_y = p0_y - kernel_margin - 4, p0_y - search_margin - 8
ax.annotate(
    "",
    xy=(p0_x - kernel_margin, kdim_y),
    xytext=(p0_x + kernel_margin, kdim_y),
    arrowprops=dict(arrowstyle="<->", color="green", shrinkA=0, shrinkB=0),
)
ax.text(
    p0_x,
    kdim_y - 3,
    "60 px (2×kernel_margin)",
    ha="center",
    va="bottom",
    fontsize=8,
    color="green",
)
ax.annotate(
    "",
    xy=(p0_x - search_margin, sdim_y),
    xytext=(p0_x + search_margin, sdim_y),
    arrowprops=dict(arrowstyle="<->", color="red", shrinkA=0, shrinkB=0),
)
ax.text(
    p0_x,
    sdim_y - 3,
    "90 px (2×search_margin)",
    ha="center",
    va="bottom",
    fontsize=8,
    color="red",
)

# guide lines from each search_margin edge down to a caption naming its dx value
caption_y = p0_y + search_margin + 18
for x_edge, sign in [(p0_x - search_margin, "-45"), (p0_x + search_margin, "+45")]:
    ax.plot(
        [x_edge, x_edge],
        [p0_y + search_margin, caption_y - 3],
        color="gray",
        linestyle="--",
        linewidth=0.8,
    )
    ax.text(
        x_edge,
        caption_y,
        f"search_margin edge = dx={sign}",
        ha="center",
        va="top",
        fontsize=7.5,
        color="darkred",
    )

ax.set_xlim(p0_x - search_margin - 55, p0_x + search_margin + 55)
ax.set_ylim(p0_y + search_margin + 35, sdim_y - 12)
ax.set_xlabel("x (pixels)")
ax.set_ylabel("y (pixels)")
ax.set_aspect("equal")

fig.savefig("recoverable_displacement_range_the_fix_cliff.png", dpi=300)
print("Saved: recoverable_displacement_range_the_fix_cliff.png")
recoverable_displacement_range_first_sweep_quadrant.py
"""Illustrates The First Sweep's cliff directly: a phase-correlation
quadrant figure for dx=30 (succeeds) and dx=31 (fails), the same
scenario as recoverable_displacement_range_first_sweep.py.

The correlation surface itself is always correct -- dictk.correlation.
phase_correlation() never wraps, confirmed separately. The bug lives in
locate_uncentered's downstream, skimage-based signed-shift conversion,
not in the surface. So each figure marks two positions on the Fixed
Image panel: the surface's own true peak (yellow dashed, unchanged from
phase_correlation_quadrant_plot's normal behavior), and where
locate_uncentered actually reports the point (magenta,
reported_position) -- for dx=30 the two coincide; for dx=31 the magenta
box lands entirely outside the visible search frame, off by exactly the
padded array's own width, matching Root Cause's description.

Runs live on every book build, not from a committed snapshot.
"""

from dictk.image import PixelCoordinate, read, subimage, translate
from dictk.plot import phase_correlation_quadrant_plot
from recoverable_displacement_range_uncentered_demo import locate_uncentered

if __name__ == "__main__":
    reference_image = read(path="astronaut0.png")
    p0 = PixelCoordinate(x=150, y=150)
    kernel_margin = 30
    search_margin = 150  # exactly half of astronaut0's 300px canvas --
    # search reads the whole image, no extraction-margin black of its
    # own, so the only black left is dx's own left-side gap

    kernel_origin = PixelCoordinate(x=p0.x - kernel_margin, y=p0.y - kernel_margin)
    kernel = subimage(
        image=reference_image,
        origin=kernel_origin,
        width=2 * kernel_margin,
        height=2 * kernel_margin,
    )
    search_origin = PixelCoordinate(x=p0.x - search_margin, y=p0.y - search_margin)

    for dx, label in [(30, "succeeds"), (31, "fails")]:
        current_image = translate(arr=reference_image, dx=dx, dy=0)
        search = subimage(
            image=current_image,
            origin=search_origin,
            width=2 * search_margin,
            height=2 * search_margin,
        )
        found = locate_uncentered(
            reference_image, current_image, p0, p0, kernel_margin, search_margin
        )
        # found is point-center convention (kernel_margin already added
        # back in); convert to the surface's own top-left-corner-of-
        # kernel-box, search-local convention to compare directly against
        # the surface's own peak.
        reported_local = PixelCoordinate(
            x=(found.x - kernel_margin) - search_origin.x,
            y=(found.y - kernel_margin) - search_origin.y,
        )
        path = f"recoverable_displacement_range_first_sweep_quadrant_dx{dx}.png"
        phase_correlation_quadrant_plot(
            kernel=kernel,
            search=search,
            title=f"Phase Correlation, Pre-Fix locate (dx={dx}, {label})",
            path=path,
            reported_position=reported_local,
            reported_position_label="locate_uncentered",
        )
        print(f"Saved: {path}\n")
recoverable_displacement_range_fixing_locate.py
r"""Fixing `locate`: re-runs The First Sweep's exact scenario and dx
values, this time against the real, shipped `dictk.translation.locate`
-- not `locate_uncentered` -- to show the fix directly, before the rest
of this page walks through why it was needed.

Same two reference frames as The First Sweep's own table: `current_image`'s
own absolute frame (what `locate` actually returns), and the local frame
of `search` itself, labeled "Fixed Image, frame $\mathcal{S}$" to match
Seeing the Cliff's quadrant figures above -- those figures aren't
redrawn here (they already show the pre-fix failure; this table shows
the post-fix success, numbers only).

Runs live on every book build, not from a committed snapshot. Raw HTML,
not markdown pipe-table syntax, for the same colspan reason The First
Sweep's own table needs it.
"""

from dictk.image import PixelCoordinate, read, translate
from dictk.translation import locate

if __name__ == "__main__":
    reference_image = read(path="astronaut0.png")
    p0 = PixelCoordinate(x=150, y=150)
    kernel_margin = 30
    search_margin = 150
    search_origin = PixelCoordinate(x=p0.x - search_margin, y=p0.y - search_margin)

    print("<table>")
    print("<thead>")
    print(
        '<tr><th rowspan="2">dx</th>'
        '<th colspan="2">current_image (absolute)</th>'
        '<th colspan="2">Fixed Image, frame $\\mathcal{S}$</th>'
        '<th rowspan="2">match</th></tr>'
    )
    print("<tr><th>expected</th><th>found</th><th>expected</th><th>found</th></tr>")
    print("</thead>")
    print("<tbody>")
    for dx in [0, 10, 20, 25, 29, 30, 31, 35, 40, 50]:
        current_image = translate(arr=reference_image, dx=dx, dy=0)
        expected = PixelCoordinate(x=p0.x + dx, y=p0.y)
        found = locate(
            reference_image=reference_image,
            current_image=current_image,
            reference_point=p0,
            search_center=p0,
            kernel_margin_width=kernel_margin,
            kernel_margin_height=kernel_margin,
            search_margin_width=search_margin,
            search_margin_height=search_margin,
        )
        expected_s = PixelCoordinate(
            x=(expected.x - kernel_margin) - search_origin.x,
            y=(expected.y - kernel_margin) - search_origin.y,
        )
        found_s = PixelCoordinate(
            x=(found.x - kernel_margin) - search_origin.x,
            y=(found.y - kernel_margin) - search_origin.y,
        )
        print(
            f"<tr><td>{dx}</td>"
            f"<td>({expected.x},{expected.y})</td><td>({found.x},{found.y})</td>"
            f"<td>({expected_s.x},{expected_s.y})</td><td>({found_s.x},{found_s.y})</td>"
            f"<td>{found == expected}</td></tr>"
        )
    print("</tbody>")
    print("</table>")
recoverable_displacement_range_fixing_locate_quadrant.py
"""Illustrates Fixing `locate`'s dx=31 row: the same phase-correlation
quadrant figure Seeing the Cliff drew for the pre-fix failure, this time
against the real, shipped `dictk.translation.locate`, with
`centered=True` -- the same centered kernel padding `locate` uses
internally now, via `_kernel_pad(..., centered=True)` -- instead of
`phase_correlation`'s own permanent bottom-right-only default.

Unlike Seeing the Cliff's dx=31 figure, the two boxes coincide here: the
surface's own true peak and locate's actual reported position agree,
since the fix is exactly what makes them agree past the old cliff.

Runs live on every book build, not from a committed snapshot.
"""

from dictk.image import PixelCoordinate, read, subimage, translate
from dictk.plot import phase_correlation_quadrant_plot
from dictk.translation import locate

if __name__ == "__main__":
    reference_image = read(path="astronaut0.png")
    p0 = PixelCoordinate(x=150, y=150)
    kernel_margin = 30
    search_margin = 150
    dx = 31

    kernel_origin = PixelCoordinate(x=p0.x - kernel_margin, y=p0.y - kernel_margin)
    kernel = subimage(
        image=reference_image,
        origin=kernel_origin,
        width=2 * kernel_margin,
        height=2 * kernel_margin,
    )
    search_origin = PixelCoordinate(x=p0.x - search_margin, y=p0.y - search_margin)
    current_image = translate(arr=reference_image, dx=dx, dy=0)
    search = subimage(
        image=current_image,
        origin=search_origin,
        width=2 * search_margin,
        height=2 * search_margin,
    )

    found = locate(
        reference_image=reference_image,
        current_image=current_image,
        reference_point=p0,
        search_center=p0,
        kernel_margin_width=kernel_margin,
        kernel_margin_height=kernel_margin,
        search_margin_width=search_margin,
        search_margin_height=search_margin,
    )
    # Same conversion The First Sweep's own table uses: found is
    # point-center convention (kernel_margin already added back in);
    # convert to the surface's own frame-S, search-local convention.
    reported_local = PixelCoordinate(
        x=(found.x - kernel_margin) - search_origin.x,
        y=(found.y - kernel_margin) - search_origin.y,
    )
    path = "recoverable_displacement_range_fixing_locate_quadrant_dx31.png"
    phase_correlation_quadrant_plot(
        kernel=kernel,
        search=search,
        title=f"Phase Correlation, Fixed locate (dx={dx}, succeeds)",
        path=path,
        reported_position=reported_local,
        reported_position_label="locate",
        centered=True,
    )
    print(f"Saved: {path}")
Pure Rotation
How large a rigid-body rotation angle can
dictk's correlation-based tracking actually recover before it breaks
down? Rigid Body Motion and the polar
decomposition (, see
Continuum Mechanics)
already separate rotation from stretch in theory — a pure rotation
carries zero strain by construction. This page starts checking that
against real tracking, not just the closed-form math.
The First Sweep
Reuse Point Grid's 12 points and
sweep rotate's angle upward. rotate pivots on the image's
top-left corner (0, 0), so each point's expected position after
rotation comes from the standard rotation matrix applied to its own
coordinate — not a fixed displacement, since points farther
from the pivot sweep a wider arc for the same angle. Size
search_margin_width/search_margin_height per angle so they always
comfortably contain the farthest point's displacement, the same
generous-margin approach Recoverable Displacement
Range used:
from dictk.image import read, rotate, PixelCoordinate
from dictk.grid import generate, locate
import numpy as np

reference_image = read(path="astronaut0.png")
points = generate(
    origin=PixelCoordinate(x=50, y=50), count_x=3, count_y=4, spacing_x=50, spacing_y=55
)
kernel_margin = 20

def expected_position(pt, angle_deg):
    theta = np.deg2rad(angle_deg)
    c, s = np.cos(theta), np.sin(theta)
    x = c * pt.x - s * pt.y
    y = s * pt.x + c * pt.y
    return PixelCoordinate(x=int(round(x)), y=int(round(y)))

for angle in [0.5, 1, 1.5, 2, 3, 5, 8, 15]:
    current_image = rotate(arr=reference_image, angle=angle)
    expected = [expected_position(pt, angle) for pt in points]
    max_disp = max(max(abs(e.x - pt.x), abs(e.y - pt.y)) for pt, e in zip(points, expected))
    search_margin = max(int(max_disp) + 15, kernel_margin + 10)
    found = locate(
        reference_image=reference_image, current_image=current_image, reference_points=points,
        kernel_margin_width=kernel_margin, kernel_margin_height=kernel_margin,
        search_margin_width=search_margin, search_margin_height=search_margin,
    )
    n_match = sum(1 for f, e in zip(found, expected) if f == e)
    print(f"{angle}deg  search_margin={search_margin}  matched={n_match}/12")
| Angle (deg) | search_margin | Matched |
|---|---|---|
| 0.5 | 30 | 12/12 |
| 1 | 30 | 12/12 |
| 1.5 | 30 | 11/12 |
| 2 | 30 | 9/12 |
| 3 | 30 | 6/12 |
| 5 | 34 | 1/12 |
| 8 | 46 | 0/12 |
| 15 | 76 | 0/12 |
Matching collapses even faster than Recoverable Displacement
Range's stretch
sweep did — well under half the points still match by 2 degrees, and
none do by 8 degrees. search_margin is generous at every angle here,
so window size isn't the constraint.
A likely reason: a large enough rotation doesn't just move a
point, it turns the kernel's own content around that point, and a
translation-only search can't follow content that's rotating, not just
sliding. The next two sections test that directly.
Confirming the Content-Rotation Hypothesis
Removing the Search Itself
The First Sweep's search_margin is generous, but it's still a guess —
locate still has to search for the right answer within that margin.
Remove that variable entirely: pass search_centers the true expected
position directly, so locate doesn't have to search at all, and shrink
the margin down to a fixed, minimal size:
| Angle (deg) | Matched |
|---|---|
| 0.5 | 12/12 |
| 1 | 12/12 |
| 1.5 | 11/12 |
| 2 | 9/12 |
| 3 | 7/12 |
| 5 | 0/12 |
| 8 | 0/12 |
| 15 | 0/12 |
Nearly the same collapse, at nearly the same angles, as the First
Sweep's generous-margin version. Handing locate the exact right
answer barely helps. Search mechanics — margin size, centering guesses
— were never the constraint.
Measuring Content Similarity Directly
If the search itself isn't the problem, the content being matched is.
Set that up as a direct measurement, with no search or locate call at
all: extract the kernel from reference_image at each point, extract
the same-sized patch from the rotated current_image at that point's
exact true position, and score their similarity with
dictk.correlation.zncc, which is exactly
1.0 for identical content and falls toward 0 (or negative) as content
diverges:
| Angle (deg) | Mean ZNCC | Min ZNCC |
|---|---|---|
| 0 | 1.000 | 1.000 |
| 0.5 | 0.968 | 0.939 |
| 1 | 0.965 | 0.948 |
| 1.5 | 0.940 | 0.879 |
| 2 | 0.909 | 0.861 |
| 3 | 0.860 | 0.800 |
| 5 | 0.736 | 0.669 |
| 8 | 0.545 | 0.408 |
| 15 | 0.249 | -0.184 |
Similarity falls off steeply and smoothly with angle, with zero search involved at all — this is the exact correct alignment, every time. By 8 degrees, mean similarity has already dropped to about half; by 15, some points score negative, meaning the rotated patch is anti-correlated with the original, not just a weaker match. That confirms the hypothesis directly: a rotated kernel's content genuinely stops resembling itself, at exactly the position where it should match perfectly. This isn't a search, margin, or centering-guess problem — it's that the content itself has changed shape.
One thing this doesn't separate out: rotate uses the same bilinear
interpolation as stretch, and Recoverable Displacement
Range
already found interpolation blur alone can cause a similar-looking
near-miss failure. A genuinely rotated feature (say, a straight edge
tilted a few degrees) looks different from the original even with
perfect, blur-free resampling — so both effects are likely compounding
here, not just one. Telling those two contributions apart is a
reasonable next step, not done yet.
Search Center Predictions
dictk.grid.locate's search_centers
parameter defaults to None, which means each point's own
reference_points entry doubles as its search center — a "zero
displacement" guess. Every worked example in this book relies on that
default. It works well here because every displacement used so far is
small relative to the search margin chosen to contain it.
Recoverable Displacement Range
establishes that the searchable range is bounded by search_margin
itself now, not by kernel_margin. That's good news — it's a real,
symmetric bound to design around — but it doesn't remove the underlying
tension: a bigger unknown displacement still needs a bigger
search_margin to contain it, and a bigger search_margin costs more
compute (a larger FFT, at every point). The zero-displacement guess is
the worst case for this: it forces search_margin to cover the entire
possible displacement, with no help from anything already known about
how the specimen is actually deforming.
A Better Guess
If some estimate of the deformation already exists — a coarse global DIC
pass, a prior loading step in a finite element analysis, or just a
reasonable assumption about how the specimen is expected to move — that
estimate can predict roughly where each point ended up, instead of
guessing zero displacement. A smaller search_margin then suffices,
since it only needs to cover how wrong that prediction might be, not
the full displacement itself.
The natural way to express such an estimate is a deformation gradient, the same Continuum Mechanics already defines — extended here to an affine map in homogeneous coordinates, so a single matrix carries both the linear part (stretch, rotation, shear) and a translation:
where is a point's reference position (in homogeneous form) and is its predicted current position — the search center to use, not the answer itself. This is not quite Continuum Mechanics' own : that one is purely linear (no translation, in 2D); this extends it to specifically so one matrix can express a rigid translation too, the same kind of motion Multi-Point Motion tracks.
The default should be — the identity:
Because , an identity
predicts zero displacement — exactly today's existing
default (search_centers=None ⟹ each point's own reference position).
Introducing this way changes nothing for every example
already in this book; it only adds a way to do better when a better
guess is available.
Not Implemented Yet
This is a real API change, not a small one, and it touches design questions this page doesn't resolve on its own:
- Where does apply —
grid.locateonly (a natural fit, since it already computes asearch_centerslist per call), or doestranslation.locate's single-point API need an equivalent? - If a caller supplies both
Fandsearch_centersexplicitly, which wins, or is that combination an error? - Applying an affine to a
PixelCoordinateis itself a small, independently testable piece — likely a new function indictk.image, alongsidetranslate/stretch, beforegrid.locateever calls it. - A worked example needs a source for that isn't
circular (an estimate close enough to be useful, but not so close it
trivializes what
locateis finding). Where that estimate comes from in practice is its own open question.
None of this is scoped or scheduled — this page records that the
direction exists and sketches its math, not a commitment to build it on
any timeline. Build it in pieces, each with its own tests, rather than
landing the whole API change at once: the small affine-transform helper
first, then wiring it into grid.locate behind the identity default,
then a worked example once both exist. See Path
Forward for the related "dynamic
search-window sizing" direction this connects to — a better
-based guess and a smaller search_margin are two sides
of the same idea.
Twelve points, twelve independent correlations, each one still sequential so far: Parallelization picks up from here.
Parallelization
Multi-Point Motion just ran 12
independent calls to
dictk.translation.locate — one
per point, each doing its own FFT-based phase correlation — to verify
every point's displacement. We anticipate the need to process a very
large number of point-to-point correspondences to support large-scale
DIC work — a real finite element mesh (see Finite Element
Method) can easily have thousands-to-millions
of nodes, not the 12 points in the simple grid above. Each point
correspondence is independent of every other: locating point never
reads or writes anything locating point touches. That independence
isn't just a convenient property to point out —
dictk.grid.locate is already written to
exploit it. Its entire body is a single map over reference_points, one
call to dictk.translation.locate
per point, accumulating no shared state between iterations:
return [
    translation.locate(
        reference_image=reference_image,
        current_image=current_image,
        reference_point=reference_point,
        search_center=search_center,
        kernel_margin_width=kernel_margin_width,
        kernel_margin_height=kernel_margin_height,
        search_margin_width=search_margin_width,
        search_margin_height=search_margin_height,
    )
    for reference_point, search_center in zip(reference_points, search_centers)
]
Because every iteration is already independent, parallelizing it is a
matter of swapping this list comprehension for a parallel map over the
same per-point calls. It is not a redesign.
dictk.grid.locate does exactly that
today, behind two extra keyword-only parameters: max_workers and
executor. Default max_workers=None stays sequential, the loop above,
byte-identical to locate's original behavior. A positive integer
switches to a worker pool instead.
Which pool, though, is not obvious. It needs its own explanation first.
Threads, Processes, and the GIL
CPython has a Global Interpreter Lock (GIL): only one thread can
execute Python bytecode at a time, even on a machine with many cores. A
plain Python for loop split across threads would not run any faster.
Each thread would still wait its turn for the same lock.
C extensions can release the GIL during their own C-level computation,
though. NumPy and SciPy both do this for many operations. The FFT
dictk.translation.locate actually runs is one of them —
skimage.registration.phase_cross_correlation calls scipy.fft.fftn
and scipy.fft.ifftn internally, not the Python-level fallback, and
scipy.fft releases the GIL for the duration of its own C computation.
So threads can run FFT correlations in true parallel. The GIL is not
held the whole time.
Whether that helps depends on scale. A tiny FFT finishes almost instantly. Most of the wall-clock time around it is Python-level overhead: function calls, object construction, array slicing. Releasing the GIL for a few microseconds does not buy much when the thread scheduling and GIL reacquisition around it cost microseconds too. A large FFT is different. Once the C computation itself dominates the call, the GIL-released fraction of wall-clock time dominates too, and threads start to pay off.
Threads vs. Processes: Two Different Costs
A ThreadPoolExecutor shares the caller's own memory. No pickling, no
process spawn. Cheap to start. But every task still pays a GIL
scheduling cost, and that cost does not shrink as task count grows. Run
one task or a million, each one pays it individually.
A ProcessPoolExecutor is different. Each worker is a separate OS
process, with its own interpreter and its own GIL. It gets true
parallelism regardless of whether the target function releases the GIL
at all. The cost moves elsewhere: data has to be pickled across the
process boundary, and on macOS (which spawns fresh interpreters rather
than forking) each worker re-imports NumPy, SciPy, and scikit-image
from scratch before it can do any work. That cost is mostly fixed and
paid once, when the pool starts.
That is the real asymmetry: processes pay once, threads pay every time. More tasks amortize a process pool's fixed startup cost. More tasks do not shrink a thread pool's per-task cost. Which one wins depends on both how big each task is and how many tasks there are — not on either alone.
Measuring the Trade Space
Rather than guess, measure.
parallelization_bench.py (full source
below) times sequential, threaded, and process-pool execution of
phase_cross_correlation across three scenarios. Correlation size and
point count are not independent in a real DIC problem — a
million-point mesh only makes sense with a small subset per point — so
this is three targeted scenarios, not one brute-force grid:
book_scale: this book's own kernel/search size (40 pixels), point count climbing from 100 to 1,000,000. Does point count alone ever create a crossover, at a size this small?large_subset: only 16 points, correlation size climbing from 200 to 2,000 pixels. Where does the threads crossover sit, as a function of size alone?realistic_mesh: a closer match to an actual finite element mesh — moderate correlation size (100 or 200 pixels), point count climbing from 1,000 to 100,000.
This sweep takes several minutes to run (the book_scale scenario's
1,000,000-point case alone runs over a minute) — far too slow to
re-run on every build the way this book's other figures do. Its results
are measured once and committed alongside the script that produced
them, not regenerated live. The table below still reads live from that
committed data, so it always matches the file on disk:
| Scenario | Size | Points | Sequential (s) | Threads (s) | Threads speedup | Processes (s) | Processes speedup |
|---|---|---|---|---|---|---|---|
| book_scale | 40 | 100 | 0.00752 | 0.02057 | 0.366x | 0.77663 | 0.01x |
| book_scale | 40 | 1000 | 0.07277 | 0.18621 | 0.391x | 0.99653 | 0.073x |
| book_scale | 40 | 10000 | 0.70866 | 1.83165 | 0.387x | 2.06538 | 0.343x |
| book_scale | 40 | 100000 | 7.16526 | 18.32857 | 0.391x | 14.26206 | 0.502x |
| book_scale | 40 | 1000000 | 71.65412 | 169.90165 | 0.422x | 116.62403 | 0.614x |
| large_subset | 200 | 16 | 0.01608 | 0.0087 | 1.847x | 0.83688 | 0.019x |
| large_subset | 500 | 16 | 0.10876 | 0.02691 | 4.041x | 0.82919 | 0.131x |
| large_subset | 1000 | 16 | 0.46973 | 0.10719 | 4.382x | 0.99717 | 0.471x |
| large_subset | 2000 | 16 | 2.2572 | 0.50896 | 4.435x | 2.85197 | 0.791x |
| realistic_mesh | 100 | 1000 | 0.26763 | 0.24035 | 1.114x | 0.8058 | 0.332x |
| realistic_mesh | 100 | 10000 | 2.6885 | 2.45357 | 1.096x | 2.13847 | 1.257x |
| realistic_mesh | 100 | 100000 | 26.81134 | 24.32667 | 1.102x | 15.24042 | 1.759x |
| realistic_mesh | 200 | 1000 | 0.95522 | 0.34662 | 2.756x | 1.02504 | 0.932x |
| realistic_mesh | 200 | 10000 | 9.59174 | 3.43856 | 2.789x | 4.41874 | 2.171x |
| realistic_mesh | 200 | 100000 | 98.60379 | 31.72111 | 3.108x | 36.23009 | 2.722x |
spawn start method). Solid lines are measured data. Dashed lines are trend extrapolations — a straight-line time-vs-point-count fit, projected out to 106, 109, and 1012 points. Top: at this book's own 40-pixel scale, sequential wins at every point count tested, up to 1,000,000, and the trend predicts it keeps winning — processes plateau near 0.62x, threads near 0.42x, even out to a trillion points. Middle: at only 16 points, threads win decisively once correlations are large enough; processes never recover their fixed startup cost. Not extrapolated: this panel's x-axis is correlation size, not point count, and a subset a billion pixels wide isn't physical. Bottom: with enough points, both help, and processes close the gap on threads as point count grows; the trend predicts each pair levels off close to its last measured value.Four findings, read directly off that data:
- At this book's own scale, sequential always wins. 1,000,000 points at 40 pixels still favors sequential (71.7s) over both threads (169.9s) and processes (116.6s). Point count alone never creates a crossover at this size — not at 100 points, not at a million.
- Few points, large correlations: threads win, processes cannot recover. At 2,000 pixels with only 16 points, threads reach 4.4x. Processes reach only 0.79x — still slower than sequential. Sixteen tasks is not enough to amortize a process pool's fixed startup cost, no matter how large each individual task is.
- Many points, moderate correlations: processes catch up, and can pass threads. At 100 pixels, processes start behind threads (0.33x vs. 1.11x at 1,000 points) but overtake them by 100,000 points (1.76x vs. 1.10x). More tasks keep amortizing a process pool's fixed cost long after a thread pool's per-task cost has stopped improving.
- The trend, extrapolated to Path Forward's north-star scale,
predicts a plateau, not a crossover. Fitting a straight line to
each method's measured time-vs-point-count and reading off the
resulting speedup ratio at 106, 109, and
1012 points:
book_scale's ordering never flips (processes settle near 0.62x, threads near 0.42x, both still slower than sequential);realistic_mesh's pairs settle close to their last measured value (size=100: threads 1.10x, processes 1.84x; size=200: threads 3.13x, processes 2.78x). This is a linear extrapolation from a handful of measured points, not a new measurement — a hypothesis worth testing at real scale, not a settled result.
Using max_workers
dictk.grid.locate accepts max_workers and executor directly now,
no sketch required. Run it against the same 12-point grid Multi-Point
Motion already tracked,
sequential and concurrent side by side:
from dictk.grid import Executor, locate

sequential = locate(
    reference_image=reference_image,
    current_image=current_image,
    reference_points=points,
    kernel_margin_width=20,
    kernel_margin_height=20,
    search_margin_width=48,
    search_margin_height=52,
)
threaded = locate(
    reference_image=reference_image,
    current_image=current_image,
    reference_points=points,
    kernel_margin_width=20,
    kernel_margin_height=20,
    search_margin_width=48,
    search_margin_height=52,
    max_workers=4,
    executor=Executor.THREAD,
)
print(f"results match: {sequential == threaded}")
results match: True
The results match, as they must — max_workers changes how the 12
points are tracked, not what answer each one finds. It does not change
the runtime in any way worth showing here, either. Twelve points at 40
pixels is deep in the book_scale regime above: sequential wins.
Demonstrating correctness at this scale, not speed, is the honest thing
to show.
Choosing an Executor
Given the measured trade space, not a guess:
- This book's own examples (small kernels, small search areas):
don't parallelize at all. Leave
max_workers=None. Sequential wins here regardless of point count. - Few points, each with a large correlation:
Executor.THREAD. Processes cannot recover their fixed cost across only a handful of tasks, no matter how large each one is. - Many points, each with a moderate-to-large correlation (the
closest match to a real finite element mesh): either pool helps;
Executor.PROCESScloses the gap on threads as point count grows, and can pass it. - Unsure which regime a problem falls in?
Executor.THREADislocate's default for exactly this reason. It is never catastrophically worse than sequential, unlike a process pool at low point counts, even though it is not always the fastest option available.
parallelization_bench.py
"""Benchmark: sequential vs. threads vs. processes for
skimage.registration.phase_cross_correlation, at varying correlation
sizes and call counts.

Not part of the dictk package -- a standalone, one-time measurement
script, matching the convention simple_shear.py already sets. Its
output (parallelization_bench.csv, parallelization_bench.png) is
committed alongside it rather than regenerated on every book build: the
full sweep takes several minutes (the 1,000,000-call case alone runs
over a minute), far too slow for the live cmdrun re-execution every
other figure in this book uses. Parallelization.md prints this script's
full source inline (see its own "parallelization_bench.py" section) so
the numbers stay checkable even though they are not live.

Must be a real module, not `python3 -c` -- ProcessPoolExecutor needs a
real, importable, top-level function to hand to spawned workers, the
same constraint dictk.grid._locate_worker exists for.

Re-run with: python3 parallelization_bench.py
"""

import csv
import os
import time
from concurrent.futures import ProcessPoolExecutor, ThreadPoolExecutor

import matplotlib.pyplot as plt
import numpy as np
from skimage.registration import phase_cross_correlation

WORKERS = os.cpu_count()

CSV_PATH = "parallelization_bench.csv"
FIGURE_PATH = "parallelization_bench.png"

# Point count and correlation size are not independent in a real DIC
# problem -- a million-point mesh only makes sense with small subsets
# per point. Three scenarios instead of one brute-force grid, each
# answering a different question:
SCENARIOS = {
    # This book's own teaching scale (kernel/search sizes throughout
    # Single/Multi-Point Motion). Does point count alone ever create a
    # crossover, at a size this small?
    "book_scale": [(40, n) for n in [100, 1_000, 10_000, 100_000, 1_000_000]],
    # Few points, growing correlation size. Where does the threads
    # crossover actually sit, as a function of size alone?
    "large_subset": [(size, 16) for size in [200, 500, 1000, 2000]],
    # A more realistic finite element mesh: moderate subset size,
    # climbing point count. Does the processes-vs-threads balance shift
    # as point count grows?
    "realistic_mesh": [(100, n) for n in [1_000, 10_000, 100_000]]
    + [(200, n) for n in [1_000, 10_000, 100_000]],
}


def one(args: tuple[np.ndarray, np.ndarray]):
    """One correlation. Module-level and single-positional-argument on
    purpose -- see the module docstring."""
    kernel, search = args
    return phase_cross_correlation(kernel, search, normalization="phase")


def make_args(size: int, n_calls: int, seed: int = 42):
    """`n_calls` copies of the same random kernel/search pair at `size`.

    The same pair repeated, not `n_calls` distinct random pairs: this
    benchmark measures call overhead, not correlation accuracy, so
    identical inputs keep every call's own work identical too."""
    rng = np.random.default_rng(seed)
    kernel = rng.random((size, size))
    search = rng.random((size, size))
    return [(kernel, search)] * n_calls


def time_sequential(args) -> float:
    t0 = time.perf_counter()
    for x in args:
        one(x)
    return time.perf_counter() - t0


def time_threads(args) -> float:
    t0 = time.perf_counter()
    with ThreadPoolExecutor(max_workers=WORKERS) as pool:
        list(pool.map(one, args))
    return time.perf_counter() - t0


def time_processes(args) -> float:
    t0 = time.perf_counter()
    with ProcessPoolExecutor(max_workers=WORKERS) as pool:
        list(pool.map(one, args))
    return time.perf_counter() - t0


def run_case(scenario: str, size: int, n_calls: int, writer: csv.DictWriter) -> None:
    args = make_args(size, n_calls)

    sequential_s = time_sequential(args)
    threads_s = time_threads(args)
    processes_s = time_processes(args)

    writer.writerow(
        {
            "scenario": scenario,
            "size": size,
            "n_calls": n_calls,
            "workers": WORKERS,
            "sequential_s": round(sequential_s, 5),
            "threads_s": round(threads_s, 5),
            "processes_s": round(processes_s, 5),
            "threads_speedup": round(sequential_s / threads_s, 3),
            "processes_speedup": round(sequential_s / processes_s, 3),
        }
    )
    print(
        f"[{scenario}] size={size:5d} n={n_calls:8d}  "
        f"sequential={sequential_s:8.3f}s  "
        f"threads={threads_s:8.3f}s (x{sequential_s / threads_s:5.2f})  "
        f"processes={processes_s:8.3f}s (x{sequential_s / processes_s:5.2f})",
        flush=True,
    )


def run_sweep() -> None:
    fieldnames = [
        "scenario",
        "size",
        "n_calls",
        "workers",
        "sequential_s",
        "threads_s",
        "processes_s",
        "threads_speedup",
        "processes_speedup",
    ]
    with open(CSV_PATH, "w", newline="") as f:
        writer = csv.DictWriter(f, fieldnames=fieldnames)
        writer.writeheader()
        for scenario, cases in SCENARIOS.items():
            for size, n_calls in cases:
                run_case(scenario, size, n_calls, writer)
                f.flush()
    print(f"\nWrote {CSV_PATH}")


# Point counts to extrapolate speedup trends out to, tying directly to
# the "north star" scale in Path Forward (billions of correlations,
# staying under a trillion by design). Only scenarios whose x-axis is
# point count (book_scale, realistic_mesh) get this treatment --
# large_subset's x-axis is correlation *size*, and extrapolating a
# subset's side length out to a billion pixels isn't physical.
EXTRAPOLATION_TARGETS = [1_000_000, 1_000_000_000, 1_000_000_000_000]


def _trend_line(ns, seq_times, other_times, targets):
    """Fit a linear time-vs-n trend (time = a*n + b) to `seq_times` and
    `other_times` independently, then extrapolate the *speedup ratio*
    (their fitted-time ratio) out to every target beyond the last real
    data point.

    Returns `(xs, speedups, marks)`: `xs`/`speedups` start at the last
    *measured* point (so a plotted dashed line picks up exactly where
    the solid measured line ends, no visual gap) and run through every
    target; `marks` is just the subset of targets genuinely beyond the
    measured range, for placing "predicted value" markers.
    """
    a_seq, b_seq = np.polyfit(ns, seq_times, 1)
    a_other, b_other = np.polyfit(ns, other_times, 1)
    last_n = ns[-1]
    marks = [t for t in targets if t > last_n]
    xs = [last_n] + marks
    speedups = [(a_seq * n + b_seq) / (a_other * n + b_other) for n in xs]
    return xs, speedups, marks


def _add_trend(ax, ns, seq_times, other_times, color):
    xs, speedups, marks = _trend_line(ns, seq_times, other_times, EXTRAPOLATION_TARGETS)
    ax.plot(xs, speedups, linestyle="--", color=color, linewidth=1.2)
    mark_speedups = speedups[-len(marks) :] if marks else []
    ax.plot(
        marks,
        mark_speedups,
        linestyle="none",
        marker="x",
        color=color,
        markersize=7,
        markeredgewidth=1.5,
    )
    for n, s in zip(marks, mark_speedups):
        ax.annotate(
            f"{s:.2f}x",
            (n, s),
            textcoords="offset points",
            xytext=(4, 4),
            fontsize=7,
            color=color,
        )


def plot_summary() -> None:
    with open(CSV_PATH) as f:
        rows = list(csv.DictReader(f))

    with plt.rc_context({"font.family": "serif", "mathtext.fontset": "cm"}):
        fig, axes = plt.subplots(3, 1, figsize=(7, 15), constrained_layout=True)

        panels = [
            (
                axes[0],
                "book_scale",
                "n_calls",
                "point count (size=40 fixed)",
                "log",
                True,
            ),
            (
                axes[1],
                "large_subset",
                "size",
                "correlation size (n=16 fixed)",
                "linear",
                False,
            ),
            (
                axes[2],
                "realistic_mesh",
                "n_calls",
                "point count (size=100 or 200)",
                "log",
                True,
            ),
        ]
        for ax, scenario, xkey, xlabel, xscale, extrapolate in panels:
            data = [r for r in rows if r["scenario"] == scenario]
            if scenario == "realistic_mesh":
                for size, marker in [("100", "o"), ("200", "s")]:
                    sub = [r for r in data if r["size"] == size]
                    xs = [int(r[xkey]) for r in sub]
                    ax.plot(
                        xs,
                        [float(r["threads_speedup"]) for r in sub],
                        marker=marker,
                        color="tab:blue",
                        label=f"threads (size={size})",
                    )
                    ax.plot(
                        xs,
                        [float(r["processes_speedup"]) for r in sub],
                        marker=marker,
                        color="tab:orange",
                        label=f"processes (size={size})",
                    )
                    if extrapolate:
                        seq = [float(r["sequential_s"]) for r in sub]
                        thr = [float(r["threads_s"]) for r in sub]
                        proc = [float(r["processes_s"]) for r in sub]
                        _add_trend(ax, xs, seq, thr, "tab:blue")
                        _add_trend(ax, xs, seq, proc, "tab:orange")
            else:
                xs = [int(r[xkey]) for r in data]
                ax.plot(
                    xs,
                    [float(r["threads_speedup"]) for r in data],
                    marker="o",
                    color="tab:blue",
                    label="threads",
                )
                ax.plot(
                    xs,
                    [float(r["processes_speedup"]) for r in data],
                    marker="o",
                    color="tab:orange",
                    label="processes",
                )
                if extrapolate:
                    seq = [float(r["sequential_s"]) for r in data]
                    thr = [float(r["threads_s"]) for r in data]
                    proc = [float(r["processes_s"]) for r in data]
                    _add_trend(ax, xs, seq, thr, "tab:blue")
                    _add_trend(ax, xs, seq, proc, "tab:orange")
            ax.axhline(
                1.0,
                color="black",
                linestyle="--",
                linewidth=1,
                label="sequential (baseline)",
            )
            ax.set_xscale(xscale)
            if extrapolate:
                # Headroom so the rightmost "N.NNx" annotation (at the
                # 10^12 target) doesn't clip against the panel edge.
                ax.set_xlim(right=ax.get_xlim()[1] * 3)
            ax.set_xlabel(xlabel)
            ax.set_ylabel("speedup vs sequential")
            ax.set_title(scenario)
            handles, labels = ax.get_legend_handles_labels()
            if extrapolate:
                from matplotlib.lines import Line2D

                handles += [
                    Line2D(
                        [0],
                        [0],
                        color="gray",
                        marker="o",
                        linestyle="-",
                        label="measured",
                    ),
                    Line2D(
                        [0],
                        [0],
                        color="gray",
                        marker="x",
                        linestyle="--",
                        label="trend (extrapolated)",
                    ),
                ]
            ax.legend(handles=handles, fontsize=7)

        fig.savefig(FIGURE_PATH, dpi=300)
        plt.close(fig)
    print(f"Wrote {FIGURE_PATH}")


if __name__ == "__main__":
    run_sweep()
    plot_summary()
Subpixel Accuracy
dictk.translation.locate's
own docstring has said this from the start: "Integer-pixel precision
only; subpixel refinement is out of scope for now." Simple Stretch
Revisited found the
concrete case where that limitation actually bites. At VIC-2D's own
point density — 5 pixels apart — most points' true stretched position
isn't an integer at all. locate can only ever report a whole pixel,
so it's necessarily wrong by some amount for those points. That's not
a tracking failure. It's the wrong question being asked.
What locate Actually Rounds Away
skimage.registration.phase_cross_correlation, the FFT-based
correlation locate runs, doesn't only find whole-pixel peaks. Its own
upsample_factor parameter refines that peak to within 1 / upsample_factor of a pixel. locate never uses it — every result gets
truncated to the nearest whole pixel with int() before it's returned.
dictk.translation.locate_subpixel
and its batch counterpart,
dictk.grid.locate_subpixel,
are new, separate functions — not a parameter added to locate itself,
so locate's own return type never changes shape based on an argument.
They pass upsample_factor straight through, and return the refined
position directly, undiscarded, as a
dictk.image.SubpixelCoordinate
— the same (x, y) shape as PixelCoordinate, but float, not int.
Measuring the Difference
Reusing Simple Stretch Revisited's own scenario — astronaut0.png,
factor_x = 1.02 — at VIC-2D's own 5-pixel spacing across the whole
image, 2862 points:
from dictk.grid import generate, locate, locate_subpixel

points = generate(
    origin=PixelCoordinate(x=18, y=16),
    count_x=53,
    count_y=54,
    spacing_x=5,
    spacing_y=5,
)
true_x = [point.x * factor_x for point in points]

integer_found = locate(
    reference_image=reference_image,
    current_image=current_image,
    reference_points=points,
    kernel_margin_width=20,
    kernel_margin_height=20,
    search_margin_width=48,
    search_margin_height=52,
)
subpixel_found = locate_subpixel(
    reference_image=reference_image,
    current_image=current_image,
    reference_points=points,
    kernel_margin_width=20,
    kernel_margin_height=20,
    search_margin_width=48,
    search_margin_height=52,
    upsample_factor=10,
)
| Method | Mean abs error (px) | Max abs error (px) |
|---|---|---|
locate() (integer, truncated) | 0.2627 | 0.5600 |
locate_subpixel(upsample_factor=1) | 0.2627 | 0.5600 |
locate_subpixel(upsample_factor=10) | 0.0940 | 0.2600 |
locate_subpixel(upsample_factor=100) | 0.0885 | 0.2600 |
locate() lands on the exact expected integer pixel for 1479/2862 points (52%) — the same interpolation confound Simple Stretch Revisited found and worked around, not a new one.
upsample_factor=1 matches locate's own error exactly — no
refinement requested, none applied. upsample_factor=10 cuts the mean
error by roughly a third. upsample_factor=100 barely improves on
10 — diminishing returns past that point, for this scenario.
Why This Isn't "Fixing" the Exact-Match Problem
upsample_factor does not make locate's own truncated answer more
often correct. If the true target is 64.26, no amount of refinement
turns that into a whole number — locate_subpixel reports something
close to 64.26 itself, not 64 or 65 more reliably. Simple
Stretch Revisited
solved a different problem: it kept every point's restricted to
values where the true target genuinely is an integer, so locate
could report it exactly. This page accepts that most targets, at this
density, aren't integers at all, and asks how close tracking gets to
the real one instead. Two different, both legitimate, answers to the
same density problem.
This closes Path Forward's own
Postponed subpixel-accuracy item — real displacements don't land on
exact pixels, and now dictk has a way to track them without
pretending otherwise. High Point
Density picks this up next, at a density
Simple Stretch Revisited's own integer-safety constraint couldn't
reach.
High Point Density
Simple Stretch Revisited
capped out at 250 points — the most x values that stay integer-safe
at factor_x = 1.02, within the image's own margins. Subpixel
Accuracy removed that ceiling: once tracking
doesn't need its answer to be a whole pixel, x doesn't need to be a
multiple of 50 either. This page pushes all the way to VIC-2D's own
density — 5 pixels apart, the same 53x54, 2862-point grid Verification
Against VIC-2D and
Subpixel Accuracy both already used.
Tracking at Full Density
Verification Against VIC-2D
noted VIC-2D's own kernel size: 25 x 25 px. Earlier pages' tracking
calls all used a much larger, generously-sized kernel and search area,
never tuned to match. Here, matching VIC-2D's own geometry is the point,
so kernel_margin_width/kernel_margin_height target VIC-2D's 25 x 25 as closely as a whole-pixel margin allows.
The closest whole-pixel match, kernel_margin = 12 (a 24 x 24 px
kernel), was tried first and rejected: checked directly against each
point's own known true position, it produced real mismatches at several
points — not sub-pixel noise, but tracking landing several pixels from
the right answer entirely. A 24 x 24 px window is apparently too
small, at this image's own speckle density, to always contain enough
distinctive texture for a unique correlation match. kernel_margin = 13
(26 x 26 px, one pixel larger than VIC-2D's own kernel) tracks cleanly
— zero mismatches across all 2862 points. VIC-2D's own search area size
isn't published; search_margin = 25 (a generous 50 x 50 px) is
chosen for headroom, not to match an unknown number. One more change
from earlier pages: upsample_factor = 100, not Subpixel
Accuracy's own 10 —
Distribution Across the Full Mesh
below explains why this page needs the finer value even though that one
didn't:
from dictk.grid import generate, locate_subpixel

points = generate(
    origin=PixelCoordinate(x=18, y=16),
    count_x=53,
    count_y=54,
    spacing_x=5,
    spacing_y=5,
)
found = locate_subpixel(
    reference_image=reference_image,
    current_image=current_image,
    reference_points=points,
    kernel_margin_width=13,
    kernel_margin_height=13,
    search_margin_width=25,
    search_margin_height=25,
    upsample_factor=100,
)
2862 points tracked
Strain at Full Density
Same recipe as Simple Stretch Revisited: dictk.grid.elements
for connectivity (2756 elements this time, not 196), then
gauss_point_log_strains/gauss_point_coordinates
at each of the resulting 11024 Gauss points. Node numbers stay off —
2862 of them would be unreadable. element_strain_plot's default
marker size (s=150) was sized for sparse meshes; at 5px point
spacing it draws neighboring Gauss points as one solid overlapping
mass, not a legible field. dot_size=6 keeps individual markers from
overlapping, and marker="s" (square, not the default circle) tiles
them edge to edge with no gaps — circles, even sized to just touch,
leave small diamond-shaped gaps at their corners, since tangent circles
never fully cover a plane. show_mesh_lines=False drops the element
outlines too — at this density the black grid lines fight the colored
points for attention without adding information, and the tiled squares
already read as a continuous field on their own:
from dictk.element import gauss_point_coordinates, gauss_point_log_strains
from dictk.grid import elements
from dictk.plot import element_strain_plot

element_indices = elements(count_x=53, count_y=54)
values = []
coordinates = []
for element in element_indices:
    reference_corners = [points[i] for i in element]
    current_corners = [found[i] for i in element]
    strains = gauss_point_log_strains(
        reference_points=reference_corners, current_points=current_corners
    )
    values.extend(strain[0, 0] for strain in strains)
    coordinates.extend(gauss_point_coordinates(points=current_corners))

element_strain_plot(
    points=found,
    elements=element_indices,
    coordinates=coordinates,
    values=values,
    label=r"Log Strain, $E_{11}$",
    dot_size=6,
    marker="s",
    show_mesh_lines=False,
    path="high_point_density_strain_gauss_points.png",
)
element_strain_plot(
    points=found,
    elements=element_indices,
    coordinates=coordinates,
    values=values,
    label=r"Log Strain, $E_{11}$",
    dot_size=6,
    marker="s",
    show_mesh_lines=False,
    image=current_image,
    path="high_point_density_strain_on_current.png",
)
current_image.Verification Against VIC-2D's
own field image has a fixed colorbar, 17560 to 22360 microstrain —
and its own particular 16-band color scale, not a generic rainbow.
Sampled directly from that image's own legend (not approximated by a
built-in colormap name), the same 16 colors, forced onto dictk's own
field at the same vmin/vmax, make the two directly comparable:
dictk's own
; both `17560`-`22360` microstrain, both VIC-2D's own
16-band color scale, sampled directly from its own legend). Most of
dictk's own field falls outside that range entirely —
only 9.5% of its 11024 Gauss points land inside `[17560, 22360]`;
52.9% are below it (solid magenta, clipped to the scale's own
floor) and 37.7% are above it (solid red, clipped to the ceiling).
The vertical striations survive the clipping — visible as bands of
solid red against solid magenta — but the color variety VIC-2D's
own field shows is gone, since almost none of dictk's
own values actually sit inside the narrow band VIC-2D's field
stays within.Show the figure-generating code
from dictk.plot import element_strain_plot
from matplotlib.colors import ListedColormap
import numpy as np

# Sampled directly from VIC-2D's own colorbar image -- its own 16
# discrete color bands, magenta (low) to red (high), not a generic
# rainbow colormap standing in for it.
vic2d_colors = [
    (0.8314, 0.0000, 1.0000),
    (0.5176, 0.0000, 1.0000),
    (0.1843, 0.0000, 1.0000),
    (0.0000, 0.1333, 1.0000),
    (0.0000, 0.4510, 1.0000),
    (0.0000, 0.7843, 1.0000),
    (0.0000, 1.0000, 0.8980),
    (0.0000, 1.0000, 0.5843),
    (0.0000, 1.0000, 0.2510),
    (0.0667, 1.0000, 0.0000),
    (0.3843, 1.0000, 0.0000),
    (0.7176, 1.0000, 0.0000),
    (1.0000, 0.9686, 0.0000),
    (1.0000, 0.6510, 0.0000),
    (1.0000, 0.3176, 0.0000),
    (1.0000, 0.0000, 0.0000),
]
vic2d_cmap = ListedColormap(vic2d_colors)

micro_values = np.array(values) * 1e6

element_strain_plot(
    points=found,
    elements=element_indices,
    coordinates=coordinates,
    values=micro_values,
    label=r"Log Strain, $E_{11}$ (microstrain)",
    image=current_image,
    dot_size=6,
    marker="s",
    show_mesh_lines=False,
    cmap=vic2d_cmap,
    vmin=17560,
    vmax=22360,
    figsize=(6.9, 6.0),
    path="high_point_density_strain_vic_colorbar.png",
)
Saved: high_point_density_strain_vic_colorbar.png
A Real Trade-Off, Not a Bug
2862-point, 5px-spacing mesh: mean = 0.0205 (true value is ), but std = 0.0165, range [-0.0164, 0.1061]
The mean is close but not exact. The spread is not small. Unlike Simple Stretch Revisited's perfectly uniform result, individual elements here scatter well beyond the true value — some report negative strain, some report more than 5 times the true value.
This isn't a tracking bug. Log strain is, in effect, a finite
difference: , a displacement difference
divided by element size . Subpixel Accuracy's
own measurement found locate_subpixel's residual error is small in
absolute terms — a few hundredths of a pixel, on average — but at 5
pixels of element spacing, that same absolute error is a much larger
fraction of than it was at Simple Stretch Revisited's 50-pixel
spacing. The smaller the element, the more a fixed amount of tracking
noise gets amplified into strain noise. Checked directly, not just
argued:
| Element spacing | Mean E11 | Std E11 |
|---|---|---|
| 5px | 0.02012 | 0.01653 |
| 10px | 0.01968 | 0.01268 |
| 20px | 0.01982 | 0.00997 |
| 40px | 0.01980 | 0.00347 |
Standard deviation falls as element spacing grows — the same tracking
noise, spread over a larger , moves less of the resulting strain.
This is exactly why VIC-2D and other commercial DIC packages offer a
strain window — averaging displacement over several subsets before
computing strain, trading spatial resolution for strain precision.
dictk doesn't implement that averaging yet. This page's own dense
mesh is accurate on average and honestly noisy point to point, not
silently smoothed into looking better than the underlying tracking
supports.
Distribution Across the Full Mesh
The mean/std/range summary above collapses the 11024 Gauss point numbers into four. The full distribution, the same way Verification Against VIC-2D plotted one for VIC-2D's own 2682 measurements, shows more:
import numpy as np
import matplotlib.pyplot as plt

micro = np.array(values) * 1e6
analytical = np.log(factor_x) * 1e6

plt.rcParams.update({"font.family": "serif", "mathtext.fontset": "cm"})
fig, ax = plt.subplots(figsize=(7, 4), constrained_layout=True)
ax.hist(micro, bins=60, color="gray", alpha=0.8)
ax.axvline(analytical, color="red", linestyle="--", linewidth=1.5)
ax.set_xlabel(r"Log strain $E_{11}$ (microstrain)")
ax.set_ylabel("frequency")
fig.savefig("high_point_density_strain_histogram.png", dpi=300)
Saved: high_point_density_strain_histogram.png
dictk's own across all 11024 Gauss points at full VIC-2D density (gray, 60 bins). The dashed red line marks the same analytical value as Verification Against VIC-2D's own histogram, microstrain. Unlike that page's multi-clustered distribution, this one is a single smooth, right-skewed peak — but a much wider one: individual Gauss points range from about -16400 to 106100 microstrain, over 21 times VIC-2D's own roughly 17300-23100 microstrain spread.dictk's own mean, 20464.3 microstrain, is close to VIC-2D's own
measured mean, 19875.8 microstrain, but not as close as
Verification Against VIC-2D's
earlier comparison found. That page's dictk value came from exact,
integer-pixel tracked positions on a 12-point sample; it landed within
0.02% of the analytical . This page's dictk value comes
from real subpixel-tracked positions on all 2862 points — the same
kind of measurement VIC-2D itself makes — and lands 3.3% from the
analytical value, noisier than VIC-2D's own 0.4%. Averaging over more
points doesn't fix this: the histogram's long right tail, not evenly
spread noise, is what pulls the mean away from the true value.
One methodological detail behind this figure is worth stating plainly.
At upsample_factor = 10 — Subpixel Accuracy's
own choice, adequate there — this same histogram doesn't look like the
smooth curve above. It separates into sharp, evenly-spaced spikes,
roughly 20000 microstrain apart. That spacing isn't a coincidence:
upsample_factor = 10 resolves displacement to steps of 0.1 px, and
0.1 / 5 = 0.02, or 20000 microstrain, at this mesh's own 5px element
spacing — exactly the gap between spikes. The clusters are an artifact
of how finely displacement gets quantized, not a real feature of the
tracked field. upsample_factor = 100 shrinks that same step to 2000
microstrain, well under the histogram's own bin width, and the spikes
disappear into the smooth distribution shown above. Mean and std barely
move between the two (std actually falls slightly, from 17776 to 16531
microstrain) — the real spread was already present at
upsample_factor = 10; only its artificially blocky shape needed the
finer value to go away. Subpixel Accuracy uses this same 5px grid and
the same 10, without hitting this problem, because it only ever
measures raw displacement error directly — it never divides by an
element size. This page does, computing strain as , and
dividing by a small turns a small, fixed quantization step into a
large one. That's the actual reason upsample_factor needed to change
here and not there — not point density, but what gets computed from
the tracked positions afterward.
That leaves a real question: why does a genuine, non-artifactual spread
show up in both tools, when each measured the exact same noiseless
synthetic deformation? A Real Trade-Off, Not a
Bug above already covered half of it:
strain amplifies whatever tracking error already exists. The other half
is why tracking error exists at all, for both tools. dictk's
locate_subpixel and VIC-2D's own optimizer are both correlation-based
subpixel estimators. Each locates a peak in a similarity surface built
from real image content, not a value handed to it directly. How sharply
that peak is defined depends on how much distinctive texture falls
inside the kernel at that particular location. Strong, varied speckle
contrast pins the peak precisely. A locally flatter or more repetitive
patch leaves it ambiguous, and the estimated position drifts toward
whichever direction the ambiguity favors. That drift is a deterministic
function of local image content, not a random draw — exactly why the
field figure above shows structured striations instead of uniform
static, and why this page's own histogram leans right instead of
sitting symmetric around the true value. It's also consistent with part
of why dictk's own spread grew on this page: matching VIC-2D's own
small px kernel, instead of earlier pages' generously
oversized ones, means averaging over less independent texture per
point. Some of that extra spread is the expected cost of matching
VIC-2D's own geometry, not a shortcoming unique to dictk.
Point count, tracking accuracy, and now strain precision have all been
free variables throughout Simple Stretch, Subpixel Accuracy, and this
page. How dictk's own tracking time scales as point count grows —
across sequential, threaded, and multi-process execution — is
Parallelization's own question, still not
attempted here either.
Timing at Scale
High Point Density closed with a question it
didn't answer: how does dictk's tracking time scale as point count
grows? Does that scaling change across sequential, threaded, and
multi-process execution?
Parallelization already measured the bare
phase_cross_correlation primitive. That benchmark ran up to
1,000,000 synthetic calls. But it never ran the real
dictk.grid.locate_subpixel pipeline. And it never used an image large
enough to make "many points" physically real, not just a parameter
sweep.
This page runs that pipeline directly. It grows the reference image until this machine's own limits show up. It reports what actually stopped the ladder, not what was expected to stop it.
Test Machine
Every number on this page depends on the hardware it was measured on. Here is what we used to-date:
- Apple MacBook Pro (14-inch, 2021), model
MacBookPro18,3, Apple M1 Pro chip, 10 cores (8 Performance + 2 Efficiency), 32GB RAM, macOS 26.5.2 (Tahoe).
Same core count as Parallelization's own already-committed benchmark ("measured once on a 10-core machine").
Points, Elements, and Gauss Points
Every point this page tracks feeds directly into
dictk.grid.elements and, from
there, into per-element strain via 2×2 Gauss quadrature
(dictk.element.gauss_points),
the same machinery High Point Density and
Finite Element Method already use.
A regular grid of points gives:
total points. Four points in a cycle make one element, so a grid with points along and along tiles into:
elements. Each axis has one fewer element than points, because every interior point is shared by up to four neighboring elements. Each element carries 4 Gauss points — the standard 2×2 quadrature rule for a Q4 element. So:
As , . So . At high density, four Gauss points exist per point, not per element.
This page's own largest successful tier (5669px, 998×998 points) confirms the asymptote numerically: points, , . That ratio is 3.992 — already within 0.2% of the limiting value of 4.
is also exactly the number of
dictk.grid.locate_subpixel
calls this page's benchmark makes: one correlation per point, not per
element or per Gauss point. That's why point count, not element or
Gauss-point count, is the x-axis variable below.
Growing the Reference Image
Every prior page in this book built its current image the same way. It
started from dictk.image.astronaut,
a fixed 512×512 photograph. When a larger canvas was needed, it
upsampled that photograph with bicubic interpolation
(scipy.ndimage.zoom). Then it added speckle via
dictk.rosta.rosta and combined the
two with combine.
That approach works fine at book scale. But growing the photograph 20x or 100x linearly risks its own artifacts: softened edges, ringing near hard boundaries. Once point counts climb into the millions, those artifacts would be indistinguishable from genuine tracking degradation.
This page drops the photo layer entirely.
rosta generates its speckle pattern
directly, at whatever resolution it's asked for. That speckle is
Gaussian-smoothed thresholded noise. It needs no upsampling step, and
it has no fixed source resolution to run out of.
Real DIC surfaces are speckle-only anyway. The astronaut photograph elsewhere in this book only helps human readers recognize the subregion. The speckle pattern carries the correlation; the photograph does not.
Reference and current images for every tier below are built this way:
reference_image = rosta(width=W, height=W, dot_size=..., smoothness=...)
current_image = stretch(arr=reference_image, factor_x=1.02)
This is the same 2% stretch every prior page in this book has used.
Here it's applied directly to the pure speckle field rosta produced.
One rescaling kept this affordable.
rosta's dot_size and smoothness
parameters set a Gaussian filter's sigma as a fraction of the image,
not a fixed pixel count: dot_size * min(width, height) / 1000.
Leaving dot_size and smoothness fixed while width grows causes a
problem. The speckle dots grow too, in real pixel size. gaussian_filter's
own cost grows with sigma. So total generation cost grows cubically
with image width.
A direct measurement confirms this. At 10,000×10,000 pixels,
generation took 34.2s using the 300px-tuned defaults. Rescaling
dot_size and smoothness by the same factor the image grew cut that
time to 8.2s.
Every tier on this page applies that rescaling. rosta_params_for (in
the script below) divides dot_size and smoothness by the image's
growth factor. This keeps the speckle dot's real pixel size constant.
Generation cost then stays close to linear in image size.
Finding the Ceiling
timing_at_scale_bench.py (full source
below) runs a geometric ladder of image widths: 300, 540, 972, 1750,
3149, 5669, 10204px — each step ×1.8 larger than the last, starting
from High Point Density's own 300px
baseline. At each size, it times sequential, threaded, and
process-pool execution of dictk.grid.locate_subpixel across the
resulting point grid.
Tracking geometry matches High Point Density
directly: kernel_margin=13, upsample_factor=100. search_margin
cannot stay fixed the way it did there, though. At a constant
factor_x=1.02, maximum displacement grows with the image itself
(max_x * 0.02). A fixed margin tuned for a 300px image would
silently undershoot the true displacement at every larger tier. So
each tier computes its own margin from its own maximum displacement
instead.
That makes the two halves of the geometry behave differently across
the ladder. Here is what each tier actually tracks, read directly from
grid_params in the script below:
| Width (px) | Points | Kernel (px) | Search area (px) | Max displacement (px) |
|---|---|---|---|---|
| 300 | 2,809 | 26x26 | 48x48 | 5.6 |
| 540 | 9,216 | 26x26 | 58x58 | 10.1 |
| 972 | 29,584 | 26x26 | 74x74 | 18.3 |
| 1750 | 95,481 | 26x26 | 102x102 | 32.9 |
| 3149 | 308,025 | 26x26 | 156x156 | 59.2 |
| 5669 | 996,004 | 26x26 | 250x250 | 106.5 |
| 10204 | 3,229,209 | 26x26 | 420x420 | 191.8 |
The kernel is fixed. Every tier correlates the same 26x26 pixels. The search area is not fixed. It grows from 48x48 to 420x420, because the displacement it has to contain grows with the image. That is 76 times more search pixels at the top of the ladder than at the bottom.
So the tracking curve below is not a pure point-count curve. Point count and per-correlation size grow together, and the plot's x-axis only shows the first of the two. This doesn't affect any comparison between executors — all three see identical geometry at every tier — but it does explain part of how steeply the curve climbs.
Each (width, executor) combination runs in its own isolated
subprocess, with its own 1800-second (30-minute) wall-clock budget. A controlling
loop launches each one; nothing runs in-process. Deliberately pushing
a laptop toward a resource limit is not something to do inside the
same process that's also tracking the result.
macOS doesn't reliably raise a catchable MemoryError the way Linux
does. A runaway allocation can instead thrash the whole machine
through heavy swapping. Or the kernel can SIGKILL the process outright,
with no Python exception to catch. Subprocess isolation contains
either outcome to one measurement. It never takes down the whole run.
This sweep takes hours, not minutes, and is expected to end in a deliberate failure. Its results were measured once, and committed alongside the script that produced them:
| Width (px) | Points | Sequential | Threads | Processes |
|---|---|---|---|---|
| 300 | 2,809 | 1.5s | 1.5s | 1.5s |
| 540 | 9,216 | 6.0s | 4.9s | 3.9s |
| 972 | 29,584 | 25.6s | 16.9s | 26.5s |
| 1750 | 95,481 | 105.1s | 58.6s | crashed |
| 3149 | 308,025 | 525.1s | 215.2s | — |
| 5669 | 996,004 | timeout (1800s) | 861.5s | — |
| 10204 | 3,229,209 | — | timeout (1800s) | — |
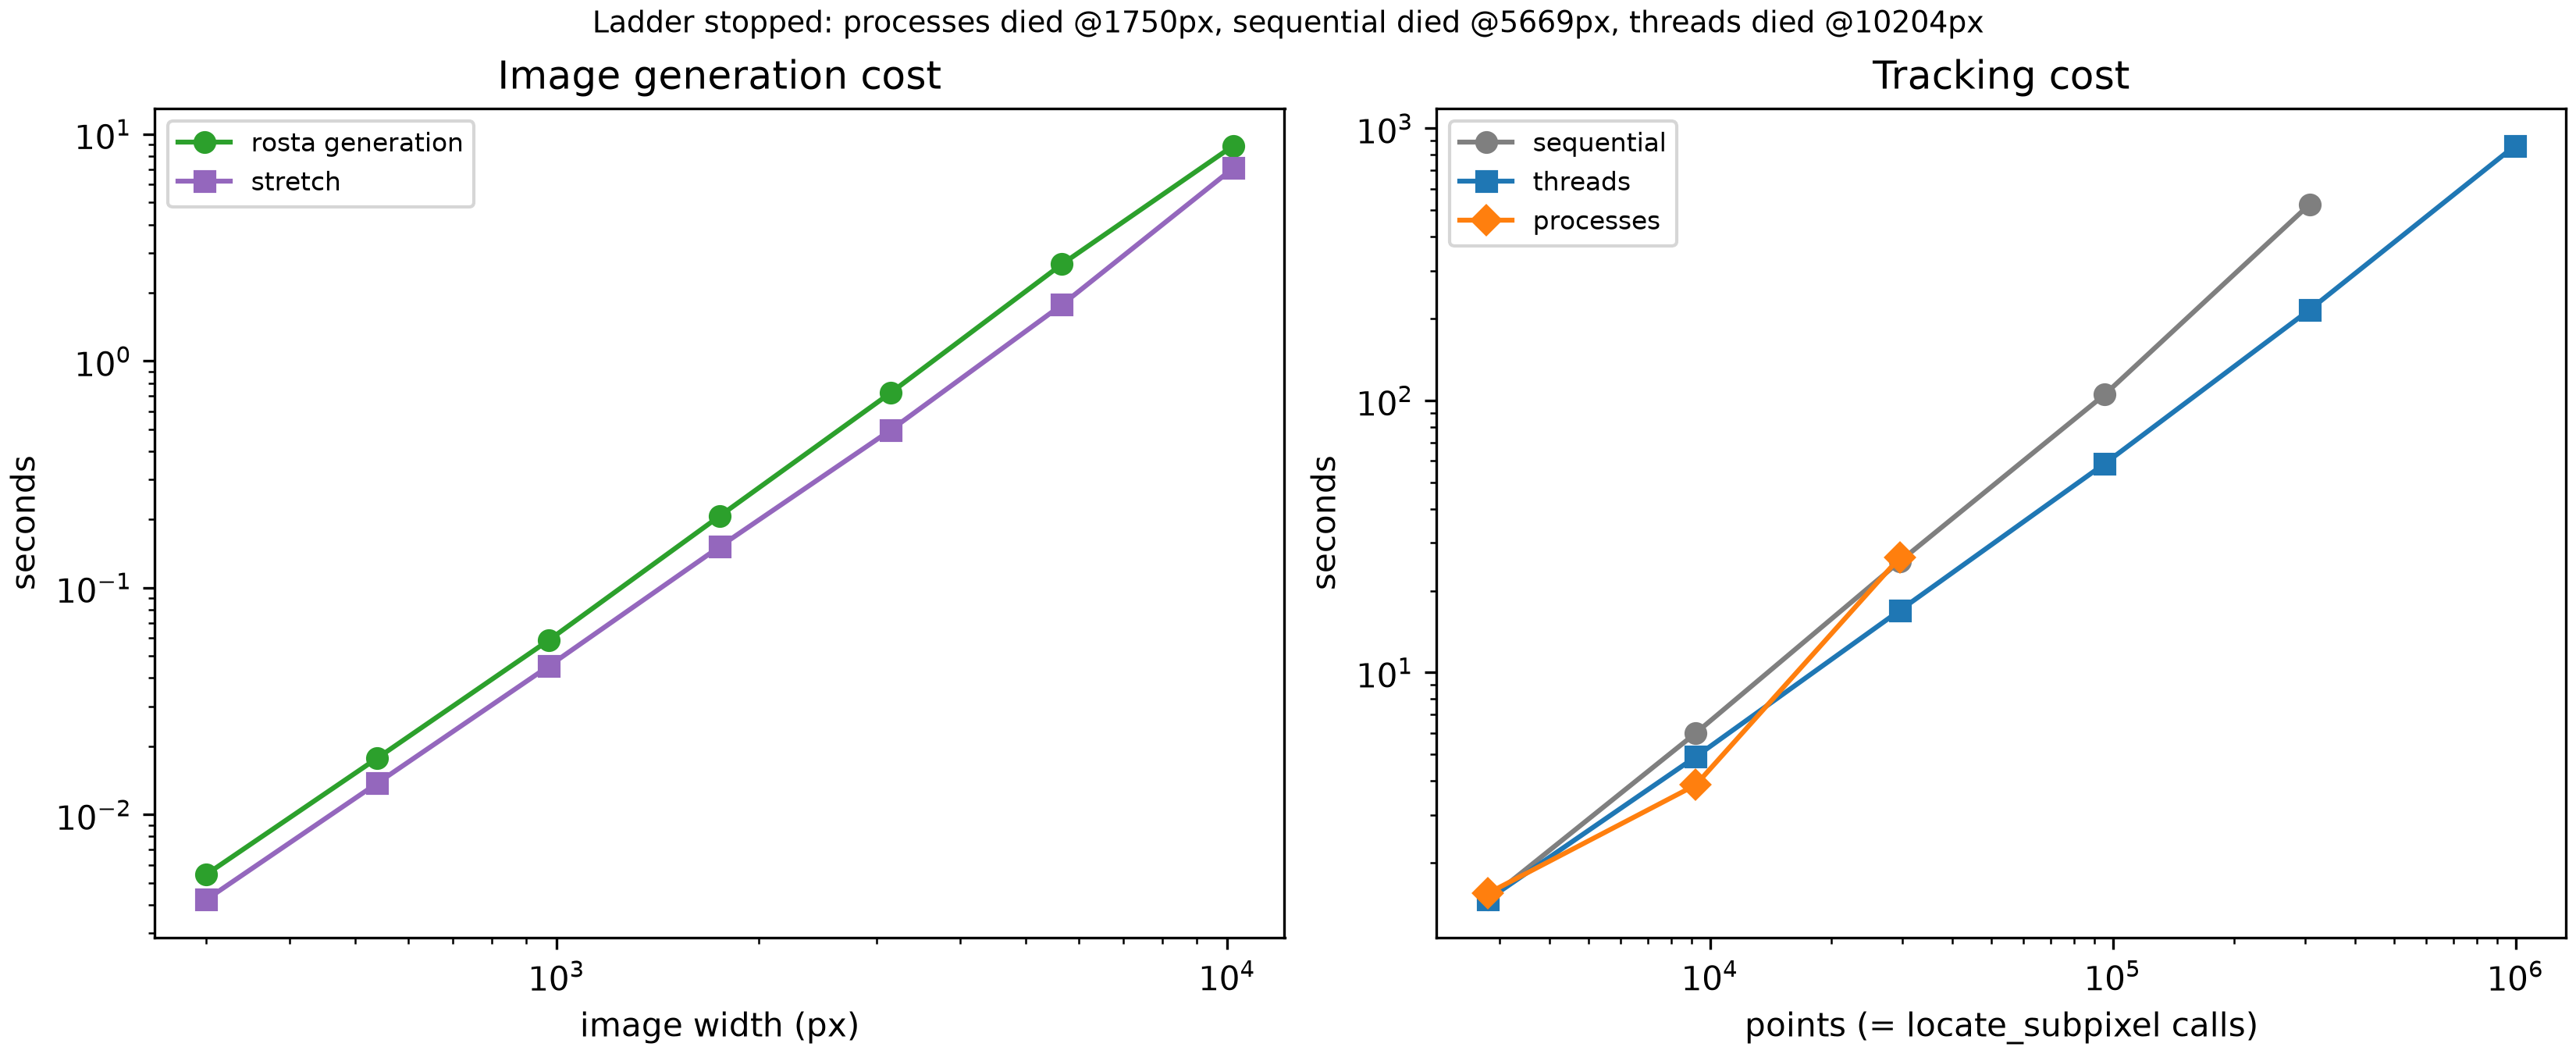
rosta generation and stretch both scale smoothly with image width, confirming the dot-size rescaling above kept generation cost from going cubic. Right: tracking cost vs. point count for all three executors. Every series ends where its own executor died — not at a common point count, and not at a common image size.Threads pull ahead as point count grows, and by a widening margin. At 300px, threads and sequential run a statistical tie (0.999x) — 2,809 points isn't enough yet to amortize thread scheduling overhead. That margin grows: 1.5x at 972px, 1.8x at 1750px, 2.4x at 3149px.
This matches Parallelization's own "many points, moderate-to-large correlations" regime. That's exactly where this pipeline sits once point counts climb past a few thousand.
Where It Breaks
None of the three executors died to memory pressure. This page checked
sysctl vm.swapusage directly, polling it roughly every 30 seconds
throughout the entire multi-hour run, watching for the moment used
became nonzero. It never did — not once, at any tier, for any
executor.
Peak resident set size (ru_maxrss, sampled after every stage) topped
out at 11.5GB. That peak came from stretch alone, at the final
10204px tier — barely a third of this machine's 32GB. Every executor
died for its own reason. None of those reasons was RAM.
processes died first, at 1750px. The cause is a real architectural
bottleneck, not a resource limit. It's already the slowest of the
three by 972px: 26.5s, versus sequential's own 25.6s. That's worse
than doing nothing extra — a full tier before its final failure.
The cause is visible directly in
dictk.grid.locate's own source. It
binds reference_image/current_image into a partial once. Then it
hands that partial to ProcessPoolExecutor.map():
worker = partial(
    _locate_worker,
    reference_image=reference_image,
    current_image=current_image,
    ...
)
with executor_cls(max_workers=max_workers) as pool:
    return list(pool.map(worker, zip(reference_points, search_centers)))
ProcessPoolExecutor.map() re-pickles that bound callable once per
task, not once per worker. The image arrays get re-pickled too, every
time. At a few hundred points and a 300px image, that cost is trivial.
At tens of thousands of points and a multi-megapixel image, it isn't:
the main process spends more time serializing the same large array
over and over than any worker spends computing.
A retry at 1750px, under this page's own raised 1800-second (30-minute) budget, confirmed this directly. CPU utilization held around 50% of one core. That's a process bottlenecked on serialization, not eight processes computing in parallel. It showed no sign of finishing soon, so this page stopped it deliberately, once the cause was understood — running it to exhaustion would only have proven a point already proven.
This is a real, unfixed limitation in dictk itself. It's named here
rather than patched, the same precedent High Point
Density set for
its own strain-window-averaging finding.
sequential and threads both died to this script's own
1800-second (30-minute) timeout. That's a compute-time wall, not a memory one.
sequential reached 3149px: 308,025 points, 525.1s. Its next tier,
5669px, then ran out the full budget.
threads went one tier further. It completed that same 5669px tier
successfully — 996,004 points, 861.5s, with healthy ~6-8x realized
parallelism visible in top-level CPU usage throughout. It then also
ran out the 1800-second (30-minute) budget at the next tier, 10204px (3,229,209
points). Extrapolating past its own last measured scaling trend, that
tier needed roughly an hour of work — about twice the budget.
Both failures were checked directly, not assumed. CPU usage stayed high, and RSS stayed well under the machine's ceiling, for the entire lifetime of each failed run. These are legitimate long computations that simply outran their own budget. None of them hung, leaked, or crashed.
The honest finding, stated plainly: on this machine, with this pipeline, compute time is the wall this ladder actually hit. Memory never became a constraint — at least not up to the roughly one million points this ladder successfully tracked.
Path Forward's GPU direction has been gated on "a
documented CPU bottleneck" since it was first written. This page
documents one, with real numbers. A real DIC problem at
finite-element-mesh scale needs at least a billion correlations, per
that same page's own north star. Reaching a million took threads
14.4 minutes on 10 cores. A billion points is 1000x that. Extrapolating
threads's own measured rate straight-line to that scale lands at
about 1.4 weeks (≈240 hours) — far past this page's own 30-minute
per-tier budget. No amount of additional CPU-side tuning closes a gap
that size on its own.
timing_at_scale_bench.py
"""Timing at Scale: push High Point Density's own tracking pipeline --
real dictk.grid.locate_subpixel, not the bare phase_cross_correlation
primitive parallelization_bench.py benchmarks -- up a geometric ladder
of point counts on this machine (Apple M1 Pro, 32GB RAM, 10 cores --
see timing_at_scale.md's own Test Machine section), looking for its
real ceiling. The ladder set out looking for a genuine memory wall; the
actual result (see timing_at_scale.md's own Where It Breaks section) is
that every executor died to this script's own TIMEOUT_S first, with
`vm.swapusage` reporting 0.00M used at every tier attempted -- a
compute-time ceiling, not a memory one, at least up to the sizes this
ladder reached.

Not part of the dictk package -- a standalone, one-time measurement
script, matching parallelization_bench.py's own precedent. Its output
(timing_at_scale_bench.csv, timing_at_scale_bench.png) is committed
alongside it rather than regenerated on every book build -- the full
ladder takes many minutes and is expected to end in a deliberate
failure, neither of which fits the live cmdrun re-execution every other
figure in this book uses.

Safety architecture (read before changing the ladder): macOS does not
reliably raise a catchable MemoryError the way Linux does -- a runaway
allocation can instead thrash the whole machine (heavy swapping, not
just this script) or get SIGKILLed by the kernel outright, with no
Python exception to catch. Each (width, executor) combination therefore
runs as its OWN ISOLATED SUBPROCESS with its OWN wall-clock timeout,
launched by the controller at the bottom of this file, never in-process
and never sharing a timeout budget with another executor. A first
version of this script ran all three executors inside one shared-budget
subprocess per width; at width=1750 the `processes` run got starved of
the remaining budget after `sequential` and `threads` had already used
most of it, and was killed by the timeout -- a real bug in the harness,
not a memory finding, caught by watching the run live rather than
trusting it unattended. Splitting each executor into its own subprocess
fixes that, and also lets each executor's own ladder stop independently
once *it* fails, rather than one executor's failure cutting off
measurements for the other two at the same size.

The core measurement (rosta generation, stretch, and locate_subpixel)
works entirely on in-memory numpy arrays -- no PNG is written or read
back during the ladder itself, so Pillow's own DecompressionBombError (a
safety default, not a hardware limit, documented separately on the page)
never becomes a confound in the RAM-limit story this script exists to
tell.

Must be a real module, not `python3 -c` -- ProcessPoolExecutor needs a
real, importable, top-level function to hand to spawned workers, the
same constraint dictk.grid._locate_worker exists for.

Re-run with: python3 timing_at_scale_bench.py
Re-run a single (width, executor) tier directly (e.g. to retry after
tuning something):
    python3 timing_at_scale_bench.py --worker 3000 threads
"""

import csv
import os
import resource
import subprocess
import sys
import time
from pathlib import Path

import matplotlib.pyplot as plt
import numpy as np

from dictk.grid import Executor, generate, locate_subpixel
from dictk.image import PixelCoordinate, stretch
from dictk.rosta import rosta

CSV_PATH = Path(__file__).parent / "timing_at_scale_bench.csv"
PNG_PATH = Path(__file__).parent / "timing_at_scale_bench.png"

WORKERS = os.cpu_count()

# Same tracking geometry High Point Density (9.2) established --
# kernel_margin=13, upsample_factor=100 -- except search_margin, which
# cannot stay fixed here: factor_x=1.02 means max displacement grows
# with the image itself (~0.02 * width), and 9.2's own fixed 25px
# search margin (tuned for a 300px image, max displacement ~5.6px)
# would silently undershoot the true displacement at any larger tier.
KERNEL_MARGIN = 13
FACTOR_X = 1.02
UPSAMPLE_FACTOR = 100
SEARCH_BUFFER = 5  # extra px of headroom beyond the max displacement

# Origin as a fraction of image width, matching 9.2's own origin=18 on
# a 300px image (18/300 = 0.06) -- keeps the grid's own margin
# proportionally identical at every tier.
ORIGIN_FRACTION = 18 / 300
SPACING = 5

# rosta()'s own defaults (dot_size=4.0, smoothness=2.0) are tuned for a
# 300px image -- see rosta_params_for's own docstring for why they must
# shrink as width grows, not stay fixed.
BASE_WIDTH = 300
BASE_DOT_SIZE = 4.0
BASE_SMOOTHNESS = 2.0
DENSITY = 0.5  # resolution-independent, matches the rest of the book

EXECUTOR_KWARGS = {
    "sequential": dict(max_workers=None),
    "threads": dict(max_workers=WORKERS, executor=Executor.THREAD),
    "processes": dict(max_workers=WORKERS, executor=Executor.PROCESS),
}

TIMEOUT_S = 1800  # per (width, executor) wall-clock budget
# Started at 240s. Raised after the first real run showed sequential and
# processes both dying to that budget (at 1750px and 3149px) well before
# any genuine memory pressure -- their own per-call FFT cost, not RAM, was
# the binding constraint at 240s. Even at 1800s, every executor still
# died to this same budget rather than to memory -- sequential at 5669px,
# threads at 10204px, both with peak RSS under 12GB out of 32GB available
# and zero swap used throughout. Compute time, not RAM, is the real
# ceiling this ladder found; see timing_at_scale.md for the full story.


def grid_params(width: int) -> tuple[int, int, int]:
    """Origin, point count, and search margin for a square width x width
    tier, holding the grid's own relative geometry constant across the
    ladder. Returns (origin, count, search_margin_px)."""
    origin = round(ORIGIN_FRACTION * width)
    count = (width - 2 * origin) // SPACING + 1
    max_x = origin + (count - 1) * SPACING
    max_displacement = max_x * (FACTOR_X - 1.0)
    search_margin = KERNEL_MARGIN + int(np.ceil(max_displacement)) + SEARCH_BUFFER
    return origin, count, search_margin


def rosta_params_for(width: int) -> tuple[float, float]:
    """dot_size/smoothness rescaled to hold the speckle dot's own real
    pixel size constant as width grows.

    rosta_pattern computes its Gaussian sigmas as
    `dot_size * min(width, height) / 1000`, so dot_size/smoothness left
    fixed while width grows makes the dots themselves grow proportionally
    larger in pixels -- and gaussian_filter's own cost then grows with
    sigma, pushing total cost cubic in linear size (measured: 34.2s vs.
    8.2s at 10000x10000, unscaled vs. rescaled). Dividing by the same
    factor width grew by holds the sigma, and the cost, close to linear.
    """
    factor = width / BASE_WIDTH
    return BASE_DOT_SIZE / factor, BASE_SMOOTHNESS / factor


def _peak_rss_gb() -> float:
    """Peak resident set size so far, in GB. macOS reports ru_maxrss in
    bytes; Linux reports it in KB -- this module only ever runs on the
    former (see the module docstring's own Test Machine reference), so
    no platform branch is needed here."""
    return resource.getrusage(resource.RUSAGE_SELF).ru_maxrss / 1e9


def _append_row(
    *, width: int, points: int, stage: str, seconds: float, peak_rss_gb: float
) -> None:
    """Appends and flushes one CSV row immediately -- not batched -- so a
    later crash in this same worker process loses nothing already
    measured."""
    is_new = not CSV_PATH.exists()
    with open(CSV_PATH, "a", newline="") as f:
        writer = csv.writer(f)
        if is_new:
            writer.writerow(["width", "points", "stage", "seconds", "peak_rss_gb"])
        writer.writerow([width, points, stage, f"{seconds:.6f}", f"{peak_rss_gb:.4f}"])
        f.flush()
        os.fsync(f.fileno())


def run_tier(width: int, executor_name: str) -> None:
    """Runs one (width, executor) tier -- image generation, stretch, then
    one locate_subpixel call under the named executor -- appending one
    CSV row per completed stage as it goes. Exits nonzero (uncaught
    exception) on any real failure; the controller subprocess treats
    that, or a timeout, as this executor's own hard stopping point at
    this size."""
    dot_size, smoothness = rosta_params_for(width)

    t0 = time.perf_counter()
    reference_image = rosta(
        width=width,
        height=width,
        dot_size=dot_size,
        smoothness=smoothness,
        density=DENSITY,
    )
    _append_row(
        width=width,
        points=0,
        stage="rosta",
        seconds=time.perf_counter() - t0,
        peak_rss_gb=_peak_rss_gb(),
    )

    t0 = time.perf_counter()
    current_image = stretch(arr=reference_image, factor_x=FACTOR_X)
    _append_row(
        width=width,
        points=0,
        stage="stretch",
        seconds=time.perf_counter() - t0,
        peak_rss_gb=_peak_rss_gb(),
    )

    origin, count, search_margin = grid_params(width)
    points = generate(
        origin=PixelCoordinate(x=origin, y=origin),
        count_x=count,
        count_y=count,
        spacing_x=SPACING,
        spacing_y=SPACING,
    )
    z = count * count

    t0 = time.perf_counter()
    found = locate_subpixel(
        reference_image=reference_image,
        current_image=current_image,
        reference_points=points,
        kernel_margin_width=KERNEL_MARGIN,
        kernel_margin_height=KERNEL_MARGIN,
        search_margin_width=search_margin,
        search_margin_height=search_margin,
        upsample_factor=UPSAMPLE_FACTOR,
        **EXECUTOR_KWARGS[executor_name],
    )
    elapsed = time.perf_counter() - t0
    _append_row(
        width=width,
        points=z,
        stage=executor_name,
        seconds=elapsed,
        peak_rss_gb=_peak_rss_gb(),
    )

    # Cheap correctness spot-check -- sampled, not exhaustive, since z can
    # be in the millions. A wrong search_margin at this tier shows up
    # here before it shows up as a confusing shape in the timing plot.
    true_x = [p.x * FACTOR_X for p in points]
    sample = np.random.default_rng(0).choice(
        len(points), size=min(50, len(points)), replace=False
    )
    max_err = max(abs(found[i].x - true_x[i]) for i in sample)
    if max_err > 1.0:
        print(
            f"WARNING width={width} executor={executor_name}: sampled max "
            f"tracking error {max_err:.2f}px -- search_margin may be too "
            "small at this tier",
            file=sys.stderr,
        )


def _widths() -> list[int]:
    """Geometric ladder starting at 9.2's own 300px baseline, x1.8 per
    step, up to a size comfortably past where the machine is expected to
    fail -- the controller stops for real once a tier actually does.

    1.8 is a practical choice, not a tuned constant -- it gives enough
    tiers to see the timing trend on a log-log plot without a step so
    fine the ladder takes unreasonably long to reach the interesting
    region. No evidence ties any finding on this page to this specific
    ratio rather than some other nearby one."""
    widths = []
    w = float(BASE_WIDTH)
    while w < 60_000:
        widths.append(round(w))
        w *= 1.8
    return widths


def _resume_plan() -> dict[str, int | None]:
    """Reads the existing CSV (if any) to decide, per executor, which
    width to resume the ladder at. A width that previously failed via
    timeout gets retried (a larger TIMEOUT_S might let it succeed now);
    widths already measured successfully are skipped; a real crash
    (non-timeout failure) marks that executor permanently dead (`None`)
    -- retrying it would just reproduce the same crash."""
    if not CSV_PATH.exists():
        return dict.fromkeys(EXECUTOR_KWARGS, BASE_WIDTH)

    with open(CSV_PATH) as f:
        rows = list(csv.DictReader(f))

    status: dict[str, dict[int, str]] = {name: {} for name in EXECUTOR_KWARGS}
    for r in rows:
        width = int(r["width"])
        stage = r["stage"]
        if stage in EXECUTOR_KWARGS:
            status[stage][width] = "success"
        elif stage.startswith("FAILED_timeout_"):
            name = stage.removeprefix("FAILED_timeout_")
            if name in status:
                status[name].setdefault(width, "timeout")
        elif stage.startswith("FAILED_returncode_"):
            name = stage.rsplit("_", 1)[-1]
            if name in status:
                status[name][width] = "crash"

    plan: dict[str, int | None] = {}
    for name in EXECUTOR_KWARGS:
        resume_width: int | None = None
        for width in _widths():
            s = status[name].get(width)
            if s == "success":
                continue
            resume_width = None if s == "crash" else width
            break
        plan[name] = resume_width
    return plan


def run_ladder() -> None:
    resume_at = _resume_plan()
    alive = {name: (resume_at[name] is not None) for name in EXECUTOR_KWARGS}
    print(f"Resuming: {resume_at}")
    for width in _widths():
        if not any(alive.values()):
            break
        print(f"--- width={width} (alive: {[k for k, v in alive.items() if v]}) ---")
        for executor_name in EXECUTOR_KWARGS:
            if not alive[executor_name]:
                continue
            if width < resume_at[executor_name]:
                print(f"  {executor_name}: already measured, skipping")
                continue
            try:
                result = subprocess.run(
                    [sys.executable, __file__, "--worker", str(width), executor_name],
                    timeout=TIMEOUT_S,
                    capture_output=True,
                    text=True,
                )
            except subprocess.TimeoutExpired:
                print(f"  {executor_name}: TIMED OUT after {TIMEOUT_S}s")
                _append_row(
                    width=width,
                    points=0,
                    stage=f"FAILED_timeout_{executor_name}",
                    seconds=float("nan"),
                    peak_rss_gb=float("nan"),
                )
                alive[executor_name] = False
                continue
            if result.returncode != 0:
                print(f"  {executor_name}: FAILED (returncode={result.returncode})")
                print(result.stderr[-1000:])
                _append_row(
                    width=width,
                    points=0,
                    stage=f"FAILED_returncode_{result.returncode}_{executor_name}",
                    seconds=float("nan"),
                    peak_rss_gb=float("nan"),
                )
                alive[executor_name] = False
                continue
            print(f"  {executor_name}: ok")
            if result.stderr.strip():
                print(f"  {executor_name} stderr: {result.stderr.strip()[-500:]}")
    print(f"Wrote {CSV_PATH}")


def plot_summary() -> None:
    with open(CSV_PATH) as f:
        rows = list(csv.DictReader(f))

    fig, (ax_gen, ax_track) = plt.subplots(
        1, 2, figsize=(11, 4.5), constrained_layout=True
    )

    for stage, color, marker, label in [
        ("rosta", "tab:green", "o", "rosta generation"),
        ("stretch", "tab:purple", "s", "stretch"),
    ]:
        by_width: dict[int, list[float]] = {}
        for r in rows:
            if r["stage"] == stage:
                by_width.setdefault(int(r["width"]), []).append(float(r["seconds"]))
        xs = sorted(by_width)
        ys = [float(np.mean(by_width[w])) for w in xs]
        ax_gen.plot(xs, ys, marker=marker, color=color, label=label)
    ax_gen.set_xscale("log")
    ax_gen.set_yscale("log")
    ax_gen.set_xlabel("image width (px)")
    ax_gen.set_ylabel("seconds")
    ax_gen.set_title("Image generation cost")
    ax_gen.legend(fontsize=8)

    for stage, color, marker in [
        ("sequential", "tab:gray", "o"),
        ("threads", "tab:blue", "s"),
        ("processes", "tab:orange", "D"),
    ]:
        xs = [int(r["points"]) for r in rows if r["stage"] == stage]
        ys = [float(r["seconds"]) for r in rows if r["stage"] == stage]
        ax_track.plot(xs, ys, marker=marker, color=color, label=stage)
    ax_track.set_xscale("log")
    ax_track.set_yscale("log")
    ax_track.set_xlabel("points (= locate_subpixel calls)")
    ax_track.set_ylabel("seconds")
    ax_track.set_title("Tracking cost")
    ax_track.legend(fontsize=8)

    # Only report an executor as dead if nothing later in the CSV shows it
    # succeeding at that width or beyond -- a retry after TIMEOUT_S was
    # raised can turn an earlier "FAILED_timeout" row into a stale one.
    final_max_success = {
        name: max((int(r["width"]) for r in rows if r["stage"] == name), default=-1)
        for name in EXECUTOR_KWARGS
    }
    still_dead = [
        r
        for r in rows
        if r["stage"].startswith("FAILED")
        and int(r["width"]) > final_max_success.get(r["stage"].rsplit("_", 1)[-1], -1)
    ]
    if still_dead:
        # Collapse to one entry per executor -- a width can appear twice
        # (e.g. timed out, then crashed on a later retry at the same
        # width); the last one in file order is the final word on that
        # executor's fate.
        by_executor: dict[str, dict] = {}
        for r in still_dead:
            name = r["stage"].rsplit("_", 1)[-1]
            by_executor[name] = r
        summary = ", ".join(
            f"{name} died @{r['width']}px" for name, r in by_executor.items()
        )
        fig.suptitle(f"Ladder stopped: {summary}", fontsize=9, wrap=True)

    fig.savefig(PNG_PATH, dpi=300)
    plt.close(fig)
    print(f"Wrote {PNG_PATH}")


if __name__ == "__main__":
    if len(sys.argv) == 4 and sys.argv[1] == "--worker":
        run_tier(int(sys.argv[2]), sys.argv[3])
    else:
        run_ladder()
        plot_summary()
Parallelism with PyTorch
Timing at Scale found a wall. Tracking a million points took 14.4 minutes on ten cores. A billion correlations, the scale Path Forward names as the real target, extrapolates to roughly 1.4 weeks on the same machine. No amount of additional CPU-side tuning closes a gap that size.
That page also found why. Every point ran its own separate correlation call, and each call carried its own Python-level overhead: a function call, a pair of array slices, an FFT plan, an object constructed for the result. When correlating just a few hundred points, that overhead disappears into the noise, seemingly costing nothing. However, then correlating a million points, the overhead bloats up the cost significantly.
This page changes the shape of the work rather than the amount. Instead of running a million small correlations, it runs a small number of very large correlations. Thousands of points get correlated in a single call. No Python loop runs between them. It reruns Timing at Scale's own ladder that way, on the same machine and the same geometry. The two sets of numbers can then be compared.
Test Machine
Every number here depends on the hardware that produced it. Same machine Timing at Scale used:
- Apple MacBook Pro (14-inch, 2021), model
MacBookPro18,3, Apple M1 Pro chip, 10 CPU cores (8 Performance + 2 Efficiency), 32GB unified memory, macOS 26.6.2. (The operating system was recently updated to 26.6.2.)
The M1 Pro also carries an integrated GPU, which every prior page in this book has left completely unused.
Where This Came From
This page continues work that Andrew Polonsky had with a colleague at the Naval Research laboratory, email dated 2025-04-15. A summary of that discussion:
Pytorch may be the likely implementation strategy. Pytorch already optimizes math used in correlations for the GPU. Depending on the subset (kernel) size, we are right on the cusp of whether or not the FFT approach for cross-correlation will be faster than the brute force sliding dot product approach.
Three conclusions from that discussion shaped everything after it.
- Numba works well for CPU work but is the wrong tool for a GPU.
- Writing raw GPU code in a portable manner is painful enough that the NRL colleague resorted to hand-written OpenCL.
- PyTorch already solves the portability problem, because it runs the same code on a CUDA card, on an Apple GPU, or on a plain CPU.
A team meeting on 2025-09-23 recorded the decision in one line: "torch implementation, then CUDA implementation."
The implementation that followed established the batching trick this page's next section describes, and measured it on a Windows machine with an NVIDIA card. Those measurements used a 35x35 pixel kernel inside a 120x120 pixel search window:
| Correlations | PyTorch GPU | PyTorch CPU | NumPy CPU |
|---|---|---|---|
| 1,000 | 0.044 s | 0.836 s | 1.47 s |
| 50,000 | 3.09 s | 40.8 s | 73.6 s |
Two things stand out in that table. The GPU beat NumPy by 24x at 50,000 correlations. And the correlation itself stopped being the expensive part: building the tensors took 16.3 seconds and checking the answers took 12.1 seconds, against 3.09 seconds of actual computation. That finding shows up again on this page, at a different scale, on different hardware.
That earlier work also left three gaps. It never implemented an FFT version. It never refined a peak to subpixel accuracy. And it never ran on macOS at all — the correlation module opened with a hard refusal:
if platform.system() != "Darwin":
    import torch
else:
    raise RuntimeError("This module requires PyTorch, which does not run on macOS.")
That claim is false. PyTorch runs on macOS, and has supported Apple GPUs since 2022.
This page closes two of those three gaps: it runs on Apple silicon, and it refines to subpixel. The FFT version stays open.
Kernels, Search Windows, and Names
Two vocabularies collide here, so it is worth harmonizing them.
This book has used kernel and search area since Cross Correlation. Commercial DIC software and the earlier work above use different words for the same two things:
| This book | VIC-2D and the earlier work | What it is |
|---|---|---|
| kernel | subset | The small patch cut from the reference image, the thing being located |
| search area | area of interest, or aoi | The larger region of the current image to look inside |
They are the same two arrays. A subset is a kernel. An aoi is a search area. The code below uses this book's names; the tensor shapes quoted from the earlier work use its own.
One Call, N Correlations
Here is the trick.
conv2d slides a small array over a larger one and reports how well
they match at every position. That is one correlation. To get N
correlations, the naive approach calls it N times in a Python loop, which
reintroduces exactly the per-call overhead this page seeks to remove.
The way out is to stack the work so a single call does all of it.
conv2d accepts a batch of images with multiple channels, and a set
of filters. By default it applies every filter to every channel, which
would compute an N x N cross product — every kernel against every search
area. That is both wrong and N times too much work.
The groups argument fixes it. Setting groups=N splits N input
channels into N independent groups of one. Kernel i then sees search
area i, and nothing else.
Three symbols carry through the rest of this page:
- is the point count, one correlation each.
- is the kernel's side, in pixels.
- is the search area's side, also in pixels.
# search areas: (1, N, S, S)   N search areas, stacked as CHANNELS
# kernels:      (N, 1, K, K)   N kernels, one per group
# output:       (1, N, S-K+1, S-K+1)
surfaces = F.conv2d(search_areas, kernels, groups=N)
Read the shapes carefully, because they are not the obvious ones. The batch dimension holds a single element. The channel dimension carries the N correlations. That deliberate misuse of the two dimensions is what lets one call do N independent correlations.
For this book's own example geometry, tracking 2,809 points in a 300 pixel image results in the following shapes:
(1, 2809, 48, 48)for the search areas,(2809, 1, 26, 26)for the kernels, and(1, 2809, 23, 23)for the output.
Every one of those 2,809 correlations happens inside a single conv2d call.
To be precise about what that geometry is: a 300 x 300 pixel rosta
speckle image, with a square 53 x 53 grid of points at 5 pixel spacing,
giving 2,809 points.
Simple Stretch sets up something
very similar, and illustrates it. It uses a 300 x 300 pixel astronaut
image, with a 53 x 54 grid at the same 5 pixel spacing, giving 2,862
points — one row more than this page uses. That page counts 2,682 in its
own heading, not 2,862, because VIC-2D masks out the 180 positions whose
correlation window would run off the edge of the image. The grid is still
2,862 points; 2,682 of them survive the mask.
Its figures are the closest picture of what this density looks like: the whole grid drawn over the reference image, then a true-scale zoom into one corner where the individual points finally separate.
One convenient accident makes this work without any correction.
Mathematical convolution flips the kernel before sliding it; correlation
does not. Despite its name, conv2d does not flip. It already computes
cross-correlation, which is exactly what tracking a point needs.
What conv2d Actually Computes
The shapes above say what goes in and what comes out. They say nothing about how, and the how turns out to matter for reading this page's results.
F.conv2d is not one algorithm. It is a dispatch. PyTorch hands the problem to a vendor library: oneDNN on a CPU, cuDNN on
an NVIDIA card, MPSGraph on an Apple GPU. That library then picks an
implementation based on the shapes it was given. The usual pick lowers the convolution
into a matrix multiply, an approach called implicit GEMM, so it lands on
decades of tuned linear-algebra work.
That is a sliding dot product, restructured. It is not an FFT.
cuDNN does carry FFT-based algorithms and can select them, but typically for kernels much larger than the 26x26 one this page uses. So in practice, on the shapes here, the answer is: brute force, executed extremely well.
Which lands this page on a specific side of the tradeoff that email
named. A direct sliding correlation costs roughly , where
counts search-area pixels and the kernel's side. An FFT-based one
costs roughly . The earlier work's own estimate put the FFT
about 300 times ahead for a 35 x 35 pixel kernel in a 120 x 120 pixel window.
Every CPU measurement in Subpixel Accuracy, High Point Density and Timing at Scale came from the FFT side of that cusp. Every measurement on this page comes from the brute-force side. Comparing them changes two things at once: the execution engine, and the algorithm. Keep that in view when reading the table below. A speedup here is not purely a GPU result.
One more detail worth naming. Setting groups=N over N channels makes
this a depthwise convolution — the same pattern that appears in
mobile-optimized neural networks. Vendor libraries treat depthwise
convolution as a special case with its own dedicated routines, separate
from the ones dense convolution uses. Whether that helps or hurts at
these shapes is a measurable question, not an assumable one.
Choosing a Device
PyTorch runs the same code on three kinds of hardware. Picking one is a short ladder, best to worst:
if torch.cuda.is_available():
    # NVIDIA GPU. Linux and Windows only -- Apple dropped NVIDIA support
    # years ago, so this branch never fires on a Mac.
    device, sync = torch.device("cuda"), torch.cuda.synchronize
elif torch.backends.mps.is_available():
    # Apple GPU, via Metal Performance Shaders. macOS ONLY, and only on
    # Apple silicon (M1 and later). Never available on Linux or Windows,
    # and not on an Intel Mac either.
    device, sync = torch.device("mps"), torch.mps.synchronize
else:
    # Every platform has this one. Always available, always correct,
    # never the fastest.
    device, sync = torch.device("cpu"), lambda: None
Note what that ordering implies. No single machine can take the first two branches. A CUDA card and an Apple GPU are mutually exclusive in practice, so this is not really a preference ranking — it is a portability ladder. The same source runs on a Linux workstation, a Windows box, and this laptop, and each one lands on whichever accelerator it actually has. That portability is the whole reason the 2025-04-15 email above landed on PyTorch rather than hand-written GPU code.
MPS stands for Metal Performance Shaders. It is Apple's framework for offloading matrix operations and tensor math onto the GPU built into Apple silicon — the M1, M2, M3 and M4 families. It is native, and it requires an Apple silicon Mac. It is fast for two reasons: the GPU runs enormous numbers of operations in parallel, and Apple's unified memory gives it very high bandwidth to work against.
Unified memory has a second consequence worth stating before any number gets compared across machines. On this laptop, the CPU and the GPU share one physical pool of memory. Moving an array to the GPU does not copy it across a bus. On a discrete NVIDIA card it does, because host and device hold genuinely separate memory. So transfer costs on this machine are not the transfer costs on that one. A speedup measured here does not carry over to a CUDA result.
Two practical constraints follow from the device choice.
Apple GPUs do not support float64. Every tensor downcasts to float32. This book's images are 8-bit to begin with, so the input loses nothing. The correlation arithmetic does run at lower precision than the CPU path uses. Whether that costs accuracy is measured below rather than assumed.
GPU work is queued, not immediate. A call returns as soon as the work
is submitted, long before it finishes. Timing it without a sync() call
measures how fast the queue accepts work — a number that looks
spectacular and means nothing. Every timing on this page brackets its own
synchronize call.
One thing this page's benchmark deliberately does not do: fall back to the CPU when a requested device is missing. The earlier work fell back with a printed warning, which is how a CPU measurement ends up labeled as a GPU one. A missing device here stops the run and says so.
Batching Against Device Memory
Stacking N search areas into one tensor raises a question Timing at Scale never had to ask. How much memory does that tensor take?
One search area is pixels on a side, so it holds float32 values. At the 300 pixel image size, , so that is 48 x 48 x 4 bytes, about 9 KB. Small. But Timing at Scale grows the search area along with the image, because a 2% stretch displaces a far edge further in a bigger picture. By the 10204 pixel size, , and one search area costs 420 x 420 x 4 bytes, about 706 KB.
Multiply by point count and the totals stop being comfortable:
| Width (px) | Points | Search area (px) | All search areas at once (GB) | Both images, resident (GB) |
|---|---|---|---|---|
| 300 | 2,809 | 48x48 | 0.0 | 0.00 |
| 540 | 9,216 | 58x58 | 0.1 | 0.00 |
| 972 | 29,584 | 74x74 | 0.6 | 0.01 |
| 1750 | 95,481 | 102x102 | 4.0 | 0.02 |
| 3149 | 308,025 | 156x156 | 30.0 | 0.08 |
| 5669 | 996,004 | 250x250 | 249.0 | 0.26 |
| 10204 | 3,229,209 | 420x420 | 2,278.5 | 0.83 |
| 18367 | 10,452,289 | 728x728 | 22,158.2 | 2.70 |
| 33060 | 33,860,761 | 1280x1280 | 221,909.9 | 8.74 |
| 59508 | 109,704,676 | 2274x2274 | 2,269,164.9 | 28.33 |
This machine has 32 GB, and Apple's Metal layer will admit only about 26.8 GB of it as a working set. So materializing every search area at once stops being possible somewhere between the 1750 pixel and 5669 pixel sizes.
The fix is to process points in chunks. Take a few thousand points,
build their tensors, correlate them, keep the answers, free the tensors,
move on. Chunk size becomes this page's own new variable, the way
max_workers was Parallelization's. A larger
chunk spreads each call's fixed cost over more correlations. A smaller
chunk keeps the batch inside memory. The benchmark below sizes each chunk
to fit a stated 4 GB budget and reports what it chose.
Chunking also exposes something wasteful. At 5 pixel point spacing and a 250 pixel search area, two neighboring points' search areas overlap almost completely. Materializing both copies nearly every pixel twice, and across a whole grid the same pixels get copied hundreds of times over. The correlation needs those copies laid out contiguously, so the waste buys something real. But it explains why the extraction step below costs what it does.
That waste is also the reason the last column above matters separately from the fourth. Search areas are chunkable; the two full images are not. Both images stay resident for an entire size, because every chunk cuts its windows out of them. Chunking can shrink everything except those two arrays — which is exactly what makes this page's stopping rule work, below.
Subpixel from a Correlation Surface
conv2d returns the whole correlation surface, not just its peak. That
surface is more informative than the single best-matching integer
position, and it makes subpixel accuracy nearly free.
The true peak almost never lands exactly on a sample. Fitting a parabola through the best sample and its two neighbors recovers where it actually sits:
applied independently along each axis. It costs one gather of each peak's immediate neighborhood, then arithmetic. It batches exactly the way the correlation does.
This closes one of the three gaps the earlier work left open. That implementation stopped at the integer peak and never refined it.
Parabolic fitting carries a known bias called peak locking: it pulls estimates slightly toward whole-pixel positions. Rather than assert how large that bias is, this page measures it. Every point's true destination is known exactly — a point at lands at — so both the error and the bias can be checked directly against truth. Those results appear in the next section.
Checking the Answer Before Timing It
A fast wrong answer is worthless. Before any timing on this page, the batched correlation gets checked two ways at the 300 pixel size, on every device.
Does it find the same integer positions
dictk.grid.locate finds? Not quite,
and the gap is instructive. It agrees on 2,772 of 2,809 points, 98.7%.
Every one of the 37 disagreements is off by exactly one pixel in and
zero in .
Those 37 are not errors. Checking where they fall: every disagreeing
point has a true destination whose fractional part lies between 0.460 and
0.560, averaging 0.503. They sit on the half-pixel boundary, where
rounding to a whole number is genuinely ambiguous. Phase correlation and
a sliding dot product break that tie differently. Measured against true
positions rather than against each other, the batched result is
marginally closer: 0.2598 pixels of mean absolute error against
locate's 0.2606.
How close does the refined position land? Mean absolute error against analytical truth, at the same 2,809 points:
| Method | Mean absolute error |
|---|---|
grid.locate_subpixel, upsample_factor=100 | 0.0925 px |
Batched conv2d, parabolic refinement | 0.0369 px |
The parabolic fit is 2.5 times more accurate than the upsampled-DFT refinement Subpixel Accuracy introduced, and it costs a small fraction of the correlation it rides on. That result was not expected. It is worth stating plainly that these are two different refinement mechanisms measured against the same truth, not a bug in either.
Peak locking does show up, mildly. Binning the refined positions' fractional parts into ten bins gives 330, 338, 258, 219, 280, 265, 210, 257, 313, 339 — against 280 per bin if the spread were flat. The bias pulls toward whole pixels, by roughly 20% excess in the outer bins. It is real, it is visible, and it is small enough that the method still beats the alternative above by a wide margin.
The Apple GPU produces results identical to the CPU, digit for digit, at every one of those 2,809 points. float32 costs nothing measurable here.
The Same Ladder, on PyTorch
Same image sizes, same point grids, same kernel, same search areas,
same machine. The only change is what runs the correlation.
The threads column is carried over from Timing at
Scale, unchanged. It was that page's fastest CPU
result, so it is the number worth beating:
| Width (px) | Points | Search area (px) | threads, Timing at Scale | torch CPU | torch MPS | MPS speedup vs threads |
|---|---|---|---|---|---|---|
| 300 | 2,809 | 48x48 | 1.5s | 0.3s | 0.2s | 6.2x |
| 540 | 9,216 | 58x58 | 4.9s | 1.4s | 0.5s | 9.3x |
| 972 | 29,584 | 74x74 | 16.9s | 7.8s | 1.1s | 15.7x |
| 1750 | 95,481 | 102x102 | 58.6s | 53.4s | 4.8s | 12.1x |
| 3149 | 308,025 | 156x156 | 215.2s | 512.7s | 34.6s | 6.2x |
| 5669 | 996,004 | 250x250 | 861.5s | cost gate | 256.5s | 3.4x |
| 10204 | 3,229,209 | 420x420 | timeout | not run | 39 min | — |
| 18367 | 10,452,289 | 728x728 | not run | not run | cost gate | — |
Three of those cells report a stop rather than a time. cost gate means this page's own predicted-cost rule declined to run that size, explained in Knowing When to Stop below. timeout means Timing at Scale's own 1800-second budget expired before that run finished. not run means the ladder never reached that size, because the device had already stopped one rung earlier. The remaining dash, in the speedup column, marks a ratio with no denominator to compute it from.
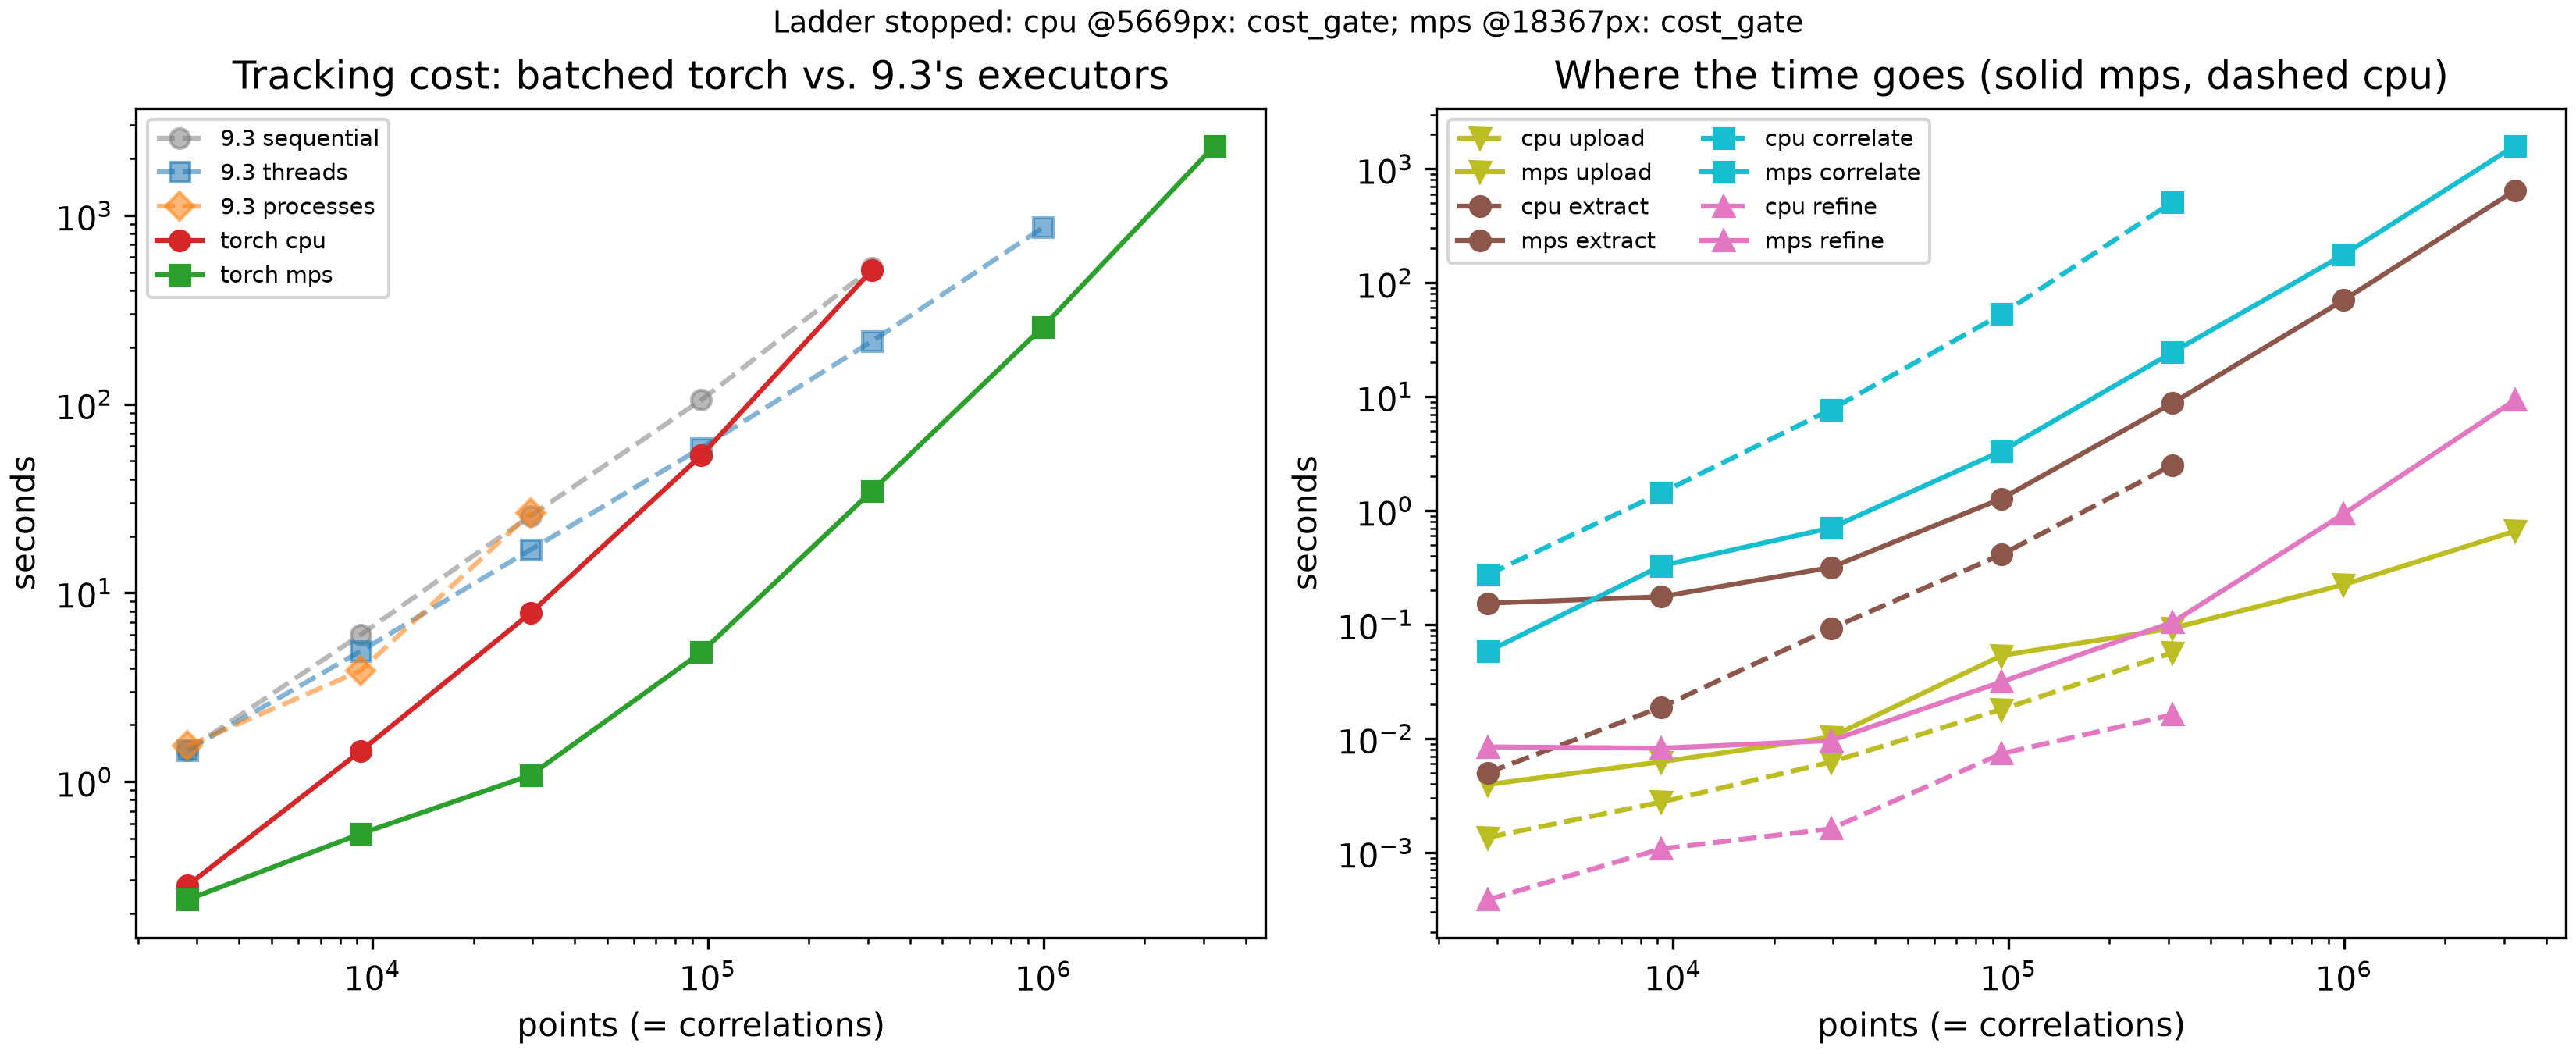
The Apple GPU wins at every size, but not by a constant factor. The way that factor moves is the most interesting thing in the table.
It climbs first. 6.2x at 2,809 points, 9.3x at 9,216, peaking at 15.7x at 29,584 points. That is batching paying off exactly as expected: more correlations per call, the same fixed cost spread thinner.
Then it falls. 12.1x, then 6.2x, then 3.4x at 996,004 points. Point count kept growing the whole time, so batching cannot explain the decline. The search area explains it.
The Cusp, Measured
Look at the torch CPU column against the threads column beside it.
Both run on the same ten cores. They differ only in algorithm.
At 29,584 points, with a 74x74 search area, torch CPU takes 7.8 seconds against 16.9. The sliding dot product wins, better than two to one.
At 95,481 points, with a 102x102 search area, they are 53.4 against 58.6. A tie.
At 308,025 points, with a 156x156 search area, torch CPU takes 512.7 seconds against 215.2. The FFT wins, better than two to one, in the other direction.
That crossover is the thing Polonsky's 2025 email predicted without being able to locate:
Depending on our subset size, we are right on the cusp of whether or not doing the FFT for cross-correlation will be faster than brute force sliding dot product.
On this machine, at this book's 26x26 kernel, the cusp sits near a
100x100 pixel search area. Below it, brute force wins. Above it, the FFT
wins. The complexity argument in What conv2d Actually Computes
predicts exactly this shape: direct correlation costs and
grows with the search area, while an FFT costs and barely
notices.
This also explains the Apple GPU's shrinking lead. The GPU is running the losing algorithm. Its hardware advantage is large enough to stay ahead anyway, but it is spending that advantage fighting an algorithm that scales worse. At 996,004 points it is still 3.4x faster than ten CPU cores, while doing asymptotically more work to get there.
Which reframes what this page found. The result is not "the GPU is 3.4x faster." It is that a GPU running the wrong algorithm still beats ten CPU cores running the right one. Nobody has combined the two yet.
Where the Time Goes
Splitting each size into its four stages answers the question hdic's own measurements raised, where building tensors cost five times what the correlation cost:
| Width (px) | Points | upload | extract | correlate | refine |
|---|---|---|---|---|---|
| 300 | 2,809 | 0.00s (2%) | 0.15s (65%) | 0.06s (25%) | 0.01s (4%) |
| 540 | 9,216 | 0.01s (1%) | 0.18s (33%) | 0.33s (62%) | 0.01s (2%) |
| 972 | 29,584 | 0.01s (1%) | 0.32s (29%) | 0.71s (65%) | 0.01s (1%) |
| 1750 | 95,481 | 0.05s (1%) | 1.28s (26%) | 3.34s (69%) | 0.03s (1%) |
| 3149 | 308,025 | 0.09s (0%) | 8.77s (25%) | 24.49s (71%) | 0.10s (0%) |
| 5669 | 996,004 | 0.22s (0%) | 70.25s (27%) | 175.54s (68%) | 0.93s (0%) |
| 10204 | 3,229,209 | 0.66s (0%) | 644.73s (28%) | 1589.20s (68%) | 9.33s (0%) |
Extraction is not the bottleneck here, and that is worth stating clearly because the earlier work found the opposite. Two differences explain it. That implementation rebuilt its tensors from NumPy on every batch, crossing the host boundary each time. This one uploads both images once per size, then cuts every window straight out of device memory. That fix came from catching this script doing the slow thing first, and measuring the difference.
Refinement costs almost nothing, which was the hope. Getting subpixel
accuracy out of a surface conv2d already computed is close to free.
Knowing When to Stop
Timing at Scale stopped each run with a 1800-second wall clock. That was the right tool there, and it is the wrong tool here.
macOS does not raise a catchable error when a process exhausts host memory. It swaps, or the kernel kills the process outright. There is no exception to catch, so a clock was the only reliable stop available.
A GPU is different. It raises a real, catchable Python exception when it runs out of device memory. So this page retires the clock and stops on two conditions instead, neither of which is an arbitrary time limit.
First, a caught out-of-memory error. This works because of the asymmetry the memory section already named. Chunking can shrink every per-point tensor, so chunking alone never runs out. The two full images cannot be chunked — both stay resident for an entire size. That unchunkable part is what eventually fails. Before each size, the benchmark computes what those two images will need and compares it against what the device will admit. Then it attempts the size anyway, and catches whatever actually happens. A prediction earns its place only if the measurement gets a chance to contradict it.
Finding the right exception took a deliberate test rather than an
assumption. Apple's Metal layer reports running out of memory in more
than one way, and only one of them uses the phrase "out of memory". An
allocation past the remaining budget raises MPS backend out of memory.
A single tensor past Metal's per-buffer ceiling raises Invalid buffer size: 3013.73 GiB instead, which never says "memory" at all. Forcing
both conditions on purpose, at a small size, revealed the second one.
Trusting the first message to be the only one would have turned a real
memory finding into an unexplained crash.
Second, a predicted-cost gate. Compute grows faster than memory here, so the ladder becomes impractical before it becomes impossible. Each size predicts its own cost from the previous size's measured rate, counting both point count and per-correlation size. A prediction past one hour stops that device, and the prediction gets recorded along with the measurement it came from.
That is not a new idea on this page. Timing at Scale already reasoned this way twice: it stopped a run deliberately once its cause was understood, and it extrapolated a measured rate out to 1.4 weeks rather than spending 1.4 weeks confirming it. The change here is making that reasoning the rule up front, instead of a judgment call afterward.
A wall-clock watchdog does still exist, set at four hours. Its only job is to stop an unattended overnight run from hanging forever on a wedged GPU driver. It sits far past anything the cost gate would allow. So if it ever fires, that is a harness problem to investigate, not a finding about scaling. There, the timeout was the finding. Here it must never be.
Where It Breaks
Neither device ran out of memory. Not once, at any size.
That is worth stating bluntly, because this page was built expecting the opposite. The stopping rules above put a caught out-of-memory error first, and worked out in advance which size should trigger it. The measurement contradicted the prediction. The cost gate fired first, on both devices, and the memory wall was never reached.
The numbers are not close. At the largest size either device attempted, the two resident images occupied 0.83 GB of Metal's 26.8 GB budget — about 3%. Peak host memory across the entire run reached 13.9 GB of 32. The prediction that images would eventually stop fitting is still arithmetically correct, at a size around 59508 pixels. This ladder simply never gets there, because the arithmetic to process such a size takes longer than anyone would wait.
cpu stopped at 5669 pixels. Its own measured rate at 3149 pixels
predicted 4,890 seconds for the next size, past the one-hour budget. The
prediction was recorded rather than run.
mps went two sizes further. It completed 10204 pixels — 3,229,209
points in 2,334.7 seconds — then predicted 23,937 seconds for 18367
pixels and stopped.
That 10204 pixel size is the interesting one. Timing at Scale attempted exactly it, with threads, and could not finish it. The Apple GPU completed it in 39 minutes.
Throughput Rises, Then Falls
Points tracked per second, at each size mps completed:
| Width (px) | Search area (px) | Points | Seconds | Points/second | 1e9 points would take (h) |
|---|---|---|---|---|---|
| 300 | 48x48 | 2,809 | 0.2 | 11,868 | 23 |
| 540 | 58x58 | 9,216 | 0.5 | 17,415 | 16 |
| 972 | 74x74 | 29,584 | 1.1 | 27,374 | 10 |
| 1750 | 102x102 | 95,481 | 4.8 | 19,723 | 14 |
| 3149 | 156x156 | 308,025 | 34.6 | 8,890 | 31 |
| 5669 | 250x250 | 996,004 | 256.5 | 3,884 | 72 |
| 10204 | 420x420 | 3,229,209 | 2,334.7 | 1,383 | 201 |
Throughput climbs to 27,374 points per second at 29,584 points, then falls away steadily. By the largest size it has dropped to 1,383, a twentyfold decline.
Point count is not the cause. Point count only ever increased. The search area is the cause. The CPU comparison already showed why: a sliding dot product's work grows with the area it slides over, and this ladder grows that area at every rung.
Which makes the last column read as a warning rather than a forecast. "How long would a billion correlations take" has no single answer here. It is 10 hours at a 74x74 search area and 201 hours at a 420x420 one, using the same hardware, the same code, and the same algorithm. Search area, not point count, is what decides.
Against Timing at Scale's own closing extrapolation, measured at the same 996,004-point size: threads managed 1,156 points per second, which is where that page's estimate of roughly 1.4 weeks for a billion came from. The Apple GPU manages 3,884 at the same size. Same problem, same machine, about 3 days instead of 10.
That is a real improvement and it is not enough. A billion correlations is Path Forward's entry-level target, not its ceiling. Three days of continuous computation for the smallest interesting problem still rules out the tens of billions that page names as realistic.
The encouraging part is where the remaining headroom sits. This page spent its entire GPU advantage running the algorithm that the cusp measurement above shows is the wrong one at these search areas. Nothing here has yet combined the better hardware with the better algorithm.
CUDA, Pending
This page has no NVIDIA results.
The machine to run them on exists: a Windows workstation with a CUDA card, the same one that produced the 2025 measurements quoted at the top of this page. Access to it is pending, so the CUDA column below stays empty rather than estimated.
The benchmark already supports it. device_select resolves cuda first
when a CUDA device is visible, and every timing already brackets the
correct per-device synchronize call. Running this page's ladder there
requires no code change — only the machine.
Two things are worth knowing in advance about how that comparison will
read. The unified memory point above means transfer costs will differ
structurally, not just in magnitude. And cuDNN chooses among more
convolution algorithms than Metal does, including FFT-based ones. So the
dispatch question in What conv2d Actually Computes may resolve
differently there.
What Comes Next
The FFT gap is still open, and it is now the obvious next step.
Every correlation on this page is a sliding dot product. Every CPU correlation in Subpixel Accuracy, High Point Density and Timing at Scale is an FFT. Those are the two sides of the cusp Polonsky's 2025 email named. This book has now measured each side on different hardware. That is exactly the comparison that cannot settle the question.
A batched torch.fft phase correlation would settle it. It would run the
same algorithm the three pages above already use, on the same devices
this page already measures. That makes the comparison engine-for-engine,
instead of across two variables at once. It would also reuse this page's chunking,
its device selection, and its stopping rules unchanged.
That work is not started.
parallelism_pytorch_bench.py
"""Parallelism with PyTorch: rerun Timing at Scale's own ladder on a
batched PyTorch correlation, on this machine (Apple M1 Pro, 32GB RAM,
10 cores -- see parallelism_pytorch.md's own Test Machine section),
across every device this machine offers.
Timing at Scale (9.3) tracked one point per `dictk.grid.locate_subpixel`
call, and every call ran its own FFT. This script replaces that inner
loop entirely. It stacks many search windows into one tensor, many
kernels into another, and correlates all of them in a single
`F.conv2d` call -- the grouped-convolution trick hdic's own
`xcorr_pytorch.py` established (see parallelism_pytorch.md for the
attribution and the shape derivation).
Not part of the dictk package -- a standalone, one-time measurement
script, matching timing_at_scale_bench.py's and parallelization_bench.py's
own precedent. Its output (parallelism_pytorch_bench.csv,
parallelism_pytorch_bench.png) is committed alongside it rather than
regenerated on every book build.
dictk itself does not depend on PyTorch, and this script does not change
that. It guards its own imports and exits with a message rather than a
traceback when torch is missing. See torch_require below.
Geometry is imported from timing_at_scale_bench, never redefined here.
Same kernel margin, same stretch factor, same origin fraction, same
spacing, same rosta parameters, same geometric ladder. A number this
script produces is only comparable to 9.3's if the geometry underneath
it is identical, so it is taken from 9.3's own module rather than
copied.
Stopping rules (read before changing the ladder): 9.3's own 1800-second
per-tier wall clock is NOT reused. macOS gives no catchable MemoryError,
so 9.3 had no better option. A GPU does: it raises a real, catchable
out-of-memory exception. This script therefore stops on three
conditions, in priority order --
1. A caught out-of-memory error. Search windows are chunkable, so
chunking alone never runs out. The two full images are not
chunkable; both stay resident for the whole size. That unchunkable
residency is what eventually fails, and _memory_predict reports the
prediction before each size so the measurement can confirm or
contradict it.
2. The predicted-cost gate. Compute grows faster than memory here, so
the ladder turns impractical before it turns impossible. Each size
predicts its own cost from the PREVIOUS size's measured throughput.
A prediction past COST_BUDGET_S stops that device, and the
prediction is written to the CSV with the throughput it came from.
3. WATCHDOG_S, a harness safety net only. It exists so an unattended
run cannot hang forever on a wedged GPU driver. It is set far past
anything the cost gate would allow. If it ever fires, that is a
harness problem to investigate, not a finding about scaling --
unlike 9.3, where the timeout WAS the finding.
Must be a real module, not `python3 -c` -- the controller re-invokes
this same file as a subprocess per (width, device).
Re-run with: python3 parallelism_pytorch_bench.py
Run the correctness gates alone:
python3 parallelism_pytorch_bench.py --check
Re-run a single (width, device) directly:
python3 parallelism_pytorch_bench.py --worker 3149 mps
"""
import csv
import os
import platform
import resource
import subprocess
import sys
import time
from pathlib import Path
import matplotlib.pyplot as plt
import numpy as np
from dictk.grid import generate, locate, locate_subpixel
from dictk.image import PixelCoordinate, stretch
from dictk.rosta import rosta
# Geometry comes from 9.3's own module, never redefined here -- see the
# module docstring for why. Importing it also keeps this script honest if
# 9.3's ladder is ever retuned: both pages move together, or neither does.
import timing_at_scale_bench as bench
CSV_PATH = Path(__file__).parent / "parallelism_pytorch_bench.csv"
PNG_PATH = Path(__file__).parent / "parallelism_pytorch_bench.png"
TIMING_CSV = Path(__file__).parent / "timing_at_scale_bench.csv"
DEVICES = ("cpu", "mps", "cuda")
# Chunk budget, in GB of device allocation per batch. Deliberately well
# under this machine's own ~26.8GB MPS working set: the two full images
# stay resident for the whole size on top of whatever a chunk holds, and
# a chunk allocates its windows, its correlation surfaces, and its
# kernels all at once. 4GB leaves room for all of that at every size the
# ladder reaches.
CHUNK_BUDGET_GB = 4.0
# Predicted-cost gate. A size whose predicted wall time exceeds this,
# extrapolated from the previous size's own measured throughput, is not
# attempted -- the prediction is recorded instead. One hour is a
# deliberate choice, not a tuned constant: it is long enough that every
# size the ladder can actually finish gets measured, and short enough
# that the two sizes past this machine's practical limit (roughly 10
# hours and 104 hours of arithmetic, by the FLOP estimate on the page)
# are reported rather than run.
COST_BUDGET_S = 3600.0
# Harness safety net ONLY -- see the module docstring's own stopping-rules
# note. This must never be the reason a result is reported. Four hours is
# far past COST_BUDGET_S, so a size that fires this one has hung rather
# than merely run long.
WATCHDOG_S = 4 * 3600
def torch_require():
"""Imports torch, or exits with a message instead of a traceback.
dictk does not depend on PyTorch. This script does. A missing
install is an ordinary, expected situation for someone reading the
book, so it gets an explanation rather than an ImportError.
"""
try:
import torch
import torch.nn.functional as functional
except ImportError:
print(
"PyTorch is required to run this benchmark, and is not installed.\n"
"\n"
"dictk itself does not depend on PyTorch. This standalone\n"
"benchmark script does, and it is the only thing in the book\n"
"that does.\n"
"\n"
"Install it with:\n"
" uv pip install torch\n"
"\n"
"Platform-specific builds (CUDA, ROCm, CPU-only):\n"
" https://pytorch.org/get-started/locally/",
file=sys.stderr,
)
raise SystemExit(1)
return torch, functional
def device_select(*, prefer: str):
"""Resolves `prefer` to a real torch device, or exits explaining why
it cannot.
Returns `(device, sync)`. `sync` blocks until queued work on that
device has actually finished. GPU work is submitted asynchronously,
so a timer that doesn't call it measures queue submission rather
than computation.
This never silently falls back to CPU. hdic's own xcorr_pytorch.py
fell back with a printed warning, which is how a CPU measurement
ends up labeled as a GPU one. A results table that mislabels its own
device is worse than a missing row.
"""
torch, _ = torch_require()
# No machine ever offers both accelerators. "mps" is macOS only, and
# only on Apple silicon (M1 and later) -- never Linux, never Windows,
# not even an Intel Mac. "cuda" needs an NVIDIA card, which in practice
# means Linux or Windows, since Apple dropped NVIDIA support years ago.
# "cpu" is the only entry every platform always has.
available = ["cpu"]
if torch.backends.mps.is_available():
available.append("mps")
if torch.cuda.is_available():
available.append("cuda")
if prefer not in available:
if prefer == "mps":
why = (
"this machine is not Apple silicon, or this torch build\n"
" has no Metal support"
if not torch.backends.mps.is_built()
else "torch was built with Metal support, but no MPS device\n"
" is available here"
)
elif prefer == "cuda":
why = "no CUDA device is visible to torch on this machine"
else:
why = "unrecognized device name"
print(
f"Device '{prefer}' was requested and is not available.\n"
f" Reason: {why}\n"
f" This machine offers: {', '.join(available)}\n"
f" Platform: {platform.platform()}\n"
f" torch: {torch.__version__}\n"
"\n"
"Not falling back to another device -- a timing labeled with\n"
"the wrong device would corrupt this benchmark's own results.",
file=sys.stderr,
)
raise SystemExit(2)
device = torch.device(prefer)
if prefer == "cuda":
sync = torch.cuda.synchronize
elif prefer == "mps":
sync = torch.mps.synchronize
else:
def sync():
return None
return device, sync
def device_budget_gb(*, prefer: str) -> float:
"""How much memory this device will admit, in GB.
MPS reports a recommended working set rather than the full unified
pool -- Metal will refuse allocations past it even though the host
has more RAM installed. CUDA reports its own card's total. CPU falls
back to installed system memory.
"""
torch, _ = torch_require()
if prefer == "mps":
return torch.mps.recommended_max_memory() / 1e9
if prefer == "cuda":
return torch.cuda.mem_get_info()[1] / 1e9
if platform.system() == "Darwin":
out = subprocess.run(
["sysctl", "-n", "hw.memsize"], capture_output=True, text=True, check=True
)
return int(out.stdout.strip()) / 1e9
return os.sysconf("SC_PAGE_SIZE") * os.sysconf("SC_PHYS_PAGES") / 1e9
def bytes_per_point(*, search: int, kernel: int) -> int:
"""Device bytes one point costs inside a chunk, as float32.
Three allocations, not one: its search window, the correlation
surface that window produces, and its kernel. The surface is nearly
as large as the window itself, so counting only the window
underestimates a chunk by roughly half.
"""
out = search - kernel + 1
return 4 * (search * search + out * out + kernel * kernel)
def chunk_size_for(*, search: int, kernel: int, budget_gb: float) -> int:
"""Largest point count whose chunk fits `budget_gb`."""
return max(1, int(budget_gb * 1e9 // bytes_per_point(search=search, kernel=kernel)))
def image_resident_gb(*, width: int) -> float:
"""Device GB the two full images occupy, as float32.
This is the part of the problem chunking cannot shrink. Both images
stay resident for an entire size, because every chunk extracts its
windows from them. When this alone exceeds the device budget, the
size is impossible at any chunk size.
"""
return 2 * width * width * 4 / 1e9
def _peak_rss_gb() -> float:
"""Peak resident set size so far, in GB. macOS reports ru_maxrss in
bytes; Linux reports it in KB."""
raw = resource.getrusage(resource.RUSAGE_SELF).ru_maxrss
return raw / 1e9 if platform.system() == "Darwin" else raw * 1024 / 1e9
def _append_row(
*,
width: int,
points: int,
device: str,
chunk: int,
stage: str,
seconds: float,
peak_rss_gb: float,
note: str = "",
) -> None:
"""Appends and flushes one CSV row immediately -- not batched -- so a
later crash loses nothing already measured. Same approach 9.3 used,
for the same reason."""
is_new = not CSV_PATH.exists()
with open(CSV_PATH, "a", newline="") as f:
writer = csv.writer(f)
if is_new:
writer.writerow(
[
"width",
"points",
"device",
"chunk",
"stage",
"seconds",
"peak_rss_gb",
"note",
]
)
writer.writerow(
[
width,
points,
device,
chunk,
stage,
f"{seconds:.6f}",
f"{peak_rss_gb:.4f}",
note,
]
)
f.flush()
os.fsync(f.fileno())
def images_build(*, width: int) -> tuple[np.ndarray, np.ndarray]:
"""Reference and current image at this size, exactly as 9.3 built
them: pure rosta speckle, rescaled dot size, 2% stretch in x."""
dot_size, smoothness = bench.rosta_params_for(width)
reference_image = rosta(
width=width,
height=width,
dot_size=dot_size,
smoothness=smoothness,
density=bench.DENSITY,
)
current_image = stretch(arr=reference_image, factor_x=bench.FACTOR_X)
return reference_image, current_image
def image_upload(*, image: np.ndarray, pad: int, device):
"""Uploads one image to the device, padded, as float32. Once.
This is the allocation the memory section of parallelism_pytorch.md
calls unchunkable. It is deliberately hoisted out of the chunk loop:
a first version of this script rebuilt it inside `windows_extract`,
which re-converted and re-uploaded the entire image twice per chunk.
At the 3149px size that is 26 redundant uploads of a 40MB array, and
it inflated the measured extraction cost by a wide margin. Build it
once per size, index it many times.
`pad` zero-fills a border wide enough that a window straddling an
edge reads zeros rather than wrapping or raising. That matches
`dictk.image.subimage`, which zero-fills outside the image, so a
point near a border tracks the same way here as it does everywhere
else in this book.
"""
torch, functional = torch_require()
return functional.pad(
torch.from_numpy(np.ascontiguousarray(image)).to(torch.float32),
(pad, pad, pad, pad),
).to(device)
def windows_extract(*, resident, origins_x, origins_y, size: int, pad: int):
"""Stacks one `size` x `size` window per origin into a single
`(N, size, size)` tensor, cut from an already-resident padded image.
The gather is advanced indexing, not a Python loop. This is the step
that allocates a chunk's largest tensor, and on real DIC geometry it
copies heavily overlapping data -- neighboring windows at 5px spacing
share almost every pixel.
"""
torch, _ = torch_require()
device = resident.device
rows = (origins_y + pad).reshape(-1, 1) + torch.arange(size, device=device)
cols = (origins_x + pad).reshape(-1, 1) + torch.arange(size, device=device)
return resident[rows[:, :, None], cols[:, None, :]]
def batch_correlate(*, kernels, windows):
"""Correlates each kernel against its own search window, in one call.
Shapes, for N points, a `K` x `K` kernel and an `S` x `S` search
window:
windows -> (1, N, S, S) N windows stacked as CHANNELS
kernels -> (N, 1, K, K) N kernels as N separate groups
output -> (1, N, S-K+1, S-K+1)
`groups=N` is the load-bearing argument. It splits the N input
channels into N groups of one, so kernel `i` sees window `i` and
nothing else. Without it, conv2d would compute the full N x N cross
product -- every kernel against every window -- which is both wrong
and N times more work.
`conv2d` is already cross-correlation. It does not flip the kernel
the way a mathematical convolution does, so no flip is needed here.
Both inputs are normalized to zero mean and unit standard deviation
beforehand, once per window and once per kernel. That is hdic's own
approach, and it makes a plain correlation behave like ZNCC. It is
an approximation: true ZNCC recomputes local statistics at every
sliding position, which costs two more conv2d passes. See
parallelism_pytorch.md for what that approximation measurably costs.
"""
_, functional = torch_require()
kernels = (kernels - kernels.mean((1, 2), keepdim=True)) / kernels.std(
(1, 2), keepdim=True
).clamp_min(1e-12)
windows = (windows - windows.mean((1, 2), keepdim=True)) / windows.std(
(1, 2), keepdim=True
).clamp_min(1e-12)
return functional.conv2d(
windows.unsqueeze(0), kernels.unsqueeze(1), groups=windows.shape[0]
)[0]
def peaks_locate(*, surfaces):
"""Integer peak of every correlation surface, as `(rows, cols)`."""
flat = surfaces.reshape(surfaces.shape[0], -1).argmax(dim=1)
width = surfaces.shape[-1]
return flat // width, flat % width
def peak_refine(*, surfaces, rows, cols):
"""Fractional offset of each peak, by a three-point parabolic fit.
conv2d returns the whole correlation surface, not just its peak. The
peak's true position is generally between samples, and fitting a
parabola through the peak and its two neighbours recovers where:
delta = 0.5 * (C[-1] - C[+1]) / (C[-1] - 2 C[0] + C[+1])
applied independently per axis. One gather of each peak's
neighbourhood, then arithmetic -- it batches exactly like the
correlation does, and costs a small fraction of it.
A parabolic fit exhibits peak locking: it pulls estimates slightly
toward integer positions. parallelism_pytorch.md measures that bias
directly rather than assuming its size.
Peaks on a surface's own border have no neighbour on one side. Those
are clamped inward, which biases them, but a peak on the border
already means the search area was too small for that point.
"""
torch, _ = torch_require()
height, width = surfaces.shape[-2], surfaces.shape[-1]
rows_in = rows.clamp(1, height - 2)
cols_in = cols.clamp(1, width - 2)
index = torch.arange(surfaces.shape[0], device=surfaces.device)
def at(row_offset, col_offset):
return surfaces[index, rows_in + row_offset, cols_in + col_offset]
def delta(minus, center, plus):
denominator = minus - 2 * center + plus
return torch.where(
denominator.abs() < 1e-12,
torch.zeros_like(denominator),
0.5 * (minus - plus) / denominator,
)
center = at(0, 0)
return (
delta(at(-1, 0), center, at(1, 0)),
delta(at(0, -1), center, at(0, 1)),
)
def track_batched(
*,
reference_image: np.ndarray,
current_image: np.ndarray,
points,
kernel_margin: int,
search_margin: int,
device_name: str,
chunk: int,
refine: bool = True,
):
"""Tracks every point through batched correlation, one chunk at a time.
Returns `(xs, ys, timings)`. `timings` splits the work into `upload`,
`extract`, `correlate` and `refine`. `upload` happens once per size;
the other three are summed across chunks. That split is the point:
the earlier work's own measurements found tensor creation costing five
times what the correlation cost, and a single total would have hidden
it completely.
"""
torch, _ = torch_require()
device, sync = device_select(prefer=device_name)
kernel = 2 * kernel_margin
search = 2 * search_margin
xs = np.empty(len(points), dtype=np.float64)
ys = np.empty(len(points), dtype=np.float64)
timings = {"upload": 0.0, "extract": 0.0, "correlate": 0.0, "refine": 0.0}
# Both images go to the device once, before any chunk runs. See
# image_upload's own docstring for what building them per chunk
# cost instead.
sync()
mark = time.perf_counter()
reference_resident = image_upload(image=reference_image, pad=search, device=device)
current_resident = image_upload(image=current_image, pad=search, device=device)
points_x = torch.tensor([p.x for p in points], device=device)
points_y = torch.tensor([p.y for p in points], device=device)
sync()
timings["upload"] += time.perf_counter() - mark
for start in range(0, len(points), chunk):
stop = min(start + chunk, len(points))
chunk_x = points_x[start:stop]
chunk_y = points_y[start:stop]
sync()
mark = time.perf_counter()
kernels = windows_extract(
resident=reference_resident,
origins_x=chunk_x - kernel_margin,
origins_y=chunk_y - kernel_margin,
size=kernel,
pad=search,
)
windows = windows_extract(
resident=current_resident,
origins_x=chunk_x - search_margin,
origins_y=chunk_y - search_margin,
size=search,
pad=search,
)
sync()
timings["extract"] += time.perf_counter() - mark
mark = time.perf_counter()
surfaces = batch_correlate(kernels=kernels, windows=windows)
rows, cols = peaks_locate(surfaces=surfaces)
sync()
timings["correlate"] += time.perf_counter() - mark
mark = time.perf_counter()
if refine:
row_delta, col_delta = peak_refine(surfaces=surfaces, rows=rows, cols=cols)
else:
row_delta = torch.zeros_like(rows, dtype=torch.float32)
col_delta = torch.zeros_like(cols, dtype=torch.float32)
found_x = (chunk_x - search_margin + cols + kernel_margin) + col_delta
found_y = (chunk_y - search_margin + rows + kernel_margin) + row_delta
sync()
timings["refine"] += time.perf_counter() - mark
xs[start:stop] = found_x.to("cpu").numpy()
ys[start:stop] = found_y.to("cpu").numpy()
del kernels, windows, surfaces
if device_name == "mps":
torch.mps.empty_cache()
elif device_name == "cuda":
torch.cuda.empty_cache()
return xs, ys, timings
# Metal reports running out of memory in more than one way, and only one
# of them says "out of memory". A request past the allocator's remaining
# budget raises "MPS backend out of memory (MPS allocated: ..., max
# allowed: ...)". A single tensor past Metal's own per-buffer ceiling
# raises "Invalid buffer size: 3013.73 GiB" instead, which never uses the
# phrase at all. Both mean the same thing here -- the device would not
# give us the memory -- so both belong in this list. Found by deliberately
# forcing an oversized allocation rather than by trusting the first
# message to be the only one.
_OUT_OF_MEMORY_PHRASES = (
"out of memory",
"invalid buffer size",
"can't allocate memory",
)
def _is_out_of_memory(error: BaseException) -> bool:
"""Whether `error` is a device out-of-memory report.
CUDA raises a dedicated class. Metal raises a plain RuntimeError
whose message names the condition, so on that backend the message
text is the only signal available.
"""
torch, _ = torch_require()
if isinstance(error, getattr(torch, "OutOfMemoryError", ())):
return True
if not isinstance(error, RuntimeError):
return False
message = str(error).lower()
return any(phrase in message for phrase in _OUT_OF_MEMORY_PHRASES)
def checks_run(*, width: int = bench.BASE_WIDTH) -> None:
"""Correctness gates. These run before any timing is trusted.
Two questions, kept separate. Does the batched correlation find the
same integer positions dictk.grid.locate already finds? And how close
does the refined position land to the analytically known truth,
compared with dictk.grid.locate_subpixel?
"""
torch, _ = torch_require()
reference_image, current_image = images_build(width=width)
origin, count, search_margin = bench.grid_params(width)
kernel_margin = bench.KERNEL_MARGIN
points = generate(
origin=PixelCoordinate(x=origin, y=origin),
count_x=count,
count_y=count,
spacing_x=bench.SPACING,
spacing_y=bench.SPACING,
)
truth_x = np.array([p.x for p in points], dtype=np.float64) * bench.FACTOR_X
integer = locate(
reference_image=reference_image,
current_image=current_image,
reference_points=points,
kernel_margin_width=kernel_margin,
kernel_margin_height=kernel_margin,
search_margin_width=search_margin,
search_margin_height=search_margin,
)
subpixel = locate_subpixel(
reference_image=reference_image,
current_image=current_image,
reference_points=points,
kernel_margin_width=kernel_margin,
kernel_margin_height=kernel_margin,
search_margin_width=search_margin,
search_margin_height=search_margin,
upsample_factor=bench.UPSAMPLE_FACTOR,
)
locate_x = np.array([p.x for p in integer], dtype=np.float64)
locate_y = np.array([p.y for p in integer], dtype=np.float64)
subpixel_x = np.array([p.x for p in subpixel], dtype=np.float64)
chunk = chunk_size_for(
search=2 * search_margin,
kernel=2 * kernel_margin,
budget_gb=CHUNK_BUDGET_GB,
)
print(f"Correctness gates at width={width}, {len(points):,} points")
print(
f" kernel {2 * kernel_margin}x{2 * kernel_margin}, "
f"search {2 * search_margin}x{2 * search_margin}, chunk {chunk:,}"
)
print(
f" grid.locate_subpixel MAE vs truth: "
f"{np.abs(subpixel_x - truth_x).mean():.4f} px"
)
for device_name in DEVICES:
try:
device_select(prefer=device_name)
except SystemExit:
print(f" {device_name}: unavailable, skipped")
continue
integer_x, integer_y, _ = track_batched(
reference_image=reference_image,
current_image=current_image,
points=points,
kernel_margin=kernel_margin,
search_margin=search_margin,
device_name=device_name,
chunk=chunk,
refine=False,
)
agree = int(((integer_x == locate_x) & (integer_y == locate_y)).sum())
disagree = integer_x != locate_x
fractional = np.abs(truth_x - np.floor(truth_x))
refined_x, _, _ = track_batched(
reference_image=reference_image,
current_image=current_image,
points=points,
kernel_margin=kernel_margin,
search_margin=search_margin,
device_name=device_name,
chunk=chunk,
refine=True,
)
error = np.abs(refined_x - truth_x)
parts = refined_x - np.floor(refined_x)
histogram, _ = np.histogram(parts, bins=10, range=(0.0, 1.0))
print(f" {device_name}:")
print(
f" integer agreement with grid.locate: {agree:,}/{len(points):,} "
f"({100 * agree / len(points):.1f}%)"
)
if disagree.any():
print(
f" disagreeing points' true fractional part: "
f"{fractional[disagree].min():.3f}..{fractional[disagree].max():.3f} "
f"(mean {fractional[disagree].mean():.3f})"
)
print(f" refined MAE vs truth: {error.mean():.4f} px")
print(
f" fractional-part histogram (flat would be "
f"{len(points) // 10:,} each): {histogram.tolist()}"
)
def work_units(*, width: int) -> float:
"""Multiply-accumulates one size costs, as a scaling proxy.
Point count alone is the wrong predictor here. 9.3's ladder grows the
search area alongside the point count, because a 2% stretch displaces
a far edge further in a larger image (see Timing at Scale's own
geometry table). Work per point therefore grows too. This counts
both: output positions per point, times kernel pixels, times points.
"""
_, count, search_margin = bench.grid_params(width)
kernel = 2 * bench.KERNEL_MARGIN
outputs = (2 * search_margin - kernel + 1) ** 2
return float(count * count) * outputs * kernel * kernel
def size_run(*, width: int, device_name: str) -> None:
"""Runs one (width, device) rung and appends its rows.
Records the memory prediction first, then attempts the size anyway.
A prediction only earns its place if the measurement gets a chance to
contradict it.
"""
device_select(prefer=device_name)
budget = device_budget_gb(prefer=device_name)
resident = image_resident_gb(width=width)
origin, count, search_margin = bench.grid_params(width)
points_total = count * count
chunk = chunk_size_for(
search=2 * search_margin,
kernel=2 * bench.KERNEL_MARGIN,
budget_gb=CHUNK_BUDGET_GB,
)
_append_row(
width=width,
points=points_total,
device=device_name,
chunk=chunk,
stage="predict_memory",
seconds=float("nan"),
peak_rss_gb=_peak_rss_gb(),
note=f"images {resident:.2f}GB of {budget:.2f}GB budget"
+ (" EXCEEDS" if resident > budget else ""),
)
mark = time.perf_counter()
reference_image, current_image = images_build(width=width)
_append_row(
width=width,
points=0,
device=device_name,
chunk=chunk,
stage="images",
seconds=time.perf_counter() - mark,
peak_rss_gb=_peak_rss_gb(),
)
points = generate(
origin=PixelCoordinate(x=origin, y=origin),
count_x=count,
count_y=count,
spacing_x=bench.SPACING,
spacing_y=bench.SPACING,
)
mark = time.perf_counter()
try:
found_x, _, timings = track_batched(
reference_image=reference_image,
current_image=current_image,
points=points,
kernel_margin=bench.KERNEL_MARGIN,
search_margin=search_margin,
device_name=device_name,
chunk=chunk,
)
except Exception as error: # noqa: BLE001 -- re-raised below unless OOM
if not _is_out_of_memory(error):
raise
_append_row(
width=width,
points=points_total,
device=device_name,
chunk=chunk,
stage="FAILED_oom",
seconds=time.perf_counter() - mark,
peak_rss_gb=_peak_rss_gb(),
note=str(error).replace("\n", " ")[:300],
)
print(f" {device_name} @{width}px: OUT OF MEMORY (caught)")
raise SystemExit(3)
elapsed = time.perf_counter() - mark
for stage, seconds in timings.items():
_append_row(
width=width,
points=points_total,
device=device_name,
chunk=chunk,
stage=stage,
seconds=seconds,
peak_rss_gb=_peak_rss_gb(),
)
_append_row(
width=width,
points=points_total,
device=device_name,
chunk=chunk,
stage="total",
seconds=elapsed,
peak_rss_gb=_peak_rss_gb(),
note=f"{points_total / elapsed:,.0f} points/s",
)
# Same sampled spot-check 9.3 used. A wrong search margin shows up
# here before it shows up as a confusing shape in the timing plot.
true_x = np.array([p.x for p in points], dtype=np.float64) * bench.FACTOR_X
sample = np.random.default_rng(0).choice(
len(points), size=min(50, len(points)), replace=False
)
worst = float(np.abs(found_x[sample] - true_x[sample]).max())
if worst > 1.0:
print(
f"WARNING width={width} device={device_name}: sampled max tracking "
f"error {worst:.2f}px -- search_margin may be too small here",
file=sys.stderr,
)
def _measured() -> dict[tuple[int, str], float]:
"""Every (width, device) total already measured, from the CSV."""
if not CSV_PATH.exists():
return {}
with open(CSV_PATH) as f:
return {
(int(r["width"]), r["device"]): float(r["seconds"])
for r in csv.DictReader(f)
if r["stage"] == "total"
}
def ladder_run() -> None:
"""Walks every device up the ladder, stopping each one on its own terms."""
torch_require()
measured = _measured()
available = []
for device_name in DEVICES:
try:
device_select(prefer=device_name)
except SystemExit:
print(f"Skipping {device_name}: not available on this machine")
continue
available.append(device_name)
for device_name in available:
budget = device_budget_gb(prefer=device_name)
print(f"=== {device_name} (budget {budget:.1f}GB) ===")
for width in bench._widths():
_, count, _ = bench.grid_params(width)
points_total = count * count
if (width, device_name) in measured:
print(f" {width}px: already measured, skipping")
continue
# Stop 2: predicted-cost gate, from the previous size's own
# measured rate on this same device. Reported, not run.
previous = [w for w in bench._widths() if (w, device_name) in measured]
if previous:
last = previous[-1]
rate = work_units(width=last) / measured[(last, device_name)]
predicted = work_units(width=width) / rate
if predicted > COST_BUDGET_S:
note = (
f"predicted {predicted:,.0f}s from {last}px rate "
f"({measured[(last, device_name)]:.1f}s), "
f"budget {COST_BUDGET_S:,.0f}s"
)
print(f" {width}px: COST GATE -- {note}")
_append_row(
width=width,
points=points_total,
device=device_name,
chunk=0,
stage="STOPPED_cost_gate",
seconds=predicted,
peak_rss_gb=float("nan"),
note=note,
)
break
try:
result = subprocess.run(
[sys.executable, __file__, "--worker", str(width), device_name],
timeout=WATCHDOG_S,
capture_output=True,
text=True,
)
except subprocess.TimeoutExpired:
# Harness event, not a scaling finding -- see the module
# docstring. Reaching this means something hung.
print(f" {width}px: WATCHDOG FIRED after {WATCHDOG_S}s -- investigate")
_append_row(
width=width,
points=points_total,
device=device_name,
chunk=0,
stage="HARNESS_watchdog",
seconds=float(WATCHDOG_S),
peak_rss_gb=float("nan"),
note="harness event, not a scaling result",
)
break
if result.returncode != 0:
print(f" {width}px: stopped (returncode={result.returncode})")
if result.stdout.strip():
print(" ", result.stdout.strip().splitlines()[-1])
if result.returncode != 3:
print(result.stderr[-800:])
_append_row(
width=width,
points=points_total,
device=device_name,
chunk=0,
stage=f"FAILED_returncode_{result.returncode}",
seconds=float("nan"),
peak_rss_gb=float("nan"),
note=result.stderr.strip().splitlines()[-1][:200]
if result.stderr.strip()
else "",
)
break
measured = _measured()
print(f" {width}px: {measured[(width, device_name)]:.1f}s")
if result.stderr.strip():
print(f" stderr: {result.stderr.strip()[-300:]}")
print(f"Wrote {CSV_PATH}")
def summary_plot() -> None:
"""Two panels: this page's devices against 9.3's own executors, and
where each size's time actually goes."""
with open(CSV_PATH) as f:
rows = list(csv.DictReader(f))
figure, (ax_compare, ax_split) = plt.subplots(
1, 2, figsize=(11, 4.5), constrained_layout=True
)
# Left: 9.3's committed CPU series, then this page's torch series on
# the same axes. Comparing them is the whole point of the page.
if TIMING_CSV.exists():
with open(TIMING_CSV) as f:
legacy = list(csv.DictReader(f))
for stage, color, marker in [
("sequential", "tab:gray", "o"),
("threads", "tab:blue", "s"),
("processes", "tab:orange", "D"),
]:
xs = [int(r["points"]) for r in legacy if r["stage"] == stage]
ys = [float(r["seconds"]) for r in legacy if r["stage"] == stage]
if xs:
ax_compare.plot(
xs,
ys,
marker=marker,
color=color,
linestyle="--",
alpha=0.55,
label=f"9.3 {stage}",
)
for device_name, color, marker in [
("cpu", "tab:red", "o"),
("mps", "tab:green", "s"),
("cuda", "tab:purple", "D"),
]:
pairs = sorted(
(int(r["points"]), float(r["seconds"]))
for r in rows
if r["stage"] == "total" and r["device"] == device_name
)
if pairs:
ax_compare.plot(
[p for p, _ in pairs],
[s for _, s in pairs],
marker=marker,
color=color,
label=f"torch {device_name}",
)
ax_compare.set_xscale("log")
ax_compare.set_yscale("log")
ax_compare.set_xlabel("points (= correlations)")
ax_compare.set_ylabel("seconds")
ax_compare.set_title("Tracking cost: batched torch vs. 9.3's executors")
ax_compare.legend(fontsize=7)
# Right: where the time goes. hdic found extraction dominating its
# own correlation five to one; this panel is what makes that visible
# rather than hidden inside one total.
for stage, color, marker in [
("upload", "tab:olive", "v"),
("extract", "tab:brown", "o"),
("correlate", "tab:cyan", "s"),
("refine", "tab:pink", "^"),
]:
for device_name, style in (("cpu", "--"), ("mps", "-")):
pairs = sorted(
(int(r["points"]), float(r["seconds"]))
for r in rows
if r["stage"] == stage and r["device"] == device_name
)
if pairs:
ax_split.plot(
[p for p, _ in pairs],
[s for _, s in pairs],
marker=marker,
color=color,
linestyle=style,
label=f"{device_name} {stage}",
)
ax_split.set_xscale("log")
ax_split.set_yscale("log")
ax_split.set_xlabel("points (= correlations)")
ax_split.set_ylabel("seconds")
ax_split.set_title("Where the time goes (solid mps, dashed cpu)")
ax_split.legend(fontsize=7, ncol=2)
stops = [
f"{r['device']} @{r['width']}px: {r['stage'].split('_', 1)[-1]}"
for r in rows
if r["stage"].startswith(("STOPPED_", "FAILED_", "HARNESS_"))
]
if stops:
figure.suptitle("Ladder stopped: " + "; ".join(stops), fontsize=9, wrap=True)
figure.savefig(PNG_PATH, dpi=300)
plt.close(figure)
print(f"Wrote {PNG_PATH}")
if __name__ == "__main__":
if len(sys.argv) == 4 and sys.argv[1] == "--worker":
size_run(width=int(sys.argv[2]), device_name=sys.argv[3])
elif len(sys.argv) == 2 and sys.argv[1] == "--check":
checks_run()
else:
ladder_run()
summary_plot()
Discontinuities
Every correlation criterion since Correlation Criteria, and every worked example through Parallelism with PyTorch, depends on one tacit assumption: the true displacement field is smooth. A kernel window moves as a rigid or gently stretching patch. The search for its match assumes one answer exists.
Real specimens may not always have a continuous displacement field. A crack, a slip band, or a material interface can produce a genuine jump in displacement instead of a continuous displacement. Image Transformation already built exactly that jump:
| Crack Dislocation | Image |
|---|---|
| Original | |
| offset=4 pixels | |
A vertical crack splits the image at its vertical midline. The left half shifts down 4 pixels. The right half shifts up 4 pixels. Standard DIC can't represent that jump.
This chapter seeks to identify characteristics of the correlation map in the presence of a discontinuous displacement field. Specifically, what does a correlation surface look like when a kernel window straddles a real discontinuity instead of sitting cleanly on one side of it?
Synthetic Dislocation answers that with a known, exact ground truth: the same 4-pixel offset above, now carrying a speckle pattern a correlation can actually track. Experimental Dislocation then repeats the same straddling window on a real experimental crack image pair. There the ground truth isn't known in advance, so it checks whether the same signature shows up outside a synthetic setup.
Neither section proposes a discontinuity-aware correlation algorithm on its own. Discontinuity Localization addresses that challenge.
Synthetic Dislocation
Discontinuities already built the plain-photo version of this jump. Here we have added a speckle pattern, so the correlation has something to track:
import dictk
from dictk.image import combine, crack_dislocation, write

speckle = dictk.rosta(width=300, height=300, density=0.5)
photo = dictk.astronaut(width=300, height=300)
reference_image = combine(a=speckle, b=photo)
current_image = crack_dislocation(arr=reference_image, offset=4.0)

write(arr=reference_image, path="synthetic_dislocation_reference.png")
write(arr=current_image, path="synthetic_dislocation_current.png")
Saved: synthetic_dislocation_reference.png, synthetic_dislocation_current.png
| Synthetic Dislocation | Image |
|---|---|
| Original synthetic_dislocation_reference.png | 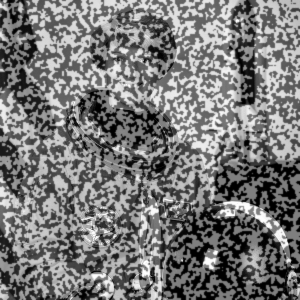 |
| offset=4 pixels synthetic_dislocation_current.png |  |
Both carry the same rosta speckle pattern — only the dislocation
differs. Discontinuities's plain-photo version
showed the geometry alone; this pair is what a correlation actually
sees.
A Window Straddling the Crack
Place a kernel window centered exactly on the crack: x = 150, the
image's own vertical midline, where the dislocation splits left from
right. A window there doesn't sit cleanly on one side. It contains both
true displacements at once: +4 pixels on its left half, -4 pixels on its
right. 0 pixels for all pixels in the current image.
Recall that
dictk's own y-axis points down the page, not up (see Multi-Point Motion for this same sign convention). So +4 here means the left half shifts down. -4 means the right half shifts up.
from dictk.plot import subimage_comparison_plot

kernel_margin = 25
kernel_origin = PixelCoordinate(x=p0.x - kernel_margin, y=p0.y - kernel_margin)
subimage_comparison_plot(
    image=reference_image,
    origin=kernel_origin,
    width=2 * kernel_margin,
    height=2 * kernel_margin,
    point=p0,
    point_color="orange",
    point_label="$P$",
    subimage_label="kernel",
    color="green",
    origin_label="$K$",
    source_origin_label="$O$",
    figsize=(6.4, 4.8),
    path="synthetic_dislocation_kernel.png",
)
Saved: synthetic_dislocation_kernel.png
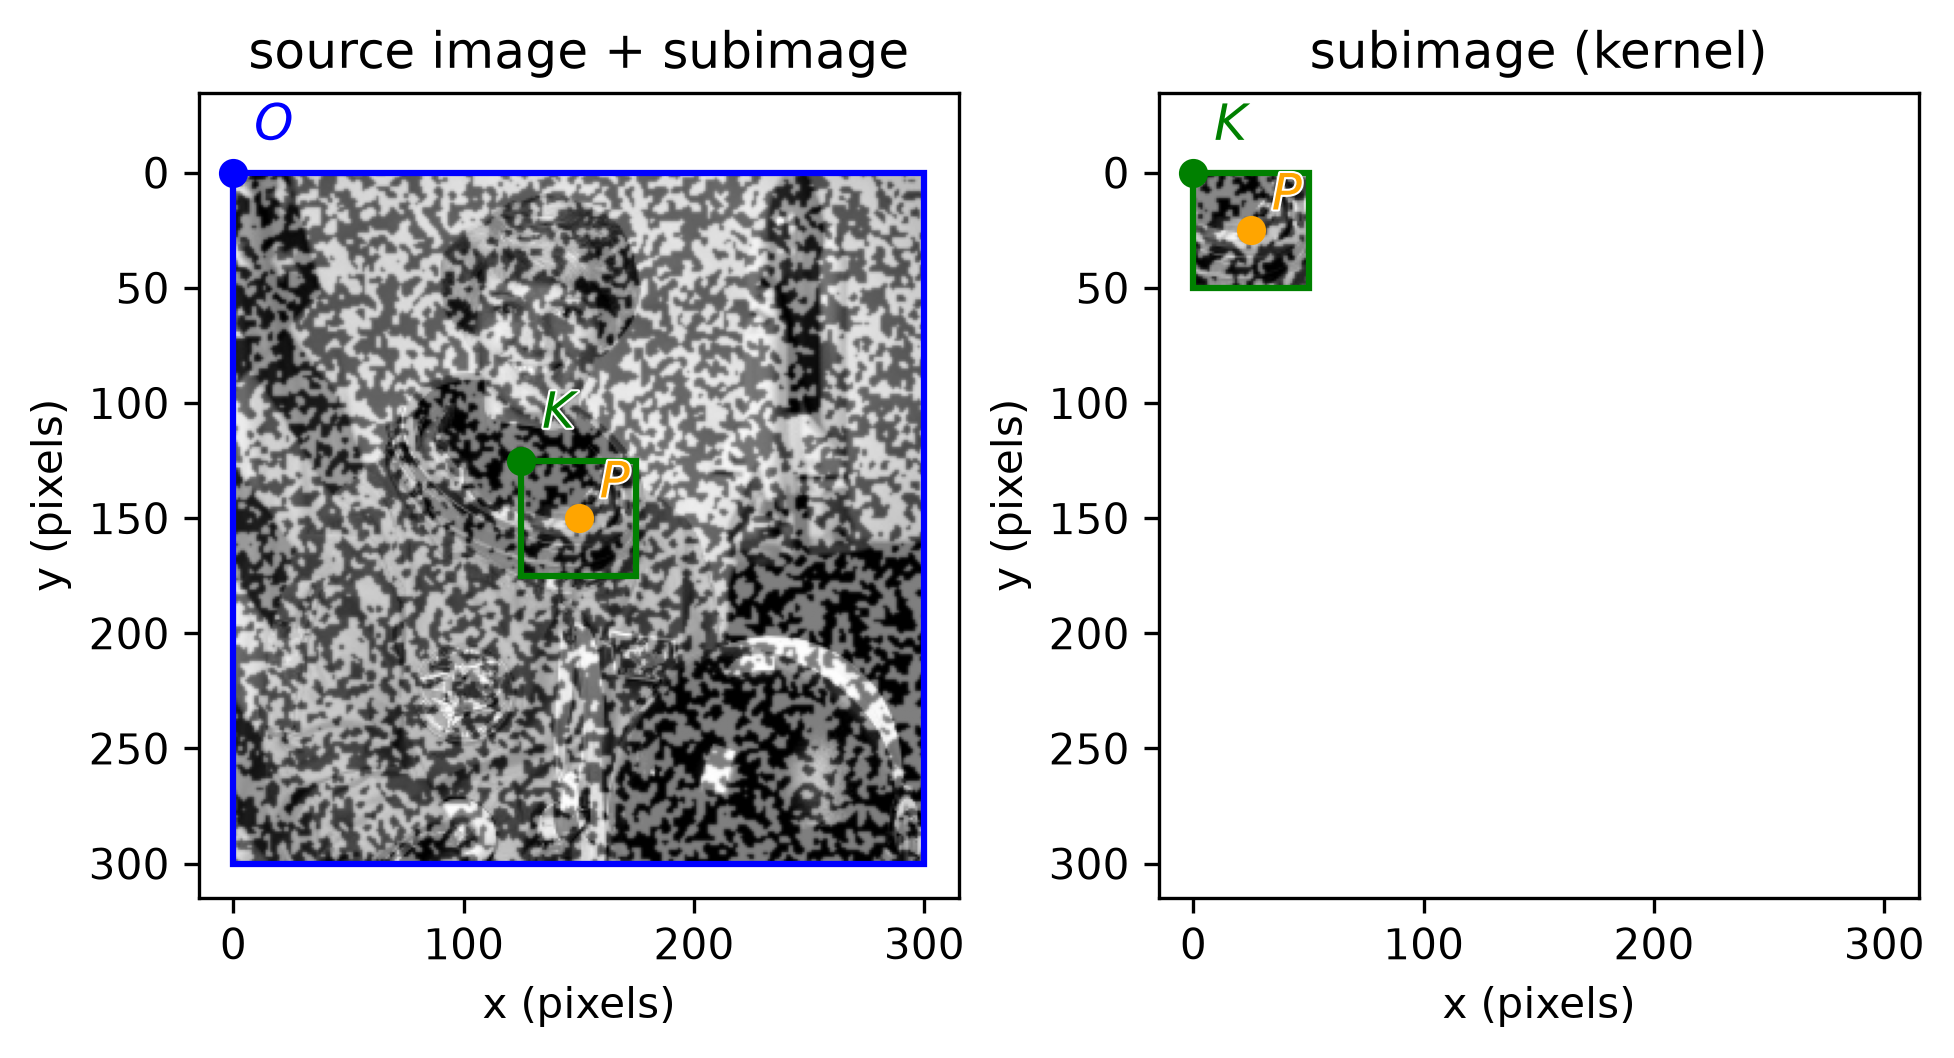
reference_image centered on the crack at , with origin pixels (green dot). Because the window straddles the crack instead of sitting on one side of it, it contains pixels from both displacements on the left and right halves of the current image. This follows the nomenclature and convention established in Cross Correlation (CC).from dictk.image import subimage, PixelCoordinate
from dictk.correlation import zncc
from dictk.plot import spatial_correlation_quadrant_plot, phase_correlation_quadrant_plot
p0 = PixelCoordinate(x=150, y=150)
kernel_margin, search_margin = 25, 45
kernel = subimage(
image=reference_image,
origin=PixelCoordinate(x=p0.x - kernel_margin, y=p0.y - kernel_margin),
width=2 * kernel_margin, height=2 * kernel_margin,
)
search = subimage(
image=current_image,
origin=PixelCoordinate(x=p0.x - search_margin, y=p0.y - search_margin),
width=2 * search_margin, height=2 * search_margin,
)
spatial_correlation_quadrant_plot(
kernel=kernel, search=search,
correlation_surface=zncc(kernel=kernel, search=search),
title="Zero-mean Normalized Cross-Correlation (ZNCC)",
path="synthetic_dislocation_zncc.png",
)
phase_correlation_quadrant_plot(
kernel=kernel, search=search,
title="Phase Correlation (FFT)",
path="synthetic_dislocation_phase.png",
)
Saved: synthetic_dislocation_reference.png, synthetic_dislocation_current.png, synthetic_dislocation_zncc.png, synthetic_dislocation_phase.png
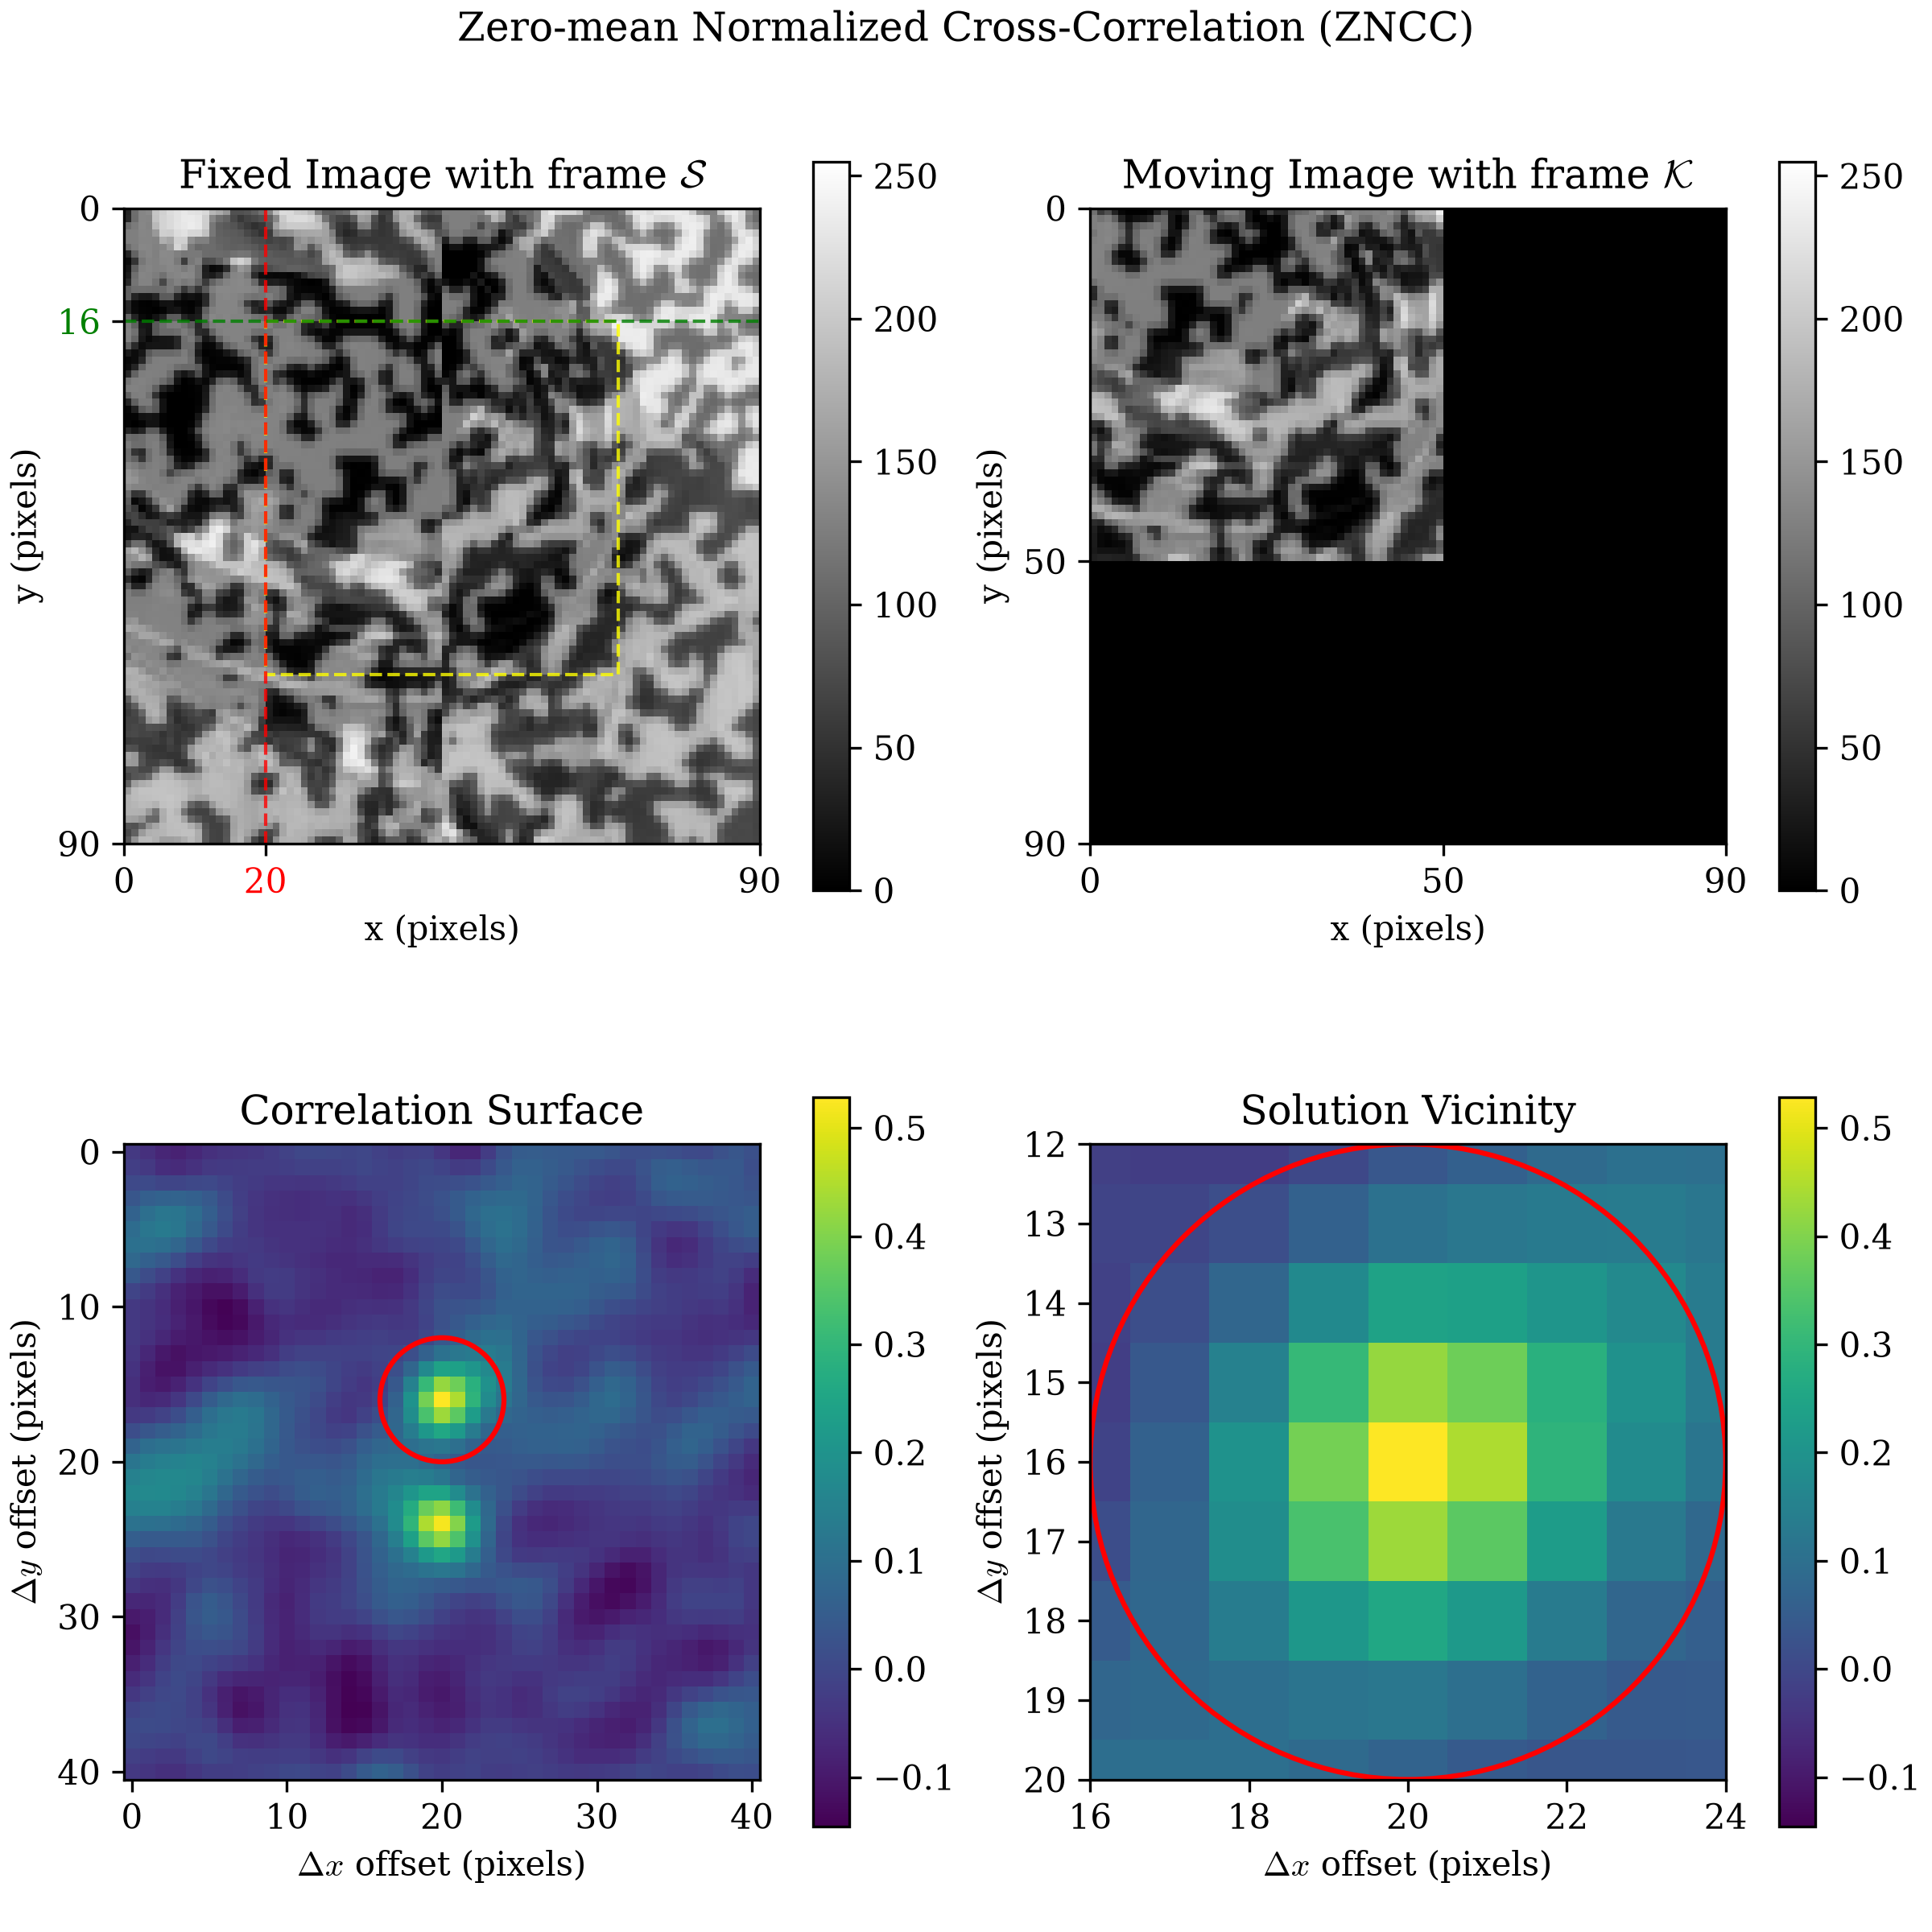
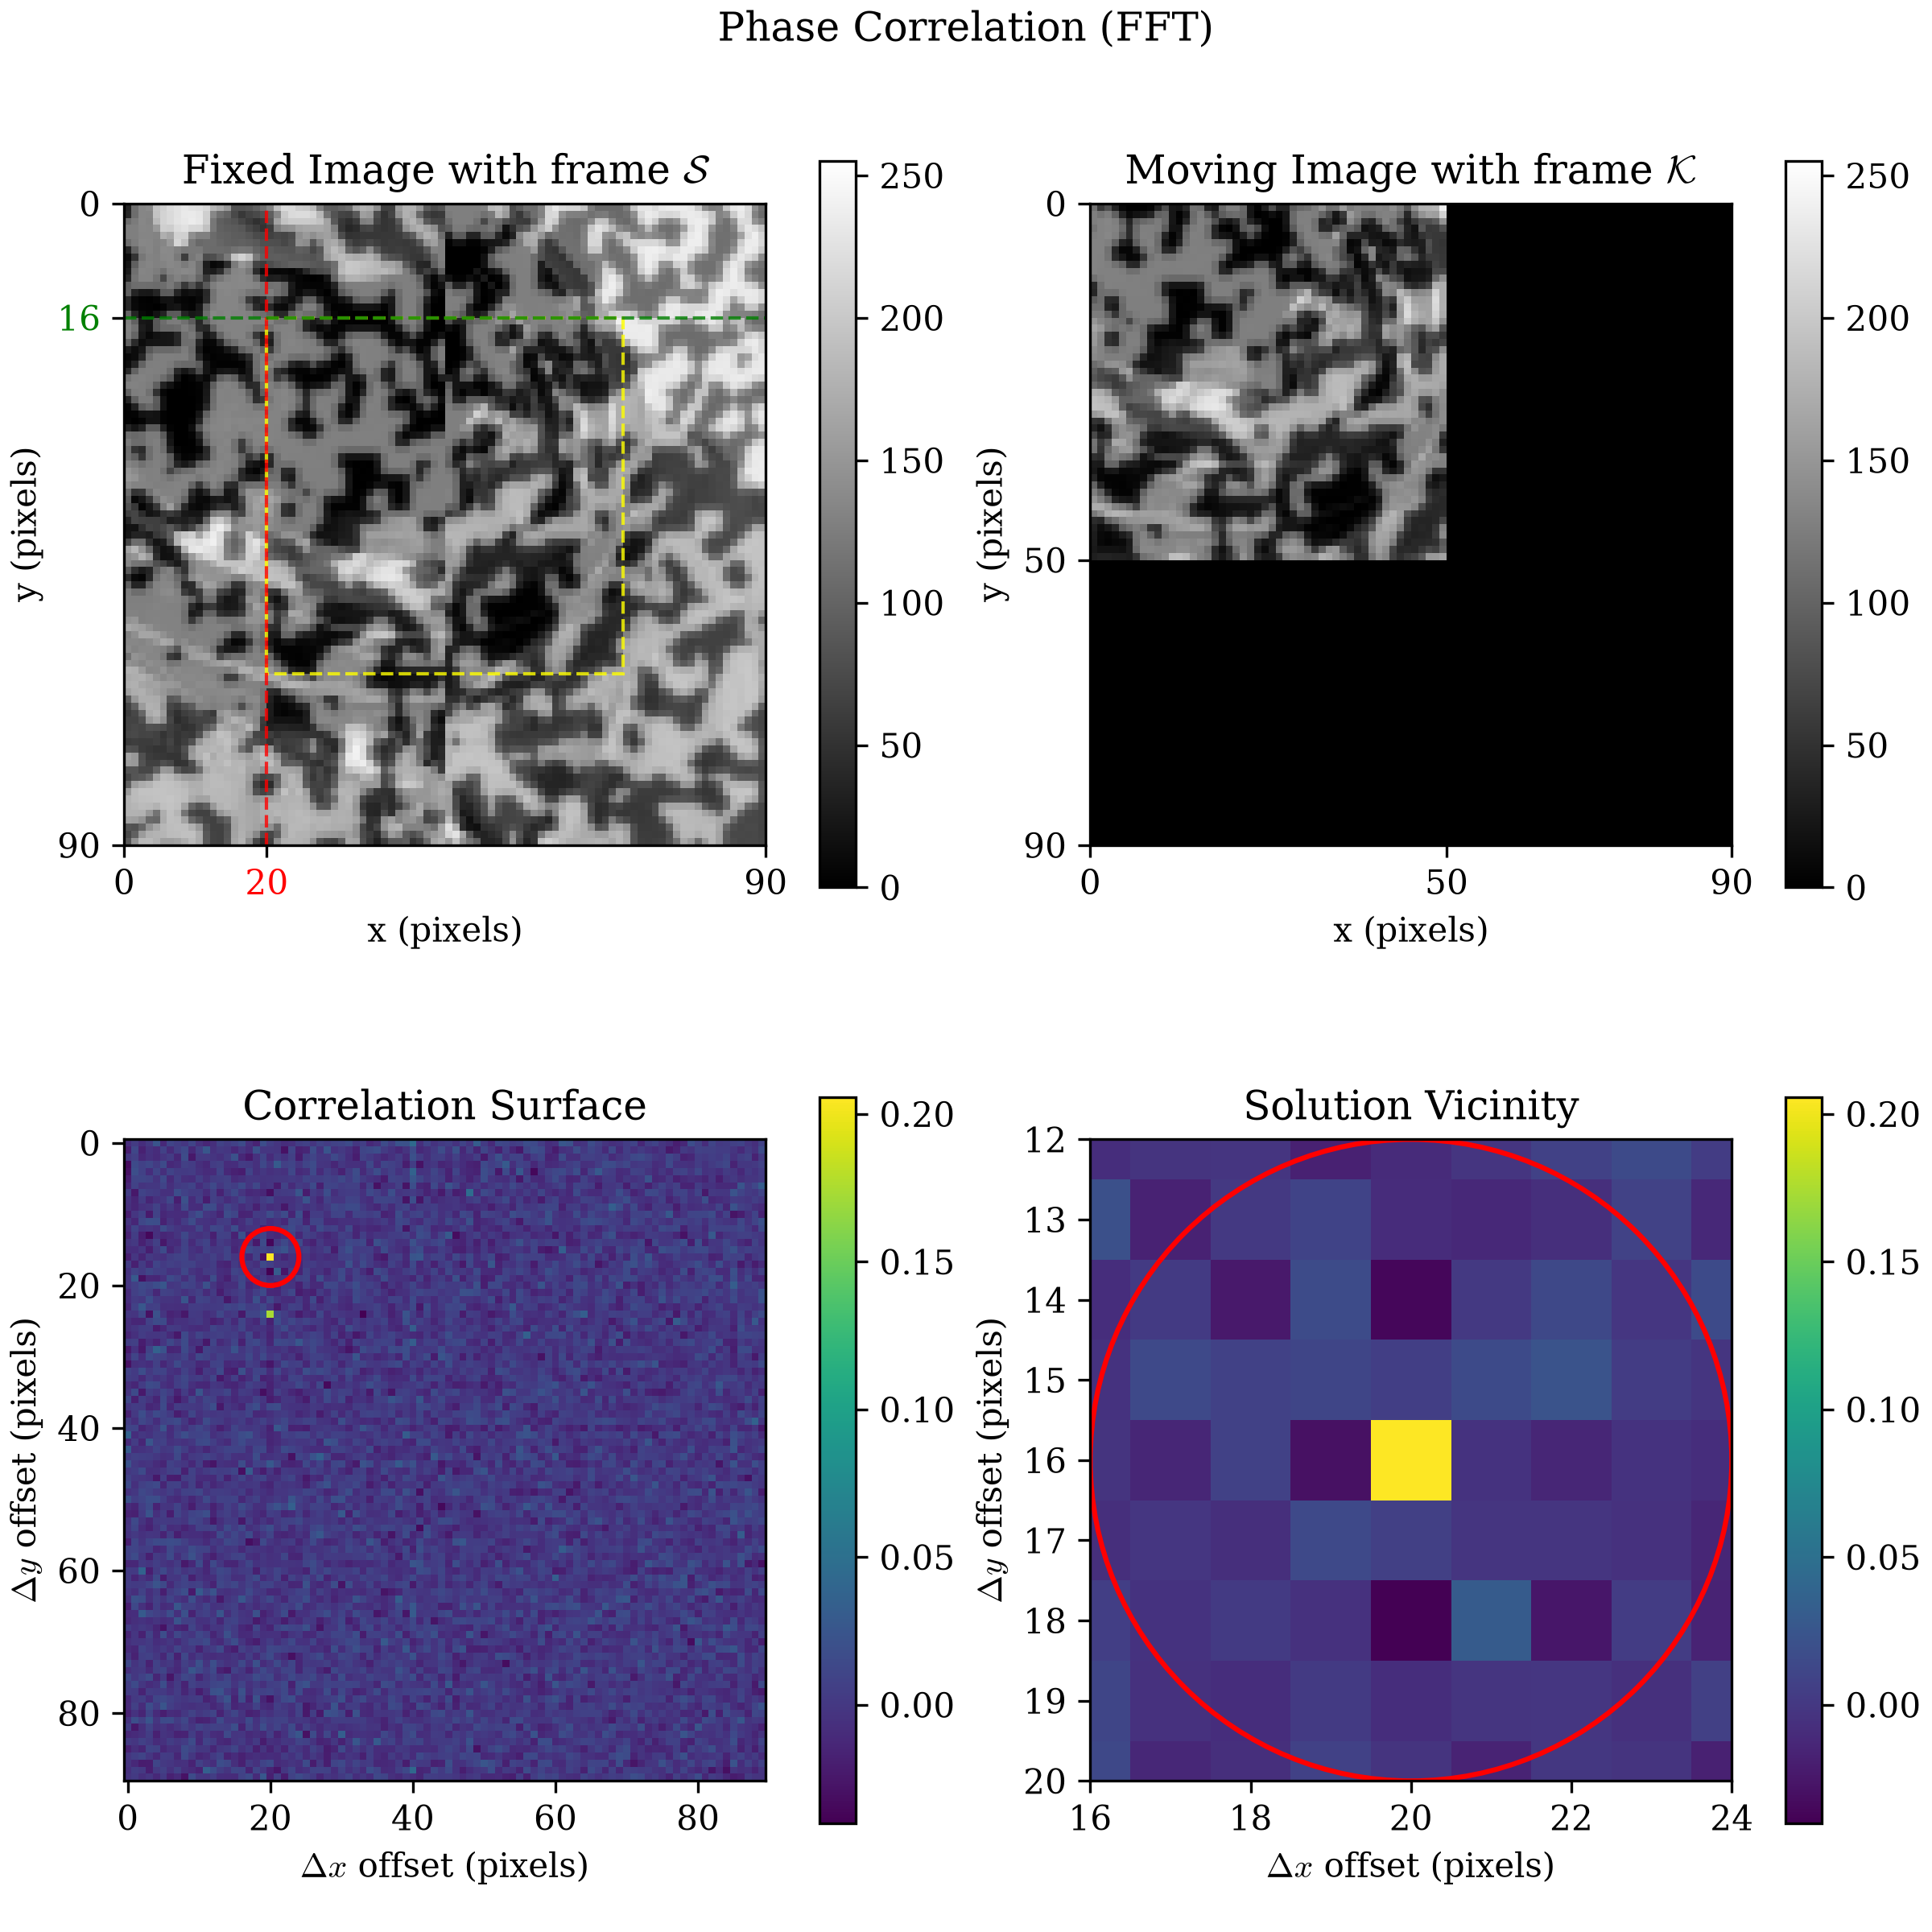
Two comparably-tall peaks appear, not one, because a single-peak
correlation answer can't represent two different true displacements at
once. Neither is a false match. Each is exactly right for its own half
of the window. The peaks sit at y=16 and y=24, straddling the
window's own zero-shift center (y=20) by exactly ∓4 pixels. That's the
same 4-pixel offset crack_dislocation applied. Their separation, 8
pixels, is exactly twice it. ZNCC (spatial) and phase correlation (FFT)
agree: both land on the same two peaks.
Does This Hold in General?
One offset proving the point isn't enough to trust it. Sweeping
crack_dislocation's offset from 1 to 32 pixels, and checking whether
each surface's two-peak separation still equals twice the offset:
| offset (px) | 2 x offset | ZNCC separation | ZNCC matches | Phase separation | Phase matches |
|---|---|---|---|---|---|
| 1 | 2 | n/a | False | 2 | True |
| 2 | 4 | 4 | True | 4 | True |
| 3 | 6 | 6 | True | 6 | True |
| 4 | 8 | 8 | True | 8 | True |
| 6 | 12 | 12 | True | 12 | True |
| 8 | 16 | 16 | True | 16 | True |
| 12 | 24 | 24 | True | 24 | True |
| 16 | 32 | 32 | True | 32 | True |
| 20 | 40 | 40 | True | 40 | True |
| 24 | 48 | 48 | True | 48 | True |
| 28 | 56 | 56 | True | 56 | True |
| 32 | 64 | 64 | True | 64 | True |
Saved: synthetic_dislocation_sweep.png
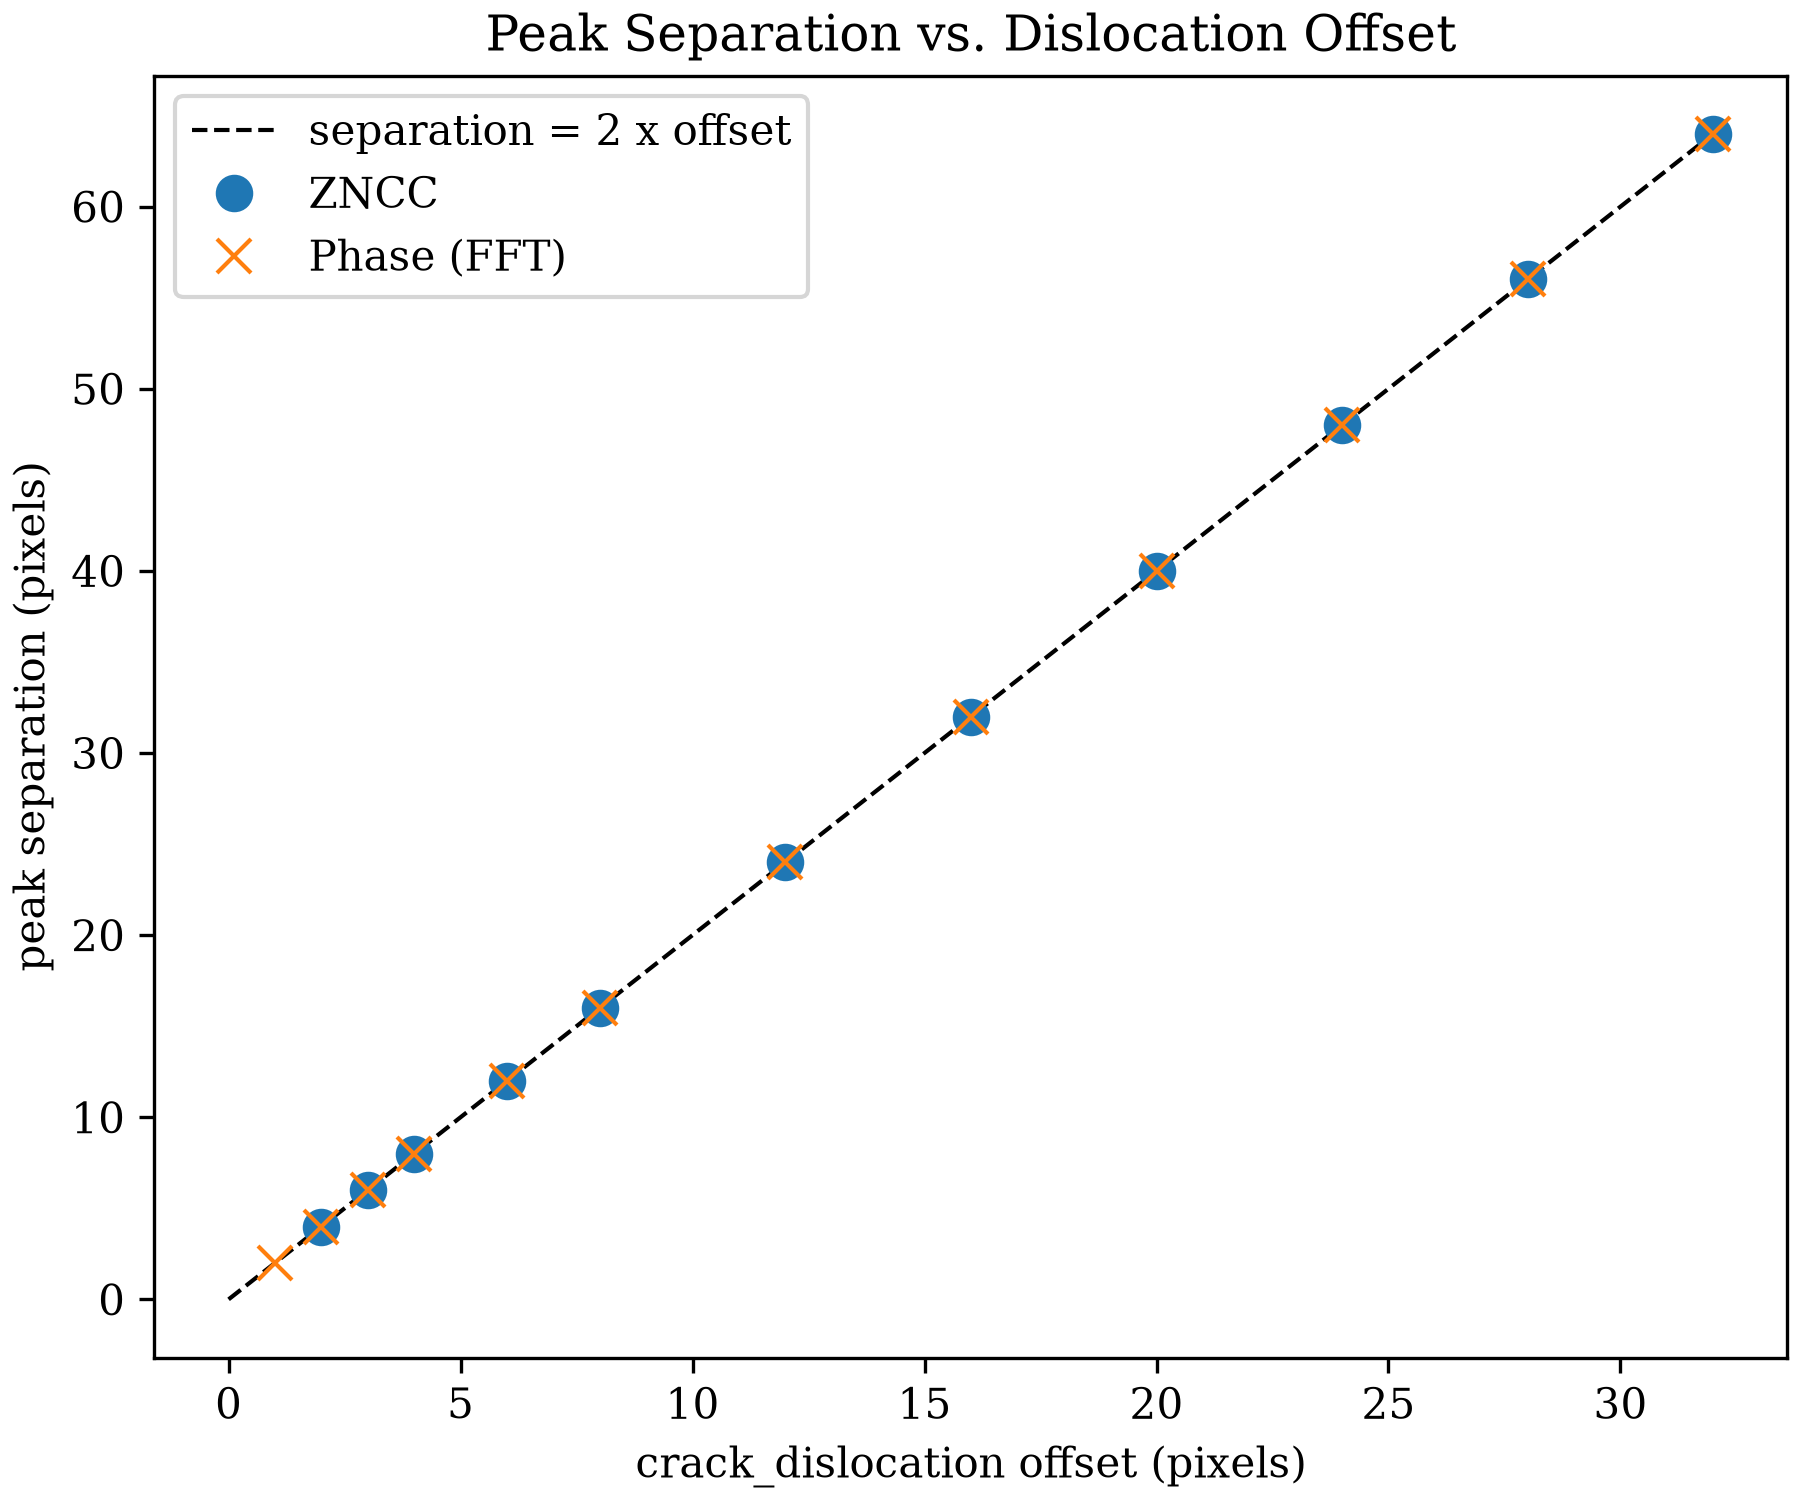
The encoding holds reliably across a 32x range of offsets, for both criteria. One exception sits at the low end: once the two true displacements are only a pixel apart, resolving them as two distinct peaks runs into the same integer-pixel resolution limit Subpixel Accuracy already covers for a single peak.
Moving the Window Off the Crack
Every result so far centers the window exactly on the crack, at
x = 150. What happens as that center slides away from it?
kernel_margin=25 sets a hard geometric boundary. Once the window's
center sits more than 25 pixels from the crack, the window no longer
touches both halves at all: it's x <= 125 for a window entirely in
the left half, x >= 175 for one entirely in the right. Sweeping
x from 100 to 200 and reading the ZNCC surface at both candidate
peak locations, Δy=+4 (the left half's own shift) and Δy=-4 (the
right half's own shift), at each step:
| kernel center x | left-half peak (dy=+4) | right-half peak (dy=-4) |
|---|---|---|
| 100 | 1.000 | 0.048 |
| 110 | 1.000 | 0.122 |
| 120 | 1.000 | 0.065 |
| 130 | 0.901 | 0.164 |
| 140 | 0.725 | 0.360 |
| 150 | 0.519 | 0.528 |
| 160 | 0.433 | 0.722 |
| 170 | 0.311 | 0.939 |
| 180 | 0.304 | 1.000 |
| 190 | 0.221 | 1.000 |
| 200 | 0.233 | 1.000 |
Saved: synthetic_dislocation_x_sweep.png
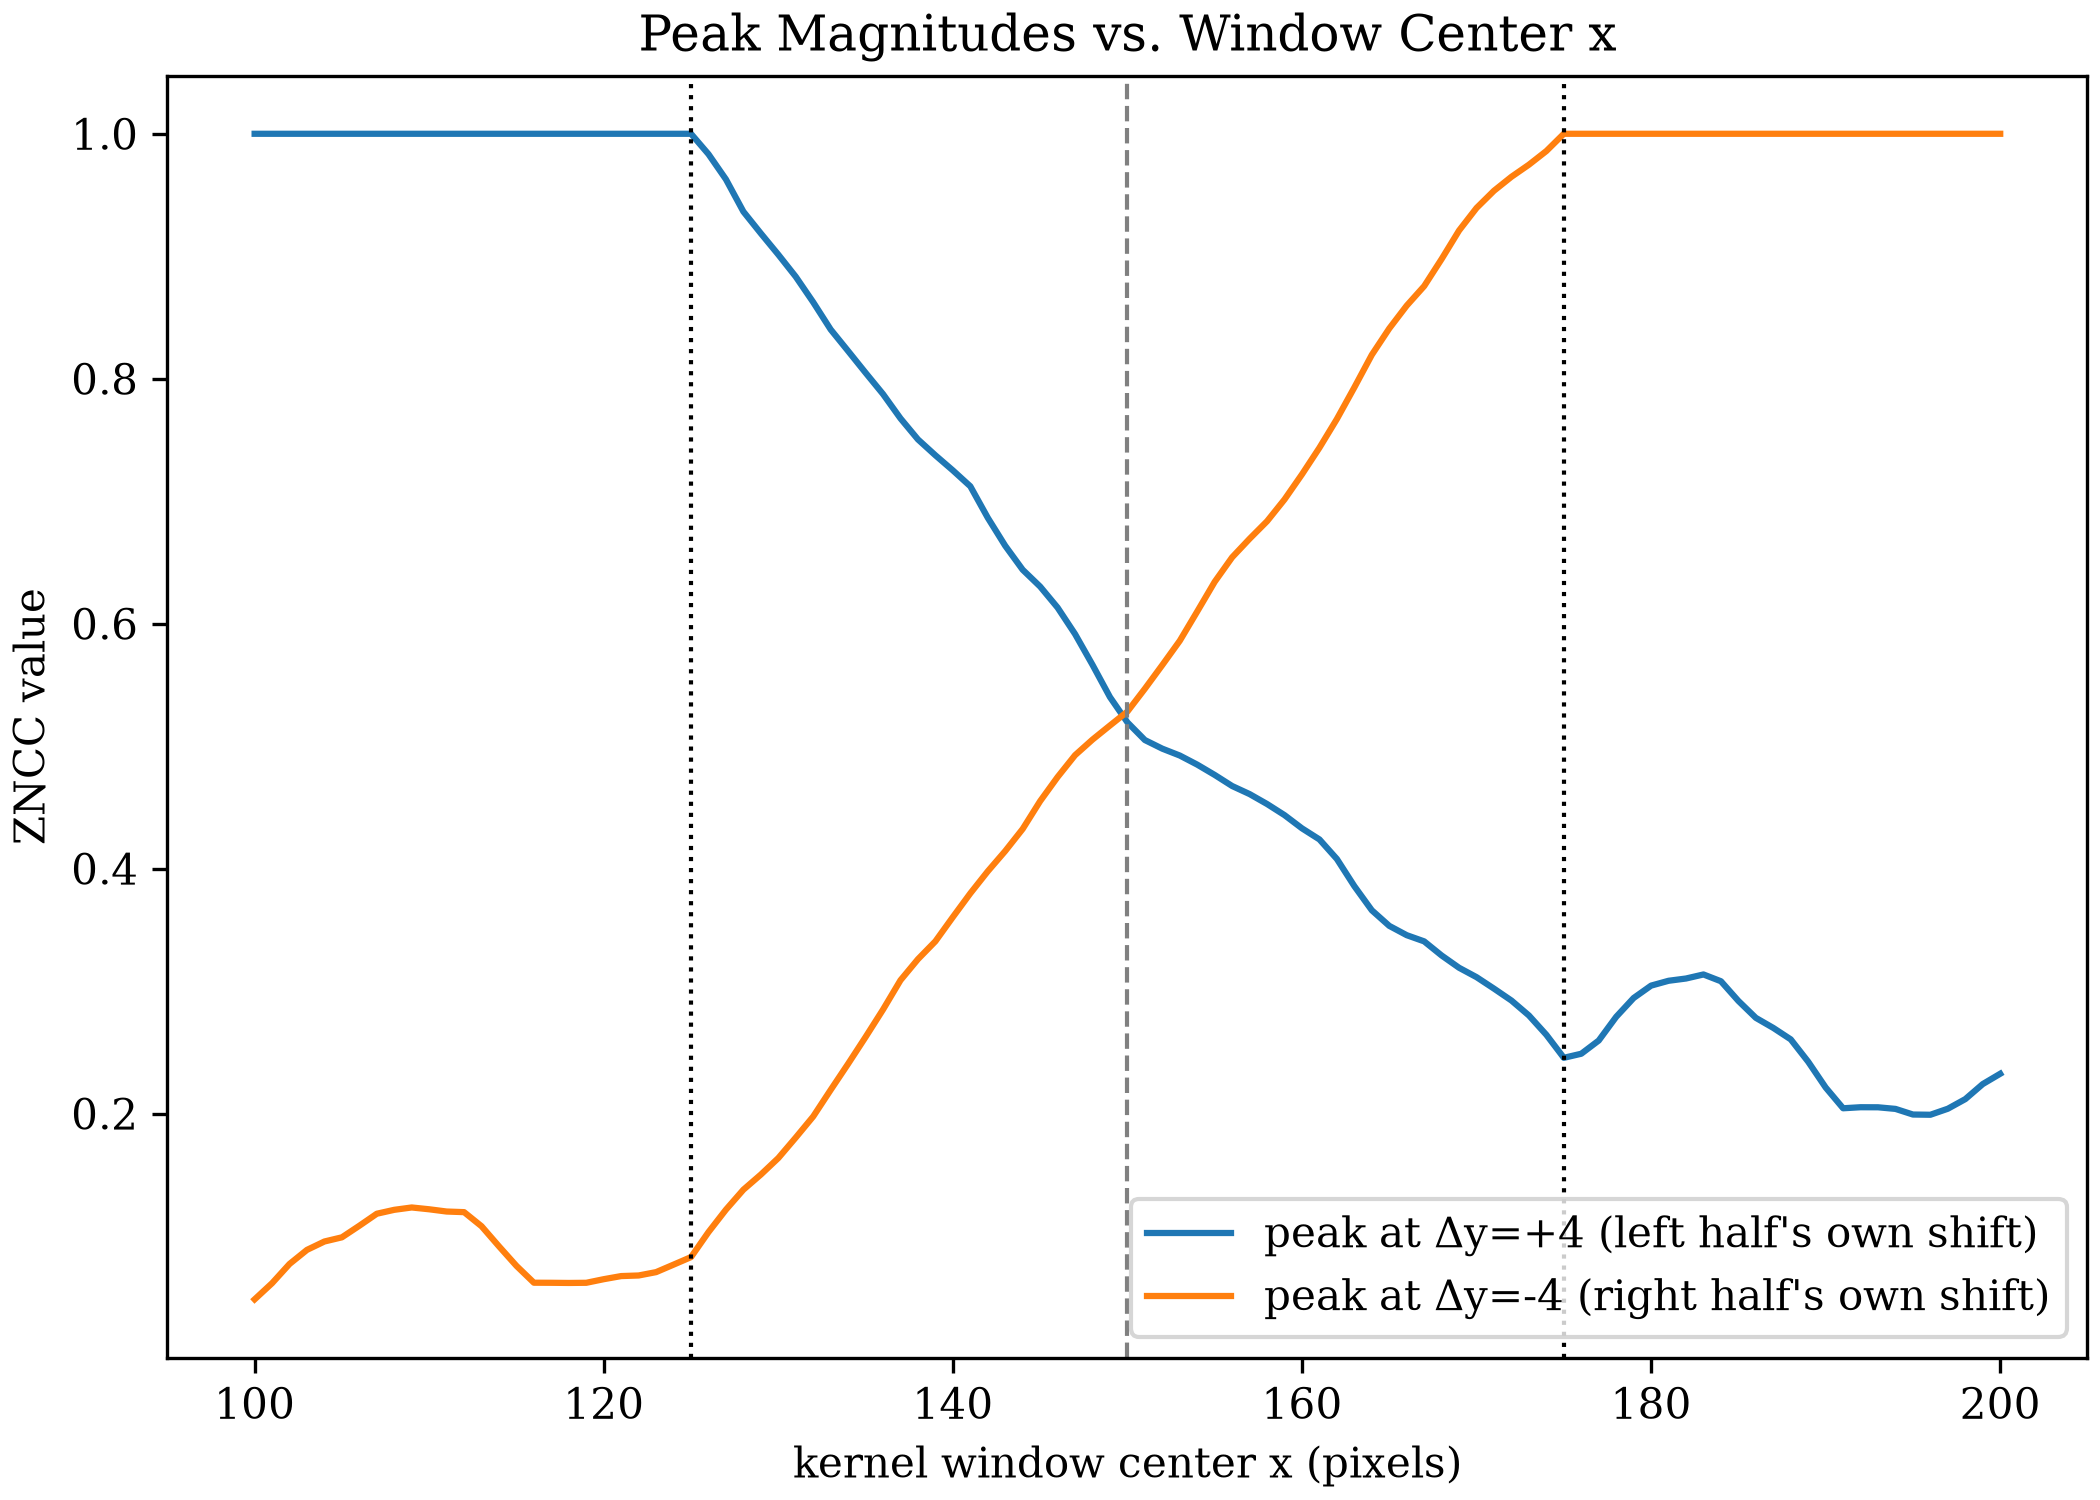
The line plot only reads two fixed points on the surface. The surface
itself tells the same story directly: the Correlation Surface panel at
five kernel window center positions, x = 130, 140, 150, 160, 170,
sharing one colorbar:
Saved: synthetic_dislocation_x_sweep_panels.png
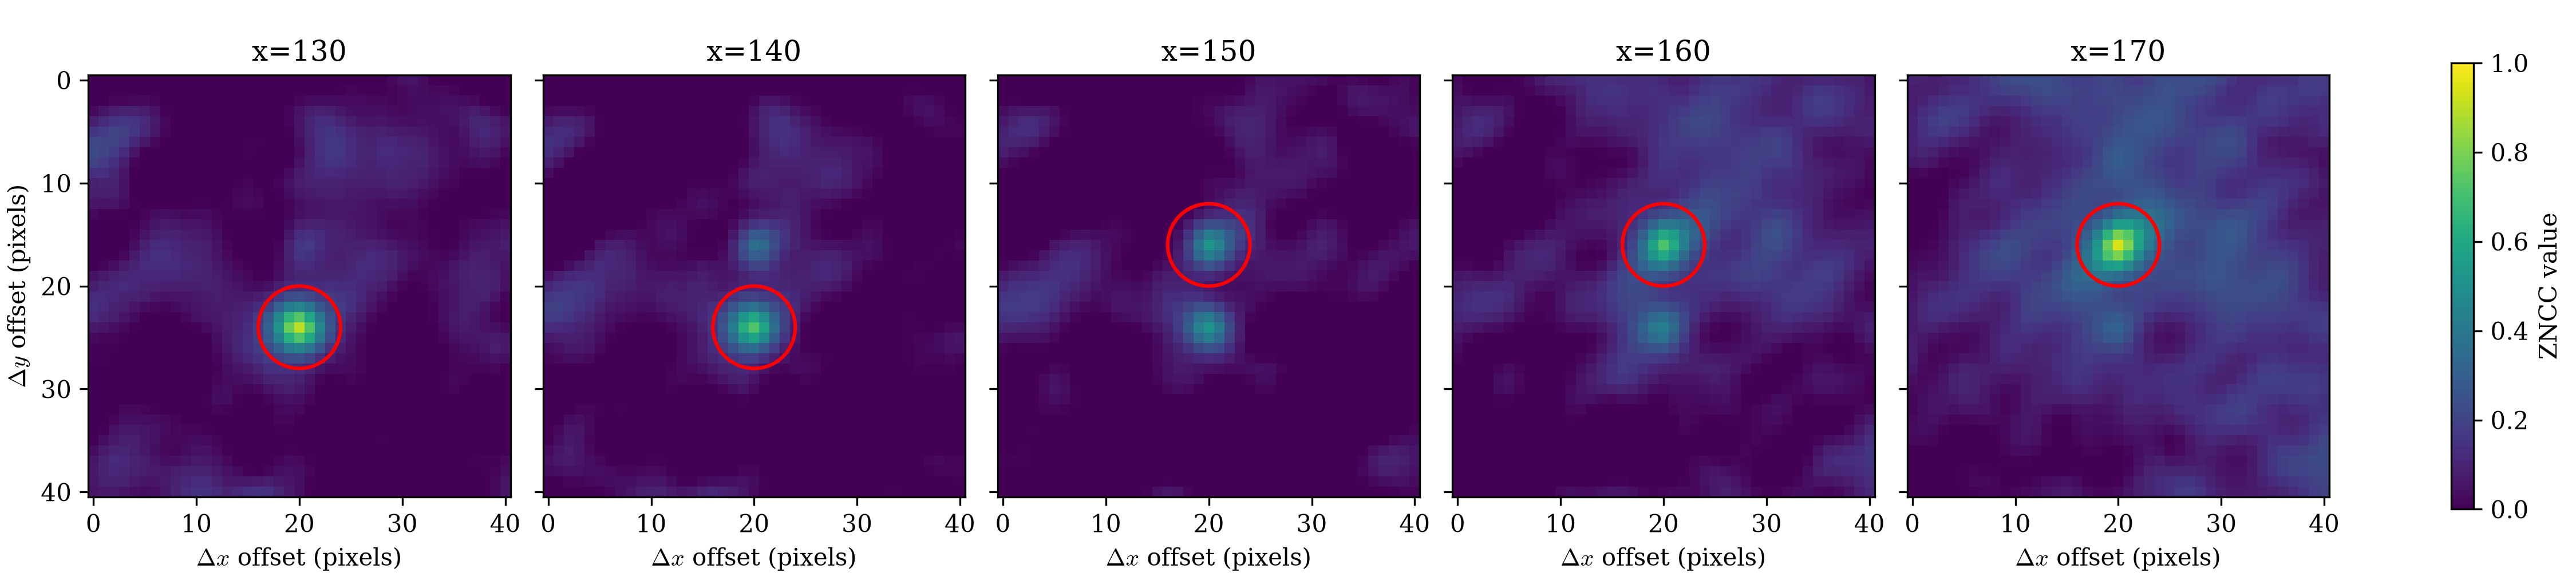
ZNCC hits exactly 1.0, not just a high value, wherever the window sits fully inside one half. That's not a coincidence: a window entirely inside one half sees a pure integer-pixel rigid shift of identical content. There's no interpolation error and nothing else to explain away, so ZNCC reaches its exact theoretical maximum.
The two sides aren't quite mirror images once the window fully clears the crack. Below x=125 the vanishing peak (Δy=-4) fades to 0.05-0.16. Above x=175 the vanishing peak (Δy=+4) settles into a higher, fluctuating 0.2-0.3 band instead, with a small bump near x=183. That difference comes from the underlying speckle and photo content on each side, not from the crack itself.
Straddling the crack is what makes two comparable peaks possible. Move the window fully clear of it, in either direction, and only one peak remains: a single, perfect match.
Displacement Field
Every result so far reads one fixed point, or one line through the
image (y = 150, sweeping x). A grid of tracked points turns that
into a field: the same displacement each single measurement already
found, but everywhere at once, not just where a human chose to look.
SEARCH_MARGIN = 45 sets how far each point's own search window
reaches from its own center. Starting the grid's own origin exactly
there keeps every point's search window fully inside the image, with no
edge effect competing with the crack for attention:
from dictk.grid import generate, locate_subpixel

points = generate(
    origin=PixelCoordinate(x=SEARCH_MARGIN, y=SEARCH_MARGIN),
    count_x=43,
    count_y=43,
    spacing_x=5,
    spacing_y=5,
)
found = locate_subpixel(
    reference_image=reference_image,
    current_image=current_image,
    reference_points=points,
    kernel_margin_width=KERNEL_MARGIN,
    kernel_margin_height=KERNEL_MARGIN,
    search_margin_width=SEARCH_MARGIN,
    search_margin_height=SEARCH_MARGIN,
    upsample_factor=100,
)
dx = [f.x - p.x for f, p in zip(found, points)]
dy = [f.y - p.y for f, p in zip(found, points)]
The dy field, painted over current_image:
from dictk.plot import point_displacement_plot

point_displacement_plot(
    points=found,
    values=dy,
    label=r"Displacement, $\delta y$ (pixels)",
    image=current_image,
    dot_size=6,
    marker="s",
    cmap="coolwarm",
    path="synthetic_dislocation_displacement_field.png",
)
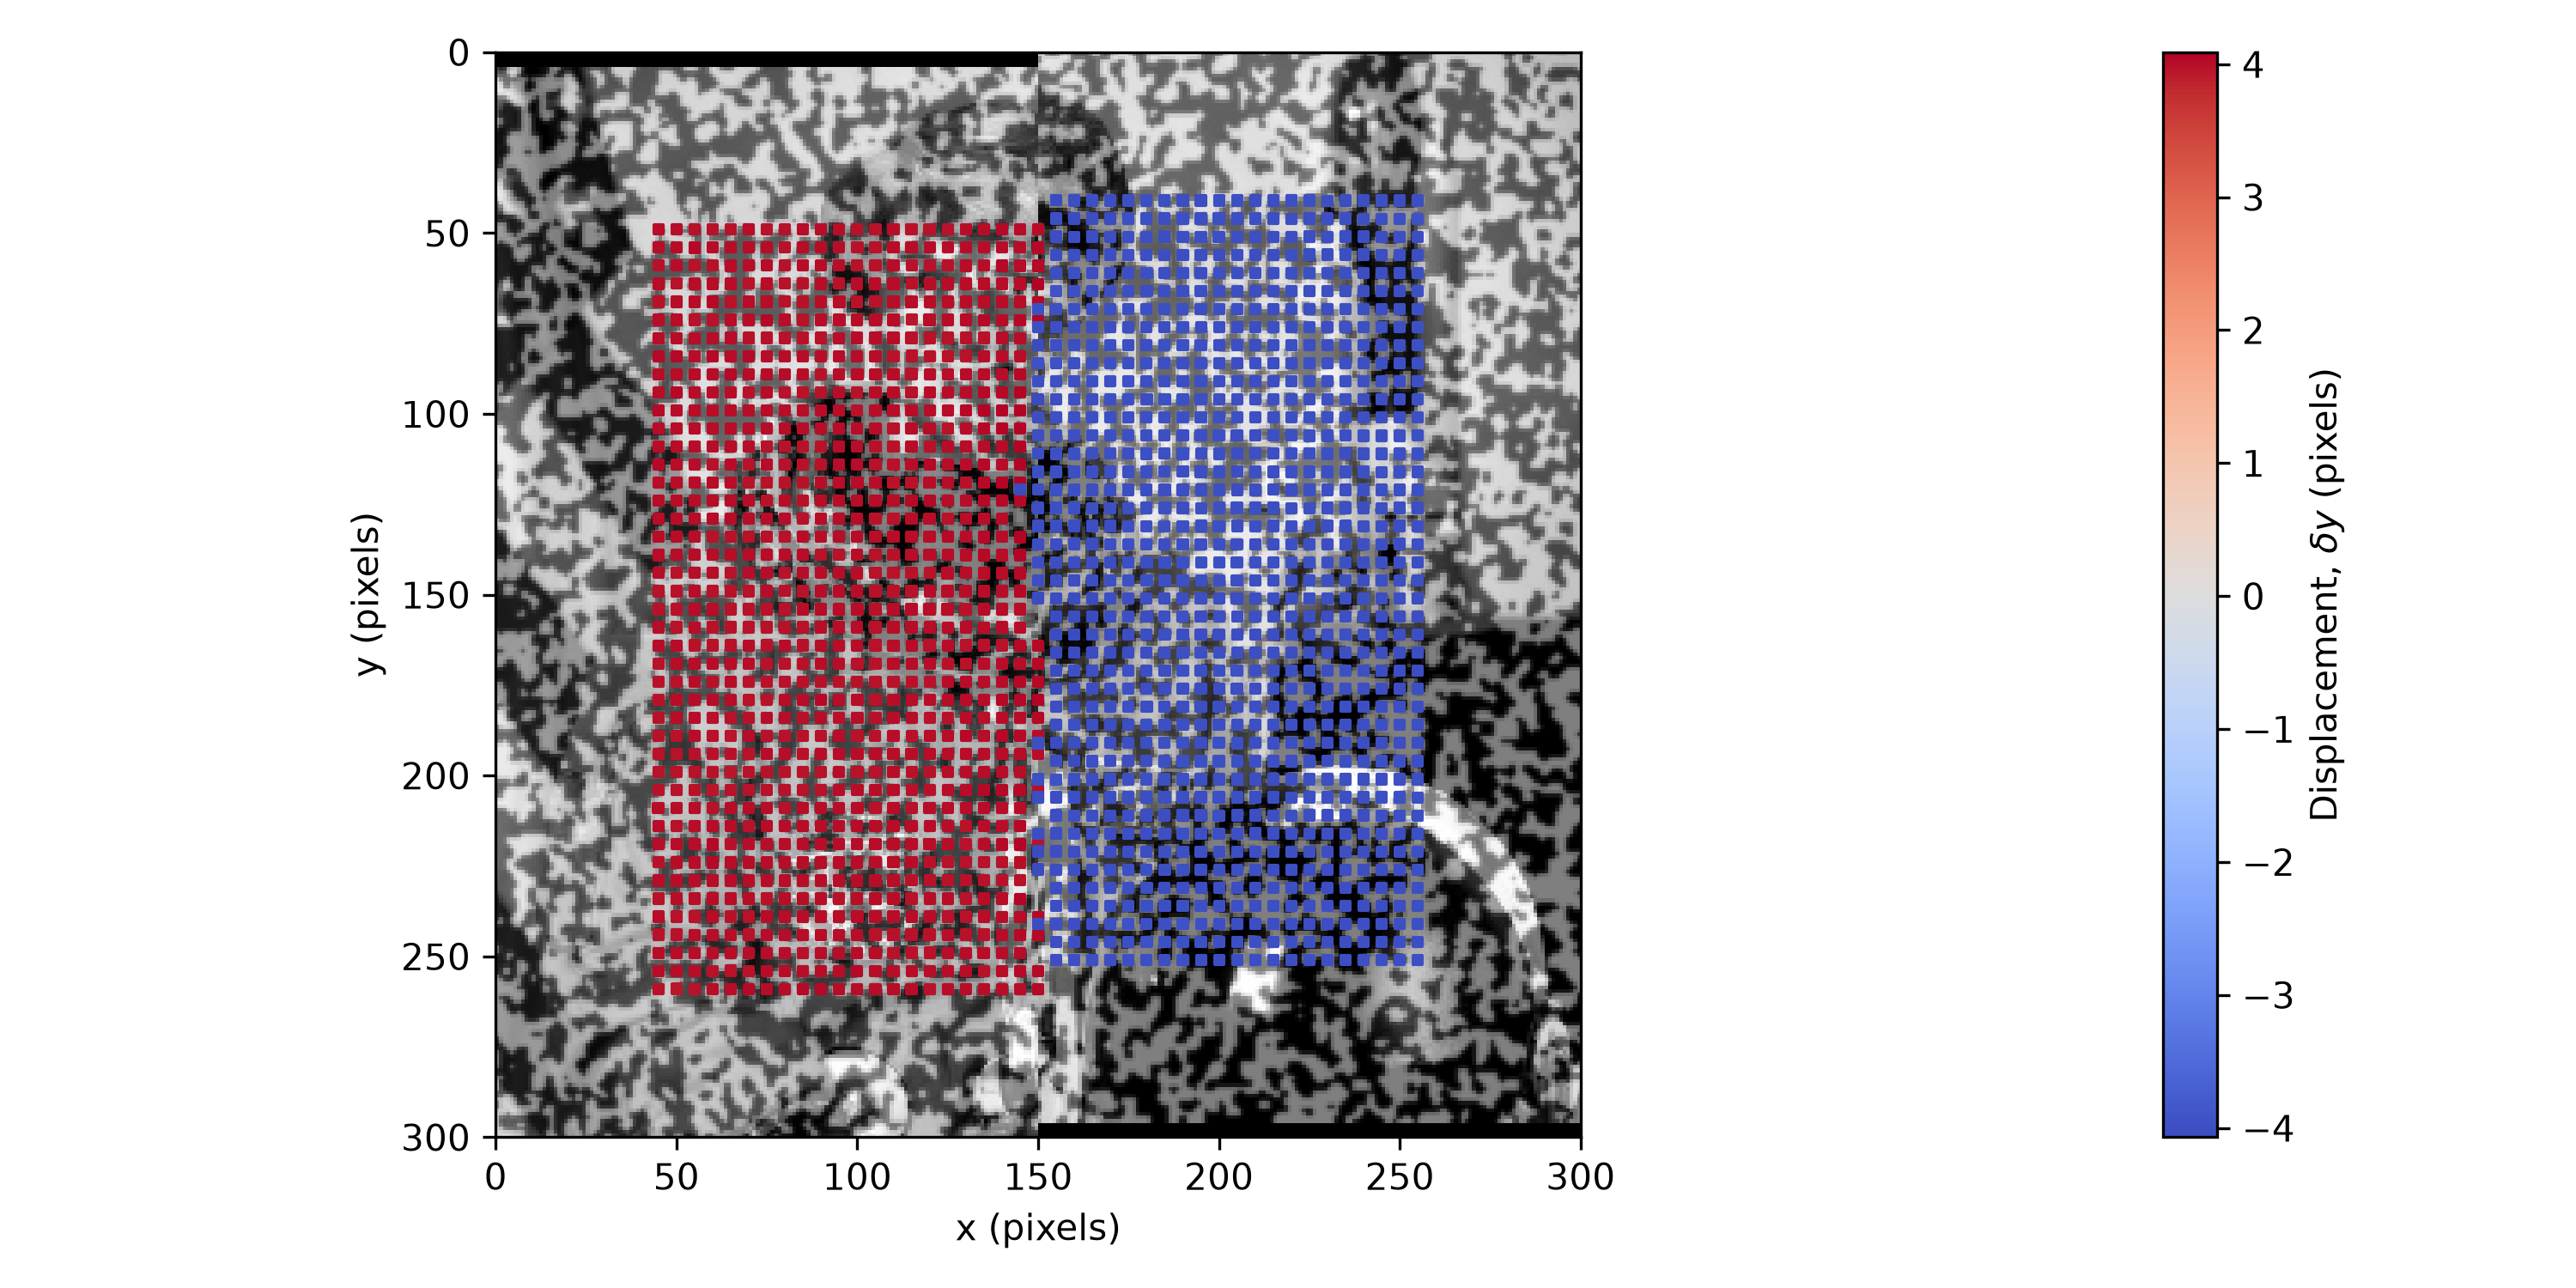
dy field over all 1849 tracked points. Not a gradient: two flat colors, solid (left) and solid (right), meeting at a boundary within one grid column (5 pixels) of the crack at , for every row.Zooming into that boundary shows small gaps: spots where the gray and black speckle image shows through, neither red nor blue. None of the 1849 points are missing -- every one of the 43 columns holds all 43 rows, and every point gets a color. The gaps come from how the points are drawn, not which ones are plotted.
dot_size=6 sizes each square marker at only about a quarter of its
own 5-pixel grid cell. Every marker sits well short of its neighbors,
on every side, everywhere in the field -- the same small gap separates
every red neighbor, every blue neighbor, and every point at the
boundary. That gap is easy to miss where it sits between two markers of
the same color: a patch of speckle between two red squares blends into
the surrounding red, and the eye skips past it, reading as texture
rather than as a hole. The identical-sized gap between a red marker and
a blue one is unmistakable, flanked by two different colors instead of
one. The gaps aren't concentrated at the crack. They're everywhere.
Only at the crack does the color change on either side make them
visible.
crack_dislocation only ever moves pixels vertically, so dx should
come back trivially close to zero at every one of these 1849 points --
worth checking directly, not just assuming it from the one point
already measured:
| quantity | value |
|---|---|
| points in group | 1849 |
| mean dx (px) | -0.0008 |
| max abs dx (px) | 0.0700 |
| quantity | value |
|---|---|
| points in group | 921 |
| mean dy (px) | 4.0038 |
| std dy (px) | 0.0173 |
| min dy (px) | 3.9500 |
| max dy (px) | 4.0900 |
| quantity | value |
|---|---|
| points in group | 928 |
| mean dy (px) | -4.0033 |
| std dy (px) | 0.0156 |
| min dy (px) | -4.0700 |
| max dy (px) | -3.9300 |
Saved: synthetic_dislocation_displacement_field.png, synthetic_dislocation_displacement_field_dx_histogram.png, synthetic_dislocation_displacement_field_dy_positive_histogram.png, synthetic_dislocation_displacement_field_dy_negative_histogram.png
Displacement dx
dx does stay trivially small: every one of the 1849 points comes back
within 0.07 pixels of zero, well under a tenth of a pixel, as the first
table above shows. The full distribution, not just its extremes:
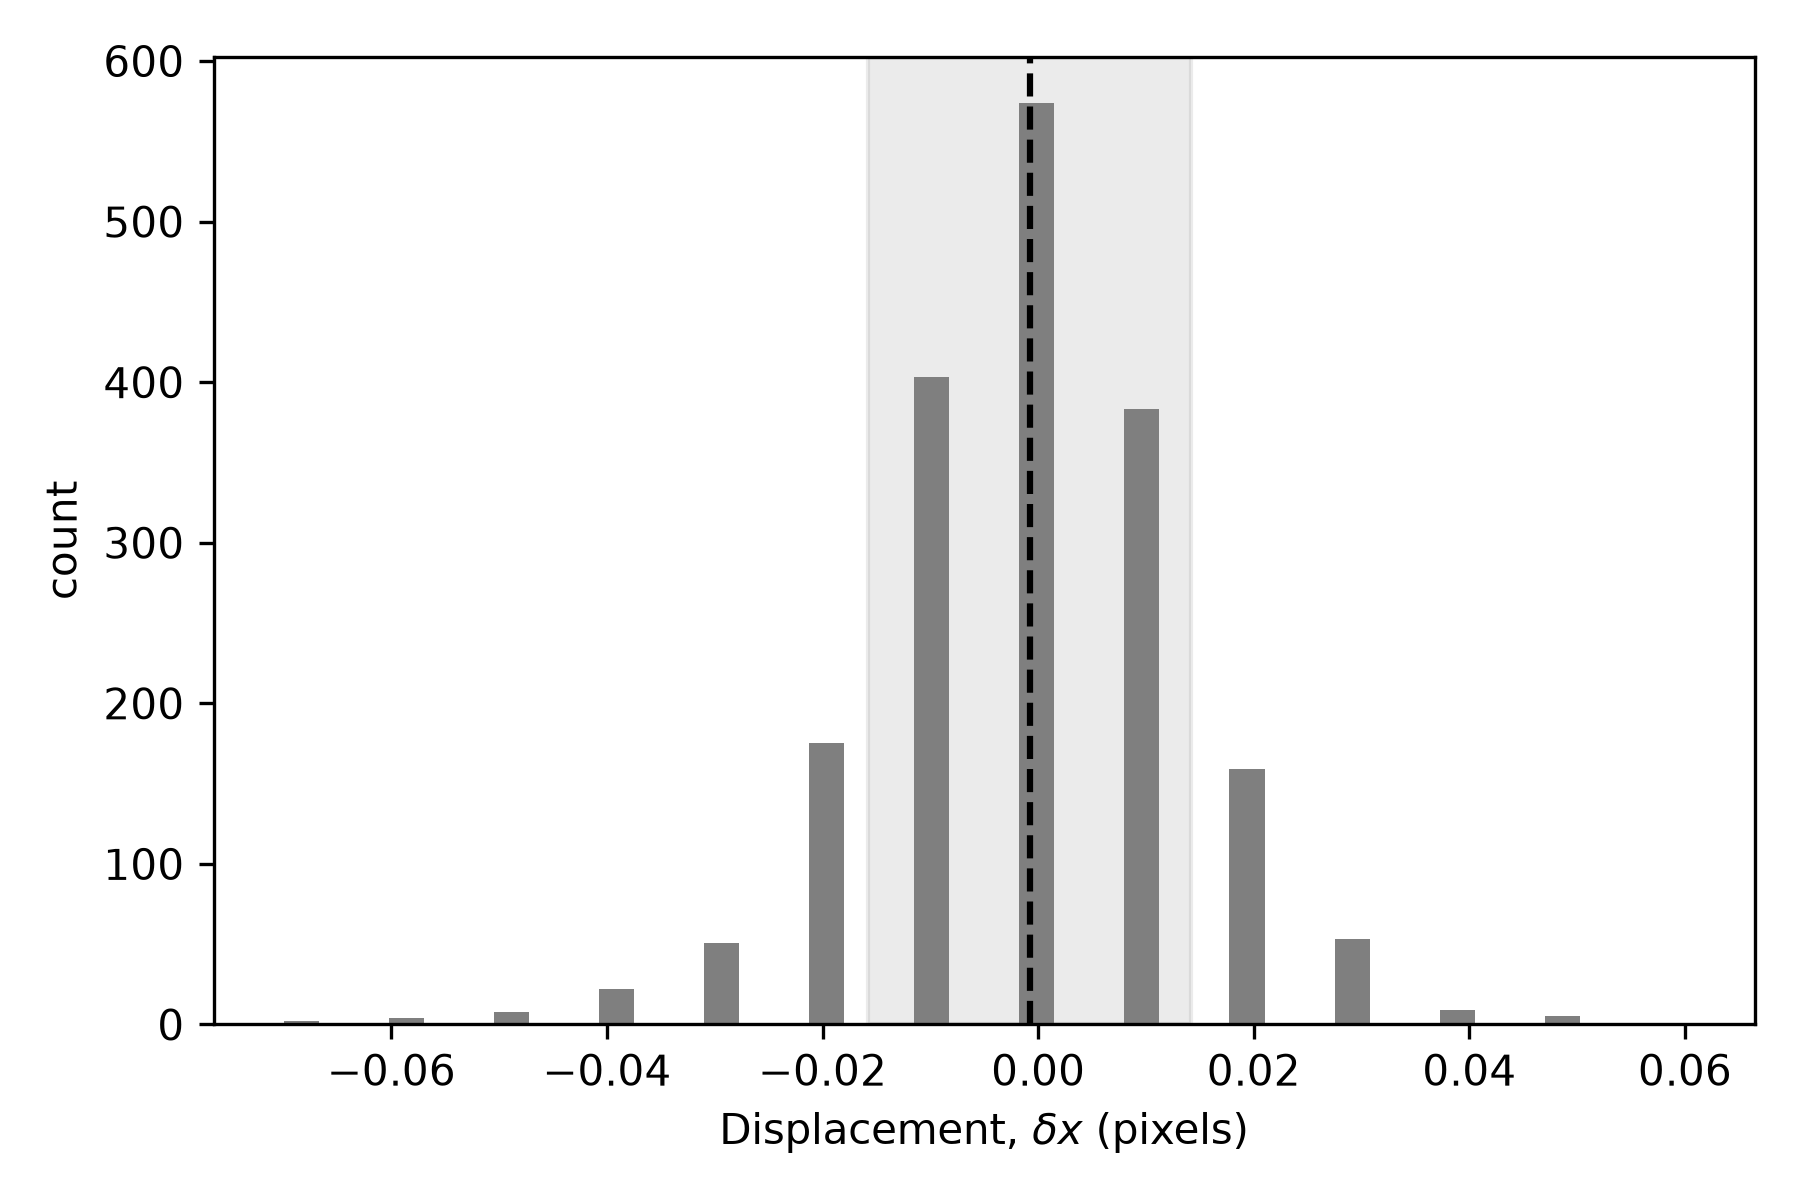
dx distribution across all 1849 tracked points: a single peak centered on zero, no second mode. The shaded band marks one std on either side of the mean; the dashed line marks the mean itself. The 0.01-pixel steps are upsample_factor=100's own subpixel quantization, the same effect High Point Density found for dy.Displacement dy
That boundary in the field figure above is sharper than "Moving the
Window Off the Crack" would suggest. Windows straddle the crack for
every point with 125 < x < 175 -- 387 of the 1849 points here -- yet
none of them return a value between the two true displacements. Each
straddling window's correlation surface does hold two comparable peaks,
exactly as the earlier single-window measurement found, but
locate_subpixel still returns one location: whichever peak is taller.
Which one wins depends on how much of that window's own area sits on
each side of the crack, and that tips over almost exactly at the crack
itself, not gradually across the full 50-pixel span a straddling window
could in principle blur together.
Splitting dy on its own sign, rather than by x position, gives the
same two groups directly: 921 points read a positive displacement, 928
read a negative one, and none read zero. The second and third tables
above cover each group on its own.
The +4 group:
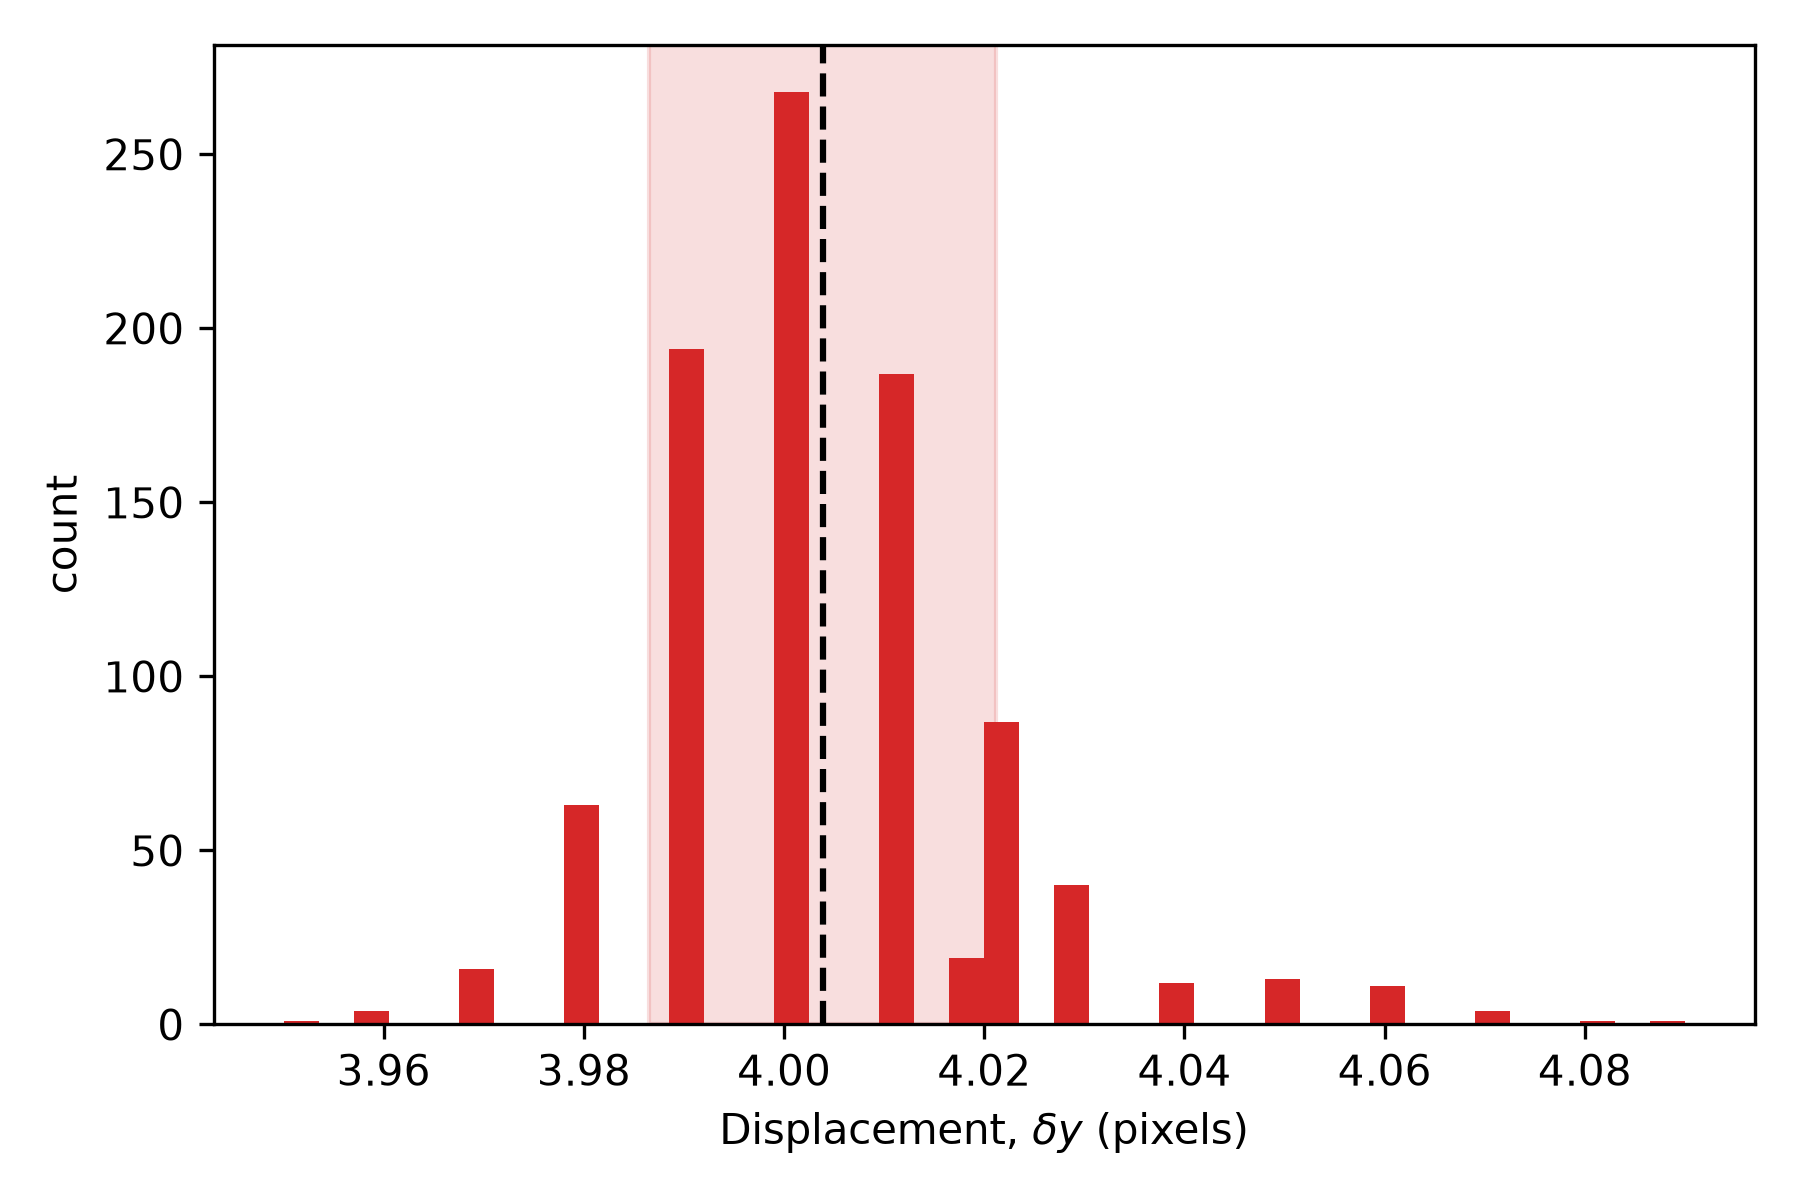
dy distribution for the 921 points in the +4 group: a single peak at 4.00 pixels, std 0.017 pixels -- the shaded band and dashed line mark that mean and its one-std spread directly.The -4 group:
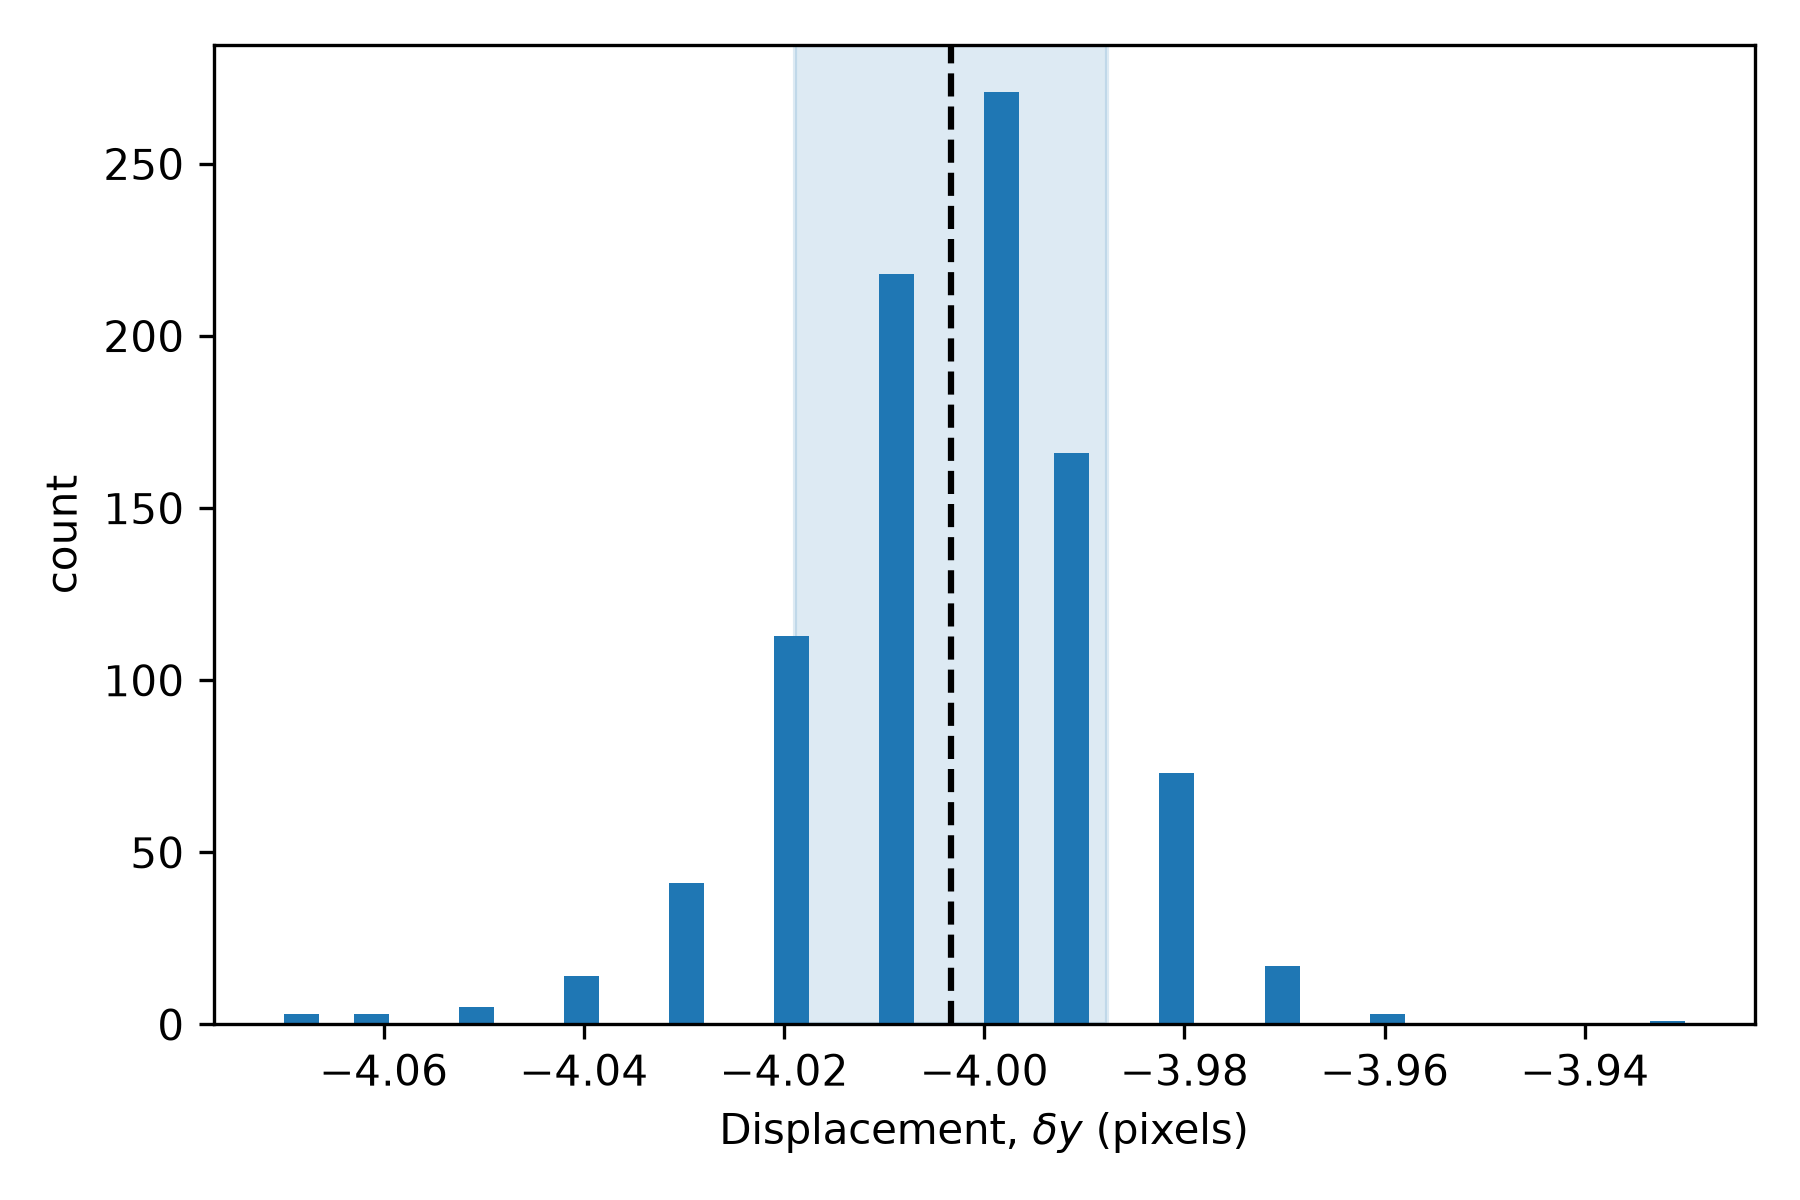
dy distribution for the 928 points in the -4 group: a single peak at -4.00 pixels, std 0.016 pixels -- the shaded band and dashed line mark that mean and its one-std spread directly.Both groups are tight, single-mode distributions, each barely 0.15 pixels wide start to finish. The largest deviation from a clean , anywhere in either group including the 387 straddling points, is 0.09 pixels.
VIC-2D-Style Point Density
High Point Density verifies a denser grid --
count_x=53, count_y=54, spacing_x=spacing_y=5, with
kernel_margin_width=kernel_margin_height=13,
search_margin_width=search_margin_height=25 -- against a real VIC-2D
run. That comparison is for a different experiment, though: a 2%
uniaxial stretch, not a crack. VIC-2D has never analyzed this page's
own crack-dislocation image pair, so nothing below is a VIC-2D result --
just the same grid density and kernel size, in VIC-2D's own style,
applied to this page's own crack instead. Does that same grid change
anything about the field above?
CURRENT_KERNEL_MARGIN = 25
CURRENT_SEARCH_MARGIN = 45
points_current = generate(
    origin=PixelCoordinate(x=CURRENT_SEARCH_MARGIN, y=CURRENT_SEARCH_MARGIN),
    count_x=43,
    count_y=43,
    spacing_x=5,
    spacing_y=5,
)

VIC2D_STYLE_KERNEL_MARGIN = 13
VIC2D_STYLE_SEARCH_MARGIN = 25
points_vic2d = generate(
    origin=PixelCoordinate(x=18, y=16),
    count_x=53,
    count_y=54,
    spacing_x=5,
    spacing_y=5,
)
Saved: synthetic_dislocation_grid_kernel_panels.png
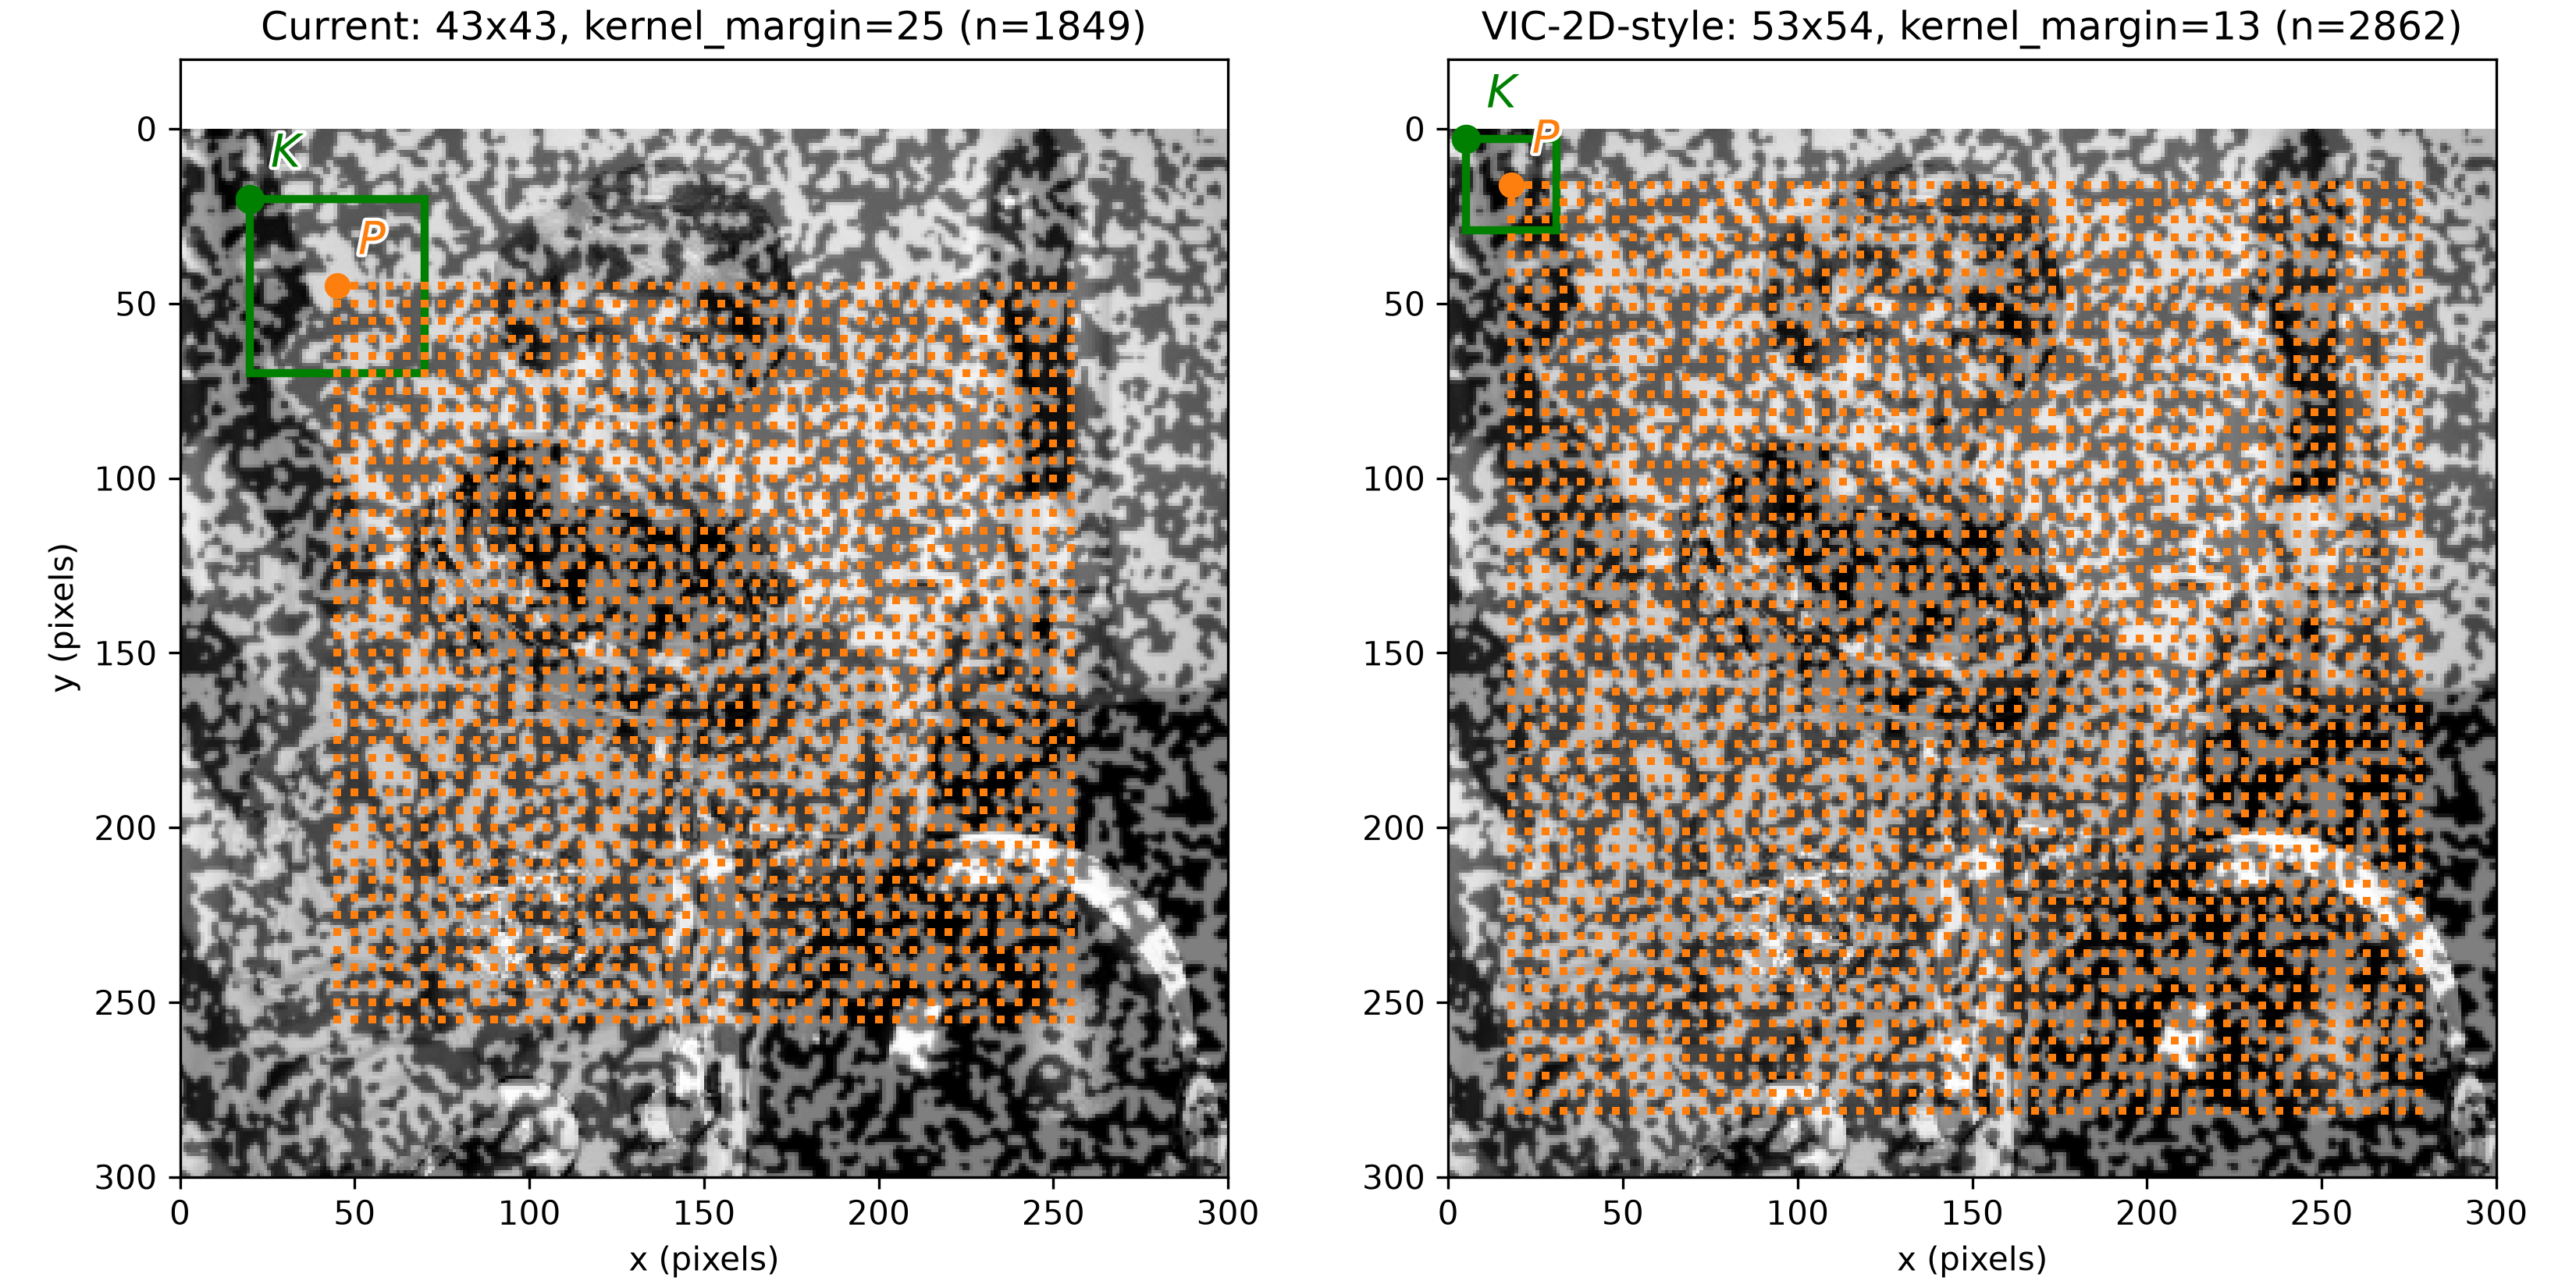
reference_image. Left: the current 43x43 grid (1849 points, 5-pixel spacing), with a green box around points_current[0] showing its 50x50 pixel kernel window (kernel_margin=25). Right: the denser VIC-2D-style 53x54 grid (2862 points, same 5-pixel spacing), with a green box around points_vic2d[0] showing its smaller 26x26 pixel kernel window (kernel_margin=13). In both, the box's origin is marked (green dot) and its tracked point (orange dot), matching A Window Straddling the Crack's own labeling convention.| grid | points | kernel (px) | clipped | max dev (px) | mean dev (px) |
|---|---|---|---|---|---|
| Current (43x43, kernel_margin=25) | 1849 | 50x50 | 0 | 0.0900 | 0.0119 |
| VIC-2D style (53x54, kernel_margin=13) | 2862 | 26x26 | 362 | 0.1900 | 0.0267 |
| grid | kernel (px) | clipped | max dev (px) | mean dev (px) |
|---|---|---|---|---|
| Current (43x43, kernel_margin=25) | 50x50 | 0 | 0.0900 | 0.0119 |
| Current density, VIC-2D kernel (43x43, kernel_margin=13) | 26x26 | 0 | 0.1600 | 0.0257 |
| VIC-2D style (53x54, kernel_margin=13) | 26x26 | 362 | 0.1900 | 0.0267 |
The first table above tracks the two grids as they'd actually run: the VIC-2D-style grid finds more points, 2862 against 1849, but its own smaller kernel window (26x26 pixels, against the current grid's 50x50) roughly doubles the largest deviation from a clean : 0.19 pixels, against 0.09. 362 of its 2862 points also sit close enough to the image edge that their own search windows reach outside it.
Is that the point spacing? Both grids use the same 5-pixel spacing, so no. The second table isolates the kernel size alone: it tracks the current grid's own 1849-point layout, at the same edge-safe origin, but with the VIC-2D grid's smaller kernel instead.
Isolating the kernel size alone already produces most of the difference. It measures 0.16 pixels, against 0.19 for the full VIC-2D grid and 0.09 for the current grid. The kernel window's side length drives this difference, not point spacing and not the image edge.
A 26x26 pixel window captures a quarter of the speckle content a 50x50 pixel window captures. With less speckle content, cross-correlation finds fewer unique features to match. It locks the subpixel position less precisely. That weaker lock raises deviation at every point, even a point whose own window never touches the crack. Edge clipping adds further deviation on top: 0.16 pixels without it, 0.19 pixels with it.
What This Doesn't Do
This is a diagnostic. It doesn't fix anything. Nothing here located the crack; a human already centered the window on it. Discontinuities names the open problem this points toward: an algorithm that finds this signature on its own, rather than a person choosing where to look.
Continue to Experimental Dislocation to check whether the same signature survives on a real crack, where the ground truth isn't known in advance.
synthetic_dislocation_kernel.py
"""Show the kernel window (green box) straddling the crack in
`reference_image`, centered on the crack's own x = 150.
"""

import dictk
from dictk.image import combine, PixelCoordinate
from dictk.plot import subimage_comparison_plot

WIDTH = HEIGHT = 300
KERNEL_MARGIN = 25

speckle = dictk.rosta(width=WIDTH, height=HEIGHT, density=0.5)
photo = dictk.astronaut(width=WIDTH, height=HEIGHT)
reference_image = combine(a=speckle, b=photo)

p0 = PixelCoordinate(x=WIDTH // 2, y=HEIGHT // 2)
kernel_origin = PixelCoordinate(x=p0.x - KERNEL_MARGIN, y=p0.y - KERNEL_MARGIN)

subimage_comparison_plot(
    image=reference_image,
    origin=kernel_origin,
    width=2 * KERNEL_MARGIN,
    height=2 * KERNEL_MARGIN,
    point=p0,
    point_color="orange",
    point_label="$P$",
    subimage_label="kernel",
    color="green",
    origin_label="$K$",
    source_origin_label="$O$",
    figsize=(6.4, 4.8),
    path="synthetic_dislocation_kernel.png",
)

print("Saved: synthetic_dislocation_kernel.png")
synthetic_dislocation_quadrant.py
"""Build a synthetic crack-dislocation image pair and plot the correlation
surface a window straddling the crack produces, ZNCC and FFT side by side.
"""

import dictk
from dictk.image import combine, crack_dislocation, subimage, write, PixelCoordinate
from dictk.correlation import zncc
from dictk.plot import (
    spatial_correlation_quadrant_plot,
    phase_correlation_quadrant_plot,
)

WIDTH = HEIGHT = 300
OFFSET = 4.0
KERNEL_MARGIN = 25
SEARCH_MARGIN = 45

speckle = dictk.rosta(width=WIDTH, height=HEIGHT, density=0.5)
photo = dictk.astronaut(width=WIDTH, height=HEIGHT)
reference_image = combine(a=speckle, b=photo)
current_image = crack_dislocation(arr=reference_image, offset=OFFSET)

write(arr=reference_image, path="synthetic_dislocation_reference.png")
write(arr=current_image, path="synthetic_dislocation_current.png")

p0 = PixelCoordinate(x=WIDTH // 2, y=HEIGHT // 2)
kernel = subimage(
    image=reference_image,
    origin=PixelCoordinate(x=p0.x - KERNEL_MARGIN, y=p0.y - KERNEL_MARGIN),
    width=2 * KERNEL_MARGIN,
    height=2 * KERNEL_MARGIN,
)
search = subimage(
    image=current_image,
    origin=PixelCoordinate(x=p0.x - SEARCH_MARGIN, y=p0.y - SEARCH_MARGIN),
    width=2 * SEARCH_MARGIN,
    height=2 * SEARCH_MARGIN,
)

spatial_correlation_quadrant_plot(
    kernel=kernel,
    search=search,
    correlation_surface=zncc(kernel=kernel, search=search),
    title="Zero-mean Normalized Cross-Correlation (ZNCC)",
    path="synthetic_dislocation_zncc.png",
)
phase_correlation_quadrant_plot(
    kernel=kernel,
    search=search,
    title="Phase Correlation (FFT)",
    path="synthetic_dislocation_phase.png",
)

print(
    "Saved: synthetic_dislocation_reference.png, "
    "synthetic_dislocation_current.png, "
    "synthetic_dislocation_zncc.png, "
    "synthetic_dislocation_phase.png"
)
synthetic_dislocation_sweep.py
"""Sweep the crack_dislocation offset and check whether the correlation
surface's two-peak separation reliably encodes 2x that offset, for both
ZNCC (spatial) and phase correlation (FFT).
"""

import numpy as np
import matplotlib.pyplot as plt
from scipy.signal import find_peaks

import dictk
from dictk.image import combine, crack_dislocation, subimage, PixelCoordinate
from dictk.correlation import zncc, phase_correlation

plt.rcParams.update({"font.family": "serif", "mathtext.fontset": "cm"})

WIDTH = HEIGHT = 300
KERNEL_MARGIN = 25
OFFSETS = [1, 2, 3, 4, 6, 8, 12, 16, 20, 24, 28, 32]

speckle = dictk.rosta(width=WIDTH, height=HEIGHT, density=0.5)
photo = dictk.astronaut(width=WIDTH, height=HEIGHT)
reference_image = combine(a=speckle, b=photo)
p0 = PixelCoordinate(x=WIDTH // 2, y=HEIGHT // 2)


def two_peak_separation(surface: np.ndarray) -> tuple[int, int] | None:
    """Return (separation, count) for the two tallest peaks along the
    argmax column, or None if fewer than two are resolvable."""
    x_max = int(np.argmax(surface.max(axis=0)))
    column = surface[:, x_max]
    peaks, props = find_peaks(column, height=0.2 * column.max(), distance=2)
    if len(peaks) < 2:
        return None
    order = np.argsort(props["peak_heights"])[::-1][:2]
    y_top_two = sorted(peaks[order])
    return int(y_top_two[1] - y_top_two[0])


rows = []
for offset in OFFSETS:
    current_image = crack_dislocation(arr=reference_image, offset=float(offset))
    search_margin = KERNEL_MARGIN + int(np.ceil(offset)) + 10

    kernel = subimage(
        image=reference_image,
        origin=PixelCoordinate(x=p0.x - KERNEL_MARGIN, y=p0.y - KERNEL_MARGIN),
        width=2 * KERNEL_MARGIN,
        height=2 * KERNEL_MARGIN,
    )
    search = subimage(
        image=current_image,
        origin=PixelCoordinate(x=p0.x - search_margin, y=p0.y - search_margin),
        width=2 * search_margin,
        height=2 * search_margin,
    )

    zncc_sep = two_peak_separation(zncc(kernel=kernel, search=search))
    phase_sep = two_peak_separation(phase_correlation(kernel=kernel, search=search))
    rows.append((offset, zncc_sep, phase_sep))

print(
    "| offset (px) | 2 x offset | ZNCC separation | ZNCC matches | Phase separation | Phase matches |"
)
print("|:---:|:---:|:---:|:---:|:---:|:---:|")
for offset, zncc_sep, phase_sep in rows:
    expected = 2 * offset
    print(
        f"| {offset} | {expected} | "
        f"{zncc_sep if zncc_sep is not None else 'n/a'} | "
        f"{zncc_sep == expected} | "
        f"{phase_sep if phase_sep is not None else 'n/a'} | "
        f"{phase_sep == expected} |"
    )
print()

fig, ax = plt.subplots(figsize=(6.0, 5.0), constrained_layout=True)
offsets_plot = [r[0] for r in rows]
zncc_plot = [r[1] for r in rows]
phase_plot = [r[2] for r in rows]
line_x = np.linspace(0, max(offsets_plot), 100)
ax.plot(
    line_x,
    2 * line_x,
    linestyle="--",
    color="black",
    linewidth=1,
    label="separation = 2 x offset",
)
ax.plot(
    offsets_plot,
    zncc_plot,
    marker="o",
    linestyle="none",
    color="tab:blue",
    label="ZNCC",
    markersize=8,
)
ax.plot(
    offsets_plot,
    phase_plot,
    marker="x",
    linestyle="none",
    color="tab:orange",
    label="Phase (FFT)",
    markersize=8,
)
ax.set_xlabel("crack_dislocation offset (pixels)")
ax.set_ylabel("peak separation (pixels)")
ax.set_title("Peak Separation vs. Dislocation Offset")
ax.legend()
fig.savefig("synthetic_dislocation_sweep.png", dpi=300)
print("Saved: synthetic_dislocation_sweep.png")
synthetic_dislocation_x_sweep.py
"""Sweep the kernel window's center x position across the crack and
watch the two ZNCC peaks trade dominance: a single peak away from the
crack, both present and comparable near it.
"""

import matplotlib.pyplot as plt

import dictk
from dictk.image import combine, crack_dislocation, subimage, PixelCoordinate
from dictk.correlation import zncc

plt.rcParams.update({"font.family": "serif", "mathtext.fontset": "cm"})

WIDTH = HEIGHT = 300
OFFSET = 4.0
KERNEL_MARGIN = 25
SEARCH_MARGIN = 45
Y = 150
CENTER_INDEX = SEARCH_MARGIN - KERNEL_MARGIN  # 20, the zero-shift index
LEFT_ROW = CENTER_INDEX + int(OFFSET)  # y=24, dy=+4 (left half's own shift)
RIGHT_ROW = CENTER_INDEX - int(OFFSET)  # y=16, dy=-4 (right half's own shift)

speckle = dictk.rosta(width=WIDTH, height=HEIGHT, density=0.5)
photo = dictk.astronaut(width=WIDTH, height=HEIGHT)
reference_image = combine(a=speckle, b=photo)
current_image = crack_dislocation(arr=reference_image, offset=OFFSET)

xs = list(range(100, 201))
left_peak = []
right_peak = []
for x in xs:
    p0 = PixelCoordinate(x=x, y=Y)
    kernel = subimage(
        image=reference_image,
        origin=PixelCoordinate(x=p0.x - KERNEL_MARGIN, y=p0.y - KERNEL_MARGIN),
        width=2 * KERNEL_MARGIN,
        height=2 * KERNEL_MARGIN,
    )
    search = subimage(
        image=current_image,
        origin=PixelCoordinate(x=p0.x - SEARCH_MARGIN, y=p0.y - SEARCH_MARGIN),
        width=2 * SEARCH_MARGIN,
        height=2 * SEARCH_MARGIN,
    )
    surf = zncc(kernel=kernel, search=search)
    left_peak.append(surf[LEFT_ROW, CENTER_INDEX])
    right_peak.append(surf[RIGHT_ROW, CENTER_INDEX])

full_left_boundary = (
    WIDTH / 2 - KERNEL_MARGIN
)  # 125: kernel entirely left of the crack at or below this x
full_right_boundary = (
    WIDTH / 2 + KERNEL_MARGIN
)  # 175: kernel entirely right of the crack at or above this x

print("| kernel center x | left-half peak (dy=+4) | right-half peak (dy=-4) |")
print("|:---:|:---:|:---:|")
for x in range(100, 201, 10):
    i = xs.index(x)
    print(f"| {x} | {left_peak[i]:.3f} | {right_peak[i]:.3f} |")
print()

fig, ax = plt.subplots(figsize=(7.0, 5.0), constrained_layout=True)
ax.plot(xs, left_peak, color="tab:blue", label="peak at Δy=+4 (left half's own shift)")
ax.plot(
    xs, right_peak, color="tab:orange", label="peak at Δy=-4 (right half's own shift)"
)
ax.axvline(full_left_boundary, color="black", linestyle=":", linewidth=1)
ax.axvline(full_right_boundary, color="black", linestyle=":", linewidth=1)
ax.axvline(WIDTH / 2, color="gray", linestyle="--", linewidth=1)
ax.set_xlabel("kernel window center x (pixels)")
ax.set_ylabel("ZNCC value")
ax.set_title("Peak Magnitudes vs. Window Center x")
ax.legend(loc="lower right")
fig.savefig("synthetic_dislocation_x_sweep.png", dpi=300)
print("Saved: synthetic_dislocation_x_sweep.png")
synthetic_dislocation_x_sweep_panels.py
"""Show the ZNCC Correlation Surface panel itself, side by side, at five
kernel window center x positions straddling the crack -- the single
peak at x=130 splitting into two, crossing near the crack, and merging
back into a single peak at x=170.
"""

import matplotlib.pyplot as plt
import matplotlib.patches as patches
import numpy as np

import dictk
from dictk.image import combine, crack_dislocation, subimage, PixelCoordinate
from dictk.correlation import zncc
from dictk.plot import _correlation_surface_ticks

plt.rcParams.update({"font.family": "serif", "mathtext.fontset": "cm"})

WIDTH = HEIGHT = 300
OFFSET = 4.0
KERNEL_MARGIN = 25
SEARCH_MARGIN = 45
Y = 150
VICINITY_MARGIN = 4
XS_PANELS = [130, 140, 150, 160, 170]

speckle = dictk.rosta(width=WIDTH, height=HEIGHT, density=0.5)
photo = dictk.astronaut(width=WIDTH, height=HEIGHT)
reference_image = combine(a=speckle, b=photo)
current_image = crack_dislocation(arr=reference_image, offset=OFFSET)

fig, axes = plt.subplots(
    1, len(XS_PANELS), figsize=(15.0, 3.4), constrained_layout=True
)
for ax, x in zip(axes, XS_PANELS):
    p0 = PixelCoordinate(x=x, y=Y)
    kernel = subimage(
        image=reference_image,
        origin=PixelCoordinate(x=p0.x - KERNEL_MARGIN, y=p0.y - KERNEL_MARGIN),
        width=2 * KERNEL_MARGIN,
        height=2 * KERNEL_MARGIN,
    )
    search = subimage(
        image=current_image,
        origin=PixelCoordinate(x=p0.x - SEARCH_MARGIN, y=p0.y - SEARCH_MARGIN),
        width=2 * SEARCH_MARGIN,
        height=2 * SEARCH_MARGIN,
    )
    surf = zncc(kernel=kernel, search=search)
    peak_y, peak_x = np.unravel_index(np.argmax(surf), surf.shape)

    im = ax.imshow(surf, cmap="viridis", vmin=0, vmax=1, origin="upper")
    ax.add_patch(
        patches.Circle(
            (peak_x, peak_y),
            radius=VICINITY_MARGIN,
            edgecolor="red",
            facecolor="none",
            linewidth=1.5,
        )
    )
    ax.set_title(f"x={x}")
    ax.set_xlabel(r"$\Delta x$ offset (pixels)")
    surface_height, surface_width = surf.shape
    ax.set_xticks(_correlation_surface_ticks(surface_width))
    ax.set_yticks(_correlation_surface_ticks(surface_height))

axes[0].set_ylabel(r"$\Delta y$ offset (pixels)")
for ax in axes[1:]:
    ax.set_yticklabels([])

fig.colorbar(im, ax=axes, shrink=0.8, label="ZNCC value")
fig.savefig("synthetic_dislocation_x_sweep_panels.png", dpi=300)
print("Saved: synthetic_dislocation_x_sweep_panels.png")
synthetic_dislocation_displacement_field.py
"""Track a full grid of points across the crack. dx stays trivially
near zero everywhere (checked, not assumed), and dy splits cleanly into
a +4 group and a -4 group -- each examined on its own.
"""

import matplotlib.pyplot as plt
import numpy as np

import dictk
from dictk.grid import generate, locate_subpixel
from dictk.image import PixelCoordinate, combine, crack_dislocation
from dictk.plot import point_displacement_plot


def mean_std_histogram(*, values, bins, color, xlabel, path):
    """Save a histogram with its own mean/std drawn behind the bars: a
    semi-transparent band, colored to match the bars, spanning mean +/-
    one std, with a black dashed line at the mean -- black rather than
    matching the bars so it stays visible regardless of bar color (a
    same-color line on tab:gray bars all but disappears).
    """
    mean, std = values.mean(), values.std()
    fig, ax = plt.subplots(figsize=(6.0, 4.0))
    ax.axvspan(mean - std, mean + std, color=color, alpha=0.15, zorder=0)
    ax.hist(values, bins=bins, color=color, zorder=1)
    ax.axvline(mean, color="black", linestyle="--", linewidth=1.5, zorder=2)
    ax.set_xlabel(xlabel)
    ax.set_ylabel("count")
    plt.tight_layout()
    plt.savefig(path, dpi=300)
    plt.close(fig)


WIDTH = HEIGHT = 300
OFFSET = 4.0
KERNEL_MARGIN = 25
SEARCH_MARGIN = 45

speckle = dictk.rosta(width=WIDTH, height=HEIGHT, density=0.5)
photo = dictk.astronaut(width=WIDTH, height=HEIGHT)
reference_image = combine(a=speckle, b=photo)
current_image = crack_dislocation(arr=reference_image, offset=OFFSET)

points = generate(
    origin=PixelCoordinate(x=SEARCH_MARGIN, y=SEARCH_MARGIN),
    count_x=43,
    count_y=43,
    spacing_x=5,
    spacing_y=5,
)
found = locate_subpixel(
    reference_image=reference_image,
    current_image=current_image,
    reference_points=points,
    kernel_margin_width=KERNEL_MARGIN,
    kernel_margin_height=KERNEL_MARGIN,
    search_margin_width=SEARCH_MARGIN,
    search_margin_height=SEARCH_MARGIN,
    upsample_factor=100,
)

dx = np.array([f.x - p.x for f, p in zip(found, points)])
dy = np.array([f.y - p.y for f, p in zip(found, points)])

DX_TOLERANCE = 0.1  # px
assert np.abs(dx).max() < DX_TOLERANCE, (
    f"dx should be trivially ~0 (crack_dislocation only shifts pixels "
    f"vertically), got max |dx| = {np.abs(dx).max():.4f} px"
)

point_displacement_plot(
    points=found,
    values=list(dy),
    label=r"Displacement, $\delta y$ (pixels)",
    image=current_image,
    dot_size=6,
    marker="s",
    cmap="coolwarm",
    path="synthetic_dislocation_displacement_field.png",
)

# --- Focus 1: dx, across all 1849 points ---
print("| quantity | value |")
print("|---|---:|")
print(f"| points in group | {len(dx)} |")
print(f"| mean dx (px) | {dx.mean():.4f} |")
print(f"| max abs dx (px) | {np.abs(dx).max():.4f} |")
print()

mean_std_histogram(
    values=dx,
    bins=40,
    color="tab:gray",
    xlabel=r"Displacement, $\delta x$ (pixels)",
    path="synthetic_dislocation_displacement_field_dx_histogram.png",
)

# --- Focus 2 & 3: dy, split into its own +4 and -4 groups ---
dy_positive = dy[dy > 0]
dy_negative = dy[dy < 0]

print("| quantity | value |")
print("|---|---:|")
print(f"| points in group | {len(dy_positive)} |")
print(f"| mean dy (px) | {dy_positive.mean():.4f} |")
print(f"| std dy (px) | {dy_positive.std():.4f} |")
print(f"| min dy (px) | {dy_positive.min():.4f} |")
print(f"| max dy (px) | {dy_positive.max():.4f} |")
print()

mean_std_histogram(
    values=dy_positive,
    bins=40,
    color="tab:red",
    xlabel=r"Displacement, $\delta y$ (pixels)",
    path="synthetic_dislocation_displacement_field_dy_positive_histogram.png",
)

print("| quantity | value |")
print("|---|---:|")
print(f"| points in group | {len(dy_negative)} |")
print(f"| mean dy (px) | {dy_negative.mean():.4f} |")
print(f"| std dy (px) | {dy_negative.std():.4f} |")
print(f"| min dy (px) | {dy_negative.min():.4f} |")
print(f"| max dy (px) | {dy_negative.max():.4f} |")
print()

mean_std_histogram(
    values=dy_negative,
    bins=40,
    color="tab:blue",
    xlabel=r"Displacement, $\delta y$ (pixels)",
    path="synthetic_dislocation_displacement_field_dy_negative_histogram.png",
)

print(
    "Saved: synthetic_dislocation_displacement_field.png, "
    "synthetic_dislocation_displacement_field_dx_histogram.png, "
    "synthetic_dislocation_displacement_field_dy_positive_histogram.png, "
    "synthetic_dislocation_displacement_field_dy_negative_histogram.png"
)
synthetic_dislocation_grid_kernel_panels.py
"""Show the two point grids from "VIC-2D-Style Point Density" side by
side over `reference_image`: the current 43x43 grid on the left, the
denser VIC-2D-style 53x54 grid on the right, each with a green box
around its own first point's kernel window -- 50x50 pixels for the
current grid's kernel_margin=25, 26x26 pixels for the VIC-2D-style
grid's kernel_margin=13. The box's own origin (green dot, labeled $K$)
and the tracked point at its center (orange dot, labeled $P$) match
"A Window Straddling the Crack"'s own labeling convention.
"""

import matplotlib.patches as patches
import matplotlib.patheffects as patheffects
import matplotlib.pyplot as plt

import dictk
from dictk.grid import generate
from dictk.image import PixelCoordinate, combine

WIDTH = HEIGHT = 300

speckle = dictk.rosta(width=WIDTH, height=HEIGHT, density=0.5)
photo = dictk.astronaut(width=WIDTH, height=HEIGHT)
reference_image = combine(a=speckle, b=photo)

CURRENT_KERNEL_MARGIN = 25
CURRENT_SEARCH_MARGIN = 45
points_current = generate(
    origin=PixelCoordinate(x=CURRENT_SEARCH_MARGIN, y=CURRENT_SEARCH_MARGIN),
    count_x=43,
    count_y=43,
    spacing_x=5,
    spacing_y=5,
)

VIC2D_STYLE_KERNEL_MARGIN = 13
VIC2D_STYLE_SEARCH_MARGIN = 25
points_vic2d = generate(
    origin=PixelCoordinate(x=18, y=16),
    count_x=53,
    count_y=54,
    spacing_x=5,
    spacing_y=5,
)

PANELS = [
    ("Current: 43x43, kernel_margin=25", points_current, CURRENT_KERNEL_MARGIN),
    ("VIC-2D-style: 53x54, kernel_margin=13", points_vic2d, VIC2D_STYLE_KERNEL_MARGIN),
]

LABEL_OFFSET = 6
LABEL_OUTLINE = [patheffects.withStroke(linewidth=2, foreground="white")]

fig, axes = plt.subplots(1, 2, figsize=(11.0, 5.5), constrained_layout=True)
for ax, (title, points, kernel_margin) in zip(axes, PANELS):
    ax.imshow(
        reference_image,
        cmap="gray",
        origin="upper",
        extent=(0, WIDTH, HEIGHT, 0),
    )
    ax.plot(
        [p.x for p in points],
        [p.y for p in points],
        marker="s",
        markersize=2.5,
        markeredgewidth=0,
        color="tab:orange",
        linestyle="none",
    )
    p0 = points[0]
    origin = PixelCoordinate(x=p0.x - kernel_margin, y=p0.y - kernel_margin)
    ax.add_patch(
        patches.Rectangle(
            (origin.x, origin.y),
            2 * kernel_margin,
            2 * kernel_margin,
            edgecolor="green",
            facecolor="none",
            linewidth=2.5,
        )
    )
    ax.plot(origin.x, origin.y, marker="o", color="green", markersize=8)
    ax.text(
        origin.x + LABEL_OFFSET,
        origin.y - LABEL_OFFSET,
        "$K$",
        color="green",
        fontsize=14,
        va="bottom",
        path_effects=LABEL_OUTLINE,
    )
    ax.plot(p0.x, p0.y, marker="o", color="tab:orange", markersize=7)
    ax.text(
        p0.x + LABEL_OFFSET,
        p0.y - LABEL_OFFSET,
        "$P$",
        color="tab:orange",
        fontsize=14,
        va="bottom",
        path_effects=LABEL_OUTLINE,
    )
    # A little headroom above y=0 so the $K$ label (which can land right
    # at the image's own top edge, depending on the grid's origin) never
    # collides with the panel's title.
    ax.set_xlim(0, WIDTH)
    ax.set_ylim(HEIGHT, -20)
    ax.set_xlabel("x (pixels)")
    ax.set_title(f"{title} (n={len(points)})")

axes[0].set_ylabel("y (pixels)")

fig.savefig("synthetic_dislocation_grid_kernel_panels.png", dpi=300)
print("Saved: synthetic_dislocation_grid_kernel_panels.png")
synthetic_dislocation_displacement_field_vic2d.py
"""Compare the page's own displacement-field grid (43x43,
kernel_margin=25) against a VIC-2D-style denser grid (53x54,
kernel_margin=13, matching high_point_density.md's own convention):
same crack, same story, but does the smaller kernel change anything?
"""

import numpy as np

import dictk
from dictk.grid import generate, locate_subpixel
from dictk.image import PixelCoordinate, combine, crack_dislocation

WIDTH = HEIGHT = 300
OFFSET = 4.0

speckle = dictk.rosta(width=WIDTH, height=HEIGHT, density=0.5)
photo = dictk.astronaut(width=WIDTH, height=HEIGHT)
reference_image = combine(a=speckle, b=photo)
current_image = crack_dislocation(arr=reference_image, offset=OFFSET)


def track(*, origin, count_x, count_y, spacing, kernel_margin, search_margin):
    points = generate(
        origin=origin,
        count_x=count_x,
        count_y=count_y,
        spacing_x=spacing,
        spacing_y=spacing,
    )
    clipped = sum(
        1
        for p in points
        if p.x - search_margin < 0
        or p.y - search_margin < 0
        or p.x + search_margin > WIDTH
        or p.y + search_margin > HEIGHT
    )
    found = locate_subpixel(
        reference_image=reference_image,
        current_image=current_image,
        reference_points=points,
        kernel_margin_width=kernel_margin,
        kernel_margin_height=kernel_margin,
        search_margin_width=search_margin,
        search_margin_height=search_margin,
        upsample_factor=100,
    )
    dy = np.array([f.y - p.y for f, p in zip(found, points)])
    return dy, clipped


def deviation(dy):
    return np.minimum(np.abs(dy - OFFSET), np.abs(dy + OFFSET))


CURRENT_KERNEL_MARGIN = 25
CURRENT_SEARCH_MARGIN = 45
dy_current, clipped_current = track(
    origin=PixelCoordinate(x=CURRENT_SEARCH_MARGIN, y=CURRENT_SEARCH_MARGIN),
    count_x=43,
    count_y=43,
    spacing=5,
    kernel_margin=CURRENT_KERNEL_MARGIN,
    search_margin=CURRENT_SEARCH_MARGIN,
)

VIC2D_STYLE_KERNEL_MARGIN = 13
VIC2D_STYLE_SEARCH_MARGIN = 25
dy_vic2d, clipped_vic2d = track(
    origin=PixelCoordinate(x=18, y=16),
    count_x=53,
    count_y=54,
    spacing=5,
    kernel_margin=VIC2D_STYLE_KERNEL_MARGIN,
    search_margin=VIC2D_STYLE_SEARCH_MARGIN,
)

# Same density and origin as the current grid, but with the VIC-2D
# grid's own smaller kernel -- isolates the kernel-size effect from
# both point density and edge clipping (this grid clips nothing).
dy_isolated, clipped_isolated = track(
    origin=PixelCoordinate(x=CURRENT_SEARCH_MARGIN, y=CURRENT_SEARCH_MARGIN),
    count_x=43,
    count_y=43,
    spacing=5,
    kernel_margin=VIC2D_STYLE_KERNEL_MARGIN,
    search_margin=VIC2D_STYLE_SEARCH_MARGIN,
)

dev_current = deviation(dy_current)
dev_vic2d = deviation(dy_vic2d)
dev_isolated = deviation(dy_isolated)

print("| grid | points | kernel (px) | clipped | max dev (px) | mean dev (px) |")
print("|---|---|---|---|---|---|")
print(
    f"| Current (43x43, kernel_margin=25) | {len(dy_current)} | "
    f"{2 * CURRENT_KERNEL_MARGIN}x{2 * CURRENT_KERNEL_MARGIN} | {clipped_current} | "
    f"{dev_current.max():.4f} | {dev_current.mean():.4f} |"
)
print(
    f"| VIC-2D style (53x54, kernel_margin=13) | {len(dy_vic2d)} | "
    f"{2 * VIC2D_STYLE_KERNEL_MARGIN}x{2 * VIC2D_STYLE_KERNEL_MARGIN} | {clipped_vic2d} | "
    f"{dev_vic2d.max():.4f} | {dev_vic2d.mean():.4f} |"
)
print()

print("| grid | kernel (px) | clipped | max dev (px) | mean dev (px) |")
print("|---|---|---|---|---|")
print(
    f"| Current (43x43, kernel_margin=25) | "
    f"{2 * CURRENT_KERNEL_MARGIN}x{2 * CURRENT_KERNEL_MARGIN} | {clipped_current} | "
    f"{dev_current.max():.4f} | {dev_current.mean():.4f} |"
)
print(
    f"| Current density, VIC-2D kernel (43x43, kernel_margin=13) | "
    f"{2 * VIC2D_STYLE_KERNEL_MARGIN}x{2 * VIC2D_STYLE_KERNEL_MARGIN} | {clipped_isolated} | "
    f"{dev_isolated.max():.4f} | {dev_isolated.mean():.4f} |"
)
print(
    f"| VIC-2D style (53x54, kernel_margin=13) | "
    f"{2 * VIC2D_STYLE_KERNEL_MARGIN}x{2 * VIC2D_STYLE_KERNEL_MARGIN} | {clipped_vic2d} | "
    f"{dev_vic2d.max():.4f} | {dev_vic2d.mean():.4f} |"
)
Experimental Dislocation
Synthetic Dislocation found a clean signature on a known ground truth: a straddling window's correlation surface shows two comparably-tall peaks, not one. A synthetic image is generous, though. It has no camera noise, no lighting variation, no unknown displacement field. This section repeats the same experiment on a real crack, to check whether the signature survives outside a synthetic setup.
Data Download
Both images below are real 512x512 experimental micrographs of a crack, included unmodified rather than generated by this book.
| File | Description | Size |
|---|---|---|
| experimental_dislocation_reference.tiff | Reference configuration, 512x512 pixels | 256 KB |
| experimental_dislocation_current.tiff | Deformed configuration, 512x512 pixels | 256 KB |
from dictk.image import read, write

reference_image = read(path="experimental_dislocation_reference.tiff")
current_image = read(path="experimental_dislocation_current.tiff")

write(arr=reference_image, path="experimental_dislocation_reference_preview.png")
write(arr=current_image, path="experimental_dislocation_current_preview.png")
Saved: experimental_dislocation_reference_preview.png, experimental_dislocation_current_preview.png
A Window Straddling the Real Crack
Unlike the synthetic case, the true displacement field here isn't known
in advance. It isn't purely vertical either: a real crack can open at
an angle, not just split into a clean up/down jump. Center a window
directly on the crack, at x=218, y=186, with kernel_margin=25 and
search_margin=65 (generous enough that the true match can't fall
outside the search area and get clipped):
from dictk.image import subimage, PixelCoordinate
from dictk.correlation import zncc
from dictk.plot import spatial_correlation_quadrant_plot, phase_correlation_quadrant_plot

p0 = PixelCoordinate(x=218, y=186)
kernel_margin, search_margin = 25, 65
kernel = subimage(
    image=reference_image,
    origin=PixelCoordinate(x=p0.x - kernel_margin, y=p0.y - kernel_margin),
    width=2 * kernel_margin, height=2 * kernel_margin,
)
search = subimage(
    image=current_image,
    origin=PixelCoordinate(x=p0.x - search_margin, y=p0.y - search_margin),
    width=2 * search_margin, height=2 * search_margin,
)

spatial_correlation_quadrant_plot(
    kernel=kernel, search=search,
    correlation_surface=zncc(kernel=kernel, search=search),
    title="Zero-mean Normalized Cross-Correlation (ZNCC)",
    path="experimental_dislocation_zncc.png",
)
Saved: experimental_dislocation_zncc.png, experimental_dislocation_phase.png
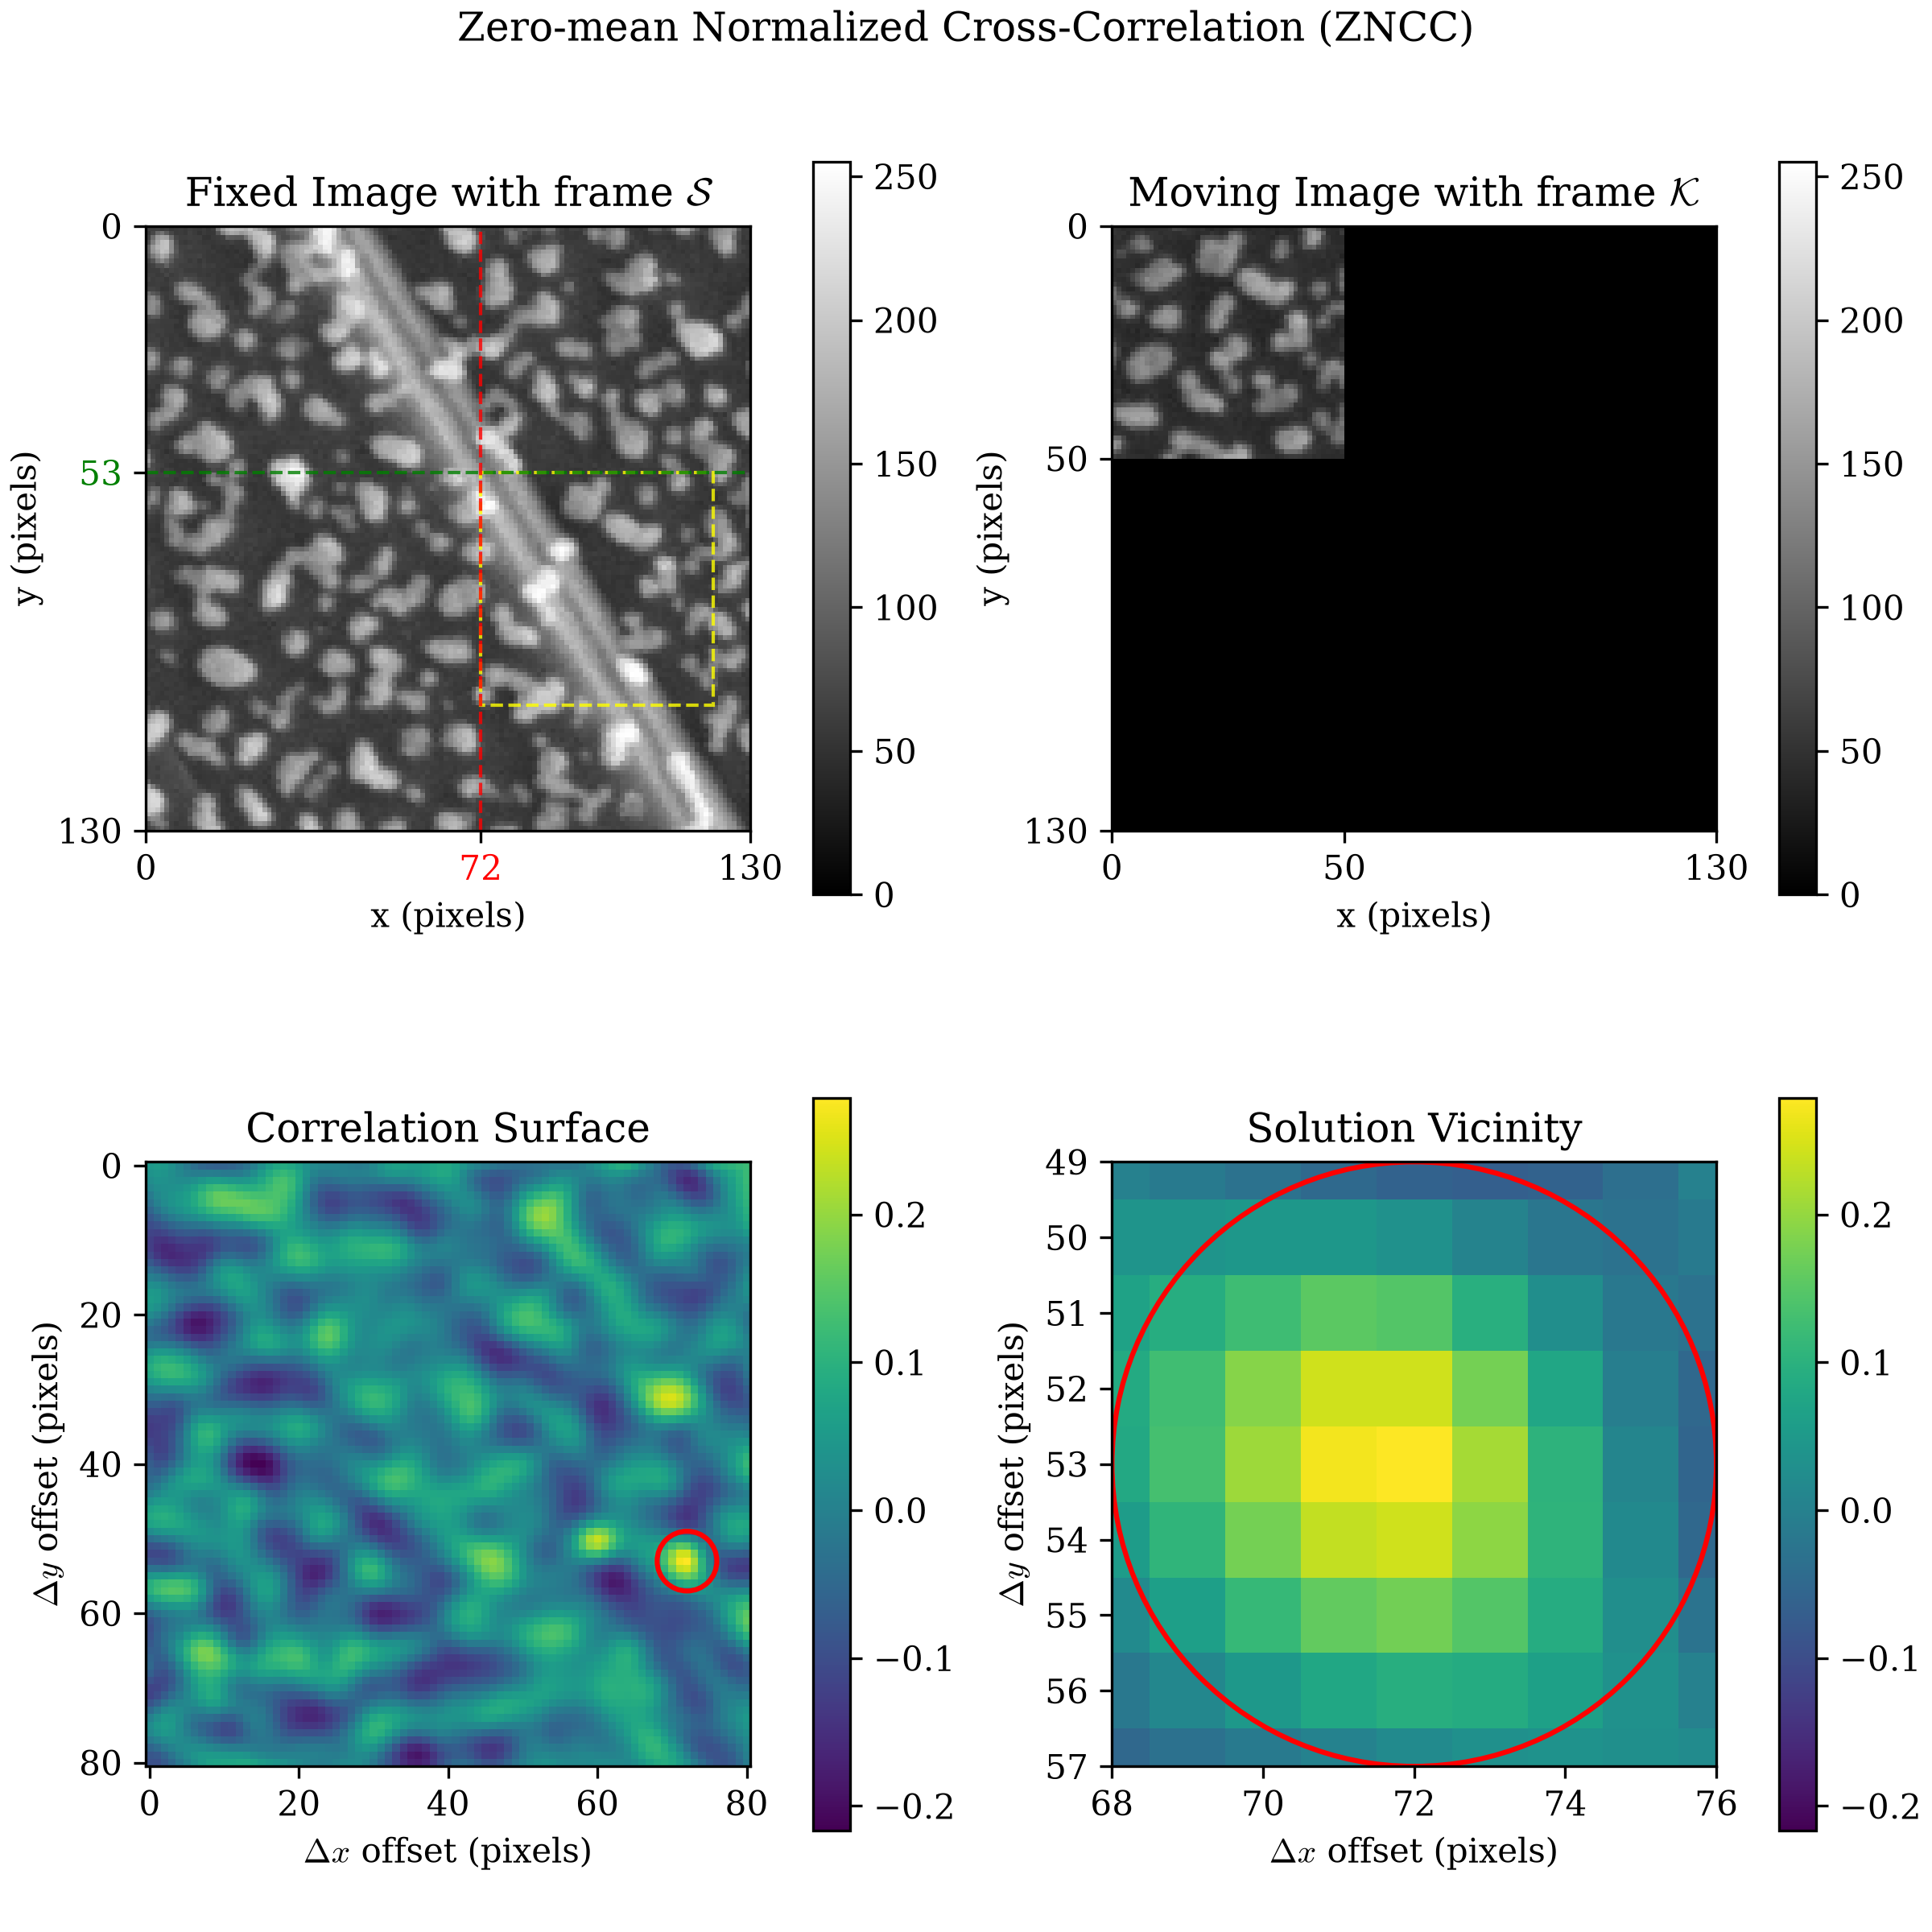
FFT on Real Texture: Noisier, Not Just Smaller
phase_correlation_quadrant_plot(
    kernel=kernel, search=search,
    title="Phase Correlation (FFT)",
    path="experimental_dislocation_phase.png",
)
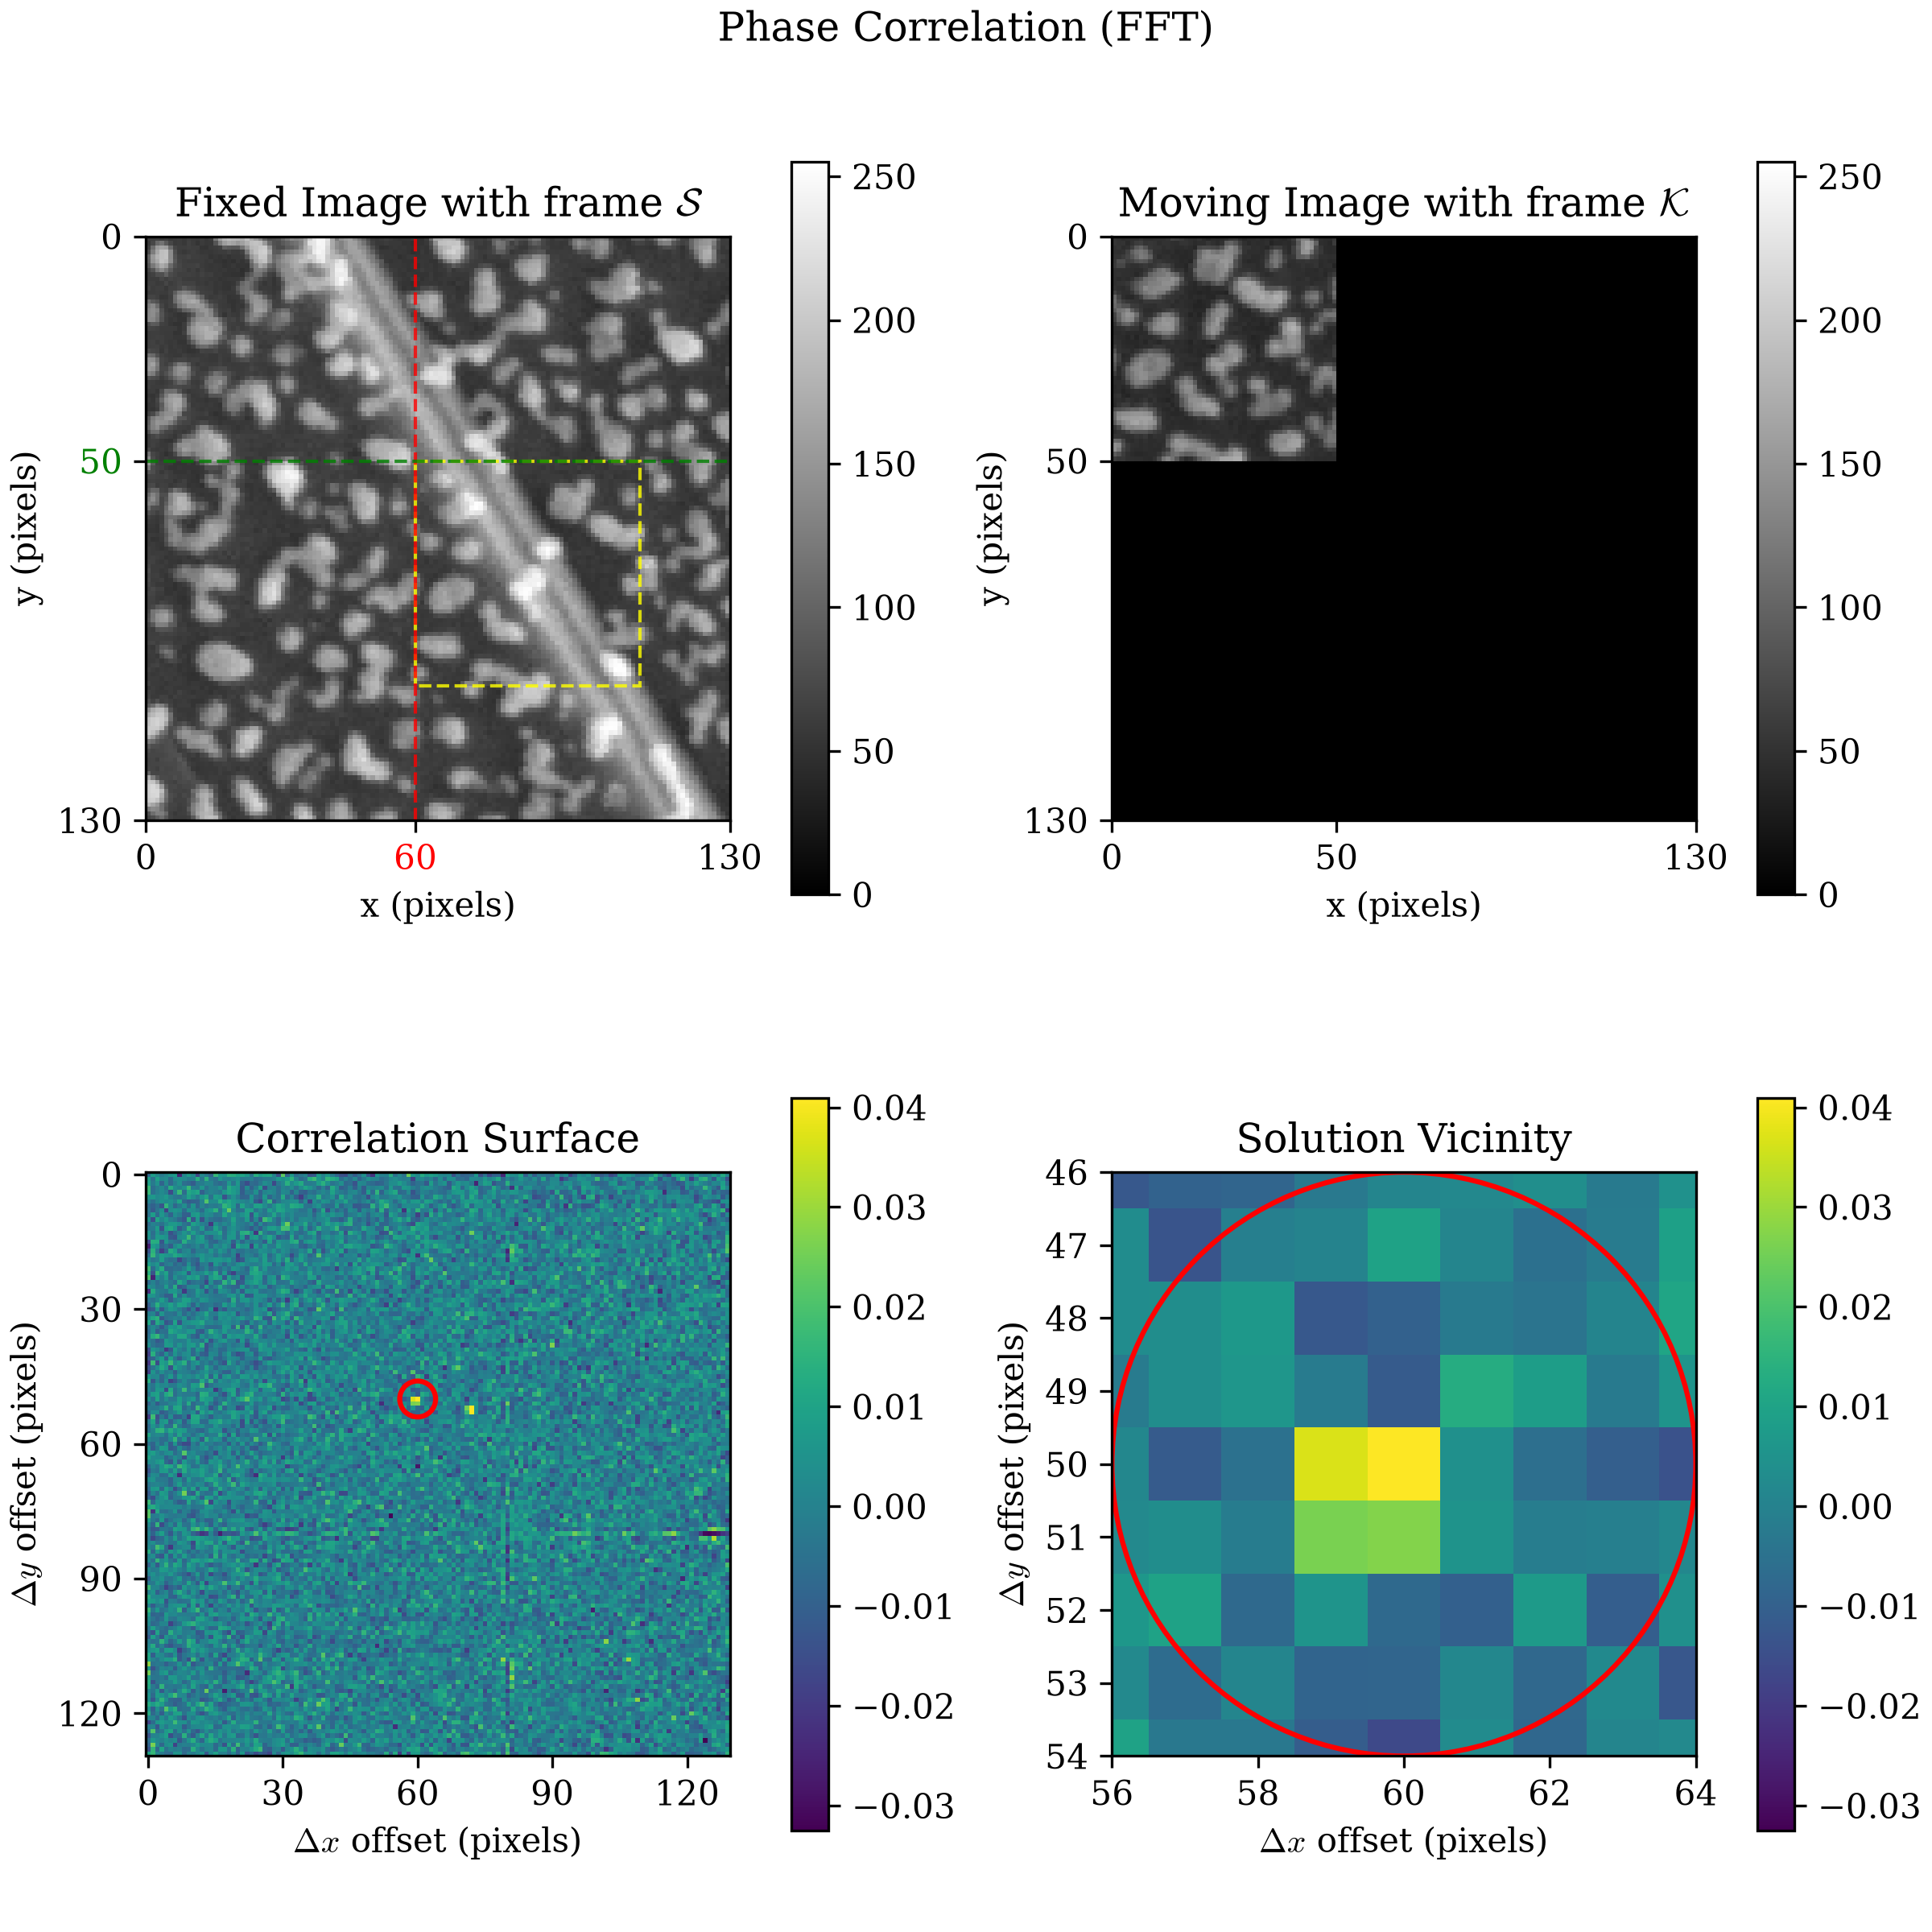
Both criteria agreed exactly on synthetic data. They don't here. Real,
non-periodic texture is exactly the case
phase_correlation's
own docstring already warns about: the raw FFT surface is far more
sensitive to noise than a spatial-domain criterion computed the same
window. ZNCC's two-peak signature is the one worth trusting on real
data. This evidence puts the FFT surface itself in doubt as a
diagnostic.
What Carries Over From the Synthetic Case
The core finding survives: a window straddling a real discontinuity still shows two comparably-tall peaks, not one, matching Synthetic Dislocation's result. What changes on real data is how cleanly the signature shows up. Here it's a bumpy, noisy background rather than a flat one, plus a real gap between the criteria that a synthetic, noise-free image can't reveal.
Discontinuities named the actual open problem: an algorithm that finds this signature on its own. Nothing here does that. Continue to Discontinuity Localization, which tries a few ways to build one.
experimental_dislocation_quadrant.py
"""Plot the correlation surface a window straddling a real experimental
crack produces, ZNCC and FFT side by side. The two source images are
real experimental micrographs, copied in unmodified.
"""

from dictk.image import read, subimage, PixelCoordinate
from dictk.correlation import zncc
from dictk.plot import (
    spatial_correlation_quadrant_plot,
    phase_correlation_quadrant_plot,
)

KERNEL_MARGIN = 25
SEARCH_MARGIN = 65

reference_image = read(path="experimental_dislocation_reference.tiff")
current_image = read(path="experimental_dislocation_current.tiff")

p0 = PixelCoordinate(x=218, y=186)
kernel = subimage(
    image=reference_image,
    origin=PixelCoordinate(x=p0.x - KERNEL_MARGIN, y=p0.y - KERNEL_MARGIN),
    width=2 * KERNEL_MARGIN,
    height=2 * KERNEL_MARGIN,
)
search = subimage(
    image=current_image,
    origin=PixelCoordinate(x=p0.x - SEARCH_MARGIN, y=p0.y - SEARCH_MARGIN),
    width=2 * SEARCH_MARGIN,
    height=2 * SEARCH_MARGIN,
)

spatial_correlation_quadrant_plot(
    kernel=kernel,
    search=search,
    correlation_surface=zncc(kernel=kernel, search=search),
    title="Zero-mean Normalized Cross-Correlation (ZNCC)",
    path="experimental_dislocation_zncc.png",
)
phase_correlation_quadrant_plot(
    kernel=kernel,
    search=search,
    title="Phase Correlation (FFT)",
    path="experimental_dislocation_phase.png",
)

print("Saved: experimental_dislocation_zncc.png, experimental_dislocation_phase.png")
Discontinuity Localization
Synthetic Dislocation and Experimental Dislocation both found the same signature: a window straddling a crack shows two comparably-tall correlation peaks, not one. Both stopped there. A person centered the window on the crack first. Neither page found the crack on its own. This page tries three ways to find a crack on its own, compares them, and ships the one that wins.
A Naive Baseline: Grid Anomaly
The cheapest thing to try uses no new code at all. Run standard,
single-peak DIC across the crack with
dictk.grid.locate, the same way every
earlier chapter does, and see what a displacement field recovered while
ignoring the crack actually looks like:
import dictk
from dictk.grid import generate, locate
from dictk.image import PixelCoordinate, combine, crack_dislocation

speckle = dictk.rosta(width=300, height=300, density=0.5)
photo = dictk.astronaut(width=300, height=300)
reference_image = combine(a=speckle, b=photo)
current_image = crack_dislocation(arr=reference_image, offset=4.0)

points = generate(
    origin=PixelCoordinate(x=100, y=150), count_x=11, count_y=1,
    spacing_x=10, spacing_y=1,
)
found = locate(
    reference_image=reference_image, current_image=current_image,
    reference_points=points,
    kernel_margin_width=25, kernel_margin_height=25,
    search_margin_width=45, search_margin_height=45,
)
Grid spacing: 10 px, 11 points, 11 correlation evaluations
Largest displacement jump: 140 -> 150px
Estimated crack position: x=145.0
Error vs. known x=150: 5.0px

Saved: discontinuity_localization_baseline.png
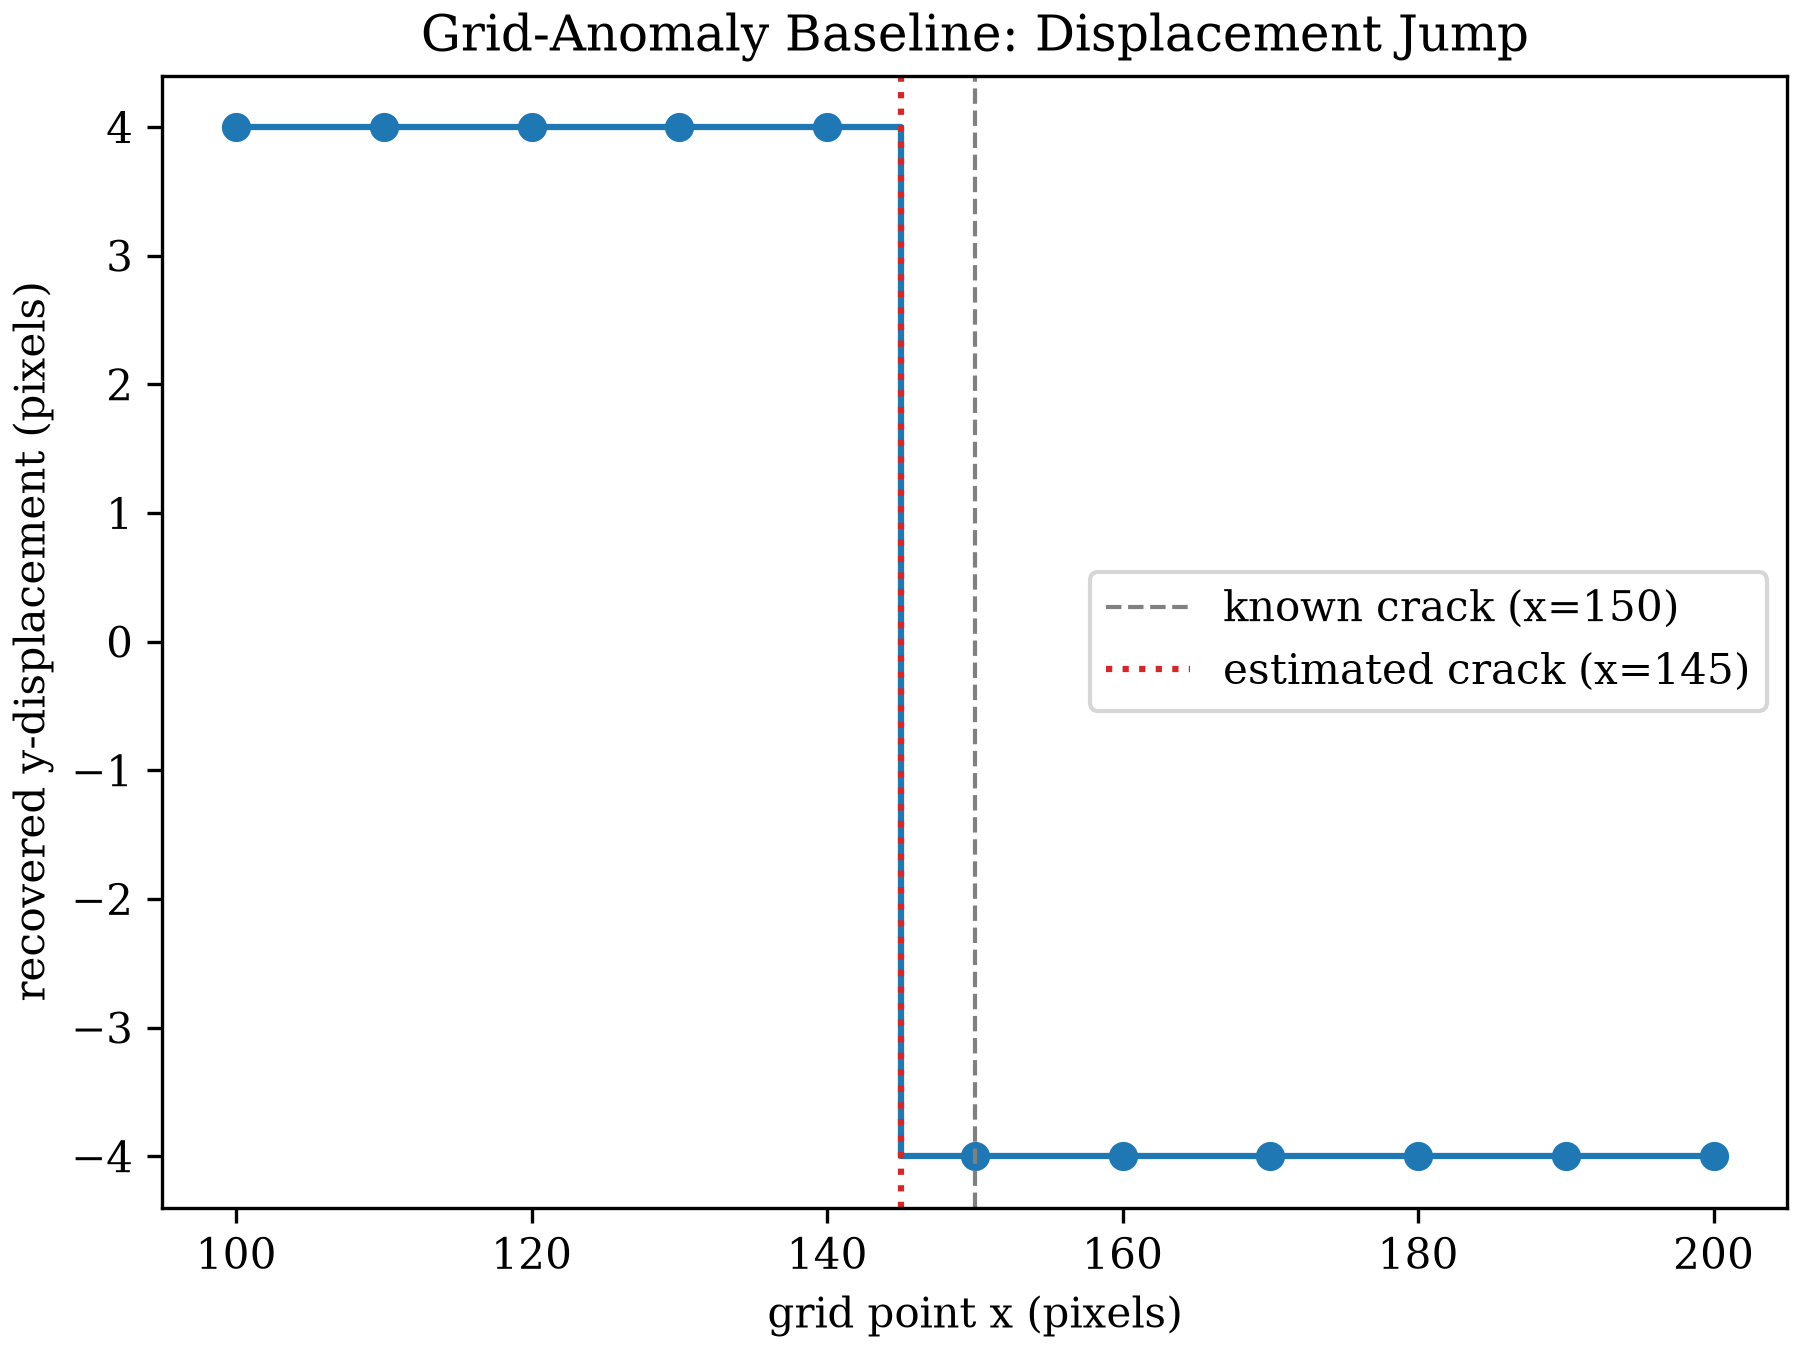
It works, in the sense that it flags roughly the right neighborhood. It's also a proxy, not a measurement of the thing itself. Nothing here looks at peak structure. A large stretch, not a crack, would produce the same kind of jump. Resolution is capped at the grid's own spacing. Tighten the grid and the jump narrows, but so does how many points a DIC run at that spacing can afford to place.
A Peak-Ratio Metric
Synthetic Dislocation
already measured a straddling window's two peaks by hand: heights 0.528
and 0.519 at x=150. Turning that into a number that needs no ground
truth: dictk.discontinuity.peak_ratio
divides the second-tallest peak by the tallest, along the correlation
surface's own argmax column.
from dictk.correlation import zncc
from dictk.discontinuity import peak_ratio
from dictk.image import PixelCoordinate, subimage

for x in (150, 100):
    p0 = PixelCoordinate(x=x, y=150)
    kernel = subimage(
        image=reference_image,
        origin=PixelCoordinate(x=p0.x - 25, y=p0.y - 25),
        width=50, height=50,
    )
    search = subimage(
        image=current_image,
        origin=PixelCoordinate(x=p0.x - 45, y=p0.y - 45),
        width=90, height=90,
    )
    ratio = peak_ratio(surface=zncc(kernel=kernel, search=search))
    print(f"x={x}: peak_ratio={ratio:.3f}")
x=150: peak_ratio=0.983
x=100: peak_ratio=0.000
Centered on the crack, peak_ratio is 0.983, close to the 1.0 two
perfectly equal peaks would give. At x=100, well clear of the crack,
it's 0.0: one peak resolvable, nothing to divide against. A single
number now stands in for "does this window straddle a discontinuity,"
with no offset to already know in advance.
A Dense Sweep and Subpixel Refinement
dictk.discontinuity.sweep
evaluates peak_ratio at many window-center positions along a line, and
dictk.discontinuity.locate
takes that sweep's tallest value and refines it to subpixel precision
with a 3-point parabolic fit. Sweeping the same x=100 to x=200 range
Synthetic Dislocation
already swept by hand:
Evaluations: 101 Located crack position: x=149.804 Error vs. known x=150: 0.196px
Saved: discontinuity_localization_sweep.png
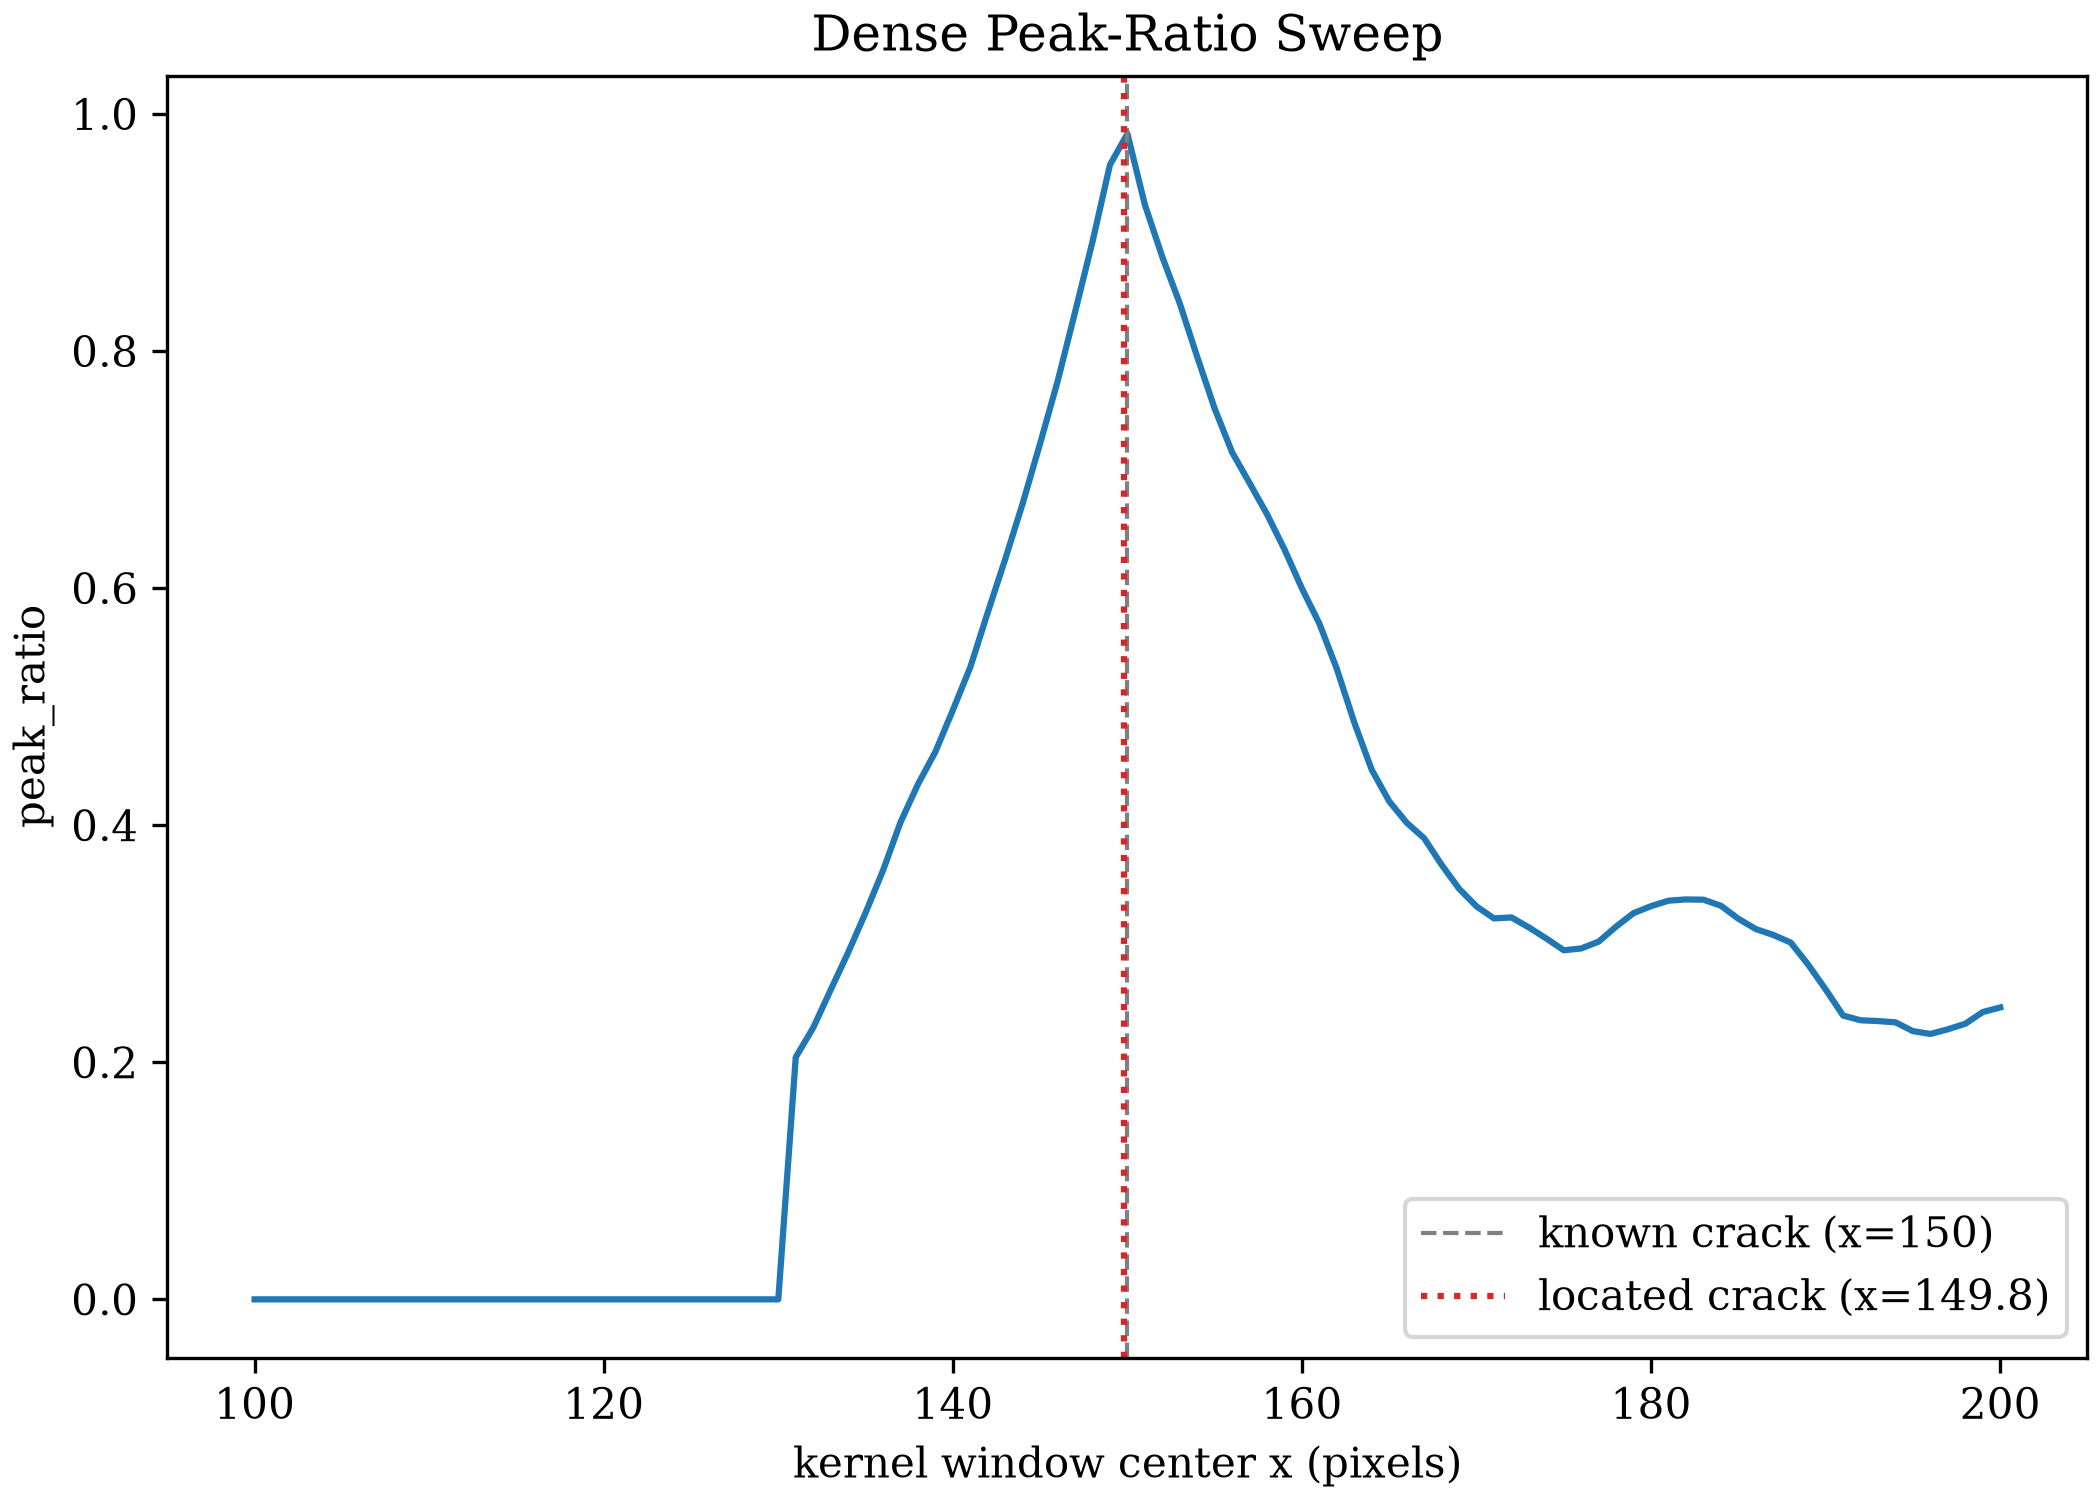
101 evaluations, one per swept position, land 0.2 pixels from the known crack. No offset, no hand-picked center. The sweep finds the crossing on its own.
A Faster Alternative: Golden-Section Search
A dense sweep evaluates every candidate position, even the ones far
from any discontinuity. peak_ratio rises to a single maximum and falls
away on both sides of the crack. That's exactly the shape a
derivative-free optimizer can search without visiting every point.
Golden-section search narrows a bracket toward a unimodal function's
maximum in evaluations instead of sweep's :
Golden-section result: x=150.25, evaluations=12 Error vs. known x=150: 0.251px
| Approach | Evaluations | Localization Error (px) | Notes |
|---|---|---|---|
| Grid anomaly (baseline) | 11 | 5.0 | resolution capped at 10px grid spacing |
| Dense peak-ratio sweep (winner) | 101 | 0.196 | robust to bracket width, see below |
| Golden-section peak-ratio search | 12 | 0.251 | fast here, breaks on real data -- see below |
Saved: discontinuity_localization_bisection.png
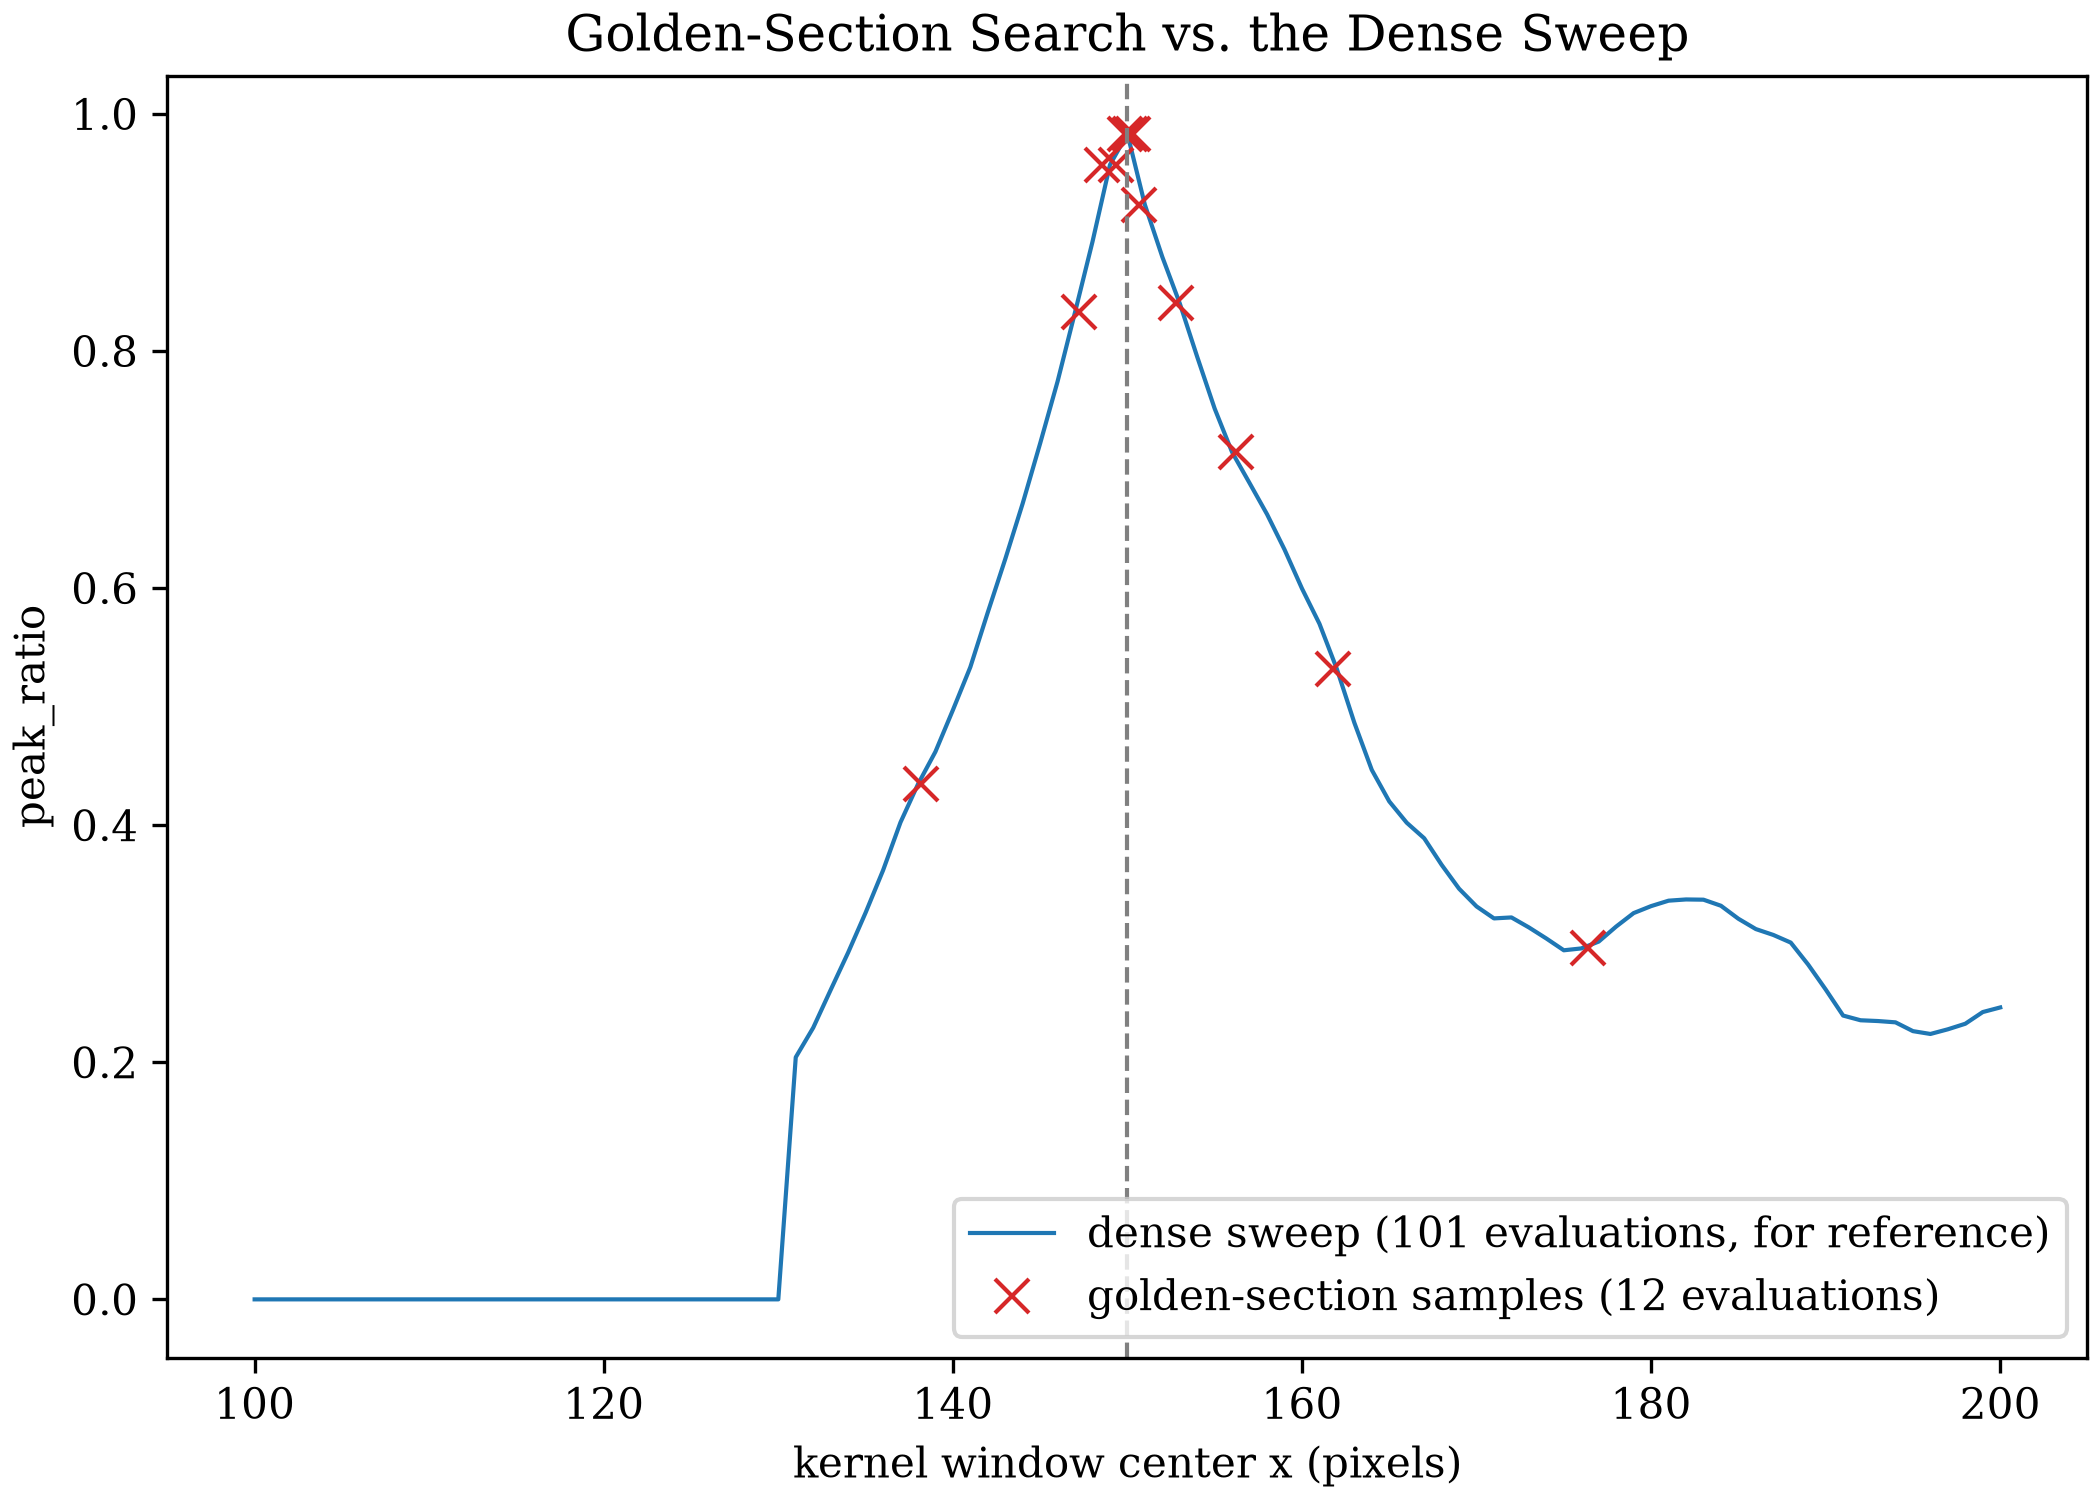
12 evaluations instead of 101, landing 0.25 pixels from the known crack. That's barely worse than the dense sweep, for roughly a tenth of the cost. On this dataset, it looks like a strictly better trade.
Applying It to Real Data
Experimental Dislocation
already centered a window by eye on the real crack, at x=218, y=186.
This runs the dense sweep across a much wider range, x=100 to
x=350, assuming nothing about roughly where the crack sits. It also
runs golden-section search at three brackets: one already centered
tightly on the crack, one moderately wide, and one as wide as the
dense sweep's own range.
Dense sweep (wide range 100-350, 126 evaluations): located crack position: x=218.74 (Experimental Dislocation's own x=218)
golden-section, bracket (178, 258): x=217.55, evaluations=12 golden-section, bracket (150, 300): x=217.25, evaluations=13 golden-section, bracket (100, 350): x=308.11, evaluations=14
The tight and moderate brackets land within 1px of the dense sweep's own answer. The wide bracket -- the one that assumes no prior knowledge of roughly where the crack is -- converges instead to a smaller, secondary peak_ratio bump far from the real crack, confidently and silently. Saved: discontinuity_localization_experimental.png
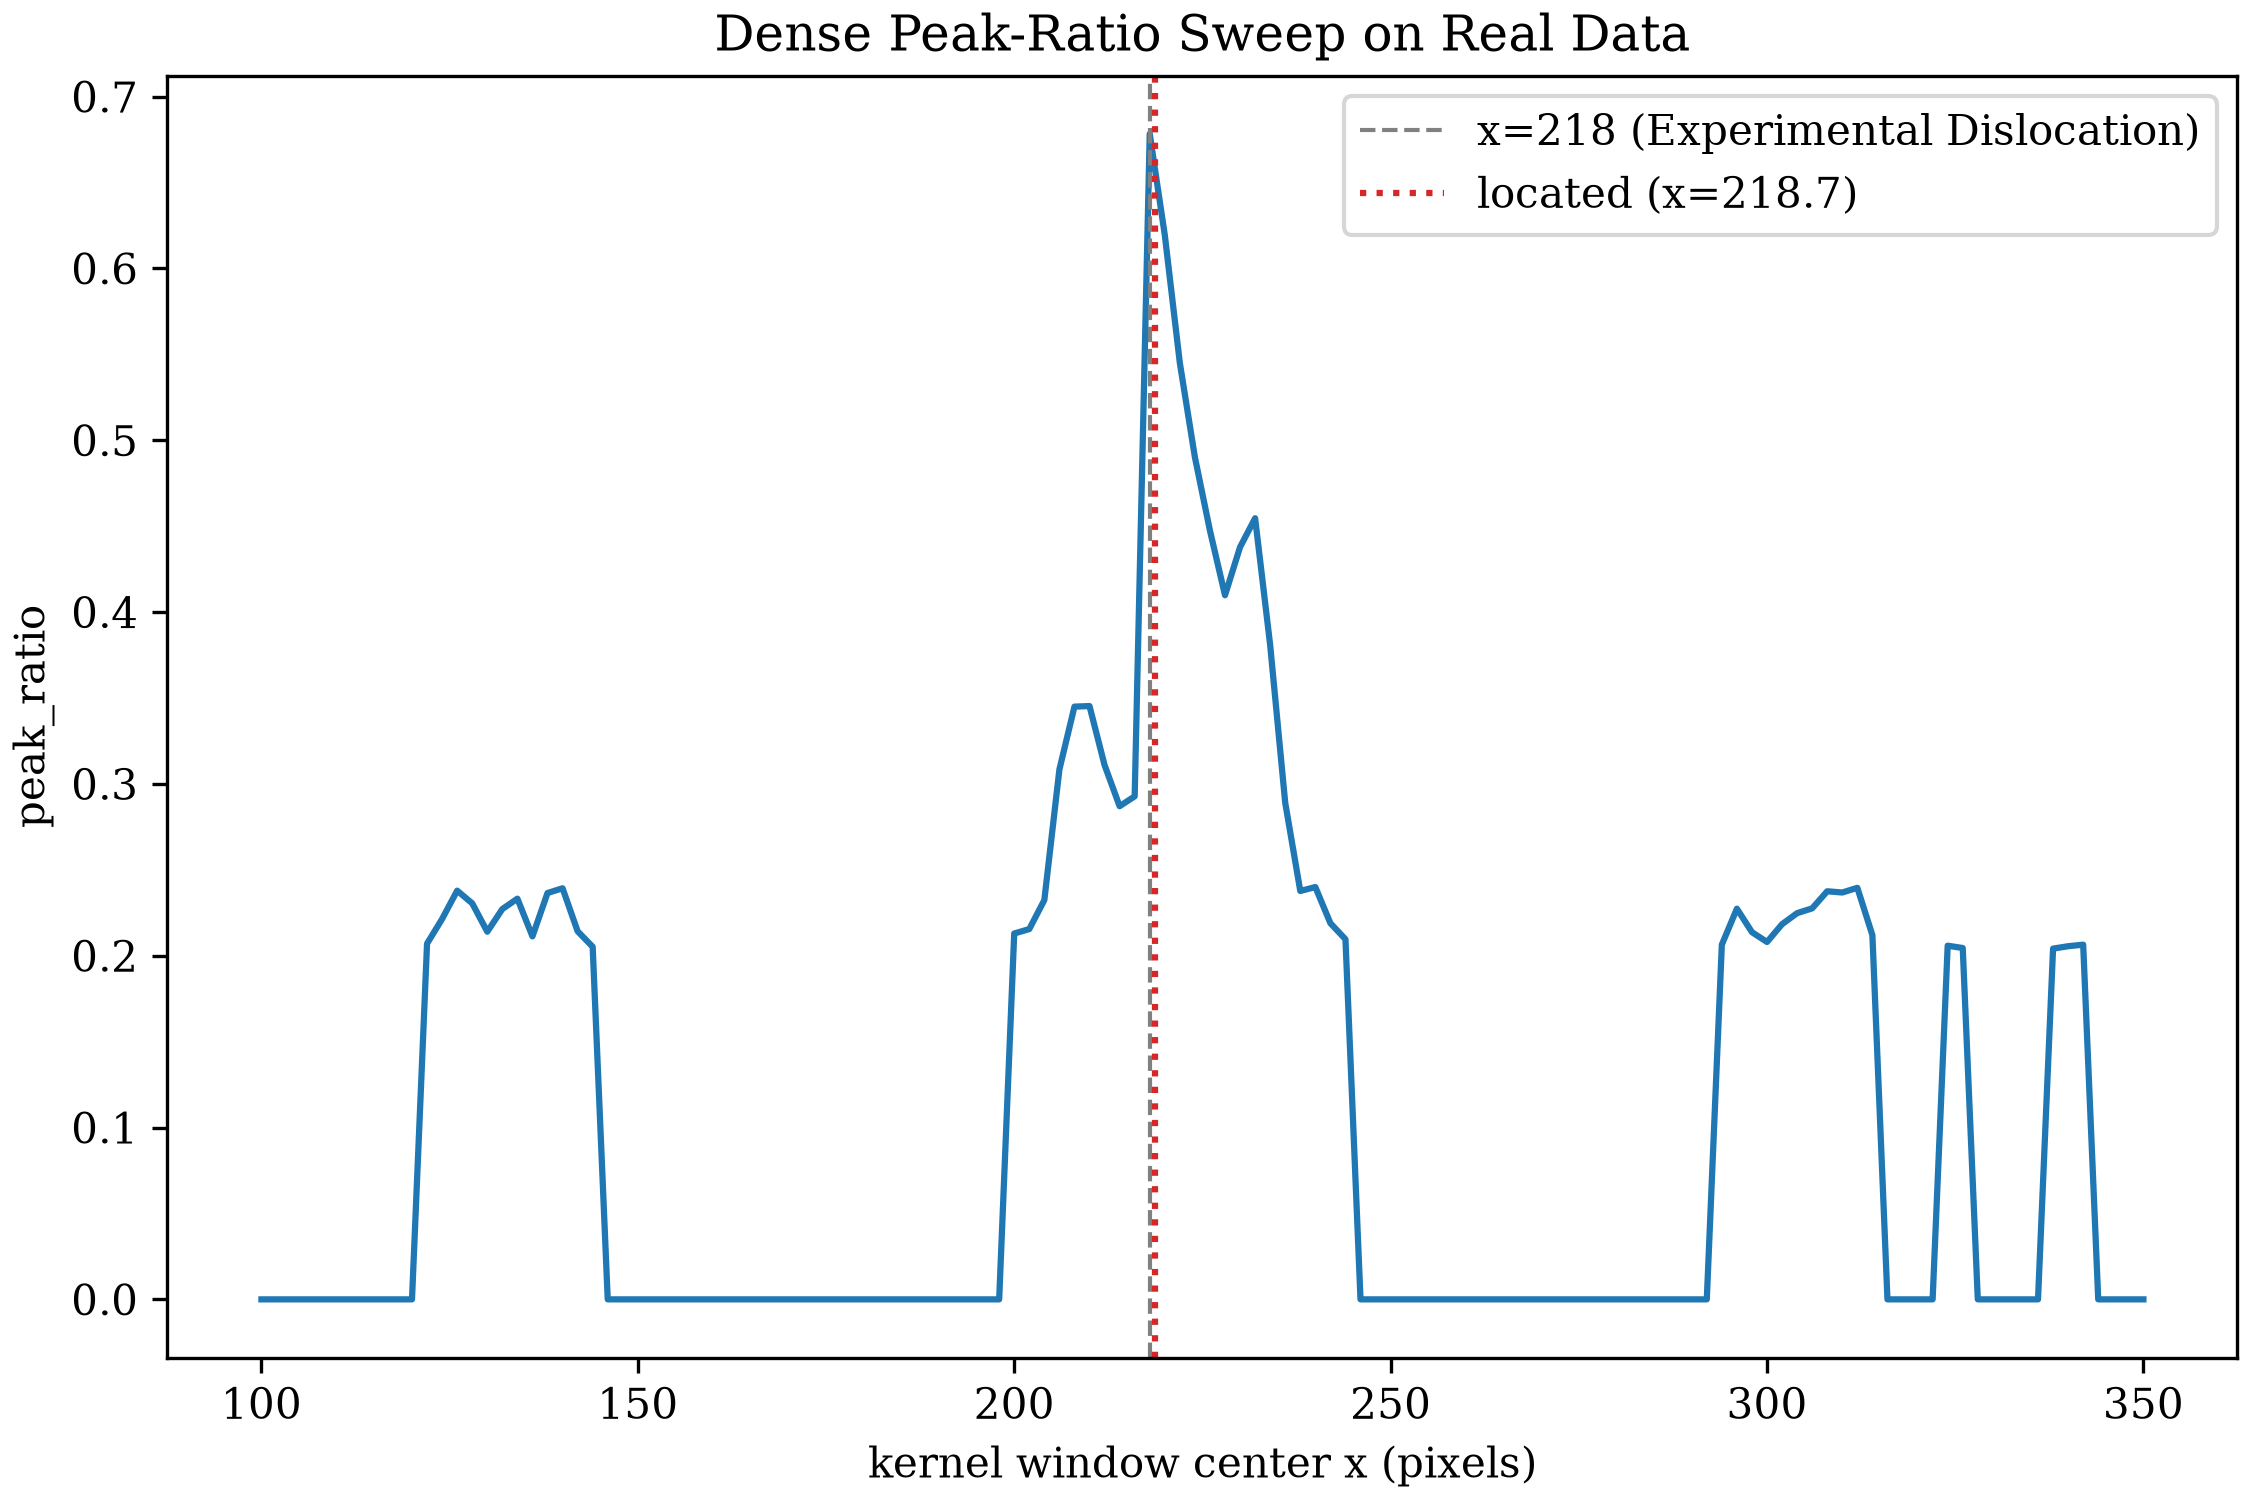
The dense sweep's global maximum lands within a pixel of the known
location, no matter how wide a range it searches. Golden-section search
does too, but only at the two brackets already narrowed toward the
crack. Given the full, uncommitted range, it converges instead to the
bump near x=308, over 90 pixels from the real crack, confidently and
silently. A fast local search only works once you already roughly know
where to look. That's most of the problem this page set out to solve
in the first place.
Declaring a Winner
The dense sweep, with subpixel parabolic refinement, ships as
dictk.discontinuity. It needs no
prior estimate of where a crack sits, its accuracy doesn't depend on
how wide a range it searches, and it holds up on both synthetic and
real data. The grid-anomaly baseline and golden-section search stay as
illustrations on this page, not library code: the baseline only ever
offers grid-spacing resolution, and golden-section search's speed comes
at the cost of needing the answer roughly in hand before it can find it.
| Approach | Evaluations (synthetic) | Localization Error (synthetic) | Real Data |
|---|---|---|---|
| Grid anomaly (baseline) | 11 | 5.0 px | weaker, noisier jump signal |
| Dense peak-ratio sweep (winner) | 101 | 0.2 px | 0.7 px from by-eye estimate |
| Golden-section search | 12 | 0.25 px | fails on a wide, honest bracket |
What This Still Doesn't Do
This locates a crossing along one already-chosen line, not a discontinuity anywhere in a 2D field. Something still has to decide where to sweep. And a located position still isn't consumed by anything: Path Forward's Heaviside DIC/XFEM item asked for detection and localization, not a finite-element formulation that acts on the result. That half stays open.
Continue to Path Forward for where this leaves it.
discontinuity_localization_baseline.py
"""A naive baseline: run standard single-peak DIC across the crack,
ignoring it, and look for a jump in the recovered displacement field
between neighboring grid points. Zero new library code -- entirely
`dictk.grid.generate`/`dictk.grid.locate`.
"""

import matplotlib.pyplot as plt
import numpy as np

import dictk
from dictk.grid import generate, locate
from dictk.image import PixelCoordinate, combine, crack_dislocation

plt.rcParams.update({"font.family": "serif", "mathtext.fontset": "cm"})

WIDTH = HEIGHT = 300
OFFSET = 4.0
KERNEL_MARGIN = 25
SEARCH_MARGIN = 45
Y = 150
SPACING = 10

speckle = dictk.rosta(width=WIDTH, height=HEIGHT, density=0.5)
photo = dictk.astronaut(width=WIDTH, height=HEIGHT)
reference_image = combine(a=speckle, b=photo)
current_image = crack_dislocation(arr=reference_image, offset=OFFSET)

points = generate(
    origin=PixelCoordinate(x=100, y=Y),
    count_x=11,
    count_y=1,
    spacing_x=SPACING,
    spacing_y=1,
)
found = locate(
    reference_image=reference_image,
    current_image=current_image,
    reference_points=points,
    kernel_margin_width=KERNEL_MARGIN,
    kernel_margin_height=KERNEL_MARGIN,
    search_margin_width=SEARCH_MARGIN,
    search_margin_height=SEARCH_MARGIN,
)
displacements = [f.y - p.y for f, p in zip(found, points)]
jumps = [
    abs(displacements[i + 1] - displacements[i]) for i in range(len(displacements) - 1)
]
jump_index = int(np.argmax(jumps))
crack_estimate = (points[jump_index].x + points[jump_index + 1].x) / 2

print(
    f"Grid spacing: {SPACING} px, {len(points)} points, {len(points)} correlation evaluations"
)
print(
    f"Largest displacement jump: {points[jump_index].x} -> {points[jump_index + 1].x}px"
)
print(f"Estimated crack position: x={crack_estimate}")
print(f"Error vs. known x=150: {abs(crack_estimate - 150)}px")
print()

fig, ax = plt.subplots(figsize=(6.0, 4.5), constrained_layout=True)
xs = [p.x for p in points]
ax.step(xs, displacements, where="mid", color="tab:blue", marker="o")
ax.axvline(150, color="gray", linestyle="--", linewidth=1, label="known crack (x=150)")
ax.axvline(
    crack_estimate,
    color="tab:red",
    linestyle=":",
    linewidth=1.5,
    label=f"estimated crack (x={crack_estimate:.0f})",
)
ax.set_xlabel("grid point x (pixels)")
ax.set_ylabel("recovered y-displacement (pixels)")
ax.set_title("Grid-Anomaly Baseline: Displacement Jump")
ax.legend(loc="center right")
fig.savefig("discontinuity_localization_baseline.png", dpi=300)
print("Saved: discontinuity_localization_baseline.png")
discontinuity_localization_sweep.py
"""Locate the crack with a dense peak-ratio sweep and subpixel parabolic
refinement, no ground truth required -- `dictk.discontinuity.sweep()`
and `.locate()`, generalizing Synthetic Dislocation's own known-offset
x-sweep into a real detector.
"""

import matplotlib.pyplot as plt

import dictk
from dictk.discontinuity import locate, sweep
from dictk.image import PixelCoordinate, combine, crack_dislocation

plt.rcParams.update({"font.family": "serif", "mathtext.fontset": "cm"})

WIDTH = HEIGHT = 300
OFFSET = 4.0
KERNEL_MARGIN = 25
SEARCH_MARGIN = 45
Y = 150
SAMPLES = 101

speckle = dictk.rosta(width=WIDTH, height=HEIGHT, density=0.5)
photo = dictk.astronaut(width=WIDTH, height=HEIGHT)
reference_image = combine(a=speckle, b=photo)
current_image = crack_dislocation(arr=reference_image, offset=OFFSET)

result = sweep(
    reference_image=reference_image,
    current_image=current_image,
    start=PixelCoordinate(x=100, y=Y),
    end=PixelCoordinate(x=200, y=Y),
    samples=SAMPLES,
    kernel_margin_width=KERNEL_MARGIN,
    kernel_margin_height=KERNEL_MARGIN,
    search_margin_width=SEARCH_MARGIN,
    search_margin_height=SEARCH_MARGIN,
)
xs = [p.x for p in result.positions]

found = locate(
    reference_image=reference_image,
    current_image=current_image,
    start=PixelCoordinate(x=100, y=Y),
    end=PixelCoordinate(x=200, y=Y),
    samples=SAMPLES,
    kernel_margin_width=KERNEL_MARGIN,
    kernel_margin_height=KERNEL_MARGIN,
    search_margin_width=SEARCH_MARGIN,
    search_margin_height=SEARCH_MARGIN,
)

print(f"Evaluations: {SAMPLES}")
print(f"Located crack position: x={found.x:.3f}")
print(f"Error vs. known x=150: {abs(found.x - 150):.3f}px")
print()

fig, ax = plt.subplots(figsize=(7.0, 5.0), constrained_layout=True)
ax.plot(xs, result.peak_ratios, color="tab:blue")
ax.axvline(150, color="gray", linestyle="--", linewidth=1, label="known crack (x=150)")
ax.axvline(
    found.x,
    color="tab:red",
    linestyle=":",
    linewidth=1.5,
    label=f"located crack (x={found.x:.1f})",
)
ax.set_xlabel("kernel window center x (pixels)")
ax.set_ylabel("peak_ratio")
ax.set_title("Dense Peak-Ratio Sweep")
ax.legend(loc="lower right")
fig.savefig("discontinuity_localization_sweep.png", dpi=300)
print("Saved: discontinuity_localization_sweep.png")
discontinuity_localization_bisection.py
"""A faster alternative: instead of sweeping every position, search for
`peak_ratio`'s maximum with golden-section search, which needs only
O(log n) evaluations if the metric is unimodal within the search
bracket. Not shipped as library code -- see Applying It to Real Data for
why.
"""

import matplotlib.pyplot as plt
import numpy as np

import dictk
from dictk.correlation import zncc
from dictk.discontinuity import locate as discontinuity_locate
from dictk.discontinuity import peak_ratio
from dictk.discontinuity import sweep as discontinuity_sweep
from dictk.grid import generate
from dictk.grid import locate as grid_locate
from dictk.image import PixelCoordinate, combine, crack_dislocation, subimage

plt.rcParams.update({"font.family": "serif", "mathtext.fontset": "cm"})

WIDTH = HEIGHT = 300
OFFSET = 4.0
KERNEL_MARGIN = 25
SEARCH_MARGIN = 45
Y = 150

speckle = dictk.rosta(width=WIDTH, height=HEIGHT, density=0.5)
photo = dictk.astronaut(width=WIDTH, height=HEIGHT)
reference_image = combine(a=speckle, b=photo)
current_image = crack_dislocation(arr=reference_image, offset=OFFSET)


def _evaluate(x):
    p0 = PixelCoordinate(x=int(round(x)), y=Y)
    kernel = subimage(
        image=reference_image,
        origin=PixelCoordinate(x=p0.x - KERNEL_MARGIN, y=p0.y - KERNEL_MARGIN),
        width=2 * KERNEL_MARGIN,
        height=2 * KERNEL_MARGIN,
    )
    search = subimage(
        image=current_image,
        origin=PixelCoordinate(x=p0.x - SEARCH_MARGIN, y=p0.y - SEARCH_MARGIN),
        width=2 * SEARCH_MARGIN,
        height=2 * SEARCH_MARGIN,
    )
    return peak_ratio(surface=zncc(kernel=kernel, search=search))


def golden_section_max(f, a, b, tol=1.0, max_iterations=50):
    """Golden-section search for a unimodal function's maximum on [a, b].

    Returns (x, evaluations, sampled_x) -- the found maximizer, how many
    times `f` was called, and every x actually sampled, in call order.
    """
    ratio = (5**0.5 - 1) / 2
    c = b - ratio * (b - a)
    d = a + ratio * (b - a)
    sampled = [c, d]
    fc, fd = f(c), f(d)
    for _ in range(max_iterations):
        if abs(b - a) <= tol:
            break
        if fc > fd:
            b, d, fd = d, c, fc
            c = b - ratio * (b - a)
            sampled.append(c)
            fc = f(c)
        else:
            a, c, fc = c, d, fd
            d = a + ratio * (b - a)
            sampled.append(d)
            fd = f(d)
    return (a + b) / 2, len(sampled), sampled


bisection_x, bisection_evaluations, bisection_samples = golden_section_max(
    _evaluate, 100, 200, tol=1.0
)
print(
    f"Golden-section result: x={bisection_x:.2f}, evaluations={bisection_evaluations}"
)
print(f"Error vs. known x=150: {abs(bisection_x - 150):.3f}px")
print()

# Full comparison, all three approaches, same synthetic dataset.
baseline_points = generate(
    origin=PixelCoordinate(x=100, y=Y), count_x=11, count_y=1, spacing_x=10, spacing_y=1
)
baseline_found = grid_locate(
    reference_image=reference_image,
    current_image=current_image,
    reference_points=baseline_points,
    kernel_margin_width=KERNEL_MARGIN,
    kernel_margin_height=KERNEL_MARGIN,
    search_margin_width=SEARCH_MARGIN,
    search_margin_height=SEARCH_MARGIN,
)
baseline_dy = [f.y - p.y for f, p in zip(baseline_found, baseline_points)]
baseline_jumps = [
    abs(baseline_dy[i + 1] - baseline_dy[i]) for i in range(len(baseline_dy) - 1)
]
baseline_i = int(np.argmax(baseline_jumps))
baseline_x = (baseline_points[baseline_i].x + baseline_points[baseline_i + 1].x) / 2

sweep_found = discontinuity_locate(
    reference_image=reference_image,
    current_image=current_image,
    start=PixelCoordinate(x=100, y=Y),
    end=PixelCoordinate(x=200, y=Y),
    samples=101,
    kernel_margin_width=KERNEL_MARGIN,
    kernel_margin_height=KERNEL_MARGIN,
    search_margin_width=SEARCH_MARGIN,
    search_margin_height=SEARCH_MARGIN,
)

print("| Approach | Evaluations | Localization Error (px) | Notes |")
print("|---|---|---|---|")
print(
    f"| Grid anomaly (baseline) | {len(baseline_points)} | "
    f"{abs(baseline_x - 150):.1f} | resolution capped at {10}px grid spacing |"
)
print(
    f"| Dense peak-ratio sweep (winner) | 101 | "
    f"{abs(sweep_found.x - 150):.3f} | robust to bracket width, see below |"
)
print(
    f"| Golden-section peak-ratio search | {bisection_evaluations} | "
    f"{abs(bisection_x - 150):.3f} | fast here, breaks on real data -- see below |"
)
print()

dense = discontinuity_sweep(
    reference_image=reference_image,
    current_image=current_image,
    start=PixelCoordinate(x=100, y=Y),
    end=PixelCoordinate(x=200, y=Y),
    samples=101,
    kernel_margin_width=KERNEL_MARGIN,
    kernel_margin_height=KERNEL_MARGIN,
    search_margin_width=SEARCH_MARGIN,
    search_margin_height=SEARCH_MARGIN,
)
fig, ax = plt.subplots(figsize=(7.0, 5.0), constrained_layout=True)
ax.plot(
    [p.x for p in dense.positions],
    dense.peak_ratios,
    color="tab:blue",
    linewidth=1,
    label="dense sweep (101 evaluations, for reference)",
)
ax.plot(
    bisection_samples,
    [_evaluate(x) for x in bisection_samples],
    marker="x",
    linestyle="none",
    color="tab:red",
    markersize=8,
    label=f"golden-section samples ({bisection_evaluations} evaluations)",
)
ax.axvline(150, color="gray", linestyle="--", linewidth=1)
ax.set_xlabel("kernel window center x (pixels)")
ax.set_ylabel("peak_ratio")
ax.set_title("Golden-Section Search vs. the Dense Sweep")
ax.legend(loc="lower right")
fig.savefig("discontinuity_localization_bisection.png", dpi=300)
print("Saved: discontinuity_localization_bisection.png")
discontinuity_localization_experimental.py
"""Apply the winning dense peak-ratio sweep, and the rejected
golden-section variant, to the real crack image pair Experimental
Dislocation already introduced. No exact ground truth exists here --
Experimental Dislocation's own straddling-window example already
centered on `x=218, y=186` by inspection, so that value is a visual
sanity check, not a precise target.
"""

import matplotlib.pyplot as plt

from dictk.correlation import zncc
from dictk.discontinuity import locate as discontinuity_locate
from dictk.discontinuity import peak_ratio
from dictk.discontinuity import sweep as discontinuity_sweep
from dictk.image import PixelCoordinate, read, subimage

plt.rcParams.update({"font.family": "serif", "mathtext.fontset": "cm"})

KERNEL_MARGIN = 25
SEARCH_MARGIN = 65
Y = 186

reference_image = read(path="experimental_dislocation_reference.tiff")
current_image = read(path="experimental_dislocation_current.tiff")


def _evaluate(x):
    p0 = PixelCoordinate(x=int(round(x)), y=Y)
    kernel = subimage(
        image=reference_image,
        origin=PixelCoordinate(x=p0.x - KERNEL_MARGIN, y=p0.y - KERNEL_MARGIN),
        width=2 * KERNEL_MARGIN,
        height=2 * KERNEL_MARGIN,
    )
    search = subimage(
        image=current_image,
        origin=PixelCoordinate(x=p0.x - SEARCH_MARGIN, y=p0.y - SEARCH_MARGIN),
        width=2 * SEARCH_MARGIN,
        height=2 * SEARCH_MARGIN,
    )
    return peak_ratio(surface=zncc(kernel=kernel, search=search))


def golden_section_max(f, a, b, tol=1.0, max_iterations=50):
    """Golden-section search for a unimodal function's maximum on [a, b]."""
    ratio = (5**0.5 - 1) / 2
    c = b - ratio * (b - a)
    d = a + ratio * (b - a)
    evaluations = 2
    fc, fd = f(c), f(d)
    for _ in range(max_iterations):
        if abs(b - a) <= tol:
            break
        if fc > fd:
            b, d, fd = d, c, fc
            c = b - ratio * (b - a)
            fc = f(c)
        else:
            a, c, fc = c, d, fd
            d = a + ratio * (b - a)
            fd = f(d)
        evaluations += 1
    return (a + b) / 2, evaluations


# The winner: a dense sweep over a wide, uncommitted range. No bracket
# to get right -- it visits every candidate position and reports the
# tallest peak_ratio wherever it actually is.
wide_start, wide_end = 100, 350
dense = discontinuity_sweep(
    reference_image=reference_image,
    current_image=current_image,
    start=PixelCoordinate(x=wide_start, y=Y),
    end=PixelCoordinate(x=wide_end, y=Y),
    samples=126,
    kernel_margin_width=KERNEL_MARGIN,
    kernel_margin_height=KERNEL_MARGIN,
    search_margin_width=SEARCH_MARGIN,
    search_margin_height=SEARCH_MARGIN,
)
found = discontinuity_locate(
    reference_image=reference_image,
    current_image=current_image,
    start=PixelCoordinate(x=wide_start, y=Y),
    end=PixelCoordinate(x=wide_end, y=Y),
    samples=126,
    kernel_margin_width=KERNEL_MARGIN,
    kernel_margin_height=KERNEL_MARGIN,
    search_margin_width=SEARCH_MARGIN,
    search_margin_height=SEARCH_MARGIN,
)
print(f"Dense sweep (wide range {wide_start}-{wide_end}, 126 evaluations):")
print(
    f"  located crack position: x={found.x:.2f} (Experimental Dislocation's own x=218)"
)
print()

# The rejected alternative, at three brackets: one already centered
# tightly on the crack, one moderately wide, one as wide as the dense
# sweep's own range -- the bracket a person without a rough answer
# already in hand would have to use.
for bracket in [(178, 258), (150, 300), (100, 350)]:
    x, evaluations = golden_section_max(_evaluate, *bracket, tol=1.0)
    print(f"  golden-section, bracket {bracket}: x={x:.2f}, evaluations={evaluations}")
print()
print(
    "The tight and moderate brackets land within 1px of the dense sweep's "
    "own answer. The wide bracket -- the one that assumes no prior "
    "knowledge of roughly where the crack is -- converges instead to a "
    "smaller, secondary peak_ratio bump far from the real crack, "
    "confidently and silently."
)

fig, ax = plt.subplots(figsize=(7.5, 5.0), constrained_layout=True)
ax.plot([p.x for p in dense.positions], dense.peak_ratios, color="tab:blue")
ax.axvline(
    218,
    color="gray",
    linestyle="--",
    linewidth=1,
    label="x=218 (Experimental Dislocation)",
)
ax.axvline(
    found.x,
    color="tab:red",
    linestyle=":",
    linewidth=1.5,
    label=f"located (x={found.x:.1f})",
)
ax.set_xlabel("kernel window center x (pixels)")
ax.set_ylabel("peak_ratio")
ax.set_title("Dense Peak-Ratio Sweep on Real Data")
ax.legend(loc="upper right")
fig.savefig("discontinuity_localization_experimental.png", dpi=300)
print("Saved: discontinuity_localization_experimental.png")
Path Forward
This page is a running log, not a tutorial. It records forward-looking notes as they come up — open questions, scale targets, directions worth exploring — dated as they're written. Nothing here is implemented yet unless the note says so.
2026-08-11
North star. DIC at real finite-element-mesh scale eventually means at least a billion correlations. Realistically, tens of billions. The working assumption is that this stays under a trillion — that's the ceiling to design for, not a target to reach.
Four directions worth exploring, in the order we'll likely take them:
- GPU implementations. Parallelization only covers CPU-bound threads and processes so far. GPU work is still explicitly deferred until a documented CPU bottleneck exists (see the parallelism roadmap referenced there) — this note doesn't change that. It's on the list for when that bottleneck shows up.
- Dynamic search-window sizing. Every worked example so far uses a fixed, generously-sized search area per point. Parallelization's own measurements found that per-correlation size, not point count alone, is the dominant cost lever. A search window only as large as it needs to be — sized from a prior displacement estimate rather than a fixed worst-case margin — shrinks that per-correlation cost directly, for every point in a mesh, not just the parallelizable part of the problem.
- Pure rotation. Rigid Body Motion and
the polar decomposition (,
see Continuum Mechanics)
already separate rotation from stretch: a pure rotation carries zero
strain by construction. Two things worth testing empirically, not
just assuming from the closed-form math: how large a rigid-body
rotation angle
dictk's own correlation-based tracking can actually recover before it breaks down — a large enough rotation distorts a kernel's own content beyond what a translation-only search can still match — and confirming a correctly-tracked pure rotation reports zero strain end to end, not just in theory. - Synthetic dataset comparison to XCorrel and VIC-2D. Run the same
synthetic datasets this book already uses through both tools, and
compare their reported displacements and strain against
dictk's own. A synthetic dataset has a known, exact ground truth — the same trick every worked example in this book already relies on — so this is a direct, numeric check against established DIC software, not just a qualitative one.
A practical constraint to design around: real DIC data typically uses kernel sizes from about 35x35 pixels on the small end up to about 50x50 pixels on the large end. Every benchmark or worked example aimed at "realistic" DIC scale should stay inside that range, not the 40-pixel figure this book's own teaching examples happen to use.
Heaviside DIC and XFEM. Every correlation technique this book covers assumes a smooth displacement field. Real specimens don't always deform smoothly — a crack or a material interface can produce a genuine discontinuity, a jump rather than a gradient. Image Transformation already generates a synthetic example of exactly that jump, and names the reason: standard DIC can't capture it, and cases like it motivate the Heaviside finite-element formulation. XFEM handles this on the finite element side by enriching the basis with Heaviside step functions, so the mesh doesn't need to conform to the crack. The DIC-side analogue — enriching the correlation itself to detect and locate a discontinuity, not just generating test images that contain one — is worth exploring. Not scoped yet.
2026-08-14
Re-running The First Sweep after the centered-padding fix: checked,
not automatically fixed. Recoverable Displacement
Range's own
opening sweep sizes search_margin_width generously for every
percentage tested — always larger than the true displacement — so it
was never hitting the asymmetric-padding bug that page's fix
addresses. Re-ran it against the fixed locate() to check directly,
rather than assume: the collapse is identical to before the fix —
12/12, 12/12, 10/12, 6/12, 1/12, 1/12, 0/12, 0/12 for
. The real cause is still the
interpolation confound that page already
names:
stretch's own bilinear interpolation subtly blurs kernel-surrounding
texture even where a point's center pixel lands on an exact integer,
producing near-miss failures — not the wraparound cliff the fix
resolved. Confirms the Postponed subpixel-accuracy item below is still
the right next step here, not something this fix already covered.
Postponed
Noted, not being pursued right now:
- Heaviside DIC and XFEM: DIC-detection half resolved, FEA/XFEM
half still open. Discontinuity
Localization closed the half this
item originally asked for:
dictk.discontinuity.locatefinds a straddling window's two-peak signature on its own, on both synthetic and real data, no human-centered window required. What's still not started: consuming a located discontinuity in an actual Heaviside-enriched finite-element formulation. That's XFEM's own side of this, untouched by anything above. grid.locate()windowing demo.windowinghas only ever been demonstrated directly ondictk.correlation.phase_correlation(see Correlation Visualization). Everygrid.locate()call across the book so far (Multi-Point Motion, Simple Stretch, Recoverable Displacement Range, Pure Rotation, Parallelization) leaveswindowingat its defaultNone— the one parameter ofgrid.locate's own signature with no live worked example yet.
2026-08-18
Pure Rotation: The First Sweep. New page, Pure
Rotation, starts checking direction 3 above
empirically. Its First Sweep reuses Point
Grid's 12-point grid and sweeps
rotate's angle, sizing search_margin generously at every step so
window size can't be the limiting factor — the same approach
Recoverable Displacement
Range used.
Matching collapses even faster than that page's stretch sweep did: well
under half the points still match by 2 degrees, none by 8 degrees. The
likely cause, already named in this page's own direction-3 note above,
isn't confirmed yet — a large enough rotation turns a kernel's own
content around a point, not just moves it, and a translation-only
search can't follow that. Checking that hypothesis directly is the next
step here, not started yet.
Pure Rotation: hypothesis confirmed. Same page, new Confirming the
Content-Rotation
Hypothesis
section. Two direct checks: handing locate the exact true search
center instead of a generous margin barely changes the collapse,
ruling out search mechanics; and a plain zncc similarity score
between the reference kernel and the true-aligned current-image patch
(no search at all) falls off steeply with angle, confirming the real
cause is content, not search. One thing this doesn't separate out yet:
rotate shares stretch's bilinear interpolation, and Recoverable
Displacement
Range
already found interpolation blur alone can look similar — genuine
geometric content rotation and interpolation blur are likely both
compounding here. Telling them apart is the next open step, not
started.
2026-08-20
Postponed subpixel accuracy item, resolved. Simple Stretch
Revisited found the
concrete trigger this Postponed item's own wording anticipated: at
factor_x = 1.02, only points whose x is a multiple of 50 land on
an integer pixel in the deformed configuration. A denser grid mostly
doesn't. New Subpixel
Accuracy page: dictk.translation.locate_subpixel
and dictk.grid.locate_subpixel, exposing
phase_cross_correlation's own upsample_factor — separate functions
from locate/grid.locate, not a parameter added to them, returning
a new dictk.image.SubpixelCoordinate (float x/y) instead of
PixelCoordinate. Measured directly against VIC-2D's own 2862-point
grid: upsample_factor doesn't make locate's truncated integer
answer more often correct (the true target usually isn't an integer at
that density, so no refinement changes that) — but it substantially
improves how close the tracked position lands to the true, generally
fractional, target (mean absolute error 0.26px at upsample_factor=1,
down to 0.09px at 10). Parallelization (9) gains this as its first
child, 9.1; a second child, 9.2 High Point Density, picking the same
subpixel tooling up at real density, is the planned next step, not
started yet.
2026-08-24
9.2 High Point Density, shipped. New page, High Point
Density, closes the 9.1/9.2 pair under
Parallelization. It pushes grid.locate_subpixel
to VIC-2D's own point density: 2862 points, 5px spacing, 2756 elements.
No new library code — it composes entirely from already-shipped
functions, the same way Simple Stretch
Revisited did.
A real finding came out of it, verified before writing anything up. The strain field isn't clean at this density. Mean E11 still tracks the true value closely (0.0199 vs. 0.0198), but individual elements scatter widely (std 0.0155, range -0.016 to 0.077). A live 4-point spacing sweep (5/10/20/40px) confirmed the mechanism directly: strain noise scales with displacement-noise divided by element size, so the same small subpixel tracking residual gets amplified more at smaller spacing. Std shrinks monotonically across the sweep (0.0154/0.0125/0.0099/0.0032). The page names VIC-2D's own strain-window averaging as the standard remedy but doesn't implement it — that stays open.
2026-08-25
High Point Density retuned to VIC-2D's real geometry, plus a
quantization finding. High Point Density's
tracking call used a much larger kernel/search area than VIC-2D's own
25 x 25 px subset — leftover from earlier pages, never tuned to
match. kernel_margin = 12 (the closest whole-pixel match) was tried
first and rejected: checked directly against known true positions, it
produced real multi-pixel mismatches at a handful of points, not just
subpixel noise. kernel_margin = 13 (26 x 26 px) tracks cleanly,
zero mismatches across all 2862 points; search_margin = 25 gives
generous headroom.
A second, unplanned finding came out of building the page's new
strain histogram (the dictk-side counterpart to Verification
Against VIC-2D's
own VIC-2D histogram). At upsample_factor = 10 — Subpixel Accuracy's
own choice — the histogram wasn't a smooth spread; it separated into
sharp spikes exactly 20000 microstrain apart. Checked directly: 0.1px
(the displacement quantization step at upsample_factor = 10) divided
by this mesh's own 5px element spacing is exactly 0.02, i.e. 20000
microstrain — the artifact was upsample_factor itself, invisible in
Subpixel Accuracy's own raw-displacement measurement but amplified into
visible banding once divided by a small element size to get strain.
upsample_factor = 100 removes the banding; mean and std barely move
(std 17776 → 16531 microstrain), confirming the real spread was already
there and only its blocky shape was artificial.
With both fixed, the real numbers: mean = 20464.3 microstrain
vs. the analytical 19802.6 (3.3% off, worse than VIC-2D's own 0.4%);
std 16531 microstrain; range -16446 to 106134 microstrain, over 21x
VIC-2D's own roughly 5800-microstrain-wide spread. The page's own
closing analysis ties this to kernel size directly: matching VIC-2D's
small subset, instead of earlier pages' generously oversized kernels,
trades away some of the noise-averaging a bigger kernel provides — part
of dictk's own extra spread here is the expected cost of matching
VIC-2D's geometry, not a dictk-specific shortcoming.
A new figure places the two fields side by side, both forced onto
VIC-2D's own fixed colorbar (17560-22360 microstrain) — not an
approximate rainbow,
but VIC-2D's own particular 16-band palette, sampled pixel-by-pixel
from its own legend image and rebuilt as a matplotlib ListedColormap.
Forced onto that same narrow range, only 9.5% of dictk's own 11024
Gauss points land inside it; 52.9% clip to the floor, 37.7% to the
ceiling — visual, not just numeric, confirmation of how much wider
dictk's own spread is. The figure's own figsize is tuned
((6.9, 6.0)) to match VIC-2D's screenshot's own aspect ratio, so the
two panels align in height in the page's side-by-side flex layout.
element_strain_plot
gained four new keyword-only parameters this session, each
default-preserving for every existing caller: dot_size (default
150), vmin/vmax (fixed color-scale bounds, for the VIC-2D
comparison above), show_mesh_lines (default True), and marker
(default "o") — cmap also widened to accept a Colormap instance,
not just a name, for the extracted VIC-2D palette. All three of this
page's dense figures now use dot_size=6, marker="s", and
show_mesh_lines=False: square markers tile a regular grid edge to
edge with no gaps, where circles — even sized to just touch — leave
small diamond-shaped gaps at their own tangent points; mesh lines add
clutter without information at this density. 348 tests (343 + 5 new).
2026-08-26
High Point Density's own
closing gap — how dictk's tracking time scales as point count grows,
across sequential, threaded, and multi-process execution — is answered
by a new page, Timing at
Scale (Parallelization's new
9.3 child). It set out looking for this M1 Pro machine's genuine RAM
ceiling: grow a pure-rosta reference image (no astronaut, avoiding
any bicubic-upsampling artifact) along a geometric ladder, tracking the
real grid.locate_subpixel pipeline at each size until 32GB of RAM ran
out.
It never did. sysctl vm.swapusage was checked directly throughout the
entire multi-hour run and never once reported nonzero swap use, even as
peak RSS climbed to 11.5GB at the largest tier reached (10204px,
3,229,209 points). What actually stopped the ladder was this script's
own 1800-second (30-minute) per-tier timeout — a genuine compute-time wall, found
by raising that timeout once (240s → 1800s, after the first pass showed
processes and sequential both dying to it well before any memory
pressure) and hitting it again anyway. threads reached the furthest
(996,004 points, 861.5s) before also timing out at the next tier.
processes died earliest (1750px) for an unrelated, real reason: its
own ProcessPoolExecutor.map() re-pickles dictk.grid.locate's bound
reference_image/current_image once per task, not once per worker —
confirmed directly in source, and directly observed as ~50% single-core
utilization on a retry, not eight processes computing in parallel.
This documents, with real numbers, the "documented CPU bottleneck" this
page's own GPU direction (below) has been gated on since it was first
written: reaching a million tracked points took threads 14.4 minutes
on 10 cores; a real problem at this page's own north-star scale (a
billion correlations) extrapolates to weeks on this same hardware. 348
tests (unchanged — docs-only, plus a new standalone benchmark script,
same precedent as parallelization_bench.py).
2026-09-01
9.4 Parallelism with PyTorch, shipped. New page,
Parallelism with PyTorch, Parallelization's
fourth child. It reruns Timing at Scale's own
ladder — same image sizes, same point grids, same 26x26 kernel, same
per-size search areas, same machine — on a batched PyTorch correlation
instead of one grid.locate_subpixel call per point. Docs-only plus a
standalone benchmark script, matching 9.3's own precedent. 348 tests
unchanged. pyproject.toml deliberately untouched: CI runs
uv sync --all-extras, so a torch extra would install PyTorch on
every CI run for a script CI never executes.
This continues work Andrew Polonsky and Chad Hovey started in the
private hdic codebase in 2025, and the page attributes it directly.
That work established the grouped-conv2d batching trick (stack N
search areas as channels, N kernels as N groups, groups=N so kernel
i sees window i only), measured it on a Windows CUDA machine, and
recorded the decision "torch implementation, then CUDA implementation"
on 2025-09-23. It left three gaps. 9.4 closes two: it runs on Apple
silicon, which hdic's own correlation module refused to do via a hard
RuntimeError("...does not run on macOS") that was simply false; and it
refines peaks to subpixel, which that implementation never did. The FFT
gap stays open, and is now the named next step.
A real prerequisite fix to 9.3. Timing at
Scale stated kernel_margin=13
and said search_margin varies per tier, but never gave pixel
dimensions. Adding them surfaced something that page never said: the
kernel is fixed at 26x26 at every tier, but the search area grows from
48x48 to 420x420, because factor_x=1.02 displaces a far edge further
in a bigger image. Search pixels therefore grow 76x across the ladder,
so 9.3's cost curve is not a pure point-count curve — it measures point
count and per-correlation size growing together. Doesn't invalidate any
9.3 finding (all three executors saw identical geometry), but it
explains part of the slope, and 9.4 could not describe its own tensor
shapes without it.
The headline result, and the caveat under it. The Apple GPU (MPS,
Metal Performance Shaders) wins at every size. It completed 10204px —
3,229,209 points in 2,334.7s — which 9.3's threads attempted and could
not finish. At the largest size both pages measured (5669px, 996,004
points) it runs 3.4x faster than threads: 3,884 points/s against
1,156, which turns 9.3's own "roughly 1.4 weeks for a billion
correlations" into roughly 3 days. Real, and not enough — a billion is
Path Forward's entry-level target, not its ceiling.
The speedup is not constant, and the shape of it is the finding. It climbs to 15.7x at 29,584 points, then falls to 3.4x at 996,004. Point count only ever increased, so batching can't explain the decline. The growing search area can, and the CPU column proves it directly.
Polonsky's cusp, located. His 2025-04-15 email said the team was
"right on the cusp of whether or not doing the FFT for cross-correlation
will be faster than brute force sliding dot product," and never resolved
it. 9.4 resolves it, because torch CPU and 9.3's threads run on the
same ten cores and differ only in algorithm. At a 74x74 search area,
torch CPU wins 7.8s to 16.9s. At 102x102 they tie, 53.4s to 58.6s. At
156x156 the FFT wins 215.2s to 512.7s. On this machine, at a 26x26
kernel, the cusp sits near a 100x100 pixel search area. Below it,
brute force wins; above it, the FFT does.
Which reframes 9.4's own GPU result: the GPU is running the losing
algorithm at these search areas and still beats ten CPU cores. Nobody
has yet combined the better hardware with the better algorithm. That
combination — a batched torch.fft phase correlation, the same
algorithm 9.1-9.3 already use, on the devices 9.4 already measures — is
the obvious next step and is not started.
Subpixel came out better than expected. A three-point parabolic fit
on the correlation surface conv2d already returns gives 0.0369px mean
absolute error against analytical truth, against
grid.locate_subpixel's own 0.0925px at upsample_factor=100 on the
same 2,809 points. 2.5x more accurate, for a small fraction of the
correlation's cost. Peak locking is present but mild (fractional-part
bins 330/338/258/219/280/265/210/257/313/339 against a flat 280).
Integer positions agree with grid.locate on 98.7% of points, and every
one of the 37 disagreements has a true fractional part between 0.460 and
0.560 — the half-pixel boundary where rounding is genuinely ambiguous,
not an error. MPS matched CPU digit for digit; float32 cost nothing
measurable.
A prediction the measurement contradicted. 9.4 retired 9.3's 1800-second wall clock and replaced it with a caught out-of-memory error as the primary stop, reasoning that search areas are chunkable but the two resident images are not, so the unchunkable part would eventually fail. It never did. Both devices stopped on the secondary rule instead — a predicted-cost gate, extrapolating each size from the previous size's measured rate. At the largest size attempted, the two images occupied 0.83GB of Metal's 26.8GB budget, about 3%; peak host RSS reached 13.9GB of 32GB. Same conclusion 9.3 reached, for the same reason: compute time is the wall, memory is not. The OOM arithmetic still holds at around 59508px; this ladder just never gets there, because that size's arithmetic outruns any reasonable wait.
Two bugs found by testing rather than assuming. Forcing an
out-of-memory on purpose revealed that Metal reports it two different
ways, and only one says "out of memory" — a single tensor past Metal's
per-buffer ceiling raises Invalid buffer size: 3013.73 GiB instead.
Trusting the first message would have turned a real memory finding into
an unexplained crash. Separately, a first version of the benchmark
re-uploaded both full images to the device once per chunk rather than
once per size (26 redundant 40MB uploads at 3149px), which inflated
measured extraction cost; partial results were discarded and the ladder
re-run after the fix. Both are recorded in the script's own docstrings.
2026-09-06
Discontinuities (10), Synthetic Dislocation (10.1), and Experimental Dislocation (10.2), shipped. New chapter. First empirical evidence toward the Postponed "Heaviside DIC and XFEM" item above. Not a resolution of it: a characterization of what the symptom looks like.
The finding: a straddling window's correlation surface shows two
comparably-tall peaks, not one.
Image Transformation's crack
shifts its left half +4px and its right half -4px, and no single
displacement answer can represent both at once. On synthetic data
(astronaut0, offset=4, kernel_margin=25, search_margin=45), ZNCC
and phase correlation (FFT) land on the exact same two peaks: y=16 and
y=24. Both straddle the window's own zero-shift center (y=20) by
exactly ∓4 pixels, the same 4-pixel offset applied, so their
separation, 8 pixels, is exactly twice the offset.
Swept offset 1-32 pixels: separation = 2 x offset held at every offset from 2 to 32, for both criteria. The only miss came at offset=1, where ZNCC's two peaks sit one pixel apart, too close for an integer-pixel surface to resolve as two separate local maxima; phase correlation still resolved it there. Not a fluke at one lucky parameter choice: the relationship holds across a 32x range.
Real data (a real experimental crack image pair, copied in
unmodified): the signature survives, noisier. At (x=218, y=186),
kernel_margin=25, search_margin=65, ZNCC's surface shows three local
maxima along its peak column (heights 0.09, 0.19, 0.28). The two
tallest, 22 pixels apart, both clearly exceed the third and the general
noise floor. Phase correlation on the same window, though, is speckled
with noise across its entire extent. It shows no clean isolated peak,
values an order of magnitude smaller, and its single reported maximum
lands at a different position than ZNCC's own tallest peak. The two
criteria agreed exactly on synthetic data and don't here: real,
non-periodic texture is exactly the case
phase_correlation's
own docstring already warns is noisier than a spatial-domain criterion.
ZNCC is the criterion worth trusting for this diagnostic on real data.
Still not started: an algorithm that finds this signature on its own, rather than a person centering a window on a crack they already know is there. That's what "enriching the correlation itself to detect and locate a discontinuity" above still means. 348 tests, unchanged. This shipped as new book pages and two harvested image assets, not new library code.
Discontinuity Localization (10.3), shipped: the DIC-detection half of
"Heaviside DIC and XFEM" is resolved. Three approaches, compared on
both the synthetic pair above and Experimental Dislocation's real crack
image pair. A grid-anomaly baseline (standard grid.locate, no new
code): 11 evaluations, 5-pixel error on synthetic data, capped at half
the grid spacing by construction. A dense peak-ratio sweep with
subpixel parabolic refinement: 101 evaluations, 0.2-pixel error on
synthetic data, 0.7 pixels from Experimental Dislocation's own by-eye
x=218 on real data. Golden-section search on the same metric: 12
evaluations, 0.25-pixel error on synthetic data, competitive with the
dense sweep. A wide, honest real-data bracket breaks it, though: with
no prior estimate of where the crack sits, it converges instead to a
smaller, secondary peak 90 pixels from the real crack, confidently and
silently.
The dense sweep wins and ships. New module dictk.discontinuity:
peak_ratio (a correlation surface's second-tallest peak divided by its
tallest: near 1.0 for a straddling window, 0.0 for a clean one),
sweep (evaluate peak_ratio along a line), and locate (the same
sweep, refined to subpixel precision). The baseline and golden-section
search stay as page illustrations, not library code. That's the same
try-and-reject pattern earlier chapters have used for a rejected
kernel_margin value or a reverted median filter. 371 tests
(348 + 23).
Still not resolved: a located discontinuity still isn't consumed by anything. The postponed item below is split to reflect exactly that.
Contributing to dictk
dictk is developed on GitHub using
Git for version control. Git is the tool that tracks
changes to the source on your own computer; GitHub is the hosting service
that holds the canonical copy of the repository, tracks issues and pull
requests, and runs the CI/CD pipeline described below.
Cloning vs. forking
Contributors can get a working copy of dictk by either cloning or forking
the repository.
| Cloning | Forking |
|---|---|
| A Git action: it creates a copy of the repository on your own computer. | A GitHub action: it creates a personal copy of the entire project under your own GitHub account. |
| For authorized collaborators who can push changes directly to the main project. | For external contributors to make changes without affecting the original repository, then submit a pull request to share those changes. |
Getting the source code
Collaborators should clone directly:
git clone git@github.com:hovey/dictk.git
cd dictk
External contributors should first fork the repository to their own GitHub account, then clone their fork locally.
Installation
Using uv (recommended)
Install uv if you don't already have it:
# macOS / Linux
curl -LsSf https://astral.sh/uv/install.sh | sh

# or via Homebrew
brew install uv
Then, from the repository root:
uv sync --all-extras --dev
This creates a .venv and installs dictk plus its dev dependencies
(pytest, pytest-cov, ruff). Run commands inside that environment with
the uv run prefix, e.g. uv run pytest.
Using venv and pip (alternative)
python3 -m venv .venv

source .venv/bin/activate       # bash/zsh
source .venv/bin/activate.fish  # fish
.venv\Scripts\activate          # Windows

pip install -e ".[dev]"
Git workflow
Branching model
main and dev are both long-lived: dev is branched from main, and
main only moves forward via merges from dev (each push to main is a
potential release — see "Releasing" below). Actual development happens one
level further out, on dev-feature, a branch cut from dev.
main          ●───────────────●───────────  (releases only, tagged)
                   \                \
dev           ●─────●───●───●───●────●────  (integration branch)
               \       \         \
dev-feature     ●───●   ●─●───●   ●──●      (your work)
dev-feature above is a placeholder — name each branch dev-<short-description>
so its purpose is clear at a glance. For example:
dev-cicd— CI/CD pipeline or workflow-file changesdev-algorithm-refactor— refactoring an existing algorithm or moduledev-imaging— new imaging transformations/workflowsdev-docs— documentation-only updates
Starting a dev-feature branch
git checkout dev
git pull origin dev
git checkout -b dev-feature
Keeping your dev-feature branch up to date with dev
Before opening a PR, or periodically during long-lived work, bring in dev's
latest changes.
Option 1: Merge (safer, keeps history of both branches)
git checkout dev
git pull origin dev
git checkout dev-feature
git merge dev
If there are conflicts, git will tell you which files — resolve them, then:
git add <resolved-files>
git commit
Option 2: Rebase (cleaner, linear history)
git checkout dev
git pull origin dev
git checkout dev-feature
git rebase dev
If conflicts come up during rebase, fix them then run git add <files>
followed by git rebase --continue (repeat until done). To bail out at any
point: git rebase --abort.
Pushing after either approach — if dev-feature was already pushed and
has commits others might be using:
- After a merge:
git push origin dev-feature - After a rebase:
git push origin dev-feature --force-with-lease(rebase rewrites history, so you need a force push —--force-with-leaseis safer than--forcesince it won't overwrite someone else's pushed work)
Which to pick
- Use merge if the branch is shared with others or you want a clear record of when
dev's changes came in - Use rebase if it's mostly just your own branch and you want a clean, linear commit history without merge bubbles.
Tip — before doing either, it's worth running:
git log dev-feature..dev --oneline
to preview what's coming in, so conflicts aren't a total surprise.
Development workflow
Developers work locally and periodically push to their dev-<feature>
branch. Before pushing changes, developers should check code quality
locally rather than solely relying on CI to catch problems. This means
running tests, linting, format checking (ruff), code coverage, and
confirming that the documentation (mdBook + pdoc) builds locally. Catching
issues locally is faster than waiting on a CI run, and it keeps the CI
pipeline green for everyone else.
Running tests
uv run pytest
With coverage (matches what CI runs):
uv run pytest --cov=src/dictk --cov-report=xml --cov-report=html
Coverage HTML report is written to htmlcov/index.html.
Linting and formatting
ruff handles both formatting and linting.
uv run ruff format          # auto-format
uv run ruff format --check  # verify formatting without changing files (CI runs this)
uv run ruff check           # lint
pyproject.toml has no [tool.ruff.lint] section, so ruff check runs
ruff's bare default rule selection — E4/E7/E9 (pycodestyle basics)
plus F (pyflakes). This is deliberate, not an oversight. ruff check is a
hard CI gate; broader rule sets (D docstring-style, ANN
type-annotation-completeness, S security, and the rest) risk fighting
conventions already established elsewhere in this codebase (e.g. the
Google-style docstrings pdoc --docformat google depends on), or simply
duplicating ground pylint already
covers informationally, without ruff's same all-or-nothing gating risk.
Building the docs
Documentation is an mdBook under
docs/userguide/, with two preprocessors enabled:
mdbook-cmdrun, so pages can
embed live, always-accurate command output (see the "Image Generation"
page for an example) instead of pasted-by-hand output, and
mdbook-katex, so pages can
include $$...$$ LaTeX math blocks (see the "Single Point Motion" page).
Neither is a Python dependency:
# mdbook must be pinned to 0.4.52: mdbook-cmdrun and mdbook-katex's 0.9.x
# line both depend on the mdbook crate's 0.4.x preprocessor JSON schema,
# which changed in mdbook 0.5 and broke compatibility
# (https://github.com/FauconFan/mdbook-cmdrun/issues/22, open as of this
# writing; mdbook-katex made the same jump at its own 0.10.0). Do not
# `brew install mdbook` or `cargo install mdbook`/`mdbook-katex` without a
# --version pin, or the build will fail with "Unable to parse the input".
cargo install mdbook --version 0.4.52
cargo install mdbook-cmdrun
cargo install mdbook-katex --version 0.9.4
If you already have a newer mdbook from Homebrew or elsewhere on your
PATH, make sure ~/.cargo/bin comes first (or check mdbook --version
reports 0.4.52 before building).
book.toml lives at the repo root (not inside docs/userguide/), with
src = "docs/userguide/src" and build-dir = "docs/userguide/book", so
both commands below run from the repo root:
uv run mdbook build           # build once, output in docs/userguide/book/
uv run mdbook serve --open    # live preview at http://localhost:3000
uv run puts dictk's own CLI on PATH for the build, since some
cmdrun directives invoke dictk directly.
Building the API docs
Python API reference docs (function signatures, docstrings) are generated from source with pdoc, a dev dependency:
uv run pdoc dictk -o docs/api --docformat google --math -t docs/pdoc_templates   # build once, output in docs/api/
uv run pdoc dictk --docformat google --math -t docs/pdoc_templates              # live preview, serves on localhost
--docformat google matters: pdoc defaults to restructuredtext, which
doesn't recognize this codebase's Google-style Args:/Returns:/Raises:
docstring sections — without it, an Args: section renders as one flat
paragraph instead of a proper bulleted list.
--math matters too: several docstrings (dictk.correlation's CC/NCC/
ZCC/ZNCC/phase-correlation formulas) use $...$/$$...$$ LaTeX — without
it, no MathJax gets included and the raw LaTeX source shows up literally
instead of being rendered. A separate trap in the same area: pdoc treats
a docstring as Markdown before MathJax ever sees it, and Markdown's own
backslash-escape rule silently strips the backslash off LaTeX commands
like \! (a backslash followed by ASCII punctuation). Avoid that pattern
in docstring math, or double the backslash (\\!).
No submodules need listing on the command line — bare pdoc dictk
discovers all of them, and also builds the "Submodules" links on the
dictk.html landing page, because every one of them
(image/translation/correlation/grid/cli/rosta) is named
directly in dictk/__init__.py's own __all__, alongside the
individual functions (astronaut, checkerboard, rosta,
__version__) it re-exports:
pdoc's __all__ handling
treats a name in __all__ that isn't already a bound attribute as a
submodule to import and document. Leaving a submodule out of __all__
doesn't fail the build — it silently drops that module from both the
generated docs and the landing page's own navigation — so if you add a
new top-level submodule, add its name to __all__ too, not to this
command.
Output goes to docs/api/ (gitignored, regenerated on demand). CI builds
this too and publishes it alongside the mdBook user guide — see
"CI/CD architecture" below.
Development note: -t docs/pdoc_templates points pdoc at
docs/pdoc_templates/custom.css, pdoc's own supported override point
(-t/--template-directory — see
pdoc's documentation). It's included
last, after theme.css/layout.css/content.css, so it always wins
the cascade. This one softens pdoc's default theme: a pure white page
background (--pdoc-background: #fff) with code-block/highlighted-box
backgrounds only slightly darker (--code: #f8f8f8, --accent: #eee)
reads as a stark white glare across the page as a whole. The override
shifts all three together — --pdoc-background: #efede7,
--code: #e3dfd7, --accent: #d7d3c9 — rather than tinting the
background alone, so the page < code-block < accent-box hierarchy
pdoc's default theme establishes stays intact, just softer throughout.
Tuned in two successive passes, each computed in HSL space (same hue/
saturation per variable, lightness lowered by a measured delta) rather
than picked by eye, so the gaps between the three tiers stay even
instead of collapsing into each other. --accent2 (the border/
scrollbar gray, #c1c1c1) is untouched — already reads with plenty of
contrast against every tone above.
Building the coverage badge
The README's coverage badge is a real SVG generated from coverage.xml with
genbadge, a dev dependency —
not a static label:
uv run pytest --cov=src/dictk --cov-report=xml --cov-report=html
uv run genbadge coverage -i coverage.xml -o coverage-badge.svg
In CI this runs in the docs job (not test) using the coverage.xml
produced by the test job's report-test artifact, so the badge only
updates on pushes to main or dev — same cadence as the Docs and API
badges, not per-PR. Both coverage-badge.svg and the full htmlcov/ report
are staged into the deployed site under that branch's subdirectory
(<branch>/badges/coverage.svg and <branch>/coverage/ respectively) — see
"CI/CD architecture" below.
Building the tests badge
The README's tests badge (tests: N pass M fail) is a real SVG built from
pytest's own JUnit XML report, not a static label:
uv run pytest --cov=src/dictk --cov-report=xml --cov-report=html --junitxml=junit.xml
uv run python .github/scripts/generate_tests_badge.py --input junit.xml --output tests-badge.svg
--junitxml is a builtin pytest flag — no extra plugin needed.
generate_tests_badge.py parses that report's pass/fail/skip counts and
requests a matching badge from shields.io directly (same service
genbadge uses for the coverage
badge above, just called directly here rather than through that library,
since genbadge's own test-badge format is N/M, not the N pass M fail
wording this one matches) — green when nothing fails, red otherwise. Like
the coverage badge, this runs in the docs job using the test job's
report-test artifact, so it updates on pushes to main/dev only. Staged
into the deployed site at <branch>/badges/tests.svg.
Development note: shields.io returns 403 Forbidden for urllib's
default User-Agent string (Python-urllib/x.y) — presumably basic bot
filtering, since curl (used by the lint badge below) isn't blocked.
Fixed by setting an explicit User-Agent header on the request rather
than shelling out to curl from a Python script for no other reason.
Running pylint (informational)
ruff (ruff format --check and ruff check) is what actually gates CI —
see "Linting and formatting" above. pylint
also runs, but only in the docs job, and only informationally: it can't
fail the build. It exists purely because ruff has no equivalent of pylint's
Your code has been rated at X.XX/10 score, and the README's lint badge
wants a score, not just a pass/fail (which the CI badge already covers).
Since pylint and ruff check overlapping-but-different rule sets, expect
pylint to flag a few things ruff doesn't (and vice versa) — that's expected
duplication from running two linters, not a bug in either.
uv run pylint src/dictk --output-format=text --reports=yes > pylint-report.txt
uv run python .github/scripts/render_pylint_report.py \
  --input pylint-report.txt --output pylint-report.html
The badge itself is built by extracting the score from that output and
requesting a matching badge from shields.io — see the "Run pylint
(informational) and generate lint badge/report" step in ci.yml for the
exact score-extraction and color-threshold logic. pylint-report.html is
staged into the deployed site at <branch>/reports/lint/, and the badge at
<branch>/badges/lint.svg — same cadence as the other gh-pages badges
(updates on pushes to main or dev).
Building the status dashboard
<branch>/dashboard/ on the deployed site is a single page linking every
badge and report above for that branch, generated by
.github/scripts/render_dashboard.py. It exists because the mdBook user
guide occupies that branch's subdirectory root, so there's no natural
landing page that lists the API reference, coverage report, and lint report
together — rather than expecting visitors to already know those paths, or
scattering the links across the README only. It doesn't require any of the
other artifacts to already exist locally (it only generates links to them,
using paths relative to <branch>/dashboard/, e.g. ../coverage/):
uv run python .github/scripts/render_dashboard.py \
  --github-repo hovey/dictk \
  --run-id local \
  --sha "$(git rev-parse HEAD)" \
  --ref-name "$(git rev-parse --abbrev-ref HEAD)" \
  --timestamp "$(date -u +'%Y-%m-%d %H:%M:%S UTC')" \
  --output dashboard.html
In CI, ${{ github.run_id }}, ${{ github.sha }}, and ${{ github.ref_name }}
fill in the run metadata instead. dashboard.html is staged into the
deployed site at <branch>/dashboard/.
Building the root landing page
The site root (/) doesn't belong to either branch — main and dev each
deploy to their own subdirectory (see "CI/CD
architecture" below), so the root is a two-column
dashboard (main "Released" in blue, dev "Development" in orange) linking to
each branch's user guide, API reference, dashboard, coverage, lint, and
tests badges, styled with the Tailwind CDN build — modeled on
sandialabs/rattlesnake-vibration-controller's gh-pages
dashboard.
It's generated by .github/scripts/render_landing.py and regenerated on
every deploy from whichever branch ran most recently (only the footer's
timestamp/commit/CI-run attribution changes between deploys — the two
columns' links are static):
uv run python .github/scripts/render_landing.py \
  --github-repo hovey/dictk \
  --run-id local \
  --sha "$(git rev-parse HEAD)" \
  --ref-name "$(git rev-parse --abbrev-ref HEAD)" \
  --timestamp "$(date -u +'%Y-%m-%d %H:%M:%S UTC')" \
  --output landing.html
landing.html is staged as index.html at the deployed site's root.
Before pushing
There's no preflight command yet (see rattlesnake-vibration-controller's
preflight.py for an example of what that could grow into) — for now, run
the checks manually:
uv run ruff format --check
uv run ruff check
uv run pytest --cov=src/dictk --cov-report=xml --cov-report=html --junitxml=junit.xml
uv run mdbook build
uv run pdoc dictk -o docs/api --docformat google --math -t docs/pdoc_templates
uv run genbadge coverage -i coverage.xml -o coverage-badge.svg
uv run python .github/scripts/generate_tests_badge.py --input junit.xml --output tests-badge.svg
uv run pylint src/dictk --output-format=text --reports=yes
These are exactly the checks the test and docs jobs run in CI.
CI/CD architecture
CI and releasing live in two workflows: .github/workflows/ci.yml (checks
and docs, on every push/PR) and .github/workflows/release.yml (publishing,
on a version tag push).
ci.yml has two jobs, plus a workflow_call trigger so release.yml can
invoke it as a reusable workflow:
-
test— runs on every push, pull request, and when called fromrelease.yml. Installs dependencies withuv sync, runsuv buildas a build sanity check,ruff format --check,ruff check, andpytest --cov(with--junitxmltoo). Uploads the coverage and JUnit XML reports as a build artifact (report-test). -
docs— runs only on pushes tomainordev, aftertestpasses (thisifcondition also means it's skipped whenrelease.ymlcallsci.ymlfrom a tag push, since the ref won't berefs/heads/mainorrefs/heads/dev). Installs the pinnedmdbook0.4.52,mdbook-cmdrun, andmdbook-katex(cached viaactions/cache), downloads thetestjob'sreport-testartifact, builds the mdBook user guide withdictk's own CLI onPATH, builds the pdoc API reference, generates a coverage badge fromcoverage.xmlwith genbadge and a tests badge fromjunit.xml(N pass M fail, viagenerate_tests_badge.py— see "Building the tests badge" above), runs pylint informationally to get a 0-10 score (fetched as a shields.io badge) and a full findings report, renders a status dashboard linking all of the above, and stages all of it into one directory (user guide at the root, API reference underapi/, badges underbadges/coverage.svg,badges/lint.svg, andbadges/tests.svg, full HTML coverage report undercoverage/, full pylint report underreports/lint/, dashboard underdashboard/).That staged directory becomes the whole subtree for whichever branch triggered the run — deployed to
main/ordev/on thegh-pagesbranch (published via GitHub Pages), alongside a regenerated rootindex.htmllanding page linking to both (see "Building the root landing page" above). Deployment is a manual clone-of-gh-pages→ replace only${DEPLOY_SUBDIR}/andindex.html→ commit → push, notpeaceiris/actions-gh-pages: that action replaces the wholepublish_dir(or, withkeep_files, tries to preserve everything else, which is imprecise ifmainanddevdeploy close together and risks one branch's content clobbering the other's — a problem sandialabs/rattlesnake-vibration-controller'sci.ymlhit and solved the same way). The job'sconcurrencygroup (gh-pages-deploy,cancel-in-progress: false) serializesmain's anddev's deploys so this step never runs for both at once.
release.yml triggers on pushing a tag matching v* and runs, in order:
validate_tag— verifies the tag is valid PEP 440, that it's strictly newer than every existing tag, and that its branch matches its prerelease status: a prerelease tag (a/b/rc/.devsuffix) must be reachable fromorigin/dev; a stable/post tag must be reachable fromorigin/mainspecifically. Outputsis_prereleasefor the jobs below.test—needs: validate_tag, callsci.yml'stestjob fresh at the tagged commit (not reused from an earlier push-to-main run).build—needs: test. Runsuv build, generates a build-provenance attestation for the dist files, and uploads them as an artifact.github-release—needs: [build, validate_tag]. Creates a GitHub Release with auto-generated notes, attaching the dist files, marked prerelease or not pervalidate_tag's output.publish_testpypi/publish_pypi—needs: [build, github-release, validate_tag], gated onis_prereleasebeingtrue/falserespectively. Publishes to TestPyPI or PyPI. See "Releasing" below.
This is intentionally a minimal setup — no matrix OS/Python testing, no
containerized builds. pytribeam's ci.yml and
rattlesnake-vibration-controller's ci.yml/release.yml are useful
references for growing any of this out later (dictk's release.yml is in
fact modeled on rattlesnake-vibration-controller's, with one addition: tying
the branch check to prerelease status, described above).
Versioning
Versions are derived automatically from git tags via
hatch-vcs — there is no hand-maintained
version string anywhere in the source. Tag format is a v-prefixed
PEP 440 version, e.g. v0.1.0.
If the current commit isn't exactly at a tag (or the working tree is dirty),
hatch-vcs appends a local version segment (e.g. 0.1.dev1+gd975d09).
PyPI and TestPyPI reject uploads with a local version segment, so a
publishable commit must be exactly the tagged commit.
Tags and semantic versioning
Tags follow PEP 440, which requires version strings to follow this structure:
N.N.N[{a|b|rc}N][.postN][.devN]
Example tags
Prerelease tags:
| tag | description |
|---|---|
v1.1.0a1 | The first alpha for version 1.1.0 |
v1.1.0b2 | The second beta for version 1.1.0 |
v1.1.0rc1 | The first release candidate for version 1.1.0 |
A release candidate is made during the final testing stage before a full release.
Stable release tags (e.g., starting from a v1.0.0 release):
| tag | description |
|---|---|
v1.0.1 | Patch release: backwards-compatible bug fixes |
v1.1.0 | Minor release: new features that are backwards-compatible |
v2.0.0 | Major release: significant changes or breaking API updates |
Development and post-release tags:
| tag | description |
|---|---|
v1.1.0.dev1 | A version currently under development |
v1.0.0.post1 | A fix for a minor error in the release process, such as a typo in the documentation, without changing the code |
Release on tag
Pushing a tag is what triggers release.yml (see
"CI/CD architecture" above) — there's no separate
commit-message keyword. Which registry it publishes to is decided by the
tag's own shape: a prerelease tag (a/b/rc/.dev suffix) publishes to
TestPyPI, a stable/post tag publishes to PyPI. The branch the tag is cut from
has to match: prerelease tags on dev, stable/post tags on main. See
"Merging dev into main" and
"Publishing a release" below for the actual
commands.
Releasing
Releases are triggered by pushing a git tag matching v* — see
"Release on tag" above. validate_tag (the first job in release.yml) checks the tag is
valid PEP 440, strictly newer than every existing tag, and cut from the
branch its prerelease status requires (dev for prerelease, main for
stable/post). Because the release jobs build whatever hatch-vcs resolves at
the tagged commit, the tag must point at the exact commit you want published.
Merging dev into main
main is a protected branch — it only accepts changes through a merged pull
request, even for repo admins, so git push origin main will be rejected.
This step is only needed before a stable release (prereleases tag dev
directly — see "Publishing a release" below). Merge
dev into main through a PR:
git checkout dev
git pull origin dev
gh pr create --base main --head dev --title "Merge dev into main" --body ""
gh pr merge --merge
No approving review is required, so you can merge your own PR.
One-time setup (already done for this repo)
- GitHub → repo Settings → Environments: create
testpypiandpypienvironments.pypihas a "Required reviewers" rule (you) configured, so a real release needs manual approval in the Actions UI before publishing —testpypidoesn't need this. - On test.pypi.org and
pypi.org, under the
dictkproject's "Publishing" settings, add a trusted publisher: ownerhovey, repositorydictk, workflow filerelease.yml(notci.yml— publishing happens in the tag-triggered workflow), environment nametestpypi(for TestPyPI) orpypi(for PyPI).
No API tokens are stored anywhere — publishing uses OIDC trusted publishing
via the id-token: write permission.
Publishing a release
Prerelease (TestPyPI) — tag dev directly, no PR needed:
git checkout dev
git pull origin dev
git tag v0.1.0rc1
git push origin v0.1.0rc1
Stable (PyPI) — merge dev into main first (see
"Merging dev into main" above), then tag
main:
git checkout main
git pull origin main
git tag v0.1.0
git push origin v0.1.0
Either way, watch the Actions tab: validate_tag → test → build →
github-release → publish_testpypi/publish_pypi. For a prerelease, check
https://test.pypi.org/project/dictk/ once it succeeds. For a stable
release, the publish_pypi job pauses for your approval (the pypi
environment's required reviewer) before it runs; approve it from the Actions
run page, then check https://pypi.org/project/dictk/.
Uploads to PyPI (and TestPyPI) are permanent — a given version's files can
never be re-uploaded or deleted, only "yanked". Prefer testing on TestPyPI
first, as with v0.1.0rc1 above, before publishing the stable release.